SpecAugment with Pytorch
A Pytorch Implementation of GoogleBrain's SpecAugment: A Simple Data Augmentation Method for Automatic Speech Recognition
SpecAugment is a state of the art data augmentation approach for speech recognition.
The paper's authors did not publish code that I could find and their implementation was in TensorFlow. We implemented all three SpecAugment transforms using Pytorch, torchaudio, and fastai / fastai-audio.
To use:
- Run
install.sh(I recommend using a uniquecondaenv for the project)
After the install script runs, you should have a torchaudio folder in your project folder.
- Check out SpecAugment.ipynb (a Jupyter notebook) for the functions.
Augmentations
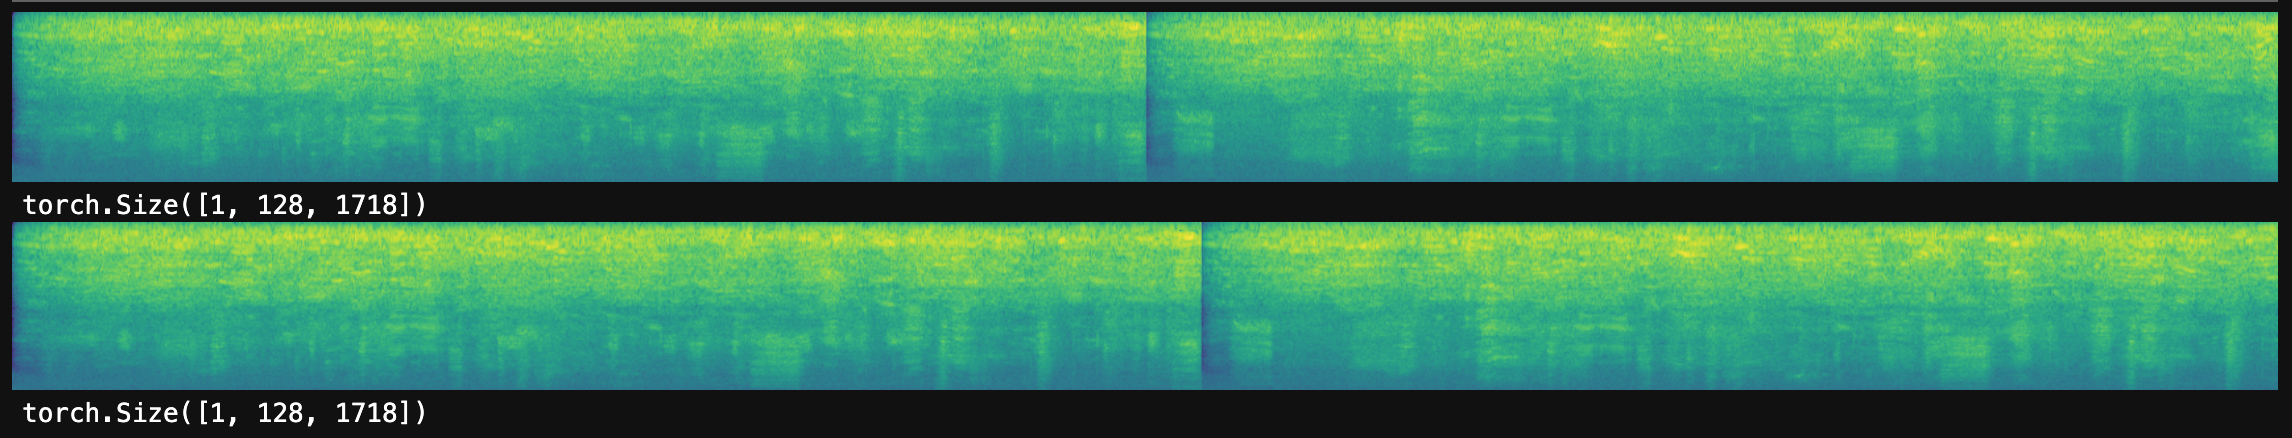
Time Warp
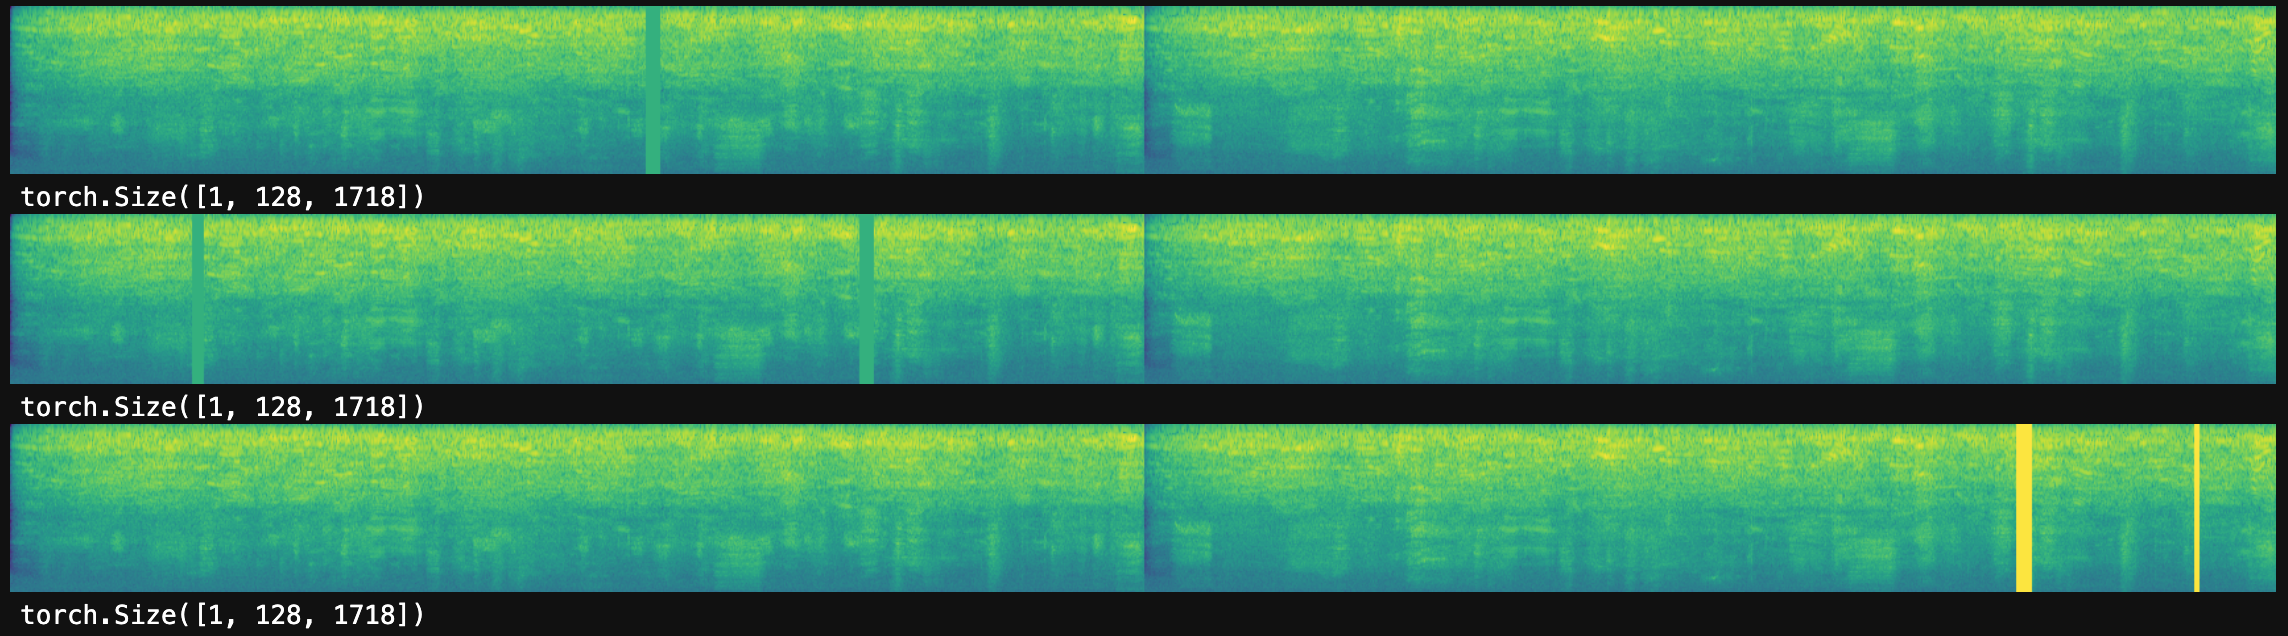
Time Mask
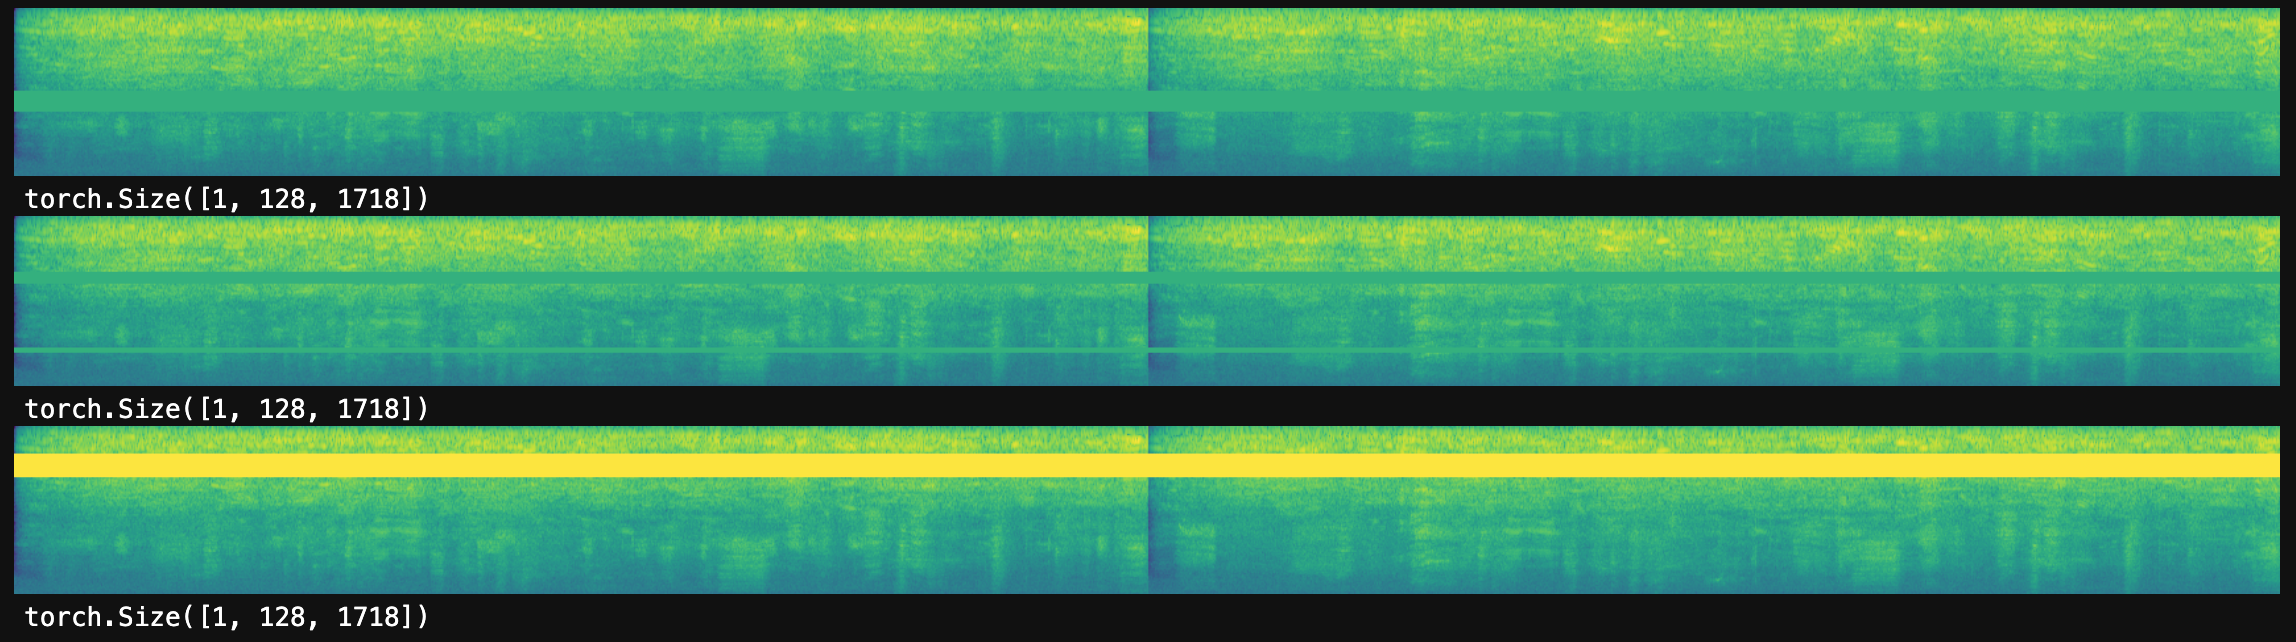
Frequency Mask
Combined:

Note on Time Warp
The Time Warp augmentation relies on Tensorflow-specific functionality not supported in Pytorch. We implemented supporting functions for this augmentation in SparseImageWarp.ipynb. You do not need to look at this notebook to use the augmentations. But the Time Warp augmentation depends on code exposed in the SparseImageWarp notebook.
Let's be friends!