Multimodal Chain-of-Thought Reasoning: A Comprehensive Survey
💡 You're very welcome to join our discussion (on WeChat or Slack) on the topic of multimodal reasoning.
📌 Please feel free to ping us for any possibly missed related work — see CONTRIBUTING.md for how to suggest a paper.

🎇 Introduction
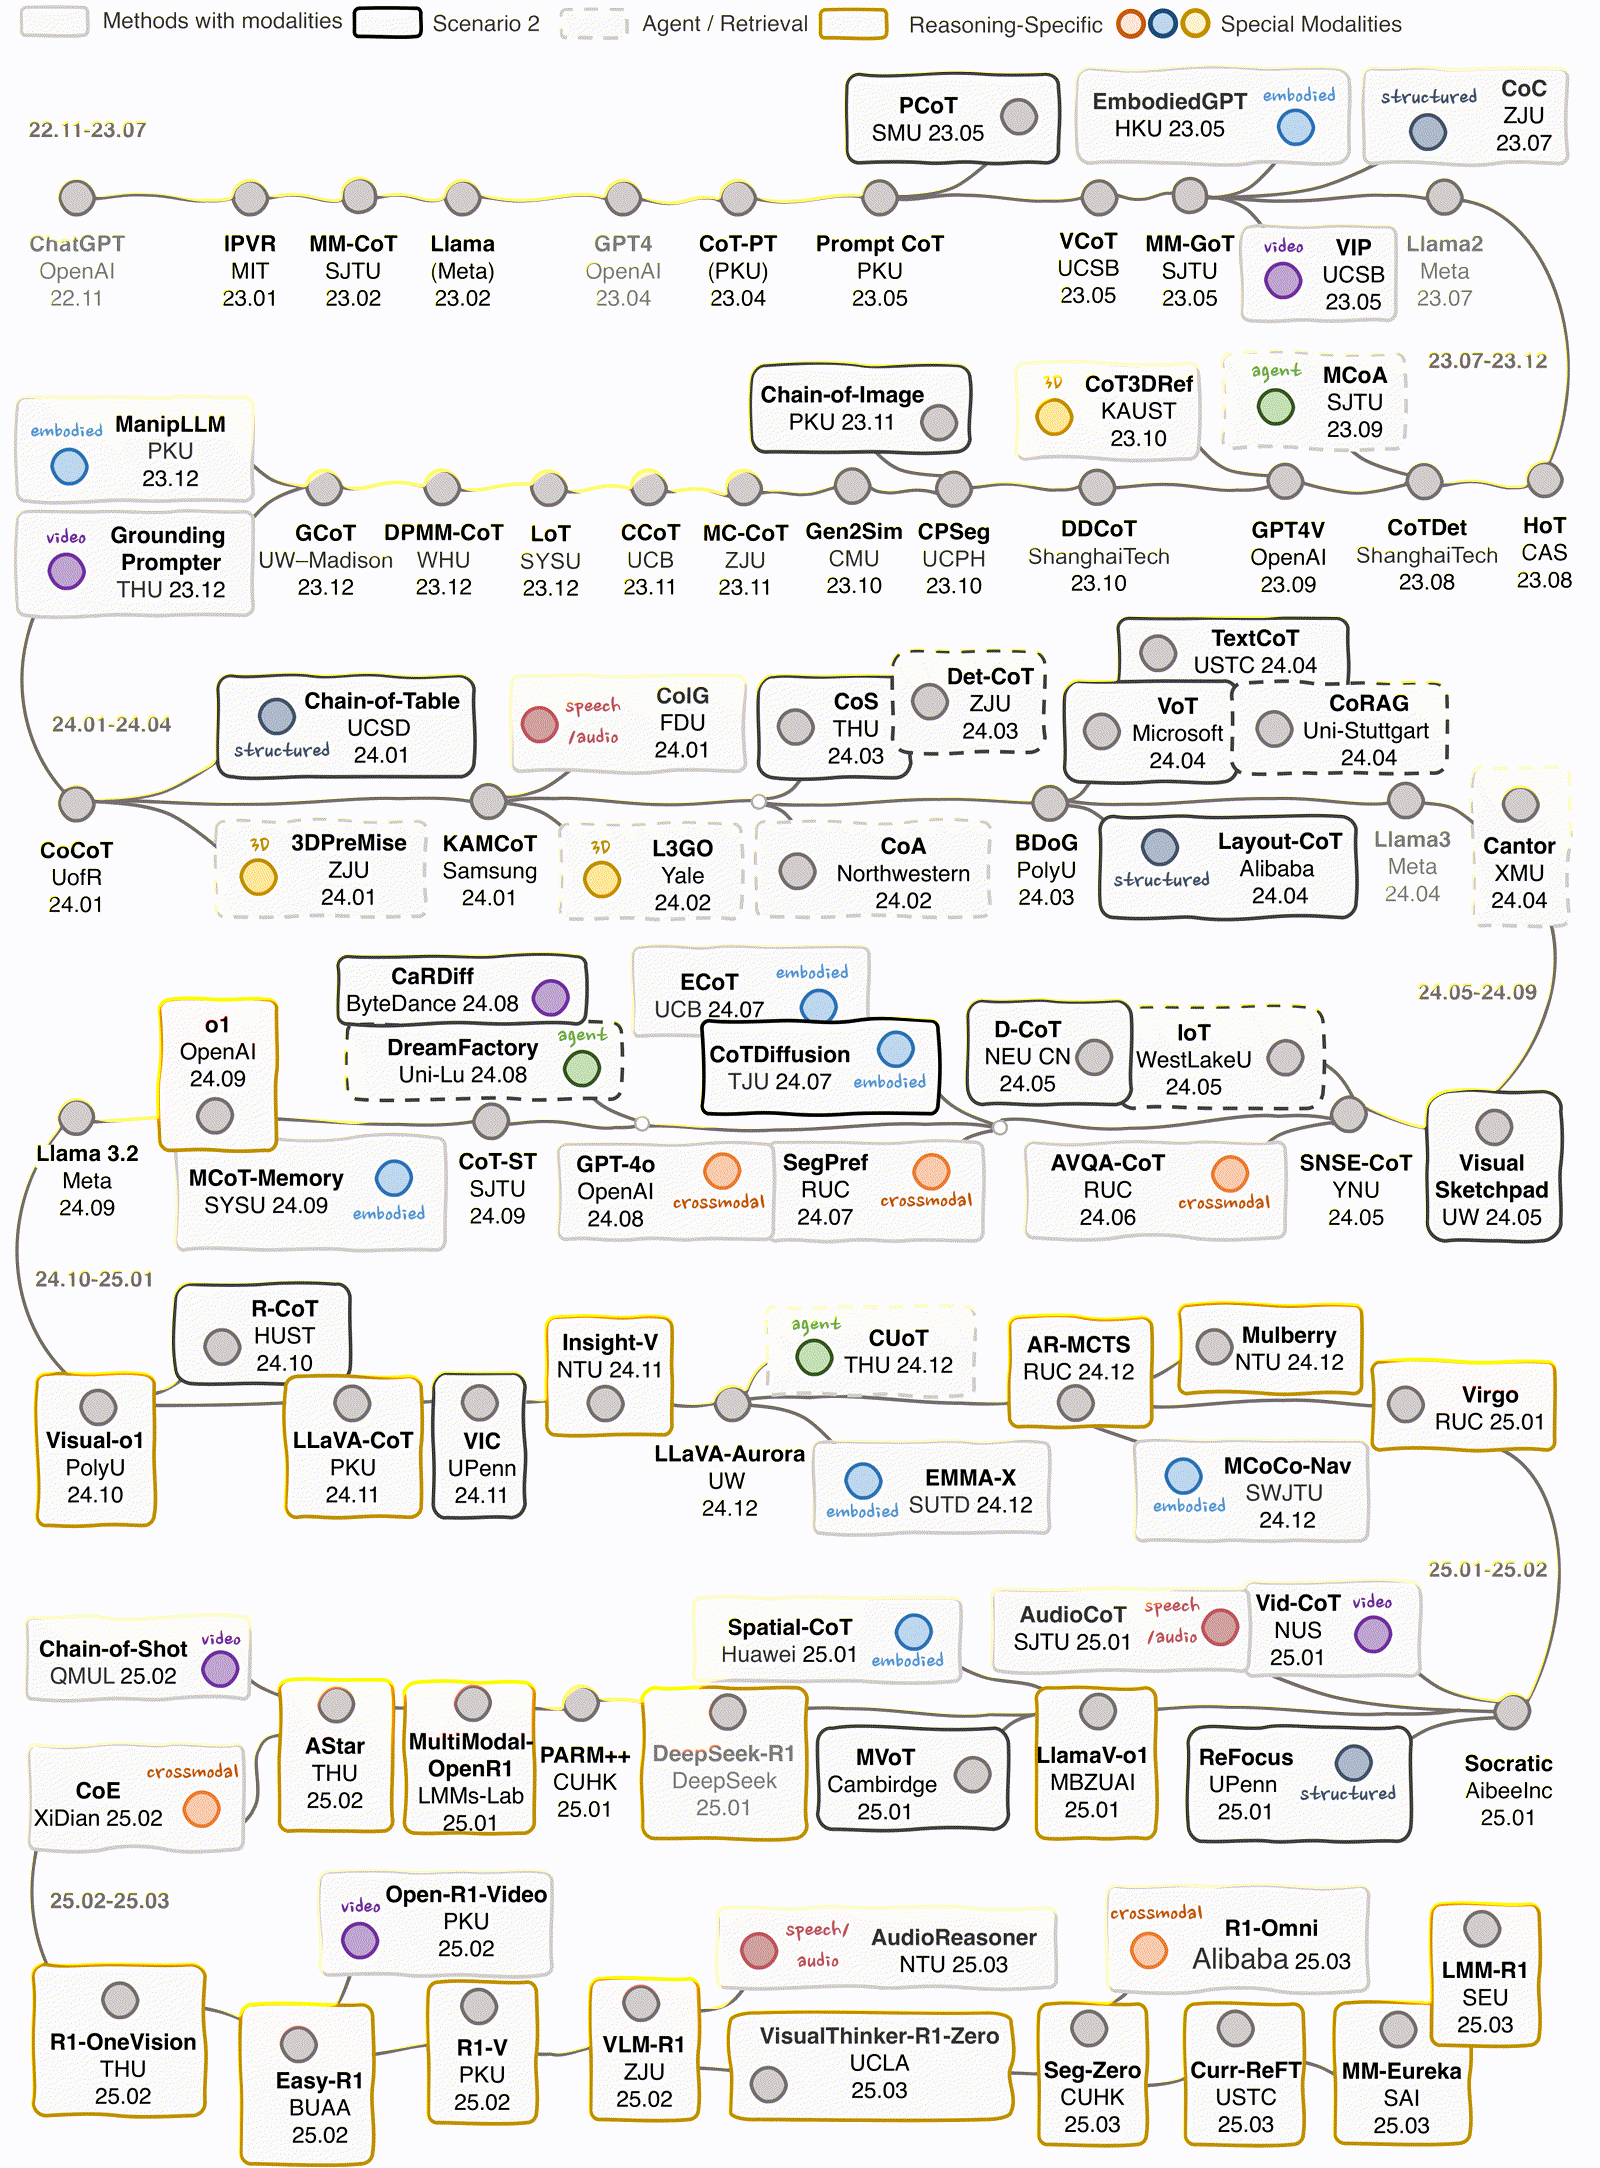
Multimodal chain-of-thought (MCoT) reasoning has garnered attention for its ability to enhance step-by-step reasoning in multimodal contexts, particularly within multimodal large language models (MLLMs). Current MCoT research explores various methodologies to address the challenges posed by images, videos, speech, audio, 3D data, and structured data, achieving success in fields such as robotics, healthcare, and autonomous driving. However, despite these advancements, the field lacks a comprehensive review that addresses the numerous remaining challenges.
To fill this gap, we present the first systematic survey of MCoT reasoning, elucidating the foundational concepts and definitions pertinent to this area. Our work includes a detailed taxonomy and an analysis of existing methodologies across different applications, as well as insights into current challenges and future research directions aimed at fostering the development of multimodal reasoning.
Updates
2025-05-20: We upload the Chinese language version, enjoy!
2025-04-25: We gain 500 stars! Thank you all!
2025-03-18: We release the Awesome-MCoT repo and survey.
📕 Table of Contents
- 🎖 MCoT Datasets and Benchmarks
- 🎊 Multimodal Reasoning via RL
- ✨ MCoT Over Various Modalities
- 🔥 MCoT Methodologies
- 🎨 Applications with MCoT Reasoning
- 🚀 Useful Links
- ❤️ Citation
- ⭐️ Star History
🎖 MCoT Datasets and Benchmarks
- "MC" and "Open" refer to multiple-choice and open-ended answer formats.
- "T", "I", "V", and "A" represent Text, Image, Video, and Audio, respectively.
Tab-1: Datasets for MCoT Training with Rationale.
| Datasets | Year | Task | Domain | Modality | Format | Samples |
|---|---|---|---|---|---|---|
| ScienceQA | 2022 | VQA | Science | T, I | MC | 21K |
| A-OKVQA | 2022 | VQA | Common | T, I | MC | 25K |
| EgoCoT | 2023 | VideoQA | Common | T, V | Open | 200M |
| VideoCoT | 2024 | VideoQA | Human Action | T, V | Open | 22K |
| VideoEspresso | 2024 | VideoQA | Common | T, V | Open | 202,164 |
| EMMA-X | 2024 | Robot Manipulation | Indoor | T, V | Robot Actions | 60K |
| M3CoT | 2024 | VQA | Science, Math, Common | T, I | MC | 11.4K |
| MAVIS | 2024 | ScienceQA | Math | T, I | MC and Open | 834K |
| LLaVA-CoT-100k | 2024 | VQA | Common, Science | T, I | MC and Open | 834K |
| MAmmoTH-VL | 2024 | Diverse | Diverse | T, I | MC and Open | 12M |
| Mulberry-260k | 2024 | Diverse | Diverse | T, I | MC and Open | 260K |
| MM-Verify | 2025 | MathQA | Math | T, I | MC and Open | 59,772 |
| VisualPRM400K | 2025 | ScienceQA | Math, Science | T, I | MC and Open | 400K |
| R1-OneVision | 2025 | Diverse | Diverse | T, I | MC and Open | 155K |
Tab-2: Benchmarks for MCoT Evaluation without Rationale.
| Datasets | Year | Task | Domain | Modality | Format | Samples |
|---|---|---|---|---|---|---|
| MMMU | 2023 | VQA | Arts, Science | T, I | MC and Open | 11.5K |
| SEED | 2023 | VQA | Common | T, I | MC | 19K |
| MathVista | 2023 | ScienceQA | Math | T, I | MC and Open | 6,141 |
| MathVerse | 2024 | ScienceQA | Math | T, I | MC and Open | 15K |
| Math-Vision | 2024 | ScienceQA | Math | T, I | MC and Open | 3040 |
| MeViS | 2023 | Referring VOS | Common | T, V | Dense Mask | 2K |
| VSIBench | 2024 | VideoQA | Indoor | T, V | MC and Open | 5K |
| HallusionBench | 2024 | VQA | Common | T, I | Yes-No | 1,129 |
| AV-Odyssey | 2024 | AVQA | Common | T, V, A | MC | 4,555 |
| AVHBench | 2024 | AVQA | Common | T, V, A | Open | 5,816 |
| RefAVS-Bench | 2024 | Referring AVS | Common | T, V, A | Dense Mask | 4,770 |
| MMAU | 2024 | AQA | Common | T, A | MC | 10K |
| AVTrustBench | 2025 | AVQA | Common | T, V, A | MC and Open | 600K |
| MIG-Bench | 2025 | Multi-image Grounding | Common | T, I | BBox | 5.89K |
| MedAgentsBench | 2025 | MedicalQA | Medical | T, I | MC and Open | 862 |
| OSWorld | 2024 | Agent | Real Comp. Env. | T, I | Agent Action | 369 |
| AgentClinic | 2024 | MedicalQA | Medical | T, I | Open | 335 |
Tab-3: Benchmarks for MCoT Evaluation with Rationale.
| Datasets | Year | Task | Domain | Modality | Format | Samples |
|---|---|---|---|---|---|---|
| CoMT | 2024 | VQA | Common | T, I | MC | 3,853 |
| OmniBench | 2024 | VideoQA | Common | T, I, A | MC | 1,142 |
| WorldQA | 2024 | VideoQA | Common | T, V, A | Open | 1,007 |
| MiCEval | 2024 | VQA | Common | T, I | Open | 643 |
| OlympiadBench | 2024 | ScienceQA | Maths, Physics | T, I | Open | 8,476 |
| MME-CoT | 2025 | VQA | Science, Math, Common | T, I | MC and Open | 1,130 |
| EMMA | 2025 | VQA | Science | T, I | MC and Open | 2,788 |
| VisualProcessBench | 2025 | ScienceQA | Math, Science | T, I | MC and Open | 2,866 |
🎊 Multimodal Reasoning via RL
- The following table concludes the techniques used by MLLMs with RL for better long-MCoT reasoning, where "T", "I", "V", and "A" represent Text, Image, Video, and Audio, respectively.
- In summary, RL unlocks complex reasoning and
aha-momentwithout SFT, demonstrating its potential to enhance model capabilities through iterative self-improvement and rule-based approaches, ultimately paving the way for more advanced and autonomous multimodal reasoning systems.
| Model | Foundational LLMs | Modality | Learning | Cold Start | Algorithm | Aha-moment |
|---|---|---|---|---|---|---|
| Deepseek-R1-Zero | Deepseek-V3 | T | RL | ❌ | GRPO | ✅ |
| Deepseek-R1 | Deepseek-V3 | T | SFT+RL | ✅ | GRPO | - |
| LLaVA-Reasoner | LLaMA3-LLaVA-NEXT-8B | T,I | SFT+RL | ✅ | DPO | - |
| Insight-V | Deepseek-V3 | T,I | SFT+RL | ✅ | DPO | - |
| Multimodal-Open-R1 | Qwen2-VL-7B-Instruct | T,I | RL | ❌ | GRPO | ❌ |
| R1-OneVision | Qwen2.5-VL-7B-Instruct | T,I | SFT | - | - | - |
| R1-V | Qwen2.5-VL | T,I | RL | ❌ | GRPO | ❌ |
| VLM-R1 | Qwen2.5-VL | T,I | RL | ❌ | GRPO | ❌ |
| LMM-R1 | Qwen2.5-VL-Instruct-3B | T,I | RL | ❌ | PPO | ❌ |
| Curr-ReFT | Qwen2.5-VL-3B | T,I | RL+SFT | ❌ | GRPO | - |
| Seg-Zero | Qwen2.5-VL-3B + SAM2 | T,I | RL | ❌ | GRPO | ❌ |
| MM-Eureka | InternVL2.5-Instruct-8B | T,I | SFT+RL | ✅ | RLOO | - |
| MM-Eureka-Zero | InternVL2.5-Pretrained-38B | T,I | RL | ❌ | GRPO | ✅ |
| VisualThinker-R1-Zero | Qwen2-VL-2B | T,I | RL | ❌ | GRPO | ✅ |
| Easy-R1 | Qwen2.5-VL | T,I | RL | ❌ | GRPO | - |
| Open-R1-Video | Qwen2-VL-7B | T,I,V | RL | ❌ | GRPO | ❌ |
| R1-Omni | HumanOmni-0.5B | T,I,V,A | SFT+RL | ✅ | GRPO | - |
| VisRL | Qwen2.5-VL-7B | T,I | SFT+RL | ✅ | DPO | - |
| R1-VL | Qwen2-VL-7B | T,I | RL | ❌ | StepGRPO | - |
| OpenVLThinker | Qwen2.5-VL-7B-Instruct | T,I | SFT+RL | ✅ | GRPO | - |
| EchoInk-R1 | Qwen2.5-Omni-7B | T, I, A | RL | ❌ | GRPO | ✅ |
| Web-CogReasoner | Qwen2.5-VL-7B | T, I | SFT | - | - | - |
✨ MCoT Over Various Modalities
MCoT Reasoning Over Image
2026 · 15 papers
- ImgCoT: Compressing Long Chain of Thought into Compact Visual Tokens for Efficient Multimodal Reasoning
- Do MLLMs Really See It: Reinforcing Visual Attention in Multimodal LLMs
- MIRROR: Multimodal Iterative Reasoning via Reflection on Visual Regions
- Annotation-Free Visual Reasoning for High-Resolution Large Multimodal Models via Reinforcement Learning
- Thinking with Images as Continuous Actions: Numerical Visual Chain-of-Thought
- PaLMR: Towards Faithful Visual Reasoning via Multimodal Process Alignment
- VaLR: Vision-aligned Latent Reasoning for Multi-modal Large Language Model
- CrystaL: Spontaneous Emergence of Visual Latents in MLLMs
- Imagination Helps Visual Reasoning, But Not Yet in Latent Space
- LanteRn: Latent Visual Structured Reasoning
- Decompose, Look, and Reason: Reinforced Latent Reasoning for VLMs
- Visual Latents Know More Than They Say: Unsilencing Latent Reasoning in MLLMs
- Retrieve, Integrate, and Synthesize: Spatial-Semantic Grounded Latent Visual Reasoning
- What is Holding Back Latent Visual Reasoning?
- Reinforced Attention Learning
2025 · 25 papers
-
Imagine while Reasoning in Space: Multimodal Visualization-of-Thought
-
Visual Thoughts: A Unified Perspective of Understanding Multimodal Chain-of-Thought
-
Multimodal Chain of Continuous Thought for Latent-Space Reasoning in Vision-Language Models
-
MM-Verify: Enhancing Multimodal Reasoning with Chain-of-Thought Verification
-
Embodied-Reasoner: Synergizing Visual Search, Reasoning, and Action for Embodied Interactive Tasks

-
MM-Eureka: Exploring Visual Aha Moment with Rule-based Large-scale Reinforcement Learning

-
Vision-R1: Incentivizing Reasoning Capability in Multimodal Large Language Models

-
VisRL: Intention-Driven Visual Perception via Reinforced Reasoning

-
R1-Onevision: Advancing Generalized Multimodal Reasoning through Cross-Modal Formalization

-
LMM-R1: Empowering 3B LMMs with Strong Reasoning Abilities Through Two-Stage Rule-Based RL

-
R1-Zero's "Aha Moment" in Visual Reasoning on a 2B Non-SFT Model

-
CreatiLayout: Siamese Multimodal Diffusion Transformer for Creative Layout-to-Image Generation

-
Seg-Zero: Reasoning-Chain Guided Segmentation via Cognitive Reinforcement

-
Sketch-of-Thought: Efficient LLM Reasoning with Adaptive Cognitive-Inspired Sketching

-
Boosting Multimodal Reasoning with MCTS-Automated Structured Thinking
-
Virgo: A Preliminary Exploration on Reproducing o1-like MLLM

-
RedStar: Does Scaling Long-CoT Data Unlock Better Slow-Reasoning Systems?
-
RelationLMM: Large Multimodal Model as Open and Versatile Visual Relationship Generalist
-
Imagine while Reasoning in Space: Multimodal Visualization-of-Thought
-
Can We Generate Images with CoT? Let's Verify and Reinforce Image Generation Step by Step


2024 · 30 papers
-
Mind's Eye of LLMs: Visualization-of-Thought Elicits Spatial Reasoning in Large Language Models
-
AR-MCTS: Progressive Multimodal Reasoning via Active Retrieval
-
Perception Tokens Enhance Visual Reasoning in Multimodal Language Models

-
MAmmoTH-VL: Eliciting Multimodal Reasoning with Instruction Tuning at Scale

-
Insight-V: Exploring Long-Chain Visual Reasoning with Multimodal Large Language Models

-
Visual Sketchpad: Sketching as a Visual Chain of Thought for Multimodal Language Models

-
Enhancing Large Vision Language Models with Self-Training on Image Comprehension

-
PS-CoT-Adapter: adapting plan-and-solve chain-of-thought for ScienceQA

-
Mind's Eye of LLMs: Visualization-of-Thought Elicits Spatial Reasoning in Large Language Models

-
DCoT: Dual Chain-of-Thought Prompting for Large Multimodal Models
-
Chain-of-Exemplar: Enhancing Distractor Generation for Multimodal Educational Question Generation

-
A Picture Is Worth a Graph: A Blueprint Debate Paradigm for Multimodal Reasoning

-
DetToolChain: A New Prompting Paradigm to Unleash Detection Ability of MLLM

-
PromptCoT: Align Prompt Distribution via Adapted Chain-of-Thought
-
Enhancing Semantics in Multimodal Chain of Thought via Soft Negative Sampling
-
TextCoT: Zoom In for Enhanced Multimodal Text-Rich Image Understanding

-
Beyond Chain-of-Thought, Effective Graph-of-Thought Reasoning in Language Models

-
Chain-of-Spot: Interactive Reasoning Improves Large Vision-Language Models

-
Compositional Chain-of-Thought Prompting for Large Multimodal Models

-
KAM-CoT: Knowledge Augmented Multimodal Chain-of-Thoughts Reasoning
-
CoCoT: Contrastive Chain-of-Thought Prompting for Large Multimodal Models with Multiple Image Inputs


2023 · 10 papers
-
CoTDet: Affordance Knowledge Prompting for Task Driven Object Detection

-
Multi-modal Latent Space Learning for Chain-of-Thought Reasoning in Language Models

-
The Art of SOCRATIC QUESTIONING: Recursive Thinking with Large Language Models

-
CPSeg: Finer-grained Image Semantic Segmentation via Chain-of-Thought Language Prompting
-
DDCoT: Duty-Distinct Chain-of-Thought Prompting for Multimodal Reasoning in Language Models

-
Thinking Like an Expert:Multimodal Hypergraph-of-Thought (HoT) Reasoning to boost Foundation Modals
-
LayoutLLM-T2I: Eliciting Layout Guidance from LLM for Text-to-Image Generation


MCoT Reasoning Over Video
2026 · 3 papers

2025 · 4 papers
-
Videochat-r1: Enhancing spatio-temporal perception via reinforcement fine-tuning
-
FrameMind: Frame-Interleaved Video Reasoning via Reinforcement Learning
-
Video-R1: Towards Super Reasoning Ability in Video Understanding

-
video-SALMONN-o1: Reasoning-enhanced Audio-visual Large Language Model


2024 · 9 papers
-
Videocot: A video chain-of-thought dataset with active annotation tool
-
Analyzing Key Factors Influencing Emotion Prediction Performance of VLLMs in Conversational Contexts
-
Interpretable Video based Stress Detection with Self-Refine Chain-of-thought Reasoning
-
DreamFactory: Pioneering Multi-Scene Long Video Generation with a Multi-Agent Framework
-
Large Vision-Language Models as Emotion Recognizers in Context Awareness

-
Hallucination Mitigation Prompts Long-term Video Understanding

-
Video-of-Thought: Step-by-Step Video Reasoning from Perception to Cognition

-
AntGPT: Can Large Language Models Help Long-term Action Anticipation from Videos?

2023 · 2 papers


MCoT Reasoning Over 3D
2025 · 3 papers
-
3D-R1: Enhancing Reasoning in 3D VLMs for Unified Scene Understanding
-
SceneCOT: Eliciting Grounded Chain-of-Thought Reasoning in 3D Scenes

-
Integrating Chain-of-Thought for Multimodal Alignment: A Study on 3D Vision-Language Learning
2024 · 3 papers
-
CoT3DRef: Chain-of-Thoughts Data-Efficient 3D Visual Grounding

-
L3GO: Language Agents with Chain-of-3D-Thoughts for Generating Unconventional Objects
-
3D-PreMise: Can Large Language Models Generate 3D Shapes with Sharp Features and Parametric Control?
2023 · 1 papers

MCoT Reasoning Over Audio and Speech
2025 · 6 papers
-
ThinkSound: Chain-of-Thought Reasoning in Multimodal Large Language Models for Audio Generation and Editing
-
Audio-Thinker: Guiding Audio Language Model When and How to Think via Reinforcement Learning
-
Audio-Reasoner: Improving Reasoning Capability in Large Audio Language Models
-
Audio-CoT: Exploring Chain-of-Thought Reasoning in Large Audio Language Model
-
Both Ears Wide Open: Towards Language-Driven Spatial Audio Generation


2024 · 2 papers
-
CoT-ST: Enhancing LLM-based Speech Translation with Multimodal Chain-of-Thought

-
SpeechGPT-Gen: Scaling Chain-of-Information Speech Generation

2023 · 2 papers
MCoT Reasoning Over Table and Chart
2025 · 2 papers
-
Multimodal Graph Constrastive Learning and Prompt for ChartQA
-
ReFocus: Visual Editing as a Chain of Thought for Structured Image Understanding

2024 · 2 papers
-
LayoutLLM: Layout Instruction Tuning with Large Language Models for Document Understanding
-
Chain-of-Table: Evolving Tables in the Reasoning Chain for Table Understanding

2023 · 1 papers

Cross-modal CoT Reasoning
2026 · 1 papers
2025 · 1 papers

2024 · 4 papers
-
Multimodal PEAR Chain-of-Thought Reasoning for Multimodal Sentiment Analysis
-
Can Textual Semantics Mitigate Sounding Object Segmentation Preference?

-
AVQA-CoT: When CoT Meets Question Answering in Audio-Visual Scenarios
🔥 MCoT Methodologies
Rationale Construction
MCoT reasoning methodologies primarily concern the construction of rationales and can be categorized into three distinct types: prompt-based, plan-based, and learning-based methods:

- Prompt-based MCoT reasoning employs carefully designed prompts, including instructions or in-context demonstrations, to guide models in generating rationales during inference, typically in zero-shot or few-shot settings.
- Plan-based MCoT reasoning enables models to dynamically explore and refine thoughts during the reasoning process.
-
A Picture Is Worth a Graph: A Blueprint Debate Paradigm for Multimodal Reasoning
-
Soft-Prompting with Graph-of-Thought for Multi-modal Representation Learning
- Learning-based MCoT reasoning embeds rationale construction within the training or fine-tuning process, requiring models to explicitly learn reasoning skills alongside multimodal inputs.

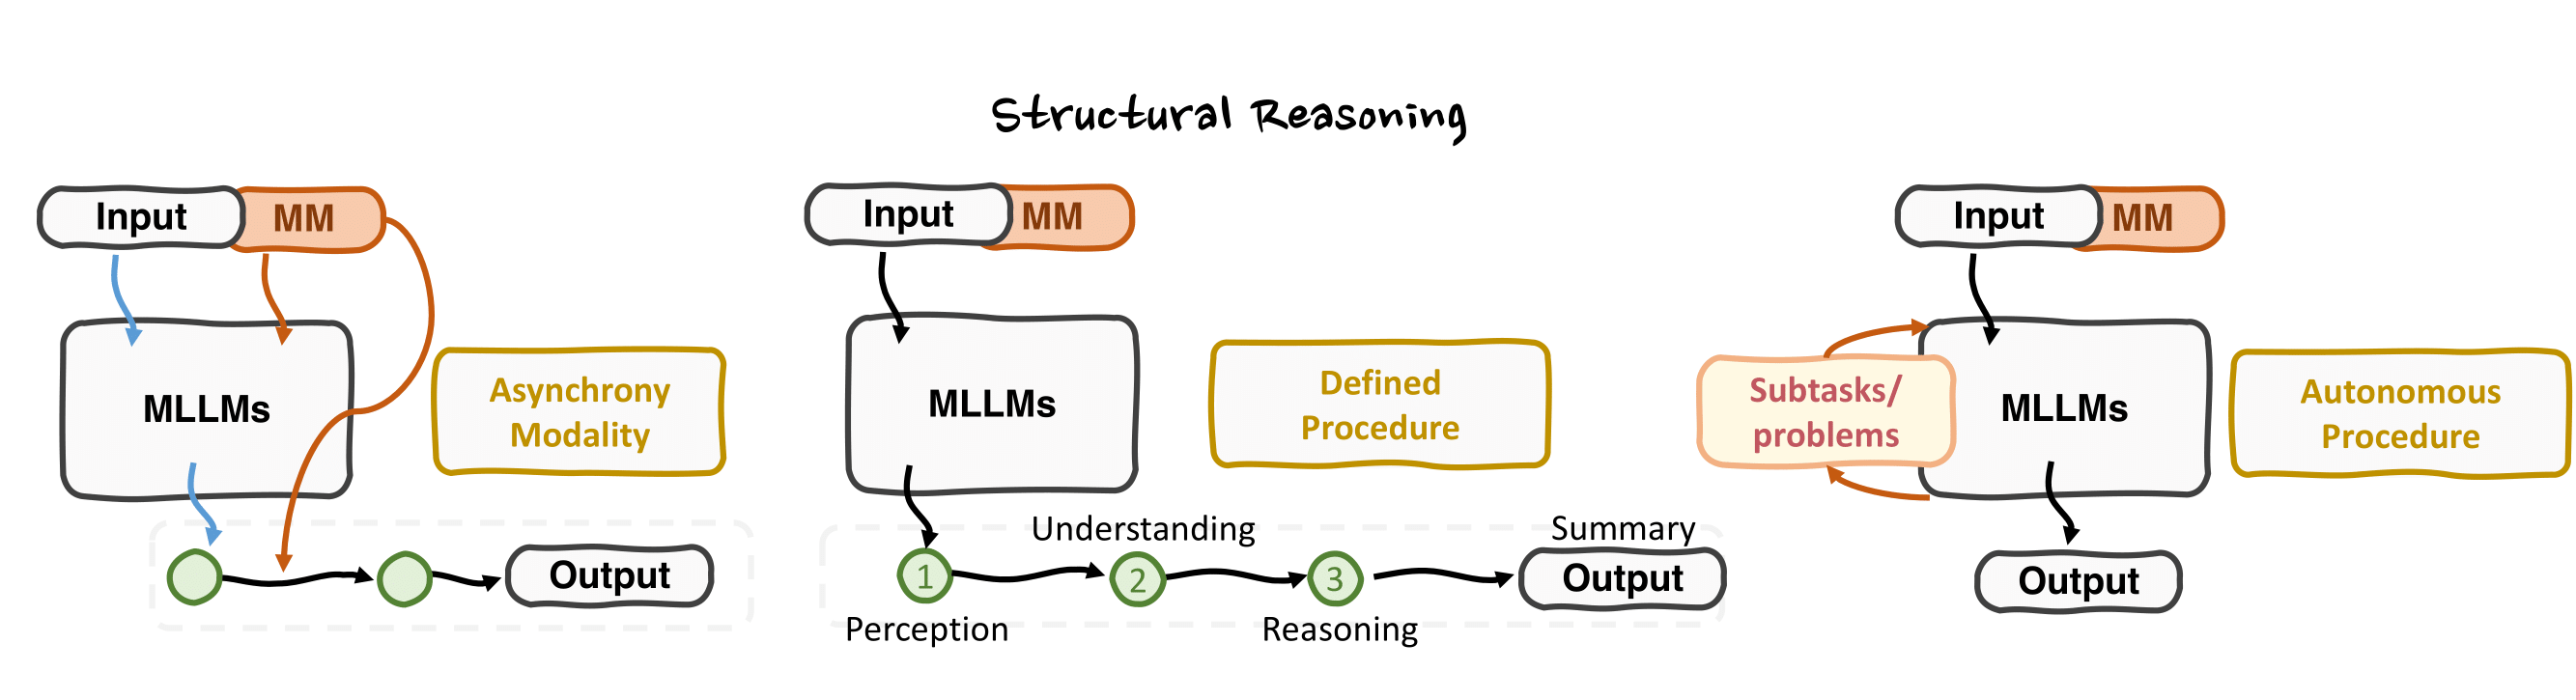
Structural Reasoning
The proposed structural reasoning framework aims to enhance the controllability and interpretability of the rationale generation process. The structured formats can be categorized into three types: asynchronous modality modeling, defined procedure staging, and autonomous procedure staging
-
Thinking Before Looking: Improving Multimodal LLM Reasoning via Mitigating Visual Hallucination

-
DetToolChain: A New Prompting Paradigm to Unleash Detection Ability of MLLM

Information Enhancing
Enhancing multimodal inputs facilitates comprehensive reasoning through the integration of expert tools and internal or external knowledge.

-
Compositional Chain-of-Thought Prompting for Large Multimodal Models
-
AR-MCTS: Progressive Multimodal Reasoning via Active Retrieval
-
DetToolChain: A New Prompting Paradigm to Unleash Detection Ability of MLLM
Objective Granularity

-
Grounded Chain-of-Thought for Multimodal Large Language Models
-
Can Textual Semantics Mitigate Sounding Object Segmentation Preference?
-
Chain-of-Spot: Interactive Reasoning Improves Large Vision-Language Models
Multimodal Rationale
The reasoning processes adopt either text-only or multimodal rationales.


Test-time Scaling

-
VisualPRM: An Effective Process Reward Model for Multimodal Reasoning
-
R1-Zero's "Aha Moment" in Visual Reasoning on a 2B Non-SFT Model
-
Boosting Multimodal Reasoning with MCTS-Automated Structured Thinking
-
RedStar: Does Scaling Long-CoT Data Unlock Better Slow-Reasoning Systems?
-
Marco-o1: Towards Open Reasoning Models for Open-Ended Solutions


🎨 Applications with MCoT Reasoning
Embodied AI
-
Enhancing Multi-Robot Semantic Navigation Through Multimodal Chain-of-Thought Score Collaboration

-
Memory-Driven Multimodal Chain of Thought for Embodied Long-Horizon Task Planning
-
OOTDiffusion: Outfitting Fusion based Latent Diffusion for Controllable Virtual Try-on

-
ManipLLM: Embodied Multimodal Large Language Model for Object-Centric Robotic Manipulation

-
EmbodiedGPT: Vision-Language Pre-Training via Embodied Chain of Thought

-
CoT-VLA: Visual Chain-of-Thought Reasoning for Vision-Language-Action Models
-
FantasyVLN: Unified Multimodal Chain-of-Thought Reasoning for Vision-Language Navigation

Agentic System
-
SmartAgent: Chain-of-User-Thought for Embodied Personalized Agent in Cyber World

-
DreamFactory: Pioneering Multi-Scene Long Video Generation with a Multi-Agent Framework
-
VideoAgent: Long-form Video Understanding with Large Language Model as Agent

-
OpenManus: An open-source framework for building general AI agents
-
RIG: Synergizing Reasoning and Imagination in End-to-End Generalist Policy
-
Web-CogReasoner: Towards Knowledge-Induced Cognitive Reasoning for Web Agents

-
Socratic Questioning: Learn to Self-guide Multimodal Reasoning in the Wild

Autonomous Driving
-
Sce2DriveX: A Generalized MLLM Framework for Scene-to-Drive Learning
-
Learning Autonomous Driving Tasks via Human Feedbacks with Large Language Models
-
Reason2Drive: Towards Interpretable and Chain-based Reasoning for Autonomous Driving

-
Receive, Reason, and React: Drive as You Say with Large Language Models in Autonomous Vehicles
-
DriveCoT: Integrating Chain-of-Thought Reasoning with End-to-End Driving
-
FutureSightDrive: Thinking Visually with Spatio-Temporal CoT for Autonomous Driving
-
DriveAgent-R1: Advancing VLM-based Autonomous Driving with Active Perception and Hybrid Thinking
Medical and Healthcare
-
Interpretable Video based Stress Detection with Self-Refine Chain-of-thought Reasoning
-
Open Set Video HOI detection from Action-centric Chain-of-Look Prompting
-
VILA-M3: Enhancing Vision-Language Models with Medical Expert Knowledge
-
M3CoTBench: Benchmark Chain-of-Thought of MLLMs in Medical Image Understanding
-
TumorChain: Interleaved Multimodal Chain-of-Thought Reasoning for Traceable Cancer Diagnosis

Social and Human
-
Chain-of-Exemplar: Enhancing Distractor Generation for Multimodal Educational Question Generation
-
X-Reflect: Cross-Reflection Prompting for Multimodal Recommendation
-
Multimodal PEAR Chain-of-Thought Reasoning for Multimodal Sentiment Analysis
-
Chain-of-Thought Prompting for Demographic Inference with Large Multimodal Models
-
PanoSent: A Panoptic Sextuple Extraction Benchmark for Multimodal Conversational Aspect-based Sentiment Analysis
Multimodal Generation
-
Can We Generate Images with CoT? Let's Verify and Reinforce Image Generation Step by Step
-
Mastering Text-to-Image Diffusion: Recaptioning, Planning, and Generating with Multimodal LLMs

-
L3GO: Language Agents with Chain-of-3D-Thoughts for Generating Unconventional Objects
-
3D-PreMise: Can Large Language Models Generate 3D Shapes with Sharp Features and Parametric Control?

-
Spatial Chain-of-Thought: Bridging Understanding and Generation Models for Spatial Reasoning
-
EndoCoT: Scaling Endogenous Chain-of-Thought Reasoning in Diffusion Models
-
Thinking Diffusion: Penalize and Guide Visual-Grounded Reasoning in Diffusion Multimodal LLMs
🚀 Useful Links
Survey
-
From System 1 to System 2: A Survey of Reasoning Large Language Models
-
Rethinking External Slow-Thinking: From Snowball Errors to Probability of Correct Reasoning
-
Towards Reasoning Era: A Survey of Long Chain-of-Thought for Reasoning Large Language Models
❤️ Citation
We would be honored if this work could assist you, and greatly appreciate it if you could consider starring and citing it:
@article{wang2025multimodal,
  title={Multimodal chain-of-thought reasoning: A comprehensive survey},
  author={Wang, Yaoting and Wu, Shengqiong and Zhang, Yuecheng and Yan, Shuicheng and Liu, Ziwei and Luo, Jiebo and Fei, Hao},
  journal={arXiv preprint arXiv:2503.12605},
  year={2025}
}