

:sunglasses: Awesome 3D and 4D World Models
 |
|---|
This survey reviews state-of-the-art 3D and 4D world models - systems that learn, predict, and simulate the geometry and dynamics of real environments from multi-modal signals.
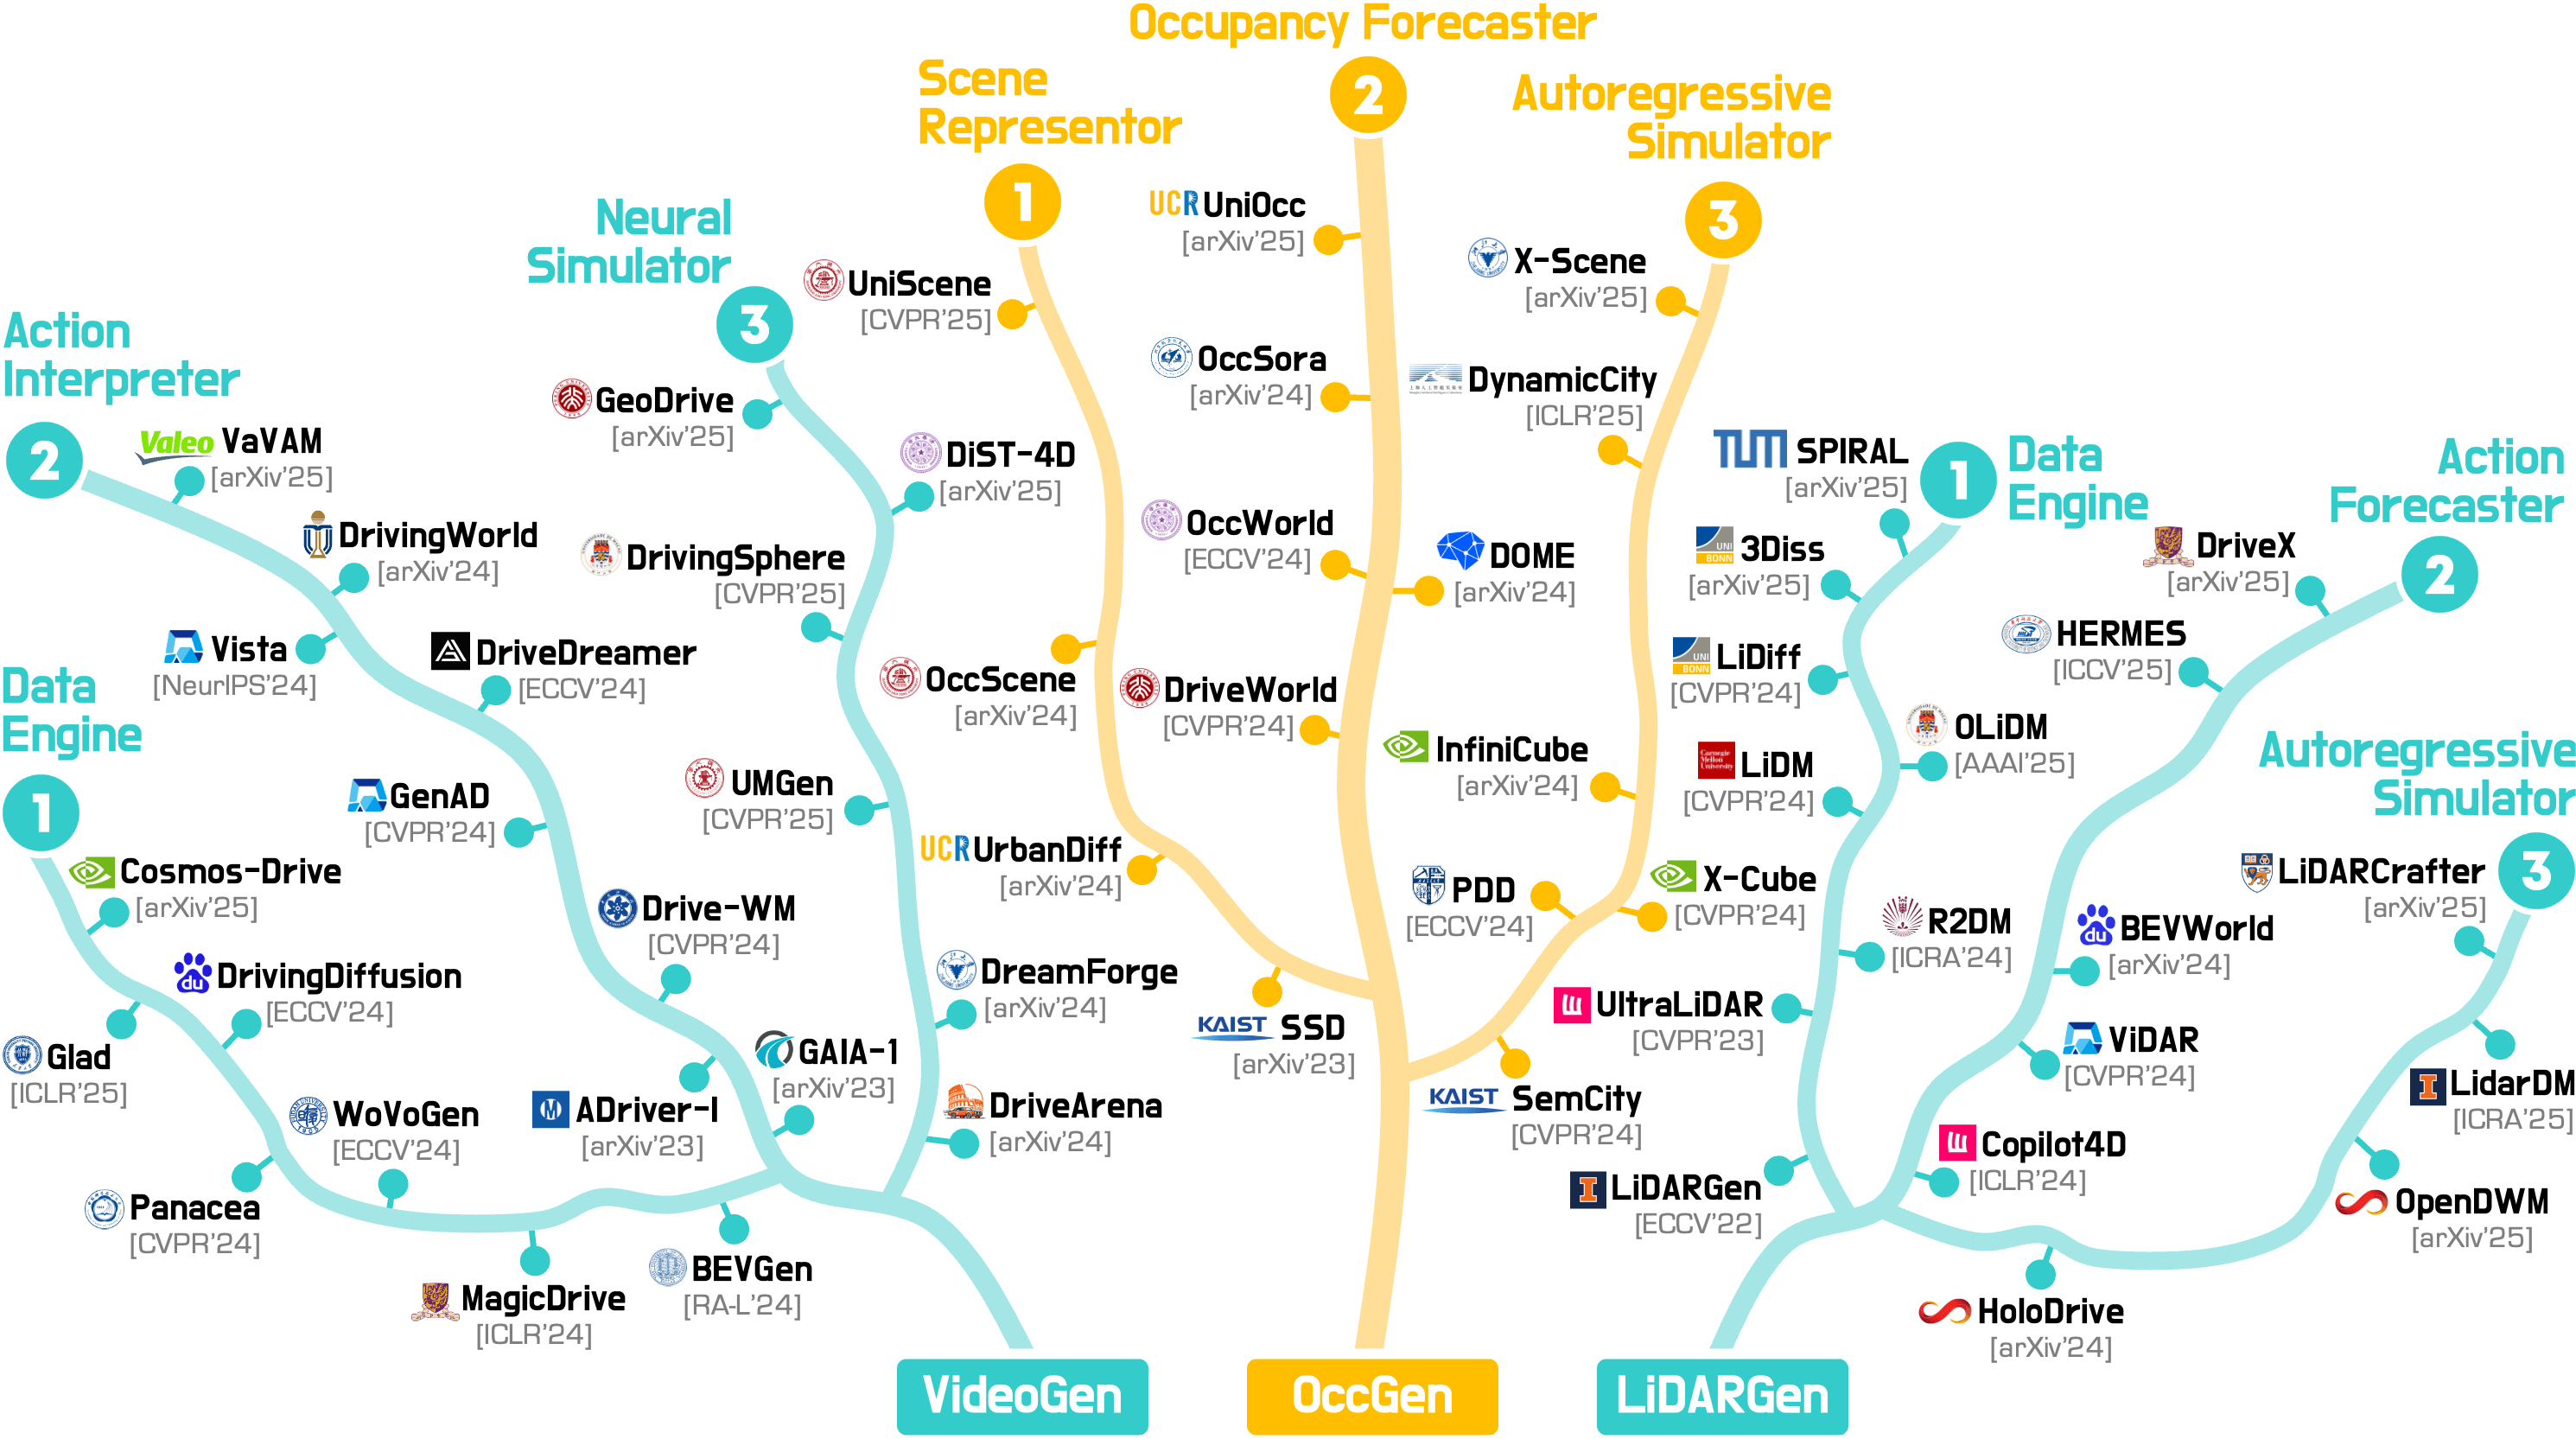
We unify terminology, scope, and evaluations, and organize the space into three complementary paradigms by representation:
 |
Learn generative or predictive models from sequential video streams with geometric and temporal constraints. VideoGen focuses on long-horizon consistency, controllability, and scene-level generation, enabling agents to imagine or forecast plausible video rollouts. |
 |
Model 3D/4D occupancy grids that encode geometry and semantics in voxel space. OccGen provides a physics-consistent scaffold for robust perception, forecasting, and simulation, bridging low-level sensor data and high-level reasoning. |
 |
Leverage point cloud sequences from LiDAR sensors to generate or predict geometry-grounded scenes. LiDARGen emphasizes high-fidelity 3D structure, robustness to environment changes, and applications in safety-critical domains such as autonomous driving. |
For more details, kindly refer to our paper and project page. :rocket:
:books: Citation
If you find this work helpful for your research, please kindly consider citing our papers:
@article{survey_3d_4d_world_models,
    title   = {{3D} and {4D} World Modeling: A Survey},
    author  = {Lingdong Kong and Yu Yang and Jianbiao Mei and Youquan Liu and Ao Liang and Dekai Zhu and Dongyue Lu and Wei Yin and Xiaotao Hu and Mingkai Jia and Junyuan Deng and Kaiwen Zhang and Yang Wu and Tianyi Yan and Shenyuan Gao and Song Wang and Linfeng Li and Liang Pan and Yong Liu and Jianke Zhu and Wei Tsang Ooi and Steven C. H. Hoi and Ziwei Liu},
    journal = {arXiv preprint arXiv:2509.07996},
    year    = {2025}
}
@inproceedings{worldlens,
    title     = {{WorldLens}: Full-Spectrum Evaluations of Driving World Models in Real World},
    author    = {Ao Liang and Lingdong Kong and Tianyi Yan and Hongsi Liu and Wesley Yang and Ziqi Huang and Wei Yin and Jialong Zuo and Yixuan Hu and Dekai Zhu and Dongyue Lu and Youquan Liu and Guangfeng Jiang and Linfeng Li and Xiangtai Li and Long Zhuo and Lai Xing Ng and Benoit R. Cottereau and Changxin Gao and Liang Pan and Wei Tsang Ooi and Ziwei Liu},
    booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
    pages     = {36385-36399},
    year      = {2026}
}
Table of Contents
- Background
- 1. Benchmarks & Datasets
- 2. World Modeling from Video Generation
- 3. World Modeling from Occupancy Generation
- 4. World Modeling from LiDAR Generation
- 5. Applications
- 6. Other Resources
- 7. Acknowledgements
Background
 |
World modeling has become a cornerstone of modern AI, enabling agents to understand, represent, and predict dynamic environments. While prior research has focused primarily on 2D images and videos, the rapid emergence of native 3D and 4D representations (e.g., RGB-D, occupancy grids, LiDAR point clouds) calls for a dedicated study. |
What Are Native 3D Representations?
Unlike 2D projections, native 3D/4D signals directly encode metric geometry, visibility, and motion in the physical coordinates where agents act. Examples include:
- RGB-D imagery (2D images with depth channels)
- Occupancy grids (voxelized maps of free vs. occupied space)
- LiDAR point clouds (3D coordinates from active sensing)
- Neural fields (e.g., NeRF, Gaussian Splatting)
What Are World Models in 3D and 4D?
A 3D/4D world model is an internal representation that allows an agent to imagine, forecast, and interact with its environment in the 3D space.
 |
Generative World Models: |
| synthesize plausible 3D/4D worlds under conditions (e.g., text prompts, trajectories). | |
 |
Predictive World Models: |
| anticipate the future evolution of 3D/4D scenes given past observations and actions. | |
Together, these models provide the foundation for simulation, planning, and embodied intelligence in complex environments.
 |
|---|
1. Benchmarks & Datasets
Benchmarks
 |
 |
 |
|---|---|---|
| WorldLens | VBench | WorldScore |
Workshops
| Theme | Venue | Date | Location | Recording |
|---|---|---|---|---|
| Workshop on 4D World Models: Bridging Generation and Reconstruction | CVPR 2026 | TBD | Denver | - |
| The 2nd Workshop on World Models | ICLR 2026 | April 23, 2026 | Rio de Janeiro | - |
| Workshop on World Modeling | - | February 4-6, 2026 | Montréal | - |
| Workshop on Embodied World Models for Decision Making | NeurIPS 2025 | December 6, 2025 | San Diego | - |
| Workshop on Reliable and Interactable World Models: Geometry, Physics, Interactivity and Real-World Generalization | ICCV 2025 | October 19, 2025 | Hawai'i | - |
| Workshop on Building Physically Plausible World Models | ICML 2025 | July 19, 2025 | Vancouver | - |
| Workshop on Assessing World Models | ICML 2025 | July 18, 2025 | Vancouver | - |
| Workshop on Benchmarking World Models | CVPR 2025 | June 12, 2025 | Nashville | - |
| Workshop on World Models: Understanding, Modelling and Scaling | ICLR 2025 | April 28, 2025 | Singapore | - |
| Workshop on Foundation Models for Autonomous Systems | CVPR 2024 | June 17, 2025 | Seattle | [YouTube] |
Datasets
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website |
|---|---|---|---|
RoboPhys-3D |
|||
| RoboPhys-3D: A Comprehensive Embodied World Model Evaluation via 3D Reconstruction | arXiv 2026 | - | |
VehDyn |
|||
| VehDyn: A Driving World Model Benchmark for Vehicle Dynamics | arXiv 2026 | - | |
Graph LiDAR Diagnostics |
|||
| Geometry vs Structure: Graph-Based Diagnostics for LiDAR Point-Cloud Simulation Fidelity | arXiv 2026 | - | |
M3ISR |
|||
| M$^3$ISR: A Multi-Modal Multi-View Benchmark for 3D/4D Gaussian Splatting and Feedforward Compression | arXiv 2026 | - | |
SIREN |
|||
| SIREN-Bench: Behavior-Driven Generation and Evaluation of Emergency-Vehicle Interactions | arXiv 2026 | - | |
V2XBench |
|||
| Roadside-Cooperative Autonomous Driving: From Data Platform to Vision-Language End-to-End Reasoning | arXiv 2026 | - | |
PAWBench |
|||
| PAWBench: How Far Are We from Probabilistically Aligned World Modeling? | arXiv 2026 | - | |
R2M-Bench |
|||
| R2M-Bench: Evaluating Revisit Memory via Relative Consistency in Interactive Video World Models | arXiv 2026 | - | |
WM-Break |
|||
| Where World Models Break: Natural-Input Failure Discovery | arXiv 2026 | - | |
CG |
|||
| CG-World: A Large-Scale World-State Dataset and Protocol for World Models | arXiv 2026 | - | |
Apple |
|||
| Apple-$π$: Benchmarking Thinking with Video Towards Law-Grounded Physical Intelligence | arXiv 2026 | - | |
Thinking |
|||
| Thinking in Video: Can Video Generators Really Reason About the Real World? | arXiv 2026 | - | |
WorldExam |
|||
| WorldExam: Benchmarking World Models from Apparent Appearance to Inherent Reactivity | arXiv 2026 | - | |
GAUGE |
|||
| GAUGE: A Measurement-Grounded Benchmark for Physical Fidelity in Simulation Engines and Video World Models | arXiv 2026 | - | |
KITTI |
Are We Ready for Autonomous Driving? The KITTI Vision Benchmark Suite | CVPR 2012 | |
NYUv2 |
Indoor Segmentation and Support Inference from RGBD Images | ECCV 2012 | |
CARLA |
|||
| CARLA: An Open Urban Driving Simulator | CoRL 2017 | ||
SemanticKITTI |
|||
| SemanticKITTI: A Dataset for Semantic Scene Understanding of LiDAR Sequences | ICCV 2019 | ||
nuScenes |
|||
| nuScenes: A Multimodal Dataset for Autonomous Driving | CVPR 2020 | ||
Waymo Open |
|||
| Scalability in Perception for Autonomous Driving: Waymo Open Dataset | CVPR 2020 | ||
STF |
|||
| Seeing Through Fog Without Seeing Fog: Deep Multimodal Sensor Fusion in Unseen Adverse Weather | CVPR 2020 | ||
Virtual KITTI 2 |
|||
| Virtual KITTI 2 | arXiv 2020 | ||
Argoverse 2 |
|||
| Argoverse 2: Next Generation Datasets for Self-Driving Perception and Forecasting | NeurIPS 2021 | ||
Lyft-Level5 |
|||
| One Thousand and One Hours: Self-Driving Motion Prediction Dataset | CoRL 2021 | ||
nuPlan |
|||
| nuPlan: A Closed-Loop ML-Based Planning Benchmark for Autonomous Vehicles | CVPRW 2021 | ||
PandaSet |
|||
| PandaSet: Advanced Sensor Suite Dataset for Autonomous Driving | ITSC 2022 | ||
OpenCOOD |
|||
| OPV2V: An Open Benchmark Dataset and Fusion Pipeline for Perception with Vehicle-to-Vehicle Communication | ICRA 2022 | ||
KITTI-360 |
|||
| KITTI-360: A Novel Dataset and Benchmarks for Urban Scene Understanding in 2D and 3D | TPAMI 2022 | ||
CarlaSC |
|||
| MotionSC: Data Set and Network for Real-Time Semantic Mapping in Dynamic Environments | RA-L 2022 | ||
Robo3D |
|||
| Robo3D: Towards Robust and Reliable 3D Perception against Corruptions | ICCV 2023 | ||
OpenOccupancy |
|||
| OpenOccupancy: A Large Scale Benchmark for Surrounding Semantic Occupancy Perception | ICCV 2023 | ||
Occ3D-nuScenes |
|||
| Occ3D: A Large-Scale 3D Occupancy Prediction Benchmark for Autonomous Driving | NeurIPS 2023 | ||
OpenDV-YouTube |
|||
| GenAD: Generalized Predictive Model for Autonomous Driving | CVPR 2024 | ||
SSCBench |
|||
| SSCBench: A Large-Scale 3D Semantic Scene Completion Benchmark for Autonomous Driving | IROS 2024 | ||
NAVSIM |
|||
| NAVSIM: Data-Driven Non-Reactive Autonomous Vehicle Simulation and Benchmarking | NeurIPS 2024 | ||
DrivingDojo |
|||
| DrivingDojo Dataset: Advancing Interactive and Knowledge-Enriched Driving World Model | NeurIPS 2024 | ||
EUVS |
|||
| Extrapolated Urban View Synthesis Benchmark | ICCV 2025 | ||
Pi3DET |
|||
| Perspective-Invariant 3D Object Detection | ICCV 2025 | ||
DrivingGen |
|||
| DrivingGen: A Comprehensive Benchmark for Generative Video World Models in Autonomous Driving | arXiv 2026 | - | |
World-in-World |
|||
| World-in-World: World Models in a Closed-Loop World | arXiv 2025 | - | |
4DWorldBench |
|||
| 4DWorldBench: A Comprehensive Evaluation Framework for 3D/4D World Generation Models | arXiv 2025 | - | |
DriveE2E |
|||
| DriveE2E: Closed-Loop Benchmark for End-to-End Autonomous Driving through Real-to-Simulation | arXiv 2025 | - | |
nuPlan-R |
|||
| nuPlan-R: A Closed-Loop Planning Benchmark for Autonomous Driving via Reactive Multi-Agent Simulation | arXiv 2025 | - | |
ReactSim-Bench |
|||
| ReactSim-Bench: Benchmarking Reactive Behavior World Model Simulation in Autonomous Driving | arXiv 2026 | - | |
Nuplan-Occ |
|||
| Scaling Up Occupancy-centric Driving Scene Generation: Dataset and Method | arXiv 2025 | - | |
4DLidarOpen |
|||
| 4DLidarOpen: An Open 4D FMCW Lidar Dataset for Motion-Aware Autonomous Driving | arXiv 2026 | - | |
OccInteract-85k |
|||
| OccDirector: Language-Guided Behavior and Interaction Generation in 4D Occupancy Space | arXiv 2026 | - | |
TerraZero |
|||
| TerraZero: Procedural Driving Simulation for Zero-Demonstration Self-Play at Scale | arXiv 2026 | - | |
Admissibility |
|||
| Validate the Dream Before You Trust Its Verdict: Admissibility for World-Model Simulators | arXiv 2026 | - | |
Seriality Gap |
|||
| The Seriality Gap in Video Diffusion Models | arXiv 2026 | - | |
VISA |
|||
| VISA: VLM-Guided Instance Semantic Auditing for 3D Occupancy World Models | arXiv 2026 | - |
2. World Modeling from Video Generation
:one: Data Engines
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
HelloWorld (Driving) |
||||
| HelloWorld: Towards Practical Applications of Generative Driving World Models | arXiv 2026 | Project | - | |
4Director |
||||
| 4Director: Controlling Video World Models with Rigid 3D Geometry | arXiv 2026 | Project | - | |
MIVIFI |
||||
| MIVIFI: Bridging Perspective and Fisheye Domains for Training Multi-View Fisheye Image Generation Models | arXiv 2026 | - | - | |
SpatialCrafter |
||||
| SpatialCrafter: Single Image World Modeling with Generative 3D Proxies | arXiv 2026 | Project | - | |
4DStreamCtrl |
||||
| 4DStreamCtrl: Interactive Video Generation with Online 4D Control | arXiv 2026 | Project | - | |
ReWorld |
||||
| ReWorld: An Interactive World Model with Long-Horizon Memory | arXiv 2026 | - | - | |
NeoWorld-Pro |
||||
| NeoWorld-Pro: Programming Interactive Scenes from Monocular Images for Embodied Simulation | arXiv 2026 | - | - | |
MiniWorld |
||||
| MiniWorld: Democratizing the Training of Video World Models from Scratch | arXiv 2026 | - | - | |
RealWeather |
||||
| RealWeather: Realistic and Scene-Faithful Weather Translation with Driving World Models | arXiv 2026 | - | - | |
muSync |
||||
| muSync-GS: Physics-Synchronized Driving Video Synthesis for Weather and Geometric Road Hazards | arXiv 2026 | - | - | |
ABot |
||||
| ABot-3DWorld 0: A Universal World Model to Explore Any 3D Space | arXiv 2026 | - | - | |
Sekai2 |
||||
| Sekai2: From World Exploration to Interactive World Modeling | arXiv 2026 | - | - | |
Xiaomi |
||||
| Xiaomi-Robotics-U0: Unified Embodied Synthesis with World Foundation Model | arXiv 2026 | - | - | |
EmbodiedVAE |
||||
| EmbodiedVAE: Disentangled Video VAE for Efficient and Controllable Embodied Manipulation | arXiv 2026 | - | - | |
H2R |
||||
| H2R-Bench: Benchmarking Human-to-Robot Manipulation Video Generation in World Models | arXiv 2026 | - | - | |
BEVControl |
||||
| BEVControl: Accurately Controlling Street-View Elements with Multi-Perspective Consistency via BEV Sketch Layout | arXiv 2023 | - | - | |
BEVGen |
||||
| Street-View Image Generation from a Bird's-Eye View Layout | RA-L 2024 | |||
MagicDrive |
||||
| MagicDrive: Street View Generation with Diverse 3D Geometry Control | ICLR 2024 | |||
Panacea |
||||
| Panacea: Panoramic and Controllable Video Generation for Autonomous Driving | CVPR 2024 | |||
DrivingDiffusion |
||||
| DrivingDiffusion: Layout-Guided Multi-View Driving Scene Video Generation with Latent Diffusion Model | ECCV 2024 | |||
WoVoGen |
||||
| WoVoGen: World Volume-Aware Diffusion for Controllable Multi-Camera Driving Scene Generation | ECCV 2024 | - | ||
Delphi |
||||
| Unleashing Generalization of End-to-End Autonomous Driving with Controllable Long Video Generation | arXiv 2024 | |||
SimGen |
||||
| SimGen: Simulator-Conditioned Driving Scene Generation | NeurIPS 2024 | |||
BEVWorld |
||||
| BEVWorld: A Multimodal World Simulator for Autonomous Driving via Scene-Level BEV Latents | arXiv 2024 | - | - | |
Panacea+ |
||||
| Panacea+: Panoramic and Controllable Video Generation for Autonomous Driving | arXiv 2024 | - | ||
DiVE |
||||
| DiVE: DiT-Based Video Generation with Enhanced Control | arXiv 2024 | |||
MyGo |
||||
| MyGo: Consistent and Controllable Multi-View Driving Video Generation with Camera Control | arXiv 2024 | - | - | |
SyntheOcc |
||||
| SyntheOcc: Synthesize Geometric-Controlled Street View Images through 3D Semantic MPIs | arXiv 2024 | |||
HoloDrive |
||||
| HoloDrive: Holistic 2D-3D Multi-Modal Street Scene Generation for Autonomous Driving | arXiv 2024 | - | - | |
CogDriving |
||||
| Seeing Beyond Views: Multi-View Driving Scene Video Generation with Holistic Attention | arXiv 2024 | - | ||
UniMLVG |
||||
| UniMLVG: Unified Framework for Multi-View Long Video Generation with Comprehensive Control Capabilities for Autonomous Driving | arXiv 2024 | - | ||
DrivePhysica |
||||
| Physical Informed Driving World Model | arXiv 2024 | - | ||
DriveDreamer-2 |
||||
| DriveDreamer-2: LLM-Enhanced World Models for Diverse Driving Video Generation | AAAI 2025 | |||
SubjectDrive |
||||
| SubjectDrive: Scaling Generative Data in Autonomous Driving via Subject Control | AAAI 2025 | - | ||
Glad |
||||
| Glad: A Streaming Scene Generator for Autonomous Driving | ICLR 2025 | - | ||
DualDiff |
||||
| DualDiff: Dual-Branch Diffusion Model for Autonomous Driving with Semantic Fusion | ICRA 2025 | - | ||
UniScene |
||||
| UniScene: Unified Occupancy-Centric Driving Scene Generation | CVPR 2025 | |||
DriveScape |
||||
| DriveScape: Towards High-Resolution Controllable Multi-View Driving Video Generation | CVPR 2025 | - | ||
PerLDiff |
||||
| PerLDiff: Controllable Street View Synthesis Using Perspective-Layout Diffusion Models | ICCV 2025 | |||
MagicDrive-V2 |
||||
| MagicDrive-V2: High-Resolution Long Video Generation for Autonomous Driving with Adaptive Control | ICCV 2025 | - | ||
DINO-Foresight |
||||
| DINO-Foresight: Looking into the Future with DINO | NeurIPS 2025 | |||
Cosmos-Transfer1 |
||||
| Cosmos-Transfer1: Conditional World Generation with Adaptive Multimodal Control | arXiv 2025 | |||
DualDiff+ |
||||
| DualDiff+: Dual-Branch Diffusion for High-Fidelity Video Generation with Reward Guidance | arXiv 2025 | - | ||
CoGen |
||||
| CoGen: 3D Consistent Video Generation via Adaptive Conditioning for Autonomous Driving | arXiv 2025 | - | ||
NoiseController |
||||
| NoiseController: Towards Consistent Multi-View Video Generation via Noise Decomposition and Collaboration | arXiv 2025 | - | - | |
STAGE |
||||
| STAGE: A Stream-Centric Generative World Model for Long-Horizon Driving-Scene Simulation | arXiv 2025 | - | - | |
WMReward |
||||
| Inference-time Physics Alignment of Video Generative Models with Latent World Models | arXiv 2026 | - | - | |
AutoScape |
||||
| AutoScape: Geometry-Consistent Long-Horizon Scene Generation | arXiv 2025 | - | - | |
Rethinking-DWM |
||||
| Rethinking Driving World Model as Synthetic Data Generator for Perception Tasks | arXiv 2025 | - | - | |
OmniDrive |
||||
| OmniDrive: An LLM-Choreographed Multi-Agent World Model with Unified Latent Co-Compression for Multi-View Driving Video Generation | arXiv 2026 | - | - | |
OpenLongTail |
||||
| OpenLongTail: Generative Scaling of Long-Tail Driving Data | arXiv 2026 | - | - | |
OmniSCS |
||||
| OmniSCS: Omni Safety-Critical Scenario Synthesis for Autonomous Driving via a Fully Editable Driving World | arXiv 2026 | - | - | |
DriveWeaver |
||||
| DriveWeaver: Point-Conditioned Video Inpainting for Controllable Vehicle Insertion in Autonomous Driving Simulation | arXiv 2026 | - | - | |
:two: Action Interpreters
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
CoDrive |
||||
| CoDrive: Cross-Vehicle World-Consistent Video Generation with Precise Trajectory Control for Cooperative Driving | arXiv 2026 | Project | - | |
SA-WAM |
||||
| Spatially Aware World Action Model via Geometric Latent Diffusion | arXiv 2026 | Project | - | |
UniDynamics |
||||
| UniDynamics: Event-RGB Fusion for Unified Future 4D Dynamic Scene Generation | arXiv 2026 | - | - | |
GeoWAM |
||||
| GeoWAM: Visual Geometry World Action Models for Autonomous Driving | arXiv 2026 | - | - | |
4DGS-WAM |
||||
| 4DGS-WAM: Bridging Past and Future with an Object-Centric World Action Model based on 4D Gaussian Splatting | arXiv 2026 | - | - | |
WALL-SS |
||||
| WALL-SS: Scaling Long-horizon World Models via Next-Scale Autoregression | arXiv 2026 | - | - | |
Cycle |
||||
| Cycle-World: Mitigating Error Accumulation in Long-term Video World Models via Reverse-Prediction Cycle Consistency | arXiv 2026 | - | - | |
Adaptive |
||||
| Adaptive-WAM: Quality-Guided Early-Exit Planning from Intermediate Video-Diffusion Features | arXiv 2026 | - | - | |
ForgeWM |
||||
| ForgeWM: Progressive Causal Training for Few-Step Action-Conditioned Video World Models | arXiv 2026 | - | - | |
DriveCache |
||||
| DriveCache: Action-Aware Caching for Driving World Model Inference | arXiv 2026 | - | - | |
ContactFlow |
||||
| ContactFlow: A video action conditioning that transfers across embodiments | arXiv 2026 | - | - | |
GeniWorld |
||||
| GeniWorld: A Generalizable Interactive World Model for Robotic Manipulation via Visual Actions | arXiv 2026 | - | - | |
DreamX |
||||
| DreamX-Phi 1.0: Action-Conditioned Video World Model for Robotic Manipulation | arXiv 2026 | - | - | |
GAIA-1 |
||||
| GAIA-1: A Generative World Model for Autonomous Driving | arXiv 2023 | - | ||
ADriver-I |
||||
| ADriver-I: A General World Model for Autonomous Driving | arXiv 2023 | - | - | |
Drive-WM |
||||
| Driving into the Future: Multiview Visual Forecasting and Planning with World Model for Autonomous Driving | CVPR 2024 | |||
DriveDreamer |
||||
| DriveDreamer: Towards Real-World-Driven World Models for Autonomous Driving | ECCV 2024 | |||
GenAD |
||||
| GenAD: Generalized Predictive Model for Autonomous Driving | CVPR 2024 | - | ||
GenAD (Gen-E2E) |
||||
| GenAD: Generative End-to-End Autonomous Driving | ECCV 2024 | - | - | |
Vista |
||||
| Vista: A Generalizable Driving World Model with High Fidelity and Versatile Controllability | NeurIPS 2024 | |||
InfinityDrive |
||||
| InfinityDrive: Breaking Time Limits in Driving World Models | arXiv 2024 | - | ||
DrivingGPT |
||||
| DrivingGPT: Unifying Driving World Modeling and Planning with Multi-Modal Autoregressive Transformers | arXiv 2024 | - | ||
DrivingWorld |
||||
| DrivingWorld: Constructing World Model for Autonomous Driving via Video GPT | arXiv 2024 | |||
GEM |
||||
| GEM: A Generalizable Ego-Vision Multimodal World Model for Fine-Grained Ego-Motion, Object Dynamics, and Scene Composition Control | CVPR 2025 | |||
MaskGWM |
||||
| MaskGWM: A Generalizable Driving World Model with Video Mask Reconstruction | CVPR 2025 | - | ||
Epona |
||||
| Epona: Autoregressive Diffusion World Model for Autonomous Driving | ICCV 2025 | |||
VaViM & VaVAM |
||||
| VaViM and VaVAM: Autonomous Driving through Video Generative Modeling | arXiv 2025 | |||
MiLA |
||||
| MiLA: Multi-View Intensive-Fidelity Long-Term Video Generation World Model for Autonomous Driving | arXiv 2025 | - | ||
GAIA-2 |
||||
| GAIA-2: A Controllable Multi-View Generative World Model for Autonomous Driving | arXiv 2025 | - | ||
Ego-Other-WM |
||||
| Other Vehicle Trajectories Are Also Needed: A Driving World Model Unifies Ego-Other Vehicle Trajectories in Video Latent Space | arXiv 2025 | - | - | |
DriVerse |
||||
| DriVerse: Navigation World Model for Driving Simulation via Multimodal Trajectory Prompting and Motion Alignment | arXiv 2025 | - | - | |
PosePilot |
||||
| PosePilot: Steering Camera Pose for Generative World Models with Self-Supervised Depth | arXiv 2025 | - | - | |
ProphetDWM |
||||
| ProphetDWM: A Driving World Model for Rolling Out Future Actions and Videos | arXiv 2025 | - | - | |
LongDWM |
||||
| LongDWM: Cross-Granularity Distillation for Building A Long-Term Driving World Model | arXiv 2025 | |||
UniDrive-WM |
||||
| UniDrive-WM: Unified Understanding, Planning and Generation World Model For Autonomous Driving | arXiv 2026 | - | ||
DriveVA |
||||
| DriveVA: Video Action Models are Zero-Shot Drivers | ECCV 2026 | - | ||
DeepSight |
||||
| DeepSight: Long-Horizon World Modeling via Latent States Prediction for End-to-End Autonomous Driving | arXiv 2026 | - | - | |
:three: Neural Simulators
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
WorldWeave |
||||
| WorldWeave: Growing Persistent Geometric Worlds for Video Generation | arXiv 2026 | - | - | |
WorldCrafter |
||||
| WorldCrafter: Consistent Video World Model with Implicit 3D-aware Memory | arXiv 2026 | - | - | |
NeuIDO |
||||
| NeuIDO: Neural Intrinsic Dynamics Operator for Physics-Informed 4D World Models | arXiv 2026 | - | - | |
VideoTok4D |
||||
| VideoTok4D: A 4D-Aware Video Tokenizer for Compact World Representation | arXiv 2026 | - | - | |
TourPhysics |
||||
| TourPhysics: Bringing Physics to World Models for Exploration and Manipulation from a Single Image | arXiv 2026 | - | - | |
SPVC |
||||
| SPVC: Structured and Panoptic Video Fixing for Cross-Dataset Driving Scene Rendering | arXiv 2026 | - | - | |
4DSynth |
||||
| 4DSynth: Controllable Procedural World Synthesis for Dynamic Embodied Simulation | arXiv 2026 | - | - | |
BehaviorWorldGen |
||||
| BehaviorWorldGen: Closing the Loop between Action Models and World Simulators via Controllable Behavior-Aware Structured World Generation | arXiv 2026 | - | - | |
CLAP |
||||
| CLAP: Cross-Embodiment Video World Models are Zero-Shot Physical Simulators | arXiv 2026 | - | - | |
From |
||||
| From Pixels to States: Rethinking Interactive World Models as Game Engines | arXiv 2026 | - | - | |
Streaming |
||||
| Streaming Multi-Agent Autoregressive Diffusion Model with World State Registers | arXiv 2026 | - | - | |
Population |
||||
| Population-Scalable Multi-Agent World Modeling | arXiv 2026 | - | - | |
Wonder |
||||
| Wonder: Video World Model Done Better | arXiv 2026 | - | - | |
Mitigating |
||||
| Mitigating Compounding Error via Video Representation Regularization | arXiv 2026 | - | - | |
HelloWorld |
||||
| HelloWorld: Enabling Socially Interactive Characters in Video World Models | arXiv 2026 | - | - | |
CrossScope |
||||
| CrossScope: A Role-Asymmetric World Model for Joint Dual-Scope Surgical Video Prediction | arXiv 2026 | - | - | |
Surg |
||||
| Surg-UniWorld: A Unified Surgical World Model with Multimodal Control Experts | arXiv 2026 | - | - | |
Stream4D |
||||
| Stream4D: 4D-Consistency for Streaming Autoregressive Diffusion Video Models | arXiv 2026 | - | - | |
Closing |
||||
| Closing the Loop: Training-Free Revisit Consistency for Autoregressive Generative Rendering | arXiv 2026 | - | - | |
MagicDrive3D |
||||
| MagicDrive3D: Controllable 3D Generation for Any-View Rendering in Street Scenes | arXiv 2024 | |||
DreamForge |
||||
| DreamForge: Motion-Aware Autoregressive Video Generation for Multi-View Driving Scenes | arXiv 2024 | |||
Doe-1 |
||||
| Doe-1: Closed-Loop Autonomous Driving with Large World Model | arXiv 2024 | |||
DrivingSphere |
||||
| DrivingSphere: Building A High-Fidelity 4D World for Closed-Loop Simulation | CVPR 2025 | |||
UMGen |
||||
| Generating Multimodal Driving Scenes via Next-Scene Prediction | CVPR 2025 | |||
DriveArena |
||||
| DriveArena: A Closed-Loop Generative Simulation Platform for Autonomous Driving | ICCV 2025 | |||
InfiniCube |
||||
| InfiniCube: Unbounded and Controllable Dynamic 3D Driving Scene Generation with World-Guided Video Models | ICCV 2025 | |||
DiST-4D |
||||
| DiST-4D: Disentangled Spatiotemporal Diffusion with Metric Depth for 4D Driving Scene Generation | ICCV 2025 | |||
UniFuture |
||||
| Seeing the Future, Perceiving the Future: A Unified Driving World Model for Future Generation and Perception | arXiv 2025 | |||
Nexus |
||||
| Decoupled Diffusion Sparks Adaptive Scene Generation | arXiv 2025 | |||
Challenger |
||||
| Challenger: Affordable Adversarial Driving Video Generation | arXiv 2025 | |||
Cosmos-Drive |
||||
| Cosmos-Drive-Dreams: Scalable Synthetic Driving Data Generation with World Foundation Models | arXiv 2025 | |||
ReSim |
||||
| ReSim: Reliable World Simulation for Autonomous Driving | arXiv 2025 | - | - | |
OmniDreams |
||||
| NVIDIA OmniDreams: Real-Time Generative World Model for Closed-Loop Autonomous Vehicle Simulation | arXiv 2026 | - | - | |
Xiaomi Auto WM |
||||
| Xiaomi Auto World Model: A Joint World Model Integrating Reconstruction and Generation for Autonomous Driving | arXiv 2026 | - | - | |
HERMES++ |
||||
| HERMES++: Toward a Unified Driving World Model for 3D Scene Understanding and Generation | arXiv 2026 | - | - | |
CausalDrive |
||||
| CausalDrive: Real-time Causal World Models for Autonomous Driving | arXiv 2026 | - | - | |
Point-as-Skeleton |
||||
| Point as Skeleton: Accumulated Point Cloud Enhanced Autoregressive Generation for Closed-Loop Autonomous Driving Simulation | arXiv 2026 | - | - | |
Cam2Sim |
||||
| Cam2Sim: Neural Scenario Reconstruction for Closed-Loop Autonomous Driving Simulation | arXiv 2026 | - | - | |
CARLA-GS |
||||
| CARLA-GS: Decoupling Representation, Reasoning, and Physics Simulation for Autonomous Driving Corner-Case Synthesis | arXiv 2026 | - | - | |
:four: Scene Reconstructors
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
RoGSW4RLD |
||||
| RoGSW4RLD: Feed-Forward 4D Gaussian Lifting for Robot World Model Rollouts | arXiv 2026 | - | - | |
PhysReal |
||||
| PhysReal: Learning Real-World Deformable Object Physics via Hybrid Constitutive Modeling | arXiv 2026 | - | - | |
Streaming4D |
||||
| Streaming4D: Accelerate 4D World Models via Block-wise Video Generation and Incremental Reconstruction | arXiv 2026 | - | - | |
M3GD |
||||
| M3GD: Multi-Modal Multi-View Geometric Diffusion for Camera--LiDAR Novel View Synthesis | arXiv 2026 | - | - | |
4DGS-Fixer |
||||
| 4DGS-Fixer: Generative Sparse-View 4D Gaussian Splatting with Iterative Refinement Guided by Video Diffusion Priors | arXiv 2026 | - | - | |
DAV4 |
||||
| Depth Anything V4: Dynamic 4D Scene Reconstruction via Riemannian Flow Matching on 4D Gaussian Splatting | arXiv 2026 | - | - | |
UniQuery4R |
||||
| UniQuery4R: Unified 4D Scene Reconstruction from a Single Query | arXiv 2026 | - | - | |
SceneReGen |
||||
| SceneReGen: Generative Reconstruction of 3D Scenes from a Single Image | arXiv 2026 | - | - | |
Gallileo-4D |
||||
| Gallileo-4D: Frozen Backbone Ensemble for Dynamic 4D Reconstruction | arXiv 2026 | - | - | |
LagrangeGS |
||||
| LagrangeGS: Non-Conservative Lagrangian System on Dynamic 3D Gaussian Splatting | arXiv 2026 | - | - | |
VersaGauss |
||||
| VersaGauss: A Versatile Framework for Generating Multiphase Dynamics with 3D Gaussians | arXiv 2026 | - | - | |
3DGS |
||||
| 3D Gaussian Splatting for Real-Time Radiance Field Rendering | TOG 2023 | |||
StreetGaussian |
||||
| Street Gaussians: Modeling Dynamic Urban Scenes with Gaussian Splatting | ECCV 2024 | |||
4DGF |
||||
| Dynamic 3D Gaussian Fields for Urban Areas | NeurIPS 2024 | |||
SCube |
||||
| SCube: Instant Large-Scale Scene Reconstruction using VoxSplats | NeurIPS 2024 | |||
HUGS |
||||
| HUGS: Holistic Urban 3D Scene Understanding via Gaussian Splatting | CVPR 2024 | |||
MagicDrive3D |
||||
| MagicDrive3D: Controllable 3D Generation for Any-View Rendering in Street Scenes | arXiv 2024 | |||
S3Gaussian |
||||
| S3Gaussian: Self-Supervised Street Gaussians for Autonomous Driving | arXiv 2024 | |||
VDG |
||||
| VDG: Vision-Only Dynamic Gaussian for Driving Simulation | arXiv 2024 | |||
UniGaussian |
||||
| UniGaussian: Driving Scene Reconstruction from Multiple Camera Models via Unified Gaussian Representations | arXiv 2024 | - | - | |
Stag-1 |
||||
| Stag-1: Towards Realistic 4D Driving Simulation with Video Generation Model | arXiv 2024 | |||
DrivingRecon |
||||
| DrivingRecon: Large 4D Gaussian Reconstruction Model For Autonomous Driving | arXiv 2024 | - | ||
OccScene |
||||
| OccScene: Semantic Occupancy-Based Cross-Task Mutual Learning for 3D Scene Generation | arXiv 2024 | - | - | |
SGD |
||||
| SGD: Street View Synthesis with Gaussian Splatting and Diffusion Prior | WACV 2025 | - | - | |
OmniRe |
||||
| OmniRe: Omni Urban Scene Reconstruction | ICLR 2025 | |||
DriveDreamer4D |
||||
| DriveDreamer4D: World Models Are Effective Data Machines for 4D Driving Scene Representation | CVPR 2025 | |||
DeSiRe-GS |
||||
| DeSiRe-GS: 4D Street Gaussians for Static-Dynamic Decomposition and Surface Reconstruction for Urban Driving Scenes | CVPR 2025 | - | ||
SplatAD |
||||
| SplatAD: Real-Time Lidar and Camera Rendering with 3D Gaussian Splatting for Autonomous Driving | CVPR 2025 | |||
ReconDreamer |
||||
| ReconDreamer: Crafting World Models for Driving Scene Reconstruction via Online Restoration | CVPR 2025 | |||
FreeSim |
||||
| FreeSim: Toward Free-Viewpoint Camera Simulation in Driving Scenes | CVPR 2025 | - | ||
StreetCrafter |
||||
| StreetCrafter: Street View Synthesis with Controllable Video Diffusion Models | CVPR 2025 | |||
FlexDrive |
||||
| FlexDrive: Toward Trajectory Flexibility in Driving Scene Reconstruction and Rendering | CVPR 2025 | - | - | |
S-NeRF++ |
||||
| S-NeRF++: Autonomous Driving Simulation via Neural Reconstruction and Generation | TPAMI 2025 | - | - | |
InfiniCube |
||||
| InfiniCube: Unbounded and Controllable Dynamic 3D Driving Scene Generation with World-Guided Video Models | ICCV 2025 | |||
DiST-4D |
||||
| Disentangled Spatiotemporal Diffusion with Metric Depth for 4D Driving Scene Generation | ICCV 2025 | |||
DreamDrive |
||||
| DreamDrive: Generative 4D Scene Modeling from Street View Images | arXiv 2025 | - | ||
Uni-Gaussians |
||||
| Uni-Gaussians: Unifying Camera and Lidar Simulation with Gaussians for Dynamic Driving Scenarios | arXiv 2025 | - | ||
MuDG |
||||
| MuDG: Taming Multi-Modal Diffusion with Gaussian Splatting for Urban Scene Reconstruction | arXiv 2025 | |||
UniFuture |
||||
| Seeing the Future, Perceiving the Future: A Unified Driving World Model for Future Generation and Perception | arXiv 2025 | |||
SceneCrafter |
||||
| Unraveling the Effects of Synthetic Data on End-to-End Autonomous Driving Humanoid Robots | arXiv 2025 | - | ||
ReconDreamer++ |
||||
| ReconDreamer++: Harmonizing Generative and Reconstructive Models for Driving Scene Representation | arXiv 2025 | |||
RealEngine |
||||
| RealEngine: Simulating Autonomous Driving in Realistic Context | arXiv 2025 | - | ||
GeoDrive |
||||
| GeoDrive: 3D Geometry-Informed Driving World Model with Precise Action Control | arXiv 2025 | - | ||
PseudoSimulation |
||||
| Pseudo-Simulation for Autonomous Driving | arXiv 2025 | - | ||
Dreamland |
||||
| Dreamland: Controllable World Creation with Simulator and Generative Models | arXiv 2025 | - | ||
Diff4Splat |
||||
| Diff4Splat: Controllable 4D Scene Generation with Latent Dynamic Reconstruction Models | arXiv 2025 | |||
SpaceTimePilot |
||||
| SpaceTimePilot: Generative Rendering of Dynamic Scenes Across Space and Time | arXiv 2025 | |||
FLAG-4D |
||||
| FLAG-4D: Flow-Guided Local-Global Dual-Deformation Model for 4D Reconstruction | arXiv 2026 | - | ||
MotionCrafter |
||||
| MotionCrafter: Dense Geometry and Motion Reconstruction with a 4D VAE | arXiv 2026 | |||
WorldSplat |
||||
| WorldSplat: Gaussian-Centric Feed-Forward 4D Scene Generation for Autonomous Driving | arXiv 2025 | - | - | |
GaussianDWM |
||||
| GaussianDWM: 3D Gaussian Driving World Model for Unified Scene Understanding and Multi-Modal Generation | arXiv 2025 | - | - | |
RealityBridge |
||||
| RealityBridge: Bridging Editable 3D Gaussian Splatting Driving Simulations and Real-World Videos | arXiv 2026 | - | - | |
Adaptive Gaussian Graph |
||||
| Beyond Perfect Priors: Adaptive Gaussian Graph for 4D Driving Reconstruction in the Wild | arXiv 2026 | - | - | |
Glob3R |
||||
| Glob3R: Global Structure-from-Motion with 3D Foundation Models | arXiv 2026 | - | - | |
NoDrift3R |
||||
| NoDrift3R: Raymap-Guided Coupling for Drift-Robust Unposed Feed-Forward 3D Reconstruction | arXiv 2026 | - | - | |
OmniX |
||||
| OmniX: Any-view and Any-time 4D Reconstruction via Feed-forward Trajectory Fields | arXiv 2026 | - | - | |
3. World Modeling from Occupancy Generation
:one: Scene Representors
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
Occupancy Filtering |
||||
| Diagnosing and Dynamically Filtering Occupancy World Models for Active Mapping | arXiv 2026 | - | - | |
GSSC |
||||
| Generative Semantic Scene Completion | arXiv 2026 | - | - | |
GaussianDWM++ |
||||
| GaussianDWM++: Language-Grounded 3D Gaussian Driving World Model for Unified Scene Understanding, Editing, and Multi-Modal Generation | arXiv 2026 | - | - | |
SSD |
||||
| Diffusion Probabilistic Models for Scene-Scale 3D Categorical Data | arXiv 2023 | - | ||
SemCity |
||||
| SemCity: Semantic Scene Generation with Triplane Diffusion | CVPR 2024 | |||
WoVoGen |
||||
| WoVoGen: World Volume-Aware Diffusion for Controllable Multi-Camera Driving Scene Generation | ECCV 2024 | - | ||
UrbanDiff |
||||
| Urban Scene Diffusion through Semantic Occupancy Map | arXiv 2024 | - | ||
OccGen |
||||
| OccGen: Generative Multi-modal 3D Occupancy Prediction for Autonomous Driving | arXiv 2024 | - | - | |
DrivingSphere |
||||
| DrivingSphere: Building A High-Fidelity 4D World for Closed-Loop Simulation | CVPR 2025 | |||
UniScene |
||||
| UniScene: Unified Occupancy-Centric Driving Scene Generation | CVPR 2025 | |||
OccScene |
||||
| OccScene: Semantic Occupancy-Based Cross-Task Mutual Learning for 3D Scene Generation | arXiv 2024 | - | - | |
InfiniCube |
||||
| InfiniCube: Unbounded and Controllable Dynamic 3D Driving Scene Generation with World-Guided Video Models | ICCV 2025 | |||
Control-3D-Scene |
||||
| Controllable 3D Outdoor Scene Generation via Scene Graphs | ICCV 2025 | |||
X-Scene |
||||
| X-Scene: Large-Scale Driving Scene Generation with High Fidelity and Flexible Controllability | arXiv 2025 | |||
GenieDrive |
||||
| GenieDrive: Towards Physics-Aware Driving World Model with 4D Occupancy Guided Video Generation | CVPR 2026 | |||
EditSSC |
||||
| EditSSC: Toward Editable Semantic Occupancy Scenes with Unconditional Diffusion Models | arXiv 2026 | - | - | |
:two: Occupancy Forecasters
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
TriO |
||||
| TriO: Tri-Modal Unsupervised Occupancy World Model for Anything Perception | arXiv 2026 | - | - | |
InterOCF |
||||
| InterOCF: Spatio-Temporal 2D-3D Interaction for Camera-Only 4D Occupancy Forecasting | arXiv 2026 | - | - | |
Geometry |
||||
| Geometry-Aware Spatio-Temporal Context Modeling for 4D Occupancy Forecasting | arXiv 2026 | - | - | |
Emergent-Occ |
||||
| Differentiable Raycasting for Self-supervised Occupancy Forecasting | ECCV 2022 | - | ||
FF4D |
||||
| Point Cloud Forecasting as a Proxy for 4D Occupancy Forecasting | CVPR 2023 | |||
UniWorld |
||||
| UniWorld: Autonomous Driving Pre-Training via World Models | arXiv 2023 | - | - | |
UniScene |
||||
| UniScene: Multi-Camera Unified Pre-Training via 3D Scene Reconstruction for Autonomous Driving | arXiv 2023 | - | ||
OccWorld |
||||
| OccWorld: Learning A 3D Occupancy World Model for Autonomous Driving | ECCV 2024 | |||
Cam4DOcc |
||||
| Cam4DOcc: Benchmark for Camera-Only 4D Occupancy Forecasting in Autonomous Driving Applications | CVPR 2024 | - | ||
DriveWorld |
||||
| DriveWorld: 4D Pre-Trained Scene Understanding via World Models for Autonomous Driving | CVPR 2024 | - | - | |
OccSora |
||||
| OccSora: 4D Occupancy Generation Models as World Simulators for Autonomous Driving | arXiv 2024 | |||
UnO |
||||
| UnO: Unsupervised Occupancy Fields for Perception and Forecasting | CVPR 2024 | - | ||
LOPR |
||||
| Self-Supervised Multi-Future Occupancy Forecasting for Autonomous Driving | arXiv 2024 | - | - | |
FSF-Net |
||||
| FSF-Net: Enhance 4D Occupancy Forecasting with Coarse BEV Scene Flow for Autonomous Driving | arXiv 2024 | - | - | |
OccLLaMA |
||||
| OccLLaMA: An Occupancy-Language-Action Generative World Model for Autonomous Driving | arXiv 2024 | - | - | |
DOME |
||||
| DOME: Taming Diffusion Model into High-Fidelity Controllable Occupancy World Model | arXiv 2024 | |||
GaussianAD |
||||
| GaussianAD: Gaussian-Centric End-to-End Autonomous Driving | arXiv 2024 | |||
GaussianWorld |
||||
| GaussianWorld: Gaussian World Model for Streaming 3D Occupancy Prediction | CVPR 2025 | - | ||
DFIT-OccWorld |
||||
| An Efficient Occupancy World Model via Decoupled Dynamic Flow and Image-Assisted Training | arXiv 2024 | - | - | |
Drive-OccWorld |
||||
| Driving in the Occupancy World: Vision-Centric 4D Occupancy Forecasting and Planning via World Models for Autonomous Driving | AAAI 2025 | |||
PreWorld |
||||
| Semi-Supervised Vision-Centric 3D Occupancy World Model for Autonomous Driving | ICLR 2025 | - | ||
OccProphet |
||||
| OccProphet: Pushing Efficiency Frontier of Camera-Only 4D Occupancy Forecasting with Observer-Forecaster-Refiner Framework | ICLR 2025 | - | ||
RenderWorld |
||||
| RenderWorld: World Model with Self-Supervised 3D Label | ICRA 2025 | - | - | |
Occ-LLM |
||||
| Occ-LLM: Enhancing Autonomous Driving with Occupancy-Based Large Language Models | ICRA 2025 | - | - | |
EfficientOCF |
||||
| Spatiotemporal Decoupling for Efficient Vision-Based Occupancy Forecasting | CVPR 2025 | - | - | |
DIO |
||||
| DIO: Decomposable Implicit 4D Occupancy-Flow World Model | CVPR 2025 | - | - | |
T³Former |
||||
| Temporal Triplane Transformers as Occupancy World Models | arXiv 2025 | - | - | |
UniOcc |
||||
| UniOcc: A Unified Benchmark for Occupancy Forecasting and Prediction in Autonomous Driving | ICCV 2025 | |||
COME |
||||
| COME: Adding Scene-Centric Forecasting Control to Occupancy World Model | arXiv 2025 | - | ||
I²World |
||||
| I²-World: Intra-Inter Tokenization for Efficient Dynamic 4D Scene Forecasting | ICCV 2025 | - | ||
OmniNWM |
||||
| OmniNWM: Omniscient Driving Navigation World Models | arXiv 2025 | - | ||
SparseOccVLA |
||||
| SparseOccVLA: Bridging Occupancy and Vision-Language Models via Sparse Queries for Unified 4D Scene Understanding and Planning | arXiv 2026 | - | ||
GenieDrive |
||||
| GenieDrive: Towards Physics-Aware Driving World Model with 4D Occupancy Guided Video Generation | CVPR 2026 | |||
OccTENS |
||||
| OccTENS: 3D Occupancy World Model via Temporal Next-Scale Prediction | arXiv 2025 | - | - | |
SparseWorld |
||||
| SparseWorld: A Flexible, Adaptive, and Efficient 4D Occupancy World Model Powered by Sparse and Dynamic Queries | arXiv 2025 | - | - | |
IR-WM |
||||
| Vision-Centric 4D Occupancy Forecasting and Planning via Implicit Residual World Models | arXiv 2025 | - | - | |
ForecastOcc |
||||
| ForecastOcc: Vision-based Semantic Occupancy Forecasting | arXiv 2026 | - | - | |
GEM (Occ) |
||||
| GEM: Gaussian Evolution Model for Occupancy Forecasting and Motion Planning | arXiv 2026 | - | - | |
OWMDrive |
||||
| OWMDrive: Causality-Aware End-to-End Autonomous Driving via 4D Occupancy World Model | arXiv 2026 | - | - | |
CascadeOcc |
||||
| CascadeOcc: Rethinking 3D Occupancy World Models with Cascaded VQ Representations | arXiv 2026 | - | - | |
:three: Autoregressive Simulators
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
SemCity |
||||
| SemCity: Semantic Scene Generation with Triplane Diffusion | CVPR 2024 | |||
XCube |
||||
| XCube: Large-Scale 3D Generative Modeling using Sparse Voxel Hierarchies | CVPR 2024 | |||
PDD |
||||
| Pyramid Diffusion for Fine 3D Large Scene Generation | ECCV 2024 | |||
OccSora |
||||
| OccSora: 4D Occupancy Generation Models as World Simulators for Autonomous Driving | arXiv 2024 | |||
DynamicCity |
||||
| DynamicCity: Large-Scale 4D Occupancy Generation from Dynamic Scenes | ICLR 2025 | |||
DrivingSphere |
||||
| DrivingSphere: Building A High-Fidelity 4D World for Closed-Loop Simulation | CVPR 2025 | |||
InfiniCube |
||||
| InfiniCube: Unbounded and Controllable Dynamic 3D Driving Scene Generation with World-Guided Video Models | ICCV 2025 | |||
X-Scene |
||||
| X-Scene: Large-Scale Driving Scene Generation with High Fidelity and Flexible Controllability | arXiv 2025 | |||
PrITTI |
||||
| PrITTI: Primitive-Based Generation of Controllable and Editable 3D Semantic Scenes | arXiv 2025 | |||
OccSim |
||||
| OccSim: Multi-kilometer Simulation with Long-horizon Occupancy World Models | arXiv 2026 | - | - | |
AutoWorld |
||||
| AutoWorld: Scaling Multi-Agent Traffic Simulation with Self-Supervised World Models | arXiv 2026 | - | - | |
OccDirector |
||||
| OccDirector: Language-Guided Behavior and Interaction Generation in 4D Occupancy Space | arXiv 2026 | - | - | |
4. World Modeling from LiDAR Generation
:one: Data Engines
:timer_clock: In chronological order, from the earliest to the latest.
| Model | Paper | Venue | Website | GitHub |
|---|---|---|---|---|
LiDAR4D-Anno |
||||
| Bootstrapping a 4D LiDAR Annotation Tool from Video Foundation Models | arXiv 2026 | - | - | |
DUSty |
||||
| Learning to Drop Points for LiDAR Scan Synthesis | IROS 2021 | |||
LiDARGen |
||||
| Learning to Generate Realistic LiDAR Point Clouds | ECCV 2022 | - | ||
DUSty v2 |
||||
| Generative Range Imaging for Learning Scene Priors of 3D LiDAR Data | WACV 2023 | |||
UltraLiDAR |
||||
| UltraLiDAR: Learning Compact Representations for LiDAR Completion and Generation | CVPR 2023 | - | ||
Copilot4D |
||||
| Copilot4D: Learning Unsupervised World Models for Autonomous Driving via Discrete Diffusion | ICLR 2024 | - | ||
R2DM |
||||
| LiDAR Data Synthesis with Denoising Diffusion Probabilistic Models | ICRA 2024 | |||
ViDAR |
||||
| Visual Point Cloud Forecasting enables Scalable Autonomous Driving | CVPR 2024 | - | ||
LiDiff |
||||
| Scaling Diffusion Models to Real-World 3D LiDAR Scene Completion | CVPR 2024 | - | ||
LiDM |
||||
| Towards Realistic Scene Generation with LiDAR Diffusion Models | CVPR 2024 | - | ||
RangeLDM |
||||
| RangeLDM: Fast Realistic LiDAR Point Cloud Generation | ECCV 2024 | - | ||
Text2LiDAR |
||||
| Text2LiDAR: Text-Guided LiDAR Point Cloud Generation via Equirectangular Transformer | ECCV 2024 | - | ||
LiDARGRIT |
||||
| Taming Transformers for Realistic LiDAR Point Cloud Generation | arXiv 2024 | - | ||
BEVWorld |
||||
| BEVWorld: A Multimodal World Simulator for Autonomous Driving via Scene-Level BEV Latents | arXiv 2024 | - | ||
SDS |
||||
| Simultaneous Diffusion Sampling for Conditional LiDAR Generation | arXiv 2024 | - | - | |
DiffSSC |
||||
| DiffSSC: Semantic LiDAR Scan Completion using Denoising Diffusion Probabilistic Models | IROS 2025 | - | - | |
HoloDrive |
||||
| HoloDrive: Holistic 2D-3D Multi-Modal Street Scene Generation for Autonomous Driving | arXiv 2024 | - | - | |
LOGen |
||||
| LOGen: Toward LiDAR Object Generation by Point Diffusion | arXiv 2024 | [ |