Awesome Multi-Task Learning
A curated list of datasets, codebases, and papers on Multi-Task Learning (MTL), from a Machine Learning perspective.
This project greatly appreciates the surveys below, which have been incredibly helpful.
We welcome your contributions! If you find any mistakes or omissions, please let us know.
Contact: Jialong Wu
Table of Contents
Awesome Multi-Task Learning
- Survey
- Benchmark & Dataset
- Codebase
- Architecture
- Optimization
- Task Relationship Learning: Grouping, Tree (Hierarchy) & Cascading
- Theory
- Misc
Survey
- ✨ Yu, J., Dai, Y., Liu, X., Huang, J., Shen, Y., Zhang, K., ... & Chen, Y. Unleashing the Power of Multi-Task Learning: A Comprehensive Survey Spanning Traditional, Deep, and Pretrained Foundation Model Eras. ArXiv, 2024.
- ✨ Vandenhende, S., Georgoulis, S., Proesmans, M., Dai, D., & Van Gool, L. Multi-Task Learning for Dense Prediction Tasks: A Survey. TPAMI, 2021.
- Crawshaw, M. Multi-Task Learning with Deep Neural Networks: A Survey. ArXiv, 2020.
- Worsham, J., & Kalita, J. Multi-task learning for natural language processing in the 2020s: Where are we going? Pattern Recognition Letters, 2020.
- Gong, T., Lee, T., Stephenson, C., Renduchintala, V., Padhy, S., Ndirango, A., Keskin, G., & Elibol, O. H. A Comparison of Loss Weighting Strategies for Multi task Learning in Deep Neural Networks. IEEE Access, 2019.
- Li, J., Liu, X., Yin, W., Yang, M., Ma, L., & Jin, Y. Empirical Evaluation of Multi-task Learning in Deep Neural Networks for Natural Language Processing. Neural Computing and Applications, 2021.
- ✨ Ruder, S. An Overview of Multi-Task Learning in Deep Neural Networks. ArXiv, 2017.
- ✨ Zhang, Y., & Yang, Q. A Survey on Multi-Task Learning. IEEE TKDE, 2021.
Benchmark & Dataset
Computer Vision
- MultiMNIST / MultiFashionMNIST
- a multitask variant of the MNIST / FashionMNIST dataset
- ⚠️ Toy datasets
- See: MGDA, Pareto MTL, IT-MTL, etc.
- ✨ NYUv2 [URL]
- 3 Tasks: Semantic Segmentation, Depth Estimation, Surface Normal Estimation
- Silberman, N., Hoiem, D., Kohli, P., & Fergus, R. (2012). Indoor Segmentation and Support Inference from RGBD Images. ECCV, 2012.
- ✨ CityScapes [URL]
- 3 Tasks: Semantic Segmentation, Instance Segmentation, Depth Estimation
- ✨ PASCAL Context [URL]
- Tasks: Semantic Segmentation, Human Part Segmentation, Semantic Edge Detection, Surface Normals Prediction, Saliency Detection.
- ✨ CelebA [URL]
- Tasks: 40 human face Attributes.
- ✨ Taskonomy [URL]
- 26 Tasks: Scene Categorization, Semantic Segmentation, Edge Detection, Monocular Depth Estimation, Keypoint Detection, etc.
- Visual Domain Decathlon [URL]
- 10 Datasets: ImageNet, Aircraft, CIFAR100, etc.
- Multi-domain multi-task learning
- Rebuffi, S.-A., Bilen, H., & Vedaldi, A. Learning multiple visual domains with residual adapters. NeurIPS, 2017.
- BDD100K [URL]
- 10-task Driving Dataset
- Yu, F., Chen, H., Wang, X., Xian, W., Chen, Y., Liu, F., Madhavan, V., & Darrell, T. BDD100K: A Diverse Driving Dataset for Heterogeneous Multitask Learning. CVPR, 2020.
- MS COCO
- Object detection, pose estimation, semantic segmentation.
- See: MultiTask-CenterNet (MCN): Efficient and Diverse Multitask Learning using an Anchor Free Approach.
- Omnidata [URL]
- A pipeline to resample comprehensive 3D scans from the real-world into static multi-task vision datasets
- Eftekhar, A., Sax, A., Bachmann, R., Malik, J., & Zamir, A. Omnidata: A Scalable Pipeline for Making Multi-Task Mid-Level Vision Datasets from 3D Scans. ICCV, 2021.
NLP
- ✨ GLUE - General Language Understanding Evaluation [URL]
- ✨ decaNLP - The Natural Language Decathlon: A Multitask Challenge for NLP [URL]
- WMT Multilingual Machine Translation
tasksource- 500+ MultipleChoice/Classification/TokenClassification tasks from HuggingFace Datasets Hub [URL]
RL & Robotics
Graph
- QM9 [URL]
- 11 properties of molecules; multi-task regression
- See: Multi-Task Learning as a Bargaining Game.
Recommendation
- AliExpress [URL]
- 2 Tasks: CTR and CTCVR from 5 countries
- Li, P., Li, R., Da, Q., Zeng, A. X., & Zhang, L. Improving Multi-Scenario Learning to Rank in E-commerce by Exploiting Task Relationships in the Label Space. CIKM, 2020.
- See: MTReclib
- MovieLens [URL]
- 2 Tasks: binary classification (whether the user will watch) & regression (user’s rating)
- See: DSelect-k: Differentiable Selection in the Mixture of Experts with Applications to Multi-Task Learning
Codebase
- General
- Computer Vision
- ✨ Multi-Task-Learning-PyTorch: PyTorch implementation of multi-task learning architectures
- ✨ mtan: The implementation of "End-to-End Multi-Task Learning with Attention"
- ✨ auto-lambda: The Implementation of "Auto-Lambda: Disentangling Dynamic Task Relationships"
- astmt: Attentive Single-tasking of Multiple Tasks
- NLP
- ✨ mt-dnn: Multi-Task Deep Neural Networks for Natural Language Understanding
- Recommendation System
- ✨ MTReclib: MTReclib provides a PyTorch implementation of multi-task recommendation models and common datasets.
- RL
- mtrl: Multi Task RL Baselines
Architecture
Hard Parameter Sharing
-
Zhao, Z., Ziser, Y., & Cohen, S. B. Layer by Layer: Uncovering Where Multi-Task Learning Happens in Instruction-Tuned Large Language Models. EMNLP, 2024.
-
Heuer, F., Mantowsky, S., Bukhari, S. S., & Schneider, G. MultiTask-CenterNet (MCN): Efficient and Diverse Multitask Learning using an Anchor Free Approach. ICCV, 2021.
-
Hu, R., & Singh, A. UniT: Multimodal Multitask Learning with a Unified Transformer. ICCV, 2021.
-
✨ Liu, X., He, P., Chen, W., & Gao, J. Multi-Task Deep Neural Networks for Natural Language Understanding. ACL, 2019.
-
✨ Kokkinos, I. UberNet: Training a Universal Convolutional Neural Network for Low-, Mid-, and High-Level Vision Using Diverse Datasets and Limited Memory. CVPR, 2017.
-
Teichmann, M., Weber, M., Zoellner, M., Cipolla, R., & Urtasun, R. MultiNet: Real-time Joint Semantic Reasoning for Autonomous Driving. ArXiv, 2016.
-
Caruana, R. Multitask Learning. 1997.
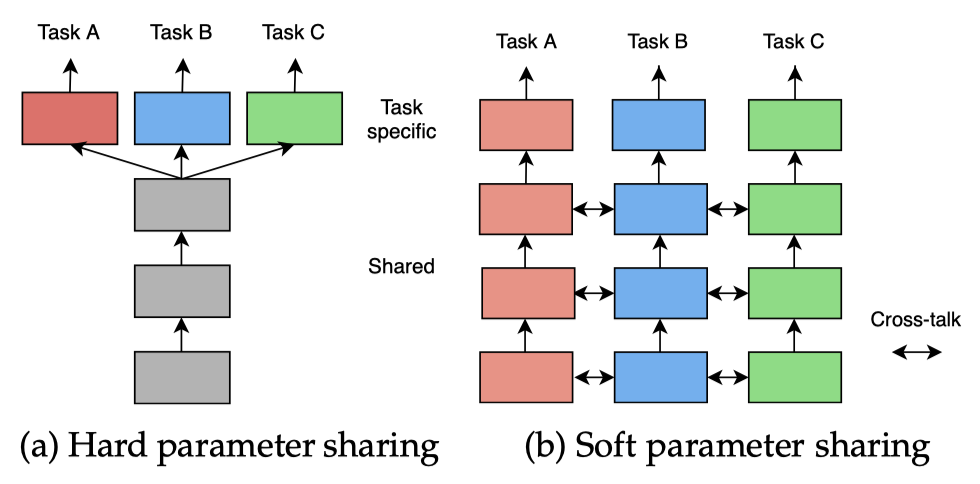
Soft Parameter Sharing
- Ruder, S., Bingel, J., Augenstein, I., & Søgaard, A. Latent Multi-task Architecture Learning. AAAI, 2019.
- Gao, Y., Ma, J., Zhao, M., Liu, W., & Yuille, A. L. NDDR-CNN: Layerwise Feature Fusing in Multi-Task CNNs by Neural Discriminative Dimensionality Reduction. CVPR, 2019.
- Long, M., Cao, Z., Wang, J., & Yu, P. S. Learning Multiple Tasks with Multilinear Relationship Networks. NeurIPS, 2017.
- ✨ Misra, I., Shrivastava, A., Gupta, A., & Hebert, M. Cross-Stitch Networks for Multi-task Learning. CVPR, 2016.
- ✨ Rusu, A. A., Rabinowitz, N. C., Desjardins, G., Soyer, H., Kirkpatrick, J., Kavukcuoglu, K., Pascanu, R., & Hadsell, R. Progressive Neural Networks. ArXiv, 2016.
- ✨ Yang, Y., & Hospedales, T. Deep Multi-task Representation Learning: A Tensor Factorisation Approach. ICLR, 2017.
- Yang, Y., & Hospedales, T. M. Trace Norm Regularised Deep Multi-Task Learning. ICLR Workshop, 2017.
Decoder-focused Model
- Ye, H., & Xu, D. TaskPrompter: Spatial-Channel Multi-Task Prompting for Dense Scene Understanding. ICLR, 2023.
- Ye, H., & Xu, D. Inverted Pyramid Multi-task Transformer for Dense Scene Understanding. ECCV, 2022.
- Bruggemann, D., Kanakis, M., Obukhov, A., Georgoulis, S., & Van Gool, L. Exploring Relational Context for Multi-Task Dense Prediction. ICCV, 2021.
- Vandenhende, S., Georgoulis, S., & Van Gool, L. MTI-Net: Multi-Scale Task Interaction Networks for Multi-Task Learning. ECCV, 2020.
- Zhang, Z., Cui, Z., Xu, C., Yan, Y., Sebe, N., & Yang, J. Pattern-Affinitive Propagation Across Depth, Surface Normal and Semantic Segmentation. CVPR, 2019.
- Xu, D., Ouyang, W., Wang, X., & Sebe, N. PAD-Net: Multi-tasks Guided Prediction-and-Distillation Network for Simultaneous Depth Estimation and Scene Parsing. CVPR, 2018.
Modulation & Adapters
- Schmied, T., Hofmarcher, M., Paischer, F., Pascanu, R., & Hochreiter, S. Learning to Modulate pre-trained Models in RL. NeurIPS, 2023.
- Sharma, M., Fantacci, C., Zhou, Y., Koppula, S., Heess, N., Scholz, J., & Aytar, Y. Lossless Adaptation of Pretrained Vision Models For Robotic Manipulation. ICLR, 2023.
- ✨ He, J., Zhou, C., Ma, X., Berg-Kirkpatrick, T., & Neubig, G. Towards a Unified View of Parameter-Efficient Transfer Learning. ICLR, 2022.
- Liu, H., Tam, D., Muqeeth, M., Mohta, J., Huang, T., Bansal, M., & Raffel, C. Few-Shot Parameter-Efficient Fine-Tuning is Better and Cheaper than In-Context Learning. NeurIPS, 2022.
- Zhang, L., Yang, Q., Liu, X., & Guan, H. Rethinking Hard-Parameter Sharing in Multi-Domain Learning. ICME, 2022.
- Wang, Z., Zhang, Z., Lee, C.-Y., Zhang, H., Sun, R., Ren, X., Su, G., Perot, V., Dy, J., & Pfister, T. Learning to Prompt for Continual Learning. CVPR, 2022.
- ✨ Lester, B., Al-Rfou, R., & Constant, N. The Power of Scale for Parameter-Efficient Prompt Tuning. EMNLP, 2021.
- ✨ Li, X. L., & Liang, P. Prefix-Tuning: Optimizing Continuous Prompts for Generation. ACL, 2021.
- Zhu, Y., Feng, J., Zhao, C., Wang, M., & Li, L. Counter-Interference Adapter for Multilingual Machine Translation. Findings of EMNLP, 2021.
- ✨ Hu, E. J., Shen, Y., Wallis, P., Allen-Zhu, Z., Li, Y., Wang, S., Wang, L., & Chen, W. LoRA: Low-Rank Adaptation of Large Language Models. Arxiv, 2021.
- Pilault, J., Elhattami, A., & Pal, C. J. Conditionally Adaptive Multi-Task Learning: Improving Transfer Learning in NLP Using Fewer Parameters & Less Data. ICLR, 2021.
- Pfeiffer, J., Kamath, A., Rücklé, A., Cho, K., & Gurevych, I. AdapterFusion: Non-Destructive Task Composition for Transfer Learning. EACL, 2021.
- Kanakis, M., Bruggemann, D., Saha, S., Georgoulis, S., Obukhov, A., & Van Gool, L. Reparameterizing Convolutions for Incremental Multi-Task Learning without Task Interference. ECCV, 2020.
- Pham, M. Q., Crego, J. M., Yvon, F., & Senellart, J. A Study of Residual Adapters for Multi-Domain Neural Machine Translation. WMT, 2020.
- ✨ Pfeiffer, J., Rücklé, A., Poth, C., Kamath, A., Vulić, I., Ruder, S., Cho, K., & Gurevych, I. AdapterHub: A Framework for Adapting Transformers. EMNLP 2020: Systems Demonstrations.
- Pfeiffer, J., Vulić, I., Gurevych, I., & Ruder, S. MAD-X: An Adapter-Based Framework for Multi-Task Cross-Lingual Transfer. EMNLP, 2020.
- Zhao, M., Lin, T., Mi, F., Jaggi, M., & Schütze, H. Masking as an Efficient Alternative to Finetuning for Pretrained Language Models. EMNLP, 2020.
- ✨ [MTAN] Liu, S., Johns, E., & Davison, A. J. End-to-End Multi-Task Learning with Attention. CVPR, 2019.
- Strezoski, G., Noord, N., & Worring, M. Many Task Learning With Task Routing. ICCV, 2019.
- Maninis, K.-K., Radosavovic, I., & Kokkinos, I. Attentive Single-Tasking of Multiple Tasks. CVPR, 2019.
- ✨ Houlsby, N., Giurgiu, A., Jastrzebski, S., Morrone, B., de Laroussilhe, Q., Gesmundo, A., Attariyan, M., & Gelly, S. Parameter-Efficient Transfer Learning for NLP. ICML, 2019.
- Stickland, A. C., & Murray, I. BERT and PALs: Projected Attention Layers for Efficient Adaptation in Multi-Task Learning. ICML, 2019.
- Zhao, X., Li, H., Shen, X., Liang, X., & Wu, Y. A Modulation Module for Multi-task Learning with Applications in Image Retrieval. ECCV, 2018.
- ✨ Rebuffi, S.-A., Vedaldi, A., & Bilen, H. Efficient Parametrization of Multi-domain Deep Neural Networks. CVPR, 2018.
- ✨ Rebuffi, S.-A., Bilen, H., & Vedaldi, A. Learning multiple visual domains with residual adapters. NeurIPS, 2017.
Modularity, MoE, Routing & NAS
- Chen, Z., Shen, Y., Ding, M., Chen, Z., Zhao, H., Learned-Miller, E., & Gan, C. Mod-Squad: Designing Mixture of Experts As Modular Multi-Task Learners. CVPR, 2023.
- ✨ Yang, X., Ye, J., & Wang, X. Factorizing Knowledge in Neural Networks. ECCV, 2022.
- ✨ Liang, H., Fan, Z., Sarkar, R., Jiang, Z., Chen, T., Zou, K., ... & Wang, Z. M$^ 3$ViT: Mixture-of-Experts Vision Transformer for Efficient Multi-task Learning with Model-Accelerator Co-design. NeurIPS, 2022.
- Zhang, L., Liu, X., & Guan, H. AutoMTL: A Programming Framework for Automated Multi-Task Learning. NeurIPS, 2022.
- Gesmundo, A., & Dean, J. An Evolutionary Approach to Dynamic Introduction of Tasks in Large-scale Multitask Learning Systems. ArXiv, 2022.
- Tang, D., Zhang, F., Dai, Y., Zhou, C., Wu, S., & Shi, S. SkillNet-NLU: A Sparsely Activated Model for General-Purpose Natural Language Understanding. ArXiv, 2022.
- Ponti, E. M., Sordoni, A., Bengio, Y., & Reddy, S. Combining Modular Skills in Multitask Learning. ArXiv, 2022.
- Hazimeh, H., Zhao, Z., Chowdhery, A., Sathiamoorthy, M., Chen, Y., Mazumder, R., Hong, L., & Chi, E. H. DSelect-k: Differentiable Selection in the Mixture of Experts with Applications to Multi-Task Learning. NeurIPS, 2021.
- ✨ [Pathways] Introducing Pathways: A next-generation AI architecture. Oct 28, 2021. Retrieved March 9, 2022, from https://blog.google/technology/ai/introducing-pathways-next-generation-ai-architecture/
- ✨ Yang, R., Xu, H., Wu, Y., & Wang, X. Multi-Task Reinforcement Learning with Soft Modularization. NeurIPS, 2020.
- Sun, X., Panda, R., & Feris, R. AdaShare: Learning What To Share For Efficient Deep Multi-Task Learning. NeurIPS, 2020.
- Bruggemann, D., Kanakis, M., Georgoulis, S., & Van Gool, L. Automated Search for Resource-Efficient Branched Multi-Task Networks. BMVC, 2020.
- Gao, Y., Bai, H., Jie, Z., Ma, J., Jia, K., & Liu, W. MTL-NAS: Task-Agnostic Neural Architecture Search towards General-Purpose Multi-Task Learning. CVPR, 2020.
- ✨ [PLE] Tang, H., Liu, J., Zhao, M., & Gong, X. Progressive Layered Extraction (PLE): A Novel Multi-Task Learning (MTL) Model for Personalized Recommendations. RecSys, 2020 (Best Paper).
- Bragman, F., Tanno, R., Ourselin, S., Alexander, D., & Cardoso, J. Stochastic Filter Groups for Multi-Task CNNs: Learning Specialist and Generalist Convolution Kernels. ICCV, 2019.
- Ahn, C., Kim, E., & Oh, S. Deep Elastic Networks with Model Selection for Multi-Task Learning. ICCV, 2019.
- Ma, J., Zhao, Z., Chen, J., Li, A., Hong, L., & Chi, E. H. SNR: Sub-Network Routing for Flexible Parameter Sharing in Multi-Task Learning. AAAI, 2019.
- Maziarz, K., Kokiopoulou, E., Gesmundo, A., Sbaiz, L., Bartok, G., & Berent, J. Flexible Multi-task Networks by Learning Parameter Allocation. ArXiv, 2019.
- Newell, A., Jiang, L., Wang, C., Li, L.-J., & Deng, J. Feature Partitioning for Efficient Multi-Task Architectures. ArXiv, 2019.
- ✨ [MMoE] Ma, J., Zhao, Z., Yi, X., Chen, J., Hong, L., & Chi, E. H. Modeling Task Relationships in Multi-task Learning with Multi-gate Mixture-of-Experts. KDD, 2018.
- Rosenbaum, C., Klinger, T., & Riemer, M. Routing Networks: Adaptive Selection of Non-linear Functions for Multi-Task Learning. ICLR, 2018.
- Meyerson, E., & Miikkulainen, R. Beyond Shared Hierarchies: Deep Multitask Learning through Soft Layer Ordering. ICLR, 2018.
- Liang, J., Meyerson, E., & Miikkulainen, R. Evolutionary architecture search for deep multitask networks. Proceedings of the Genetic and Evolutionary Computation Conference, 2018.
- Kim, E., Ahn, C., & Oh, S. NestedNet: Learning Nested Sparse Structures in Deep Neural Networks. CVPR, 2018.
- Andreas, J., Klein, D., & Levine, S. Modular Multitask Reinforcement Learning with Policy Sketches. ICML, 2017.
- Devin, C., Gupta, A., Darrell, T., Abbeel, P., & Levine, S. Learning Modular Neural Network Policies for Multi-Task and Multi-Robot Transfer. ICRA, 2017
- ✨ Fernando, C., Banarse, D., Blundell, C., Zwols, Y., Ha, D., Rusu, A. A., Pritzel, A., & Wierstra, D. PathNet: Evolution Channels Gradient Descent in Super Neural Networks. ArXiv, 2017.
Task Representation
- Sodhani, S., Zhang, A., & Pineau, J. Multi-Task Reinforcement Learning with Context-based Representations. ICML, 2021.
Others
- Sun, T., Shao, Y., Li, X., Liu, P., Yan, H., Qiu, X., & Huang, X. Learning Sparse Sharing Architectures for Multiple Tasks. AAAI, 2020.
- Lee, H. B., Yang, E., & Hwang, S. J. Deep Asymmetric Multi-task Feature Learning. ICML, 2018.
- Zhang, Y., Wei, Y., & Yang, Q. Learning to Multitask. NeurIPS, 2018.
- ✨ Mallya, A., Davis, D., & Lazebnik, S. Piggyback: Adapting a Single Network to Multiple Tasks by Learning to Mask Weights. ECCV 2018.
- ✨ Mallya, A., & Lazebnik, S. PackNet: Adding Multiple Tasks to a Single Network by Iterative Pruning. CVPR, 2018.
- Lee, G., Yang, E., & Hwang, S. J. Asymmetric Multi-task Learning based on Task Relatedness and Confidence. ICML, 2016.
Optimization
Loss & Gradient Strategy
- [FS-MTL] Phan, H., Tran, L., Tran, N. N., Ho, N., Phung, D., & Le, T. Beyond Losses Reweighting: Empowering Multi-Task Learning via the Generalization Perspective. ICCV Highlight, 2025.
- [UPGrad] Quinton, P. & Rey, V. Jacobian Descent for Multi-Objective Optimization. ArXiv, 2024.
- [ConFIG] Liu, Q., Chu, M., & Thuerey, N. ConFIG: Towards conflict-free training of physics informed neural networks. ArXiv, 2024.
- [FairGrad] Ban, H., & Ji, K. Fair Resource Allocation in Multi-Task Learning. ICML, 2024.
- [SDMGrad] Xiao, P., Ban, H., & Ji, K. Direction-oriented multi-objective learning: Simple and provable stochastic algorithms. NeurIPS, 2023.
- [Population-Based Training] Royer, A., Blankevoort, T., & Bejnordi, B. E. Scalarization for Multi-Task and Multi-Domain Learning at Scale. NeurIPS, 2023.
- [IGB] Dai, Y., Fei, N., & Lu, Z. Improvable Gap Balancing for Multi-Task Learning. UAI, 2023.
- [Aligned-MTL] Senushkin, D., Patakin, N., Kuznetsov, A., & Konushin, A. Independent Component Alignment for Multi-Task Learning. CVPR, 2023.
- [MoCo] Fernando, H. D., Shen, H., Liu, M., Chaudhury, S., Murugesan, K., & Chen, T. Mitigating Gradient Bias in Multi-objective Learning: A Provably Convergent Approach. ICLR, 2023.
- [FAMO] Liu, B., Feng, Y., Stone, P., & Liu, Q. FAMO: Fast Adaptive Multitask Optimization. ArXiv, 2023.
- ✨ [ForkMerge] Jiang, J., Chen, B., Pan, J., Wang, X., Dapeng, L., Jiang, J., & Long, M. ForkMerge: Overcoming Negative Transfer in Multi-Task Learning. ArXiv, 2023.
- [AuxiNash] Shamsian, A., Navon, A., Glazer, N., Kawaguchi, K., Chechik, G., & Fetaya, E. Auxiliary Learning as an Asymmetric Bargaining Game. ArXiv, 2023.
- ✨ Xin, Derrick, Behrooz Ghorbani, Justin Gilmer, Ankush Garg, and Orhan Firat. Do Current Multi-Task Optimization Methods in Deep Learning Even Help? NeurIPS, 2022.
- [Unitary Scalarization] Kurin, V., De Palma, A., Kostrikov, I., Whiteson, S., & Kumar, M. P. In Defense of the Unitary Scalarization for Deep Multi-Task Learning. NeurIPS, 2022.
- Minimize the multi-task training objective with a standard gradient-based algorithm.
- [Auto-λ] Liu, S., James, S., Davison, A. J., & Johns, E. Auto-Lambda: Disentangling Dynamic Task Relationships. TMLR, 2022.
- [Nash-MTL] Navon, A., Shamsian, A., Achituve, I., Maron, H., Kawaguchi, K., Chechik, G., & Fetaya, E. Multi-Task Learning as a Bargaining Game. ICML, 2022.
- Also resurrects important Scale-invariant (SI) baseline which minimizes $\sum_k \log \ell_k$.
- [Rotograd] Javaloy, A., & Valera, I. RotoGrad: Gradient Homogenization in Multitask Learning. ICLR, 2022.
- [RLW / RGW] Lin, B., Ye, F., & Zhang, Y. Reasonable Effectiveness of Random Weighting: A Litmus Test for Multi-Task Learning. TMLR, 2022.
- [PINNsNTK] Wang, S., Yu, X., & Perdikaris, P. When and why PINNs fail to train: A neural tangent kernel perspective. Journal of Computational Physics, 2022.
- [Inverse-Dirichlet PINNs] Maddu, S., Sturm, D., Müller, C. L., & Sbalzarini, I. F. Inverse Dirichlet weighting enables reliable training of physics informed neural networks. Machine Learning: Science and Technology, 2022.
- [CAGrad] Liu, B., Liu, X., Jin, X., Stone, P., & Liu, Q. Conflict-Averse Gradient Descent for Multi-task Learning. NeurIPS, 2021.
- ✨ [Gradient Vaccine] Wang, Z., Tsvetkov, Y., Firat, O., & Cao, Y. Gradient Vaccine: Investigating and Improving Multi-task Optimization in Massively Multilingual Models. ICLR, 2021.
- [IMTL] Liu, L., Li, Y., Kuang, Z., Xue, J.-H., Chen, Y., Yang, W., Liao, Q., & Zhang, W. Towards Impartial Multi-task Learning. ICLR, 2021.
- [GradientPathologiesPINNs] Wang, S., Teng, Y., & Perdikaris, P. Understanding and mitigating gradient flow pathologies in physics-informed neural networks. SIAM Journal on Scientific Computing, 2021.
- [IT-MTL] Fifty, C., Amid, E., Zhao, Z., Yu, T., Anil, R., & Finn, C. Measuring and Harnessing Transference in Multi-Task Learning. ArXiv, 2020.
- [GradDrop] Chen, Z., Ngiam, J., Huang, Y., Luong, T., Kretzschmar, H., Chai, Y., & Anguelov, D. Just Pick a Sign: Optimizing Deep Multitask Models with Gradient Sign Dropout. NeurIPS, 2020.
- ✨ [PCGrad] Yu, T., Kumar, S., Gupta, A., Levine, S., Hausman, K., & Finn, C. Gradient Surgery for Multi-Task Learning. NeurIPS, 2020.
- [Dynamic Stop-and-Go (DSG)] Lu, J., Goswami, V., Rohrbach, M., Parikh, D., & Lee, S. 12-in-1: Multi-Task Vision and Language Representation Learning. CVPR, 2020.
- [Online Learning for Auxiliary losses (OL-AUX)] Lin, X., Baweja, H., Kantor, G., & Held, D. Adaptive Auxiliary Task Weighting for Reinforcement Learning. NeurIPS, 2019.
- [PopArt] Hessel, M., Soyer, H., Espeholt, L., Czarnecki, W., Schmitt, S., & Van Hasselt, H. (2019). Multi-Task Deep Reinforcement Learning with PopArt. AAAI, 2019.
- PopArt: Learning values across many orders of magnitude. NeurIPS, 2016.
- [Dynamic Weight Average (DWA)] Liu, S., Johns, E., & Davison, A. J. End-to-End Multi-Task Learning with Attention. CVPR, 2019.
- [Geometric Loss Strategy (GLS)] Chennupati, S., Sistu, G., Yogamani, S., & Rawashdeh, S. A. MultiNet++: Multi-Stream Feature Aggregation and Geometric Loss Strategy for Multi-Task Learning. CVPR 2019 Workshop on Autonomous Driving (WAD).
- [Orthogonal] Suteu, M., & Guo, Y. Regularizing Deep Multi-Task Networks using Orthogonal Gradients. ArXiv, 2019.
- Enforcing near orthogonal gradients
- [LBTW] Liu, S., Liang, Y., & Gitter, A. Loss-Balanced Task Weighting to Reduce Negative Transfer in Multi-Task Learning. AAAI, 2019.
- ✨ [Gradient Cosine Similarity] Du, Y., Czarnecki, W. M., Jayakumar, S. M., Farajtabar, M., Pascanu, R., & Lakshminarayanan, B. Adapting Auxiliary Losses Using Gradient Similarity. ArXiv, 2018.
- Uses a thresholded cosine similarity to determine whether to use each auxiliary task.
- Extension: OL-AUX
- [Revised Uncertainty] Liebel, L., & Körner, M. Auxiliary Tasks in Multi-task Learning. ArXiv, 2018.
- ✨ [GradNorm] Chen, Z., Badrinarayanan, V., Lee, C.-Y., & Rabinovich, A. GradNorm: Gradient Normalization for Adaptive Loss Balancing in Deep Multitask Networks. ICML, 2018.
- ✨ [Dynamic Task Prioritization] Guo, M., Haque, A., Huang, D.-A., Yeung, S., & Fei-Fei, L. Dynamic Task Prioritization for Multitask Learning. ECCV, 2018.
- ✨ [Uncertainty] Kendall, A., Gal, Y., & Cipolla, R. Multi-task Learning Using Uncertainty to Weigh Losses for Scene Geometry and Semantics. CVPR, 2018.
- ✨ [MGDA] Sener, O., & Koltun, V. Multi-Task Learning as Multi-Objective Optimization. NeurIPS, 2018.
- [AdaLoss] Hu, H., Dey, D., Hebert, M., & Bagnell, J. A. Learning Anytime Predictions in Neural Networks via Adaptive Loss Balancing. ArXiv, 2017.
- The weights are inversely proportional to average of each loss.
- [Task-wise Early Stopping] Zhang, Z., Luo, P., Loy, C. C., & Tang, X. Facial Landmark Detection by Deep Multi-task Learning. ECCV, 2014.
Note:
- We find that AdaLoss, IMTL-l, and Uncertainty are quite similiar in form.
Task Interference
- Porrello, A., Buzzega, P., Dangel, F., Sommariva, T., Salami, R., Bonicelli, L., Calderara, S. Dataless Weight Disentanglement in Task Arithmetic via Kronecker-Factored Approximate Curvature. ICLR, 2026.
- Mitigates cross-task interference during task combination using a KFAC regularization approach.
- Jiang, J., Chen, B., Pan, J., Wang, X., Dapeng, L., Jiang, J., & Long, M. ForkMerge: Overcoming Negative Transfer in Multi-Task Learning. ArXiv, 2023.
- Wang, Z., Lipton, Z. C., & Tsvetkov, Y. On Negative Interference in Multilingual Models: Findings and A Meta-Learning Treatment. EMNLP, 2020.
- Schaul, T., Borsa, D., Modayil, J., & Pascanu, R. Ray Interference: A Source of Plateaus in Deep Reinforcement Learning. Arxiv, 2019.
- Zhao, X., Li, H., Shen, X., Liang, X., & Wu, Y. A Modulation Module for Multi-task Learning with Applications in Image Retrieval. ECCV, 2018.
- Uses Update Compliance Ratio (UCR) to identify the destructive interference
Task Sampling
- [Scheduled Multi-Task Training] Cho, M., Park, J., Lee, S., & Sung, Y. Hard Tasks First: Multi-Task Reinforcement Learning Through Task Scheduling. ICML, 2024.
- [MT-Uncertainty Sampling] Pilault, J., Elhattami, A., & Pal, C. J. Conditionally Adaptive Multi-Task Learning: Improving Transfer Learning in NLP Using Fewer Parameters & Less Data. ICLR, 2021.
- [Uniform, Task size, Counterfactual] Glover, J., & Hokamp, C. Task Selection Policies for Multitask Learning. ArXiv, 2019.
Adversarial Training
- ✨ Maninis, K.-K., Radosavovic, I., & Kokkinos, I. Attentive Single-Tasking of Multiple Tasks. CVPR, 2019.
- Sinha, A., Chen, Z., Badrinarayanan, V., & Rabinovich, A. Gradient Adversarial Training of Neural Networks. ArXiv, 2018.
- Liu, P., Qiu, X., & Huang, X. Adversarial Multi-task Learning for Text Classification. ACL, 2017.
Pareto
- Phan, H., Tran, N., Le, T., Tran, T., Ho, N., & Phung, D. Stochastic Multiple Target Sampling Gradient Descent. NeurIPS, 2022.
- Ma, P., Du, T., & Matusik, W. Effcient Continuous Pareto Exploration in Multi-Task Learning. ICML, 2020.
- Lin, X., Zhen, H.-L., Li, Z., Zhang, Q.-F., & Kwong, S. Pareto Multi-Task Learning. NeurIPS, 2019.
Distillation
- ✨ Yang, X., Ye, J., & Wang, X. Factorizing Knowledge in Neural Networks. ECCV, 2022.
- Li, W.-H., Liu, X., & Bilen, H. Universal Representations: A Unified Look at Multiple Task and Domain Learning. ArXiv, 2022.
- Ghiasi, G., Zoph, B., Cubuk, E. D., Le, Q. V., & Lin, T.-Y. Multi-Task Self-Training for Learning General Representations. ICCV, 2021.
- Li, W. H., & Bilen, H. Knowledge Distillation for Multi-task Learning, ECCV-Workshop, 2020.
- ✨ Teh, Yee Whye, Victor Bapst, Wojciech Marian Czarnecki, John Quan, James Kirkpatrick, Raia Hadsell, Nicolas Heess, and Razvan Pascanu. Distral: Robust Multitask Reinforcement Learning. NeurIPS, 2017.
- ✨ Parisotto, Emilio, Jimmy Lei Ba, and Ruslan Salakhutdinov. Actor-Mimic: Deep Multitask and Transfer Reinforcement Learning. ICLR, 2016.
- ✨ Rusu, Andrei A., Sergio Gomez Colmenarejo, Caglar Gulcehre, Guillaume Desjardins, James Kirkpatrick, Razvan Pascanu, Volodymyr Mnih, Koray Kavukcuoglu, and Raia Hadsell. Policy Distillation. ICLR, 2016.
Consistency
- ✨ Zamir, A., Sax, A., Yeo, T., Kar, O., Cheerla, N., Suri, R., Cao, Z., Malik, J., & Guibas, L. Robust Learning Through Cross-Task Consistency. CVPR, 2020.
Task Relationship Learning: Grouping, Tree (Hierarchy) & Cascading
- Zhao, Z., Ziser, Y., & Cohen, S. B. Layer by Layer: Uncovering Where Multi-Task Learning Happens in Instruction-Tuned Large Language Models. EMNLP, 2024.
- ✨ Hu, Y., Yang, J., Chen, L., Li, K., Sima, C., Zhu, X., ... & Li, H. Planning-oriented autonomous driving. CVPR, 2023 (Best Paper).
- ✨ Ilharco, Gabriel, Marco Tulio Ribeiro, Mitchell Wortsman, Suchin Gururangan, Ludwig Schmidt, Hannaneh Hajishirzi, and Ali Farhadi. Editing Models with Task Arithmetic. ICLR, 2023.
- Song, Xiaozhuang, Shun Zheng, Wei Cao, James Yu, and Jiang Bian. Efficient and Effective Multi-Task Grouping via Meta Learning on Task Combinations. NeurIPS, 2022.
- Zhang, L., Liu, X., & Guan, H. A Tree-Structured Multi-Task Model Recommender. AutoML-Conf, 2022.
- ✨ Fifty, C., Amid, E., Zhao, Z., Yu, T., Anil, R., & Finn, C. Efficiently Identifying Task Groupings for Multi-Task Learning. NeurIPS, 2021.
- ✨ Vandenhende, S., Georgoulis, S., De Brabandere, B., & Van Gool, L. Branched Multi-Task Networks: Deciding What Layers To Share. BMVC, 2020.
- Bruggemann, D., Kanakis, M., Georgoulis, S., & Van Gool, L. Automated Search for Resource-Efficient Branched Multi-Task Networks. BMVC, 2020.
- ✨ Standley, T., Zamir, A. R., Chen, D., Guibas, L., Malik, J., & Savarese, S. Which Tasks Should Be Learned Together in Multi-task Learning? ICML, 2020.
- Guo, P., Lee, C.-Y., & Ulbricht, D. Learning to Branch for Multi-Task Learning. ICML, 2020.
- Achille, A., Lam, M., Tewari, R., Ravichandran, A., Maji, S., Fowlkes, C., Soatto, S., & Perona, P. Task2Vec: Task Embedding for Meta-Learning. ICCV, 2019.
- Dwivedi, K., & Roig, G. Representation Similarity Analysis for Efficient Task Taxonomy & Transfer Learning. CVPR, 2019.
- Guo, H., Pasunuru, R., & Bansal, M. AutoSeM: Automatic Task Selection and Mixing in Multi-Task Learning. NAACL, 2019.
- ✨ Sanh, V., Wolf, T., & Ruder, S. A Hierarchical Multi-task Approach for Learning Embeddings from Semantic Tasks. AAAI, 2019.
- ✨ Zamir, A. R., Sax, A., Shen, W., Guibas, L. J., Malik, J., & Savarese, S. Taskonomy: Disentangling Task Transfer Learning. CVPR, 2018.
- Kim, J., Park, Y., Kim, G., & Hwang, S. J. SplitNet: Learning to Semantically Split Deep Networks for Parameter Reduction and Model Parallelization. ICML, 2017.
- Alonso, H. M., & Plank, B. When is multitask learning effective? Semantic sequence prediction under varying data conditions. EACL, 2017.
- ✨ Bingel, J., & Søgaard, A. Identifying beneficial task relations for multi-task learning in deep neural networks. EACL, 2017.
- Hand, E. M., & Chellappa, R. Attributes for Improved Attributes: A Multi-Task Network Utilizing Implicit and Explicit Relationships for Facial Attribute Classification. AAAI, 2017.
- ✨ Lu, Y., Kumar, A., Zhai, S., Cheng, Y., Javidi, T., & Feris, R. Fully-adaptive Feature Sharing in Multi-Task Networks with Applications in Person Attribute Classification. CVPR, 2017.
- Hashimoto, K., xiong, caiming, Tsuruoka, Y., & Socher, R. A Joint Many-Task Model: Growing a Neural Network for Multiple NLP Tasks. EMNLP, 2017.
- Søgaard, A., & Goldberg, Y. Deep multi-task learning with low level tasks supervised at lower layers. ACL, 2016.
- Kumar, A., & Daume III, H. Learning Task Grouping and Overlap in Multi-task Learning. ICML, 2012.
- Kang, Z., Grauman, K., & Sha, F. Learning with Whom to Share in Multi-task Feature Learning. ICML, 2011.
- Zhang, Y., & Yeung, D.-Y. A Convex Formulation for Learning Task Relationships in Multi-Task Learning. UAI, 2010.
Theory
- Wang, H., Zhao, H., & Li, B. Bridging Multi-Task Learning and Meta-Learning: Towards Efficient Training and Effective Adaptation. ICML, 2021.
- Tiomoko, M., Ali, H. T., & Couillet, R. Deciphering and Optimizing Multi-Task Learning: A Random Matrix Approach. ICLR, 2021.
- ✨ Tripuraneni, N., Jordan, M. I., & Jin, C. On the Theory of Transfer Learning: The Importance of Task Diversity. NeurIPS, 2020.
- Wu, S., Zhang, H. R., & Re, C. Understanding and Improving Information Transfer in Multi-Task Learning. ICLR, 2020.
Misc
- ✨ Bachmann, R., Mizrahi, D., Atanov, A., & Zamir, A. MultiMAE: Multi-modal Multi-task Masked Autoencoders. ECCV, 2022.
- Deng, W., Gould, S., & Zheng, L. What Does Rotation Prediction Tell Us about Classifier Accuracy under Varying Testing Environments?. ICML, 2021.
- Lu, J., Goswami, V., Rohrbach, M., Parikh, D., & Lee, S. 12-in-1: Multi-Task Vision and Language Representation Learning. CVPR, 2020.
- Mao, C., Gupta, A., Nitin, V., Ray, B., Song, S., Yang, J., & Vondrick, C. Multitask Learning Strengthens Adversarial Robustness. ECCV, 2020.
- Guo, P., Xu, Y., Lin, B., & Zhang, Y. Multi-Task Adversarial Attack. ArXiv, 2020.
- Clark, K., Luong, M.-T., Khandelwal, U., Manning, C. D., & Le, Q. V. BAM! Born-Again Multi-Task Networks for Natural Language Understanding. ACL, 2019.
- Pramanik, S., Agrawal, P., & Hussain, A. OmniNet: A unified architecture for multi-modal multi-task learning. ArXiv, 2019.
- Zimin, A., & Lampert, C. H. Tasks Without Borders: A New Approach to Online Multi-Task Learning. AMTL Workshop at ICML 2019.
- Meyerson, E., & Miikkulainen, R. Modular Universal Reparameterization: Deep Multi-task Learning Across Diverse Domains. NeurIPS, 2019.
- Meyerson, E., & Miikkulainen, R. Pseudo-task Augmentation: From Deep Multitask Learning to Intratask Sharing---and Back. ICML, 2018.
- Chou, Y.-M., Chan, Y.-M., Lee, J.-H., Chiu, C.-Y., & Chen, C.-S. Unifying and Merging Well-trained Deep Neural Networks for Inference Stage. IJCAI-ECAI, 2018.
- Doersch, C., & Zisserman, A. Multi-task Self-Supervised Visual Learning. ICCV, 2017.
- Smith, V., Chiang, C.-K., Sanjabi, M., & Talwalkar, A. S. Federated Multi-Task Learning. NeurIPS, 2017.
- Kaiser, L., Gomez, A. N., Shazeer, N., Vaswani, A., Parmar, N., Jones, L., & Uszkoreit, J. One Model To Learn Them All. ArXiv, 2017.
- Yang, Y., & Hospedales, T. M. Unifying Multi-Domain Multi-Task Learning: Tensor and Neural Network Perspectives. ArXiv, 2016.
- Yang, Y., & Hospedales, T. M. A Unified Perspective on Multi-Domain and Multi-Task Learning. ICLR, 2015.