GVS5H: Five Qwen3.8-27B Models Match Claude Fable 5 on LiveCodeBench Hard
GVS5H: Gorilla vs. 5 Humans
Results
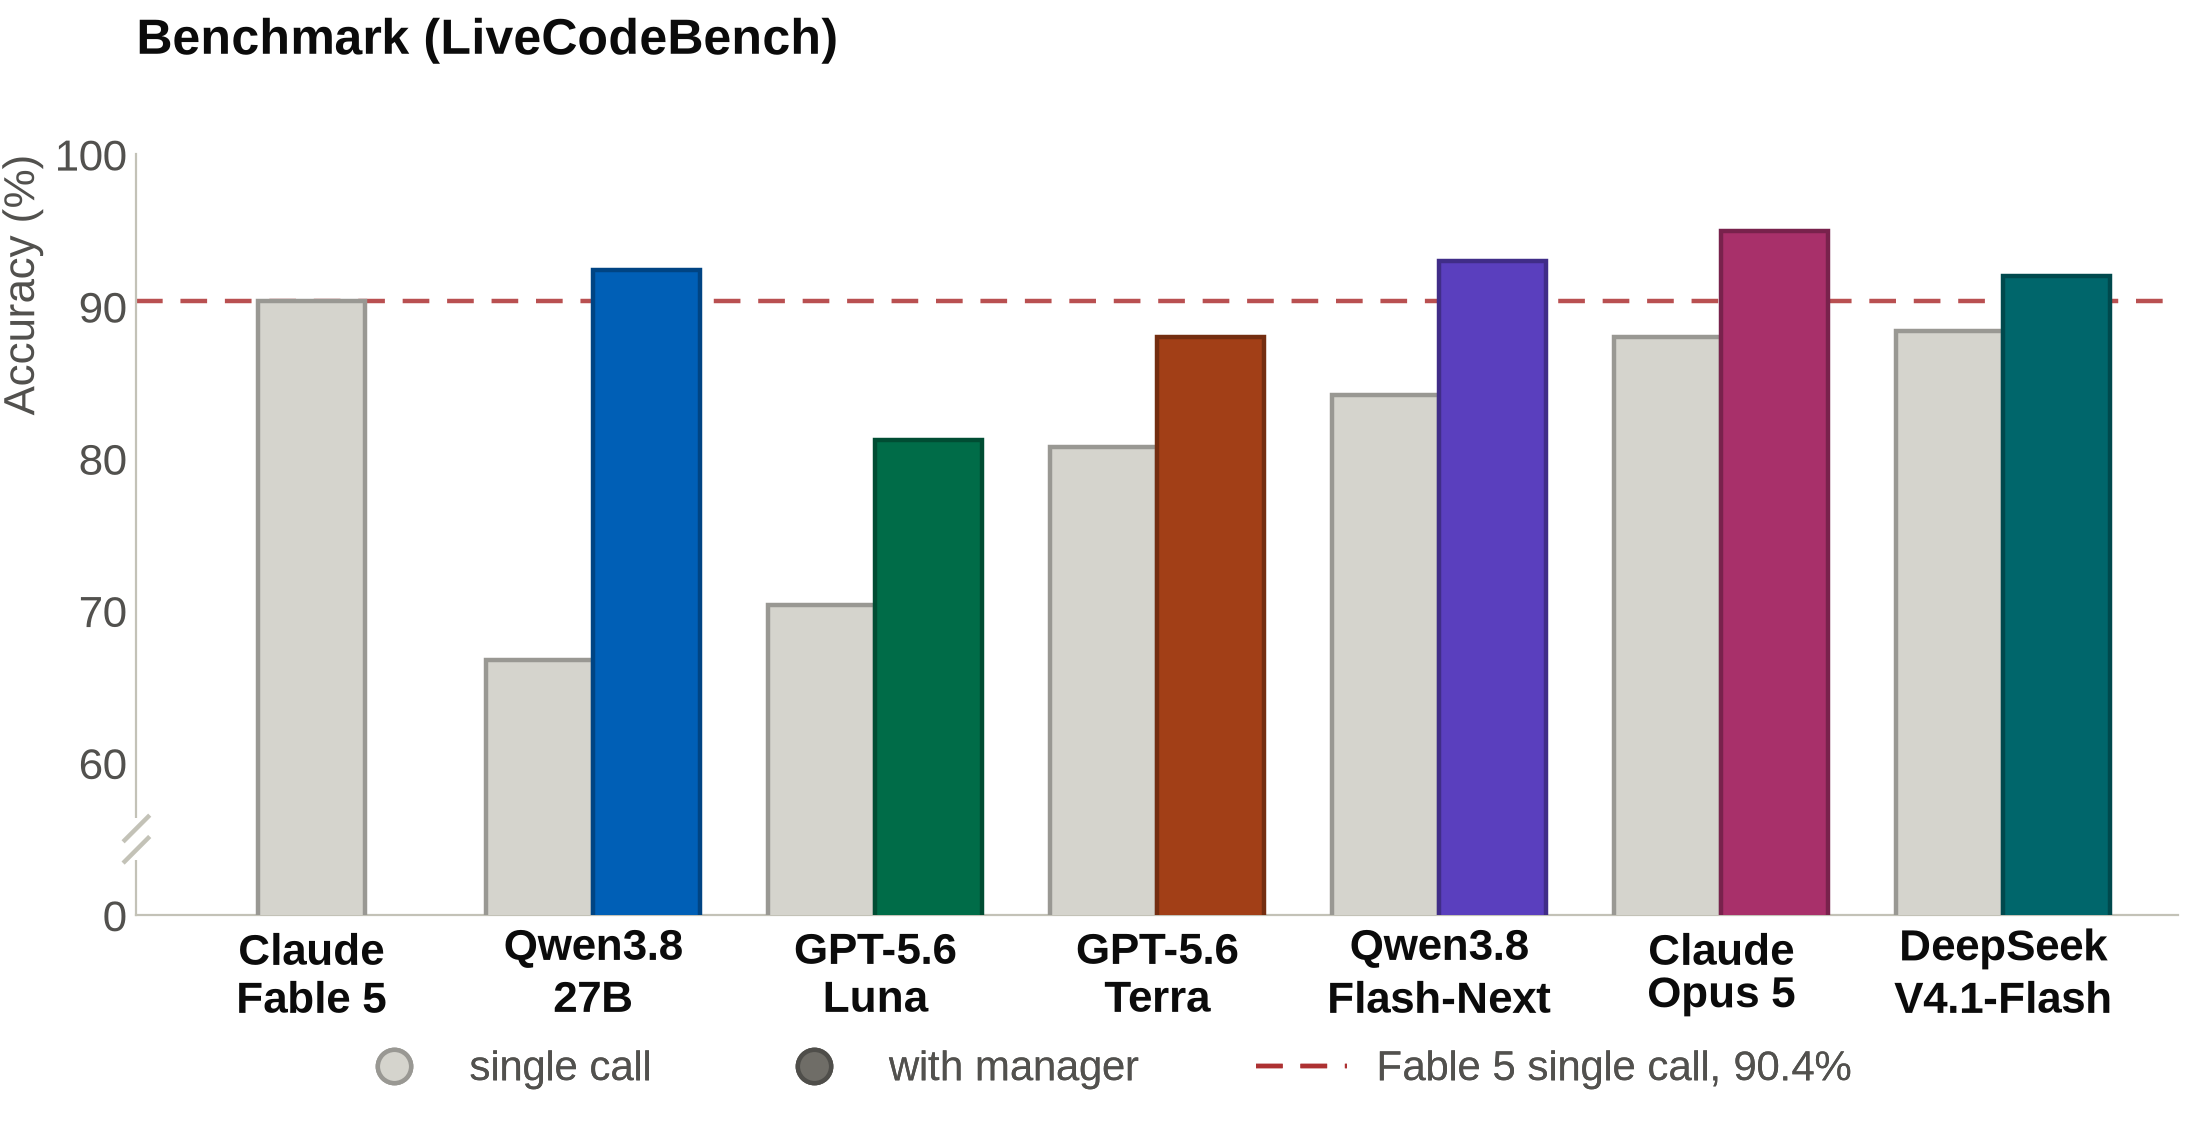
Opus 5 ran on an earlier version of the scaffold, in a single pass served through OpenRouter rather than five on a pinned backend.
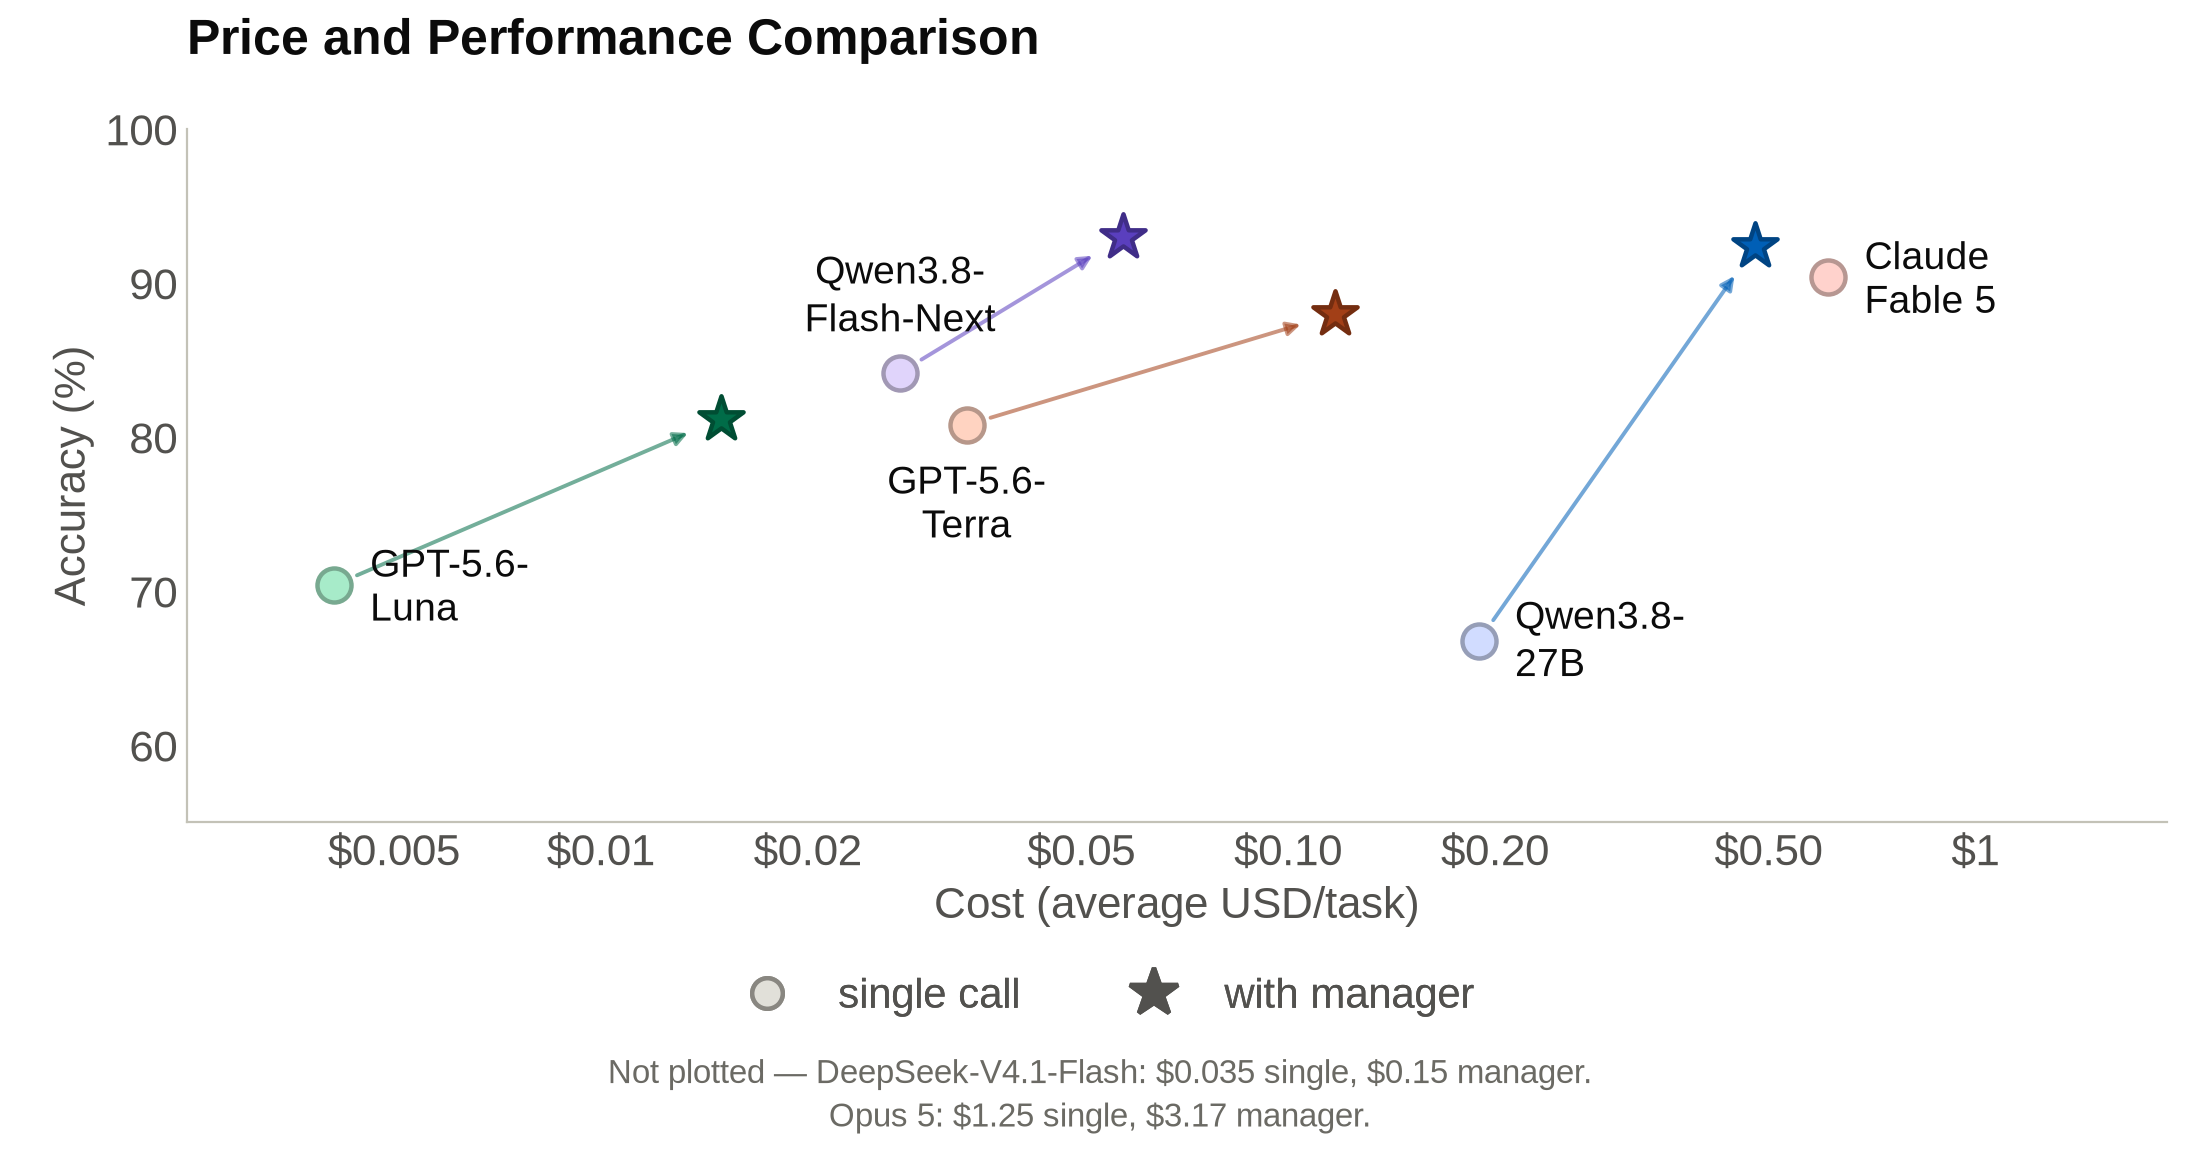
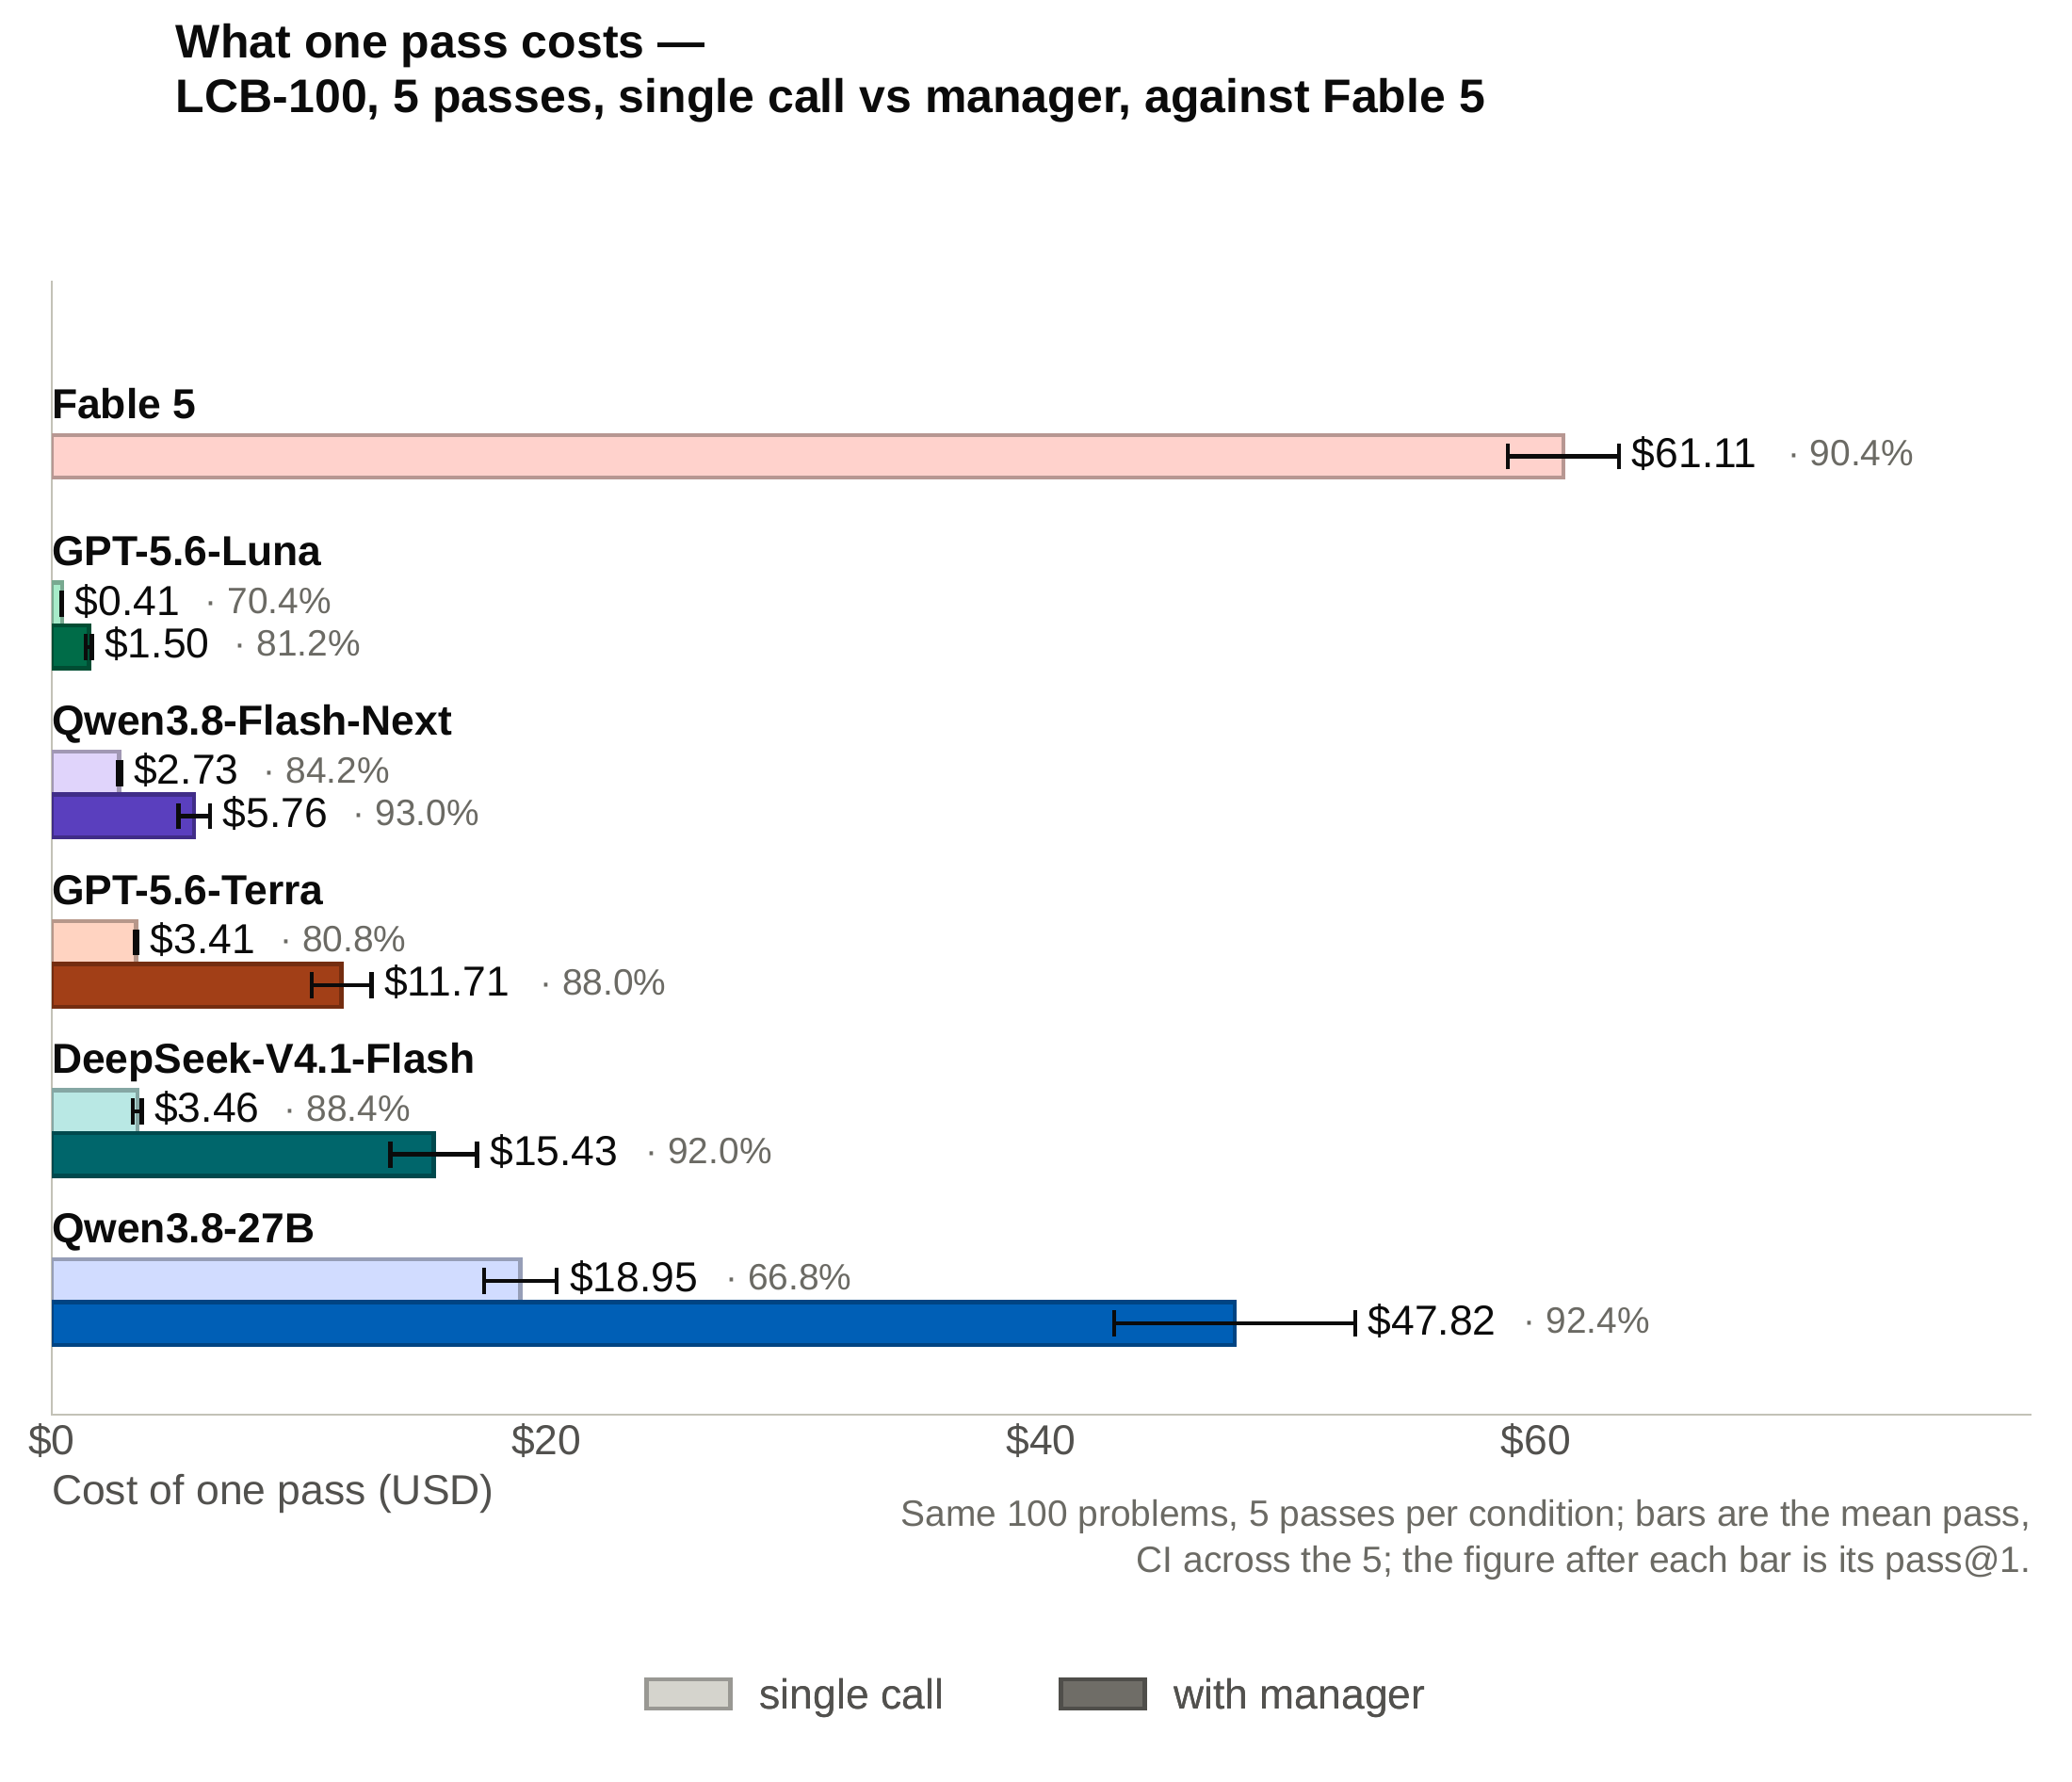
Abstract. Frontier coding performance is typically bought with larger proprietary models at high cost. We introduce ledger-based zero-shot self-orchestration, a training-free method in which fresh instances of one model decompose problems and coordinate through a shared filesystem holding a plan, notes and current solution. Across eleven open and closed-weight models on the 100 latest hard LiveCodeBench problems, the method yields gains of up to 25.6 percentage points on pinned backends and offers two routes to frontier-level accuracy. Orchestrated Qwen3.8 Flash Next reaches 93.0% pass@1 against Fable 5's 90.4% at 9% of the cost, and locally served, open-weight Qwen3.8-27B rises from 66.8% to 92.4%. Gains are not universal: some models are unchanged or worse. Transcript analysis attributes the gain to decomposition and persistent context. Inference-time organization can approach frontier coding accuracy at a fraction of the cost, or slightly exceed it on self-hostable weights.
Running the code
Needs uv and an API key for the model you want to test.
cd codebase/v2-current
export OPENAI_API_KEY=...

LCB_RELEASE=release_v6 \
ESCALATION_CLOUD_MAX_TOKENS=128000 \
ESCALATION_CLOUD_TIMEOUT=7200 \
MULTIAGENT_MODEL=openai:gpt-5.6-terra \
uv run --no-project --python 3.12 --with 'datasets<4' --with numpy --with anthropic \
  python escalation/run_bench.py --engine multiagent --only lcb --lcb 100 --parallel 8
--engine multiagentruns the manager;--engine singleis the one-call baseline.- Other models:
anthropic:,dashscope:,openrouter:, each with its own*_API_KEY. - The pass@1 score prints at the end. Results are written to
runs/results.json, workspaces toruns/ws/.
License
Code is under the MIT License. The paper, figures and run data are under CC BY 4.0. The LiveCodeBench fork, the benchmark problem statements and the LaTeX template files keep their own licenses. See NOTICE.md for which license covers which path.