Awesome Video Diffusion 
A curated list of recent diffusion models for video generation, editing, restoration, understanding, nerf, etc.
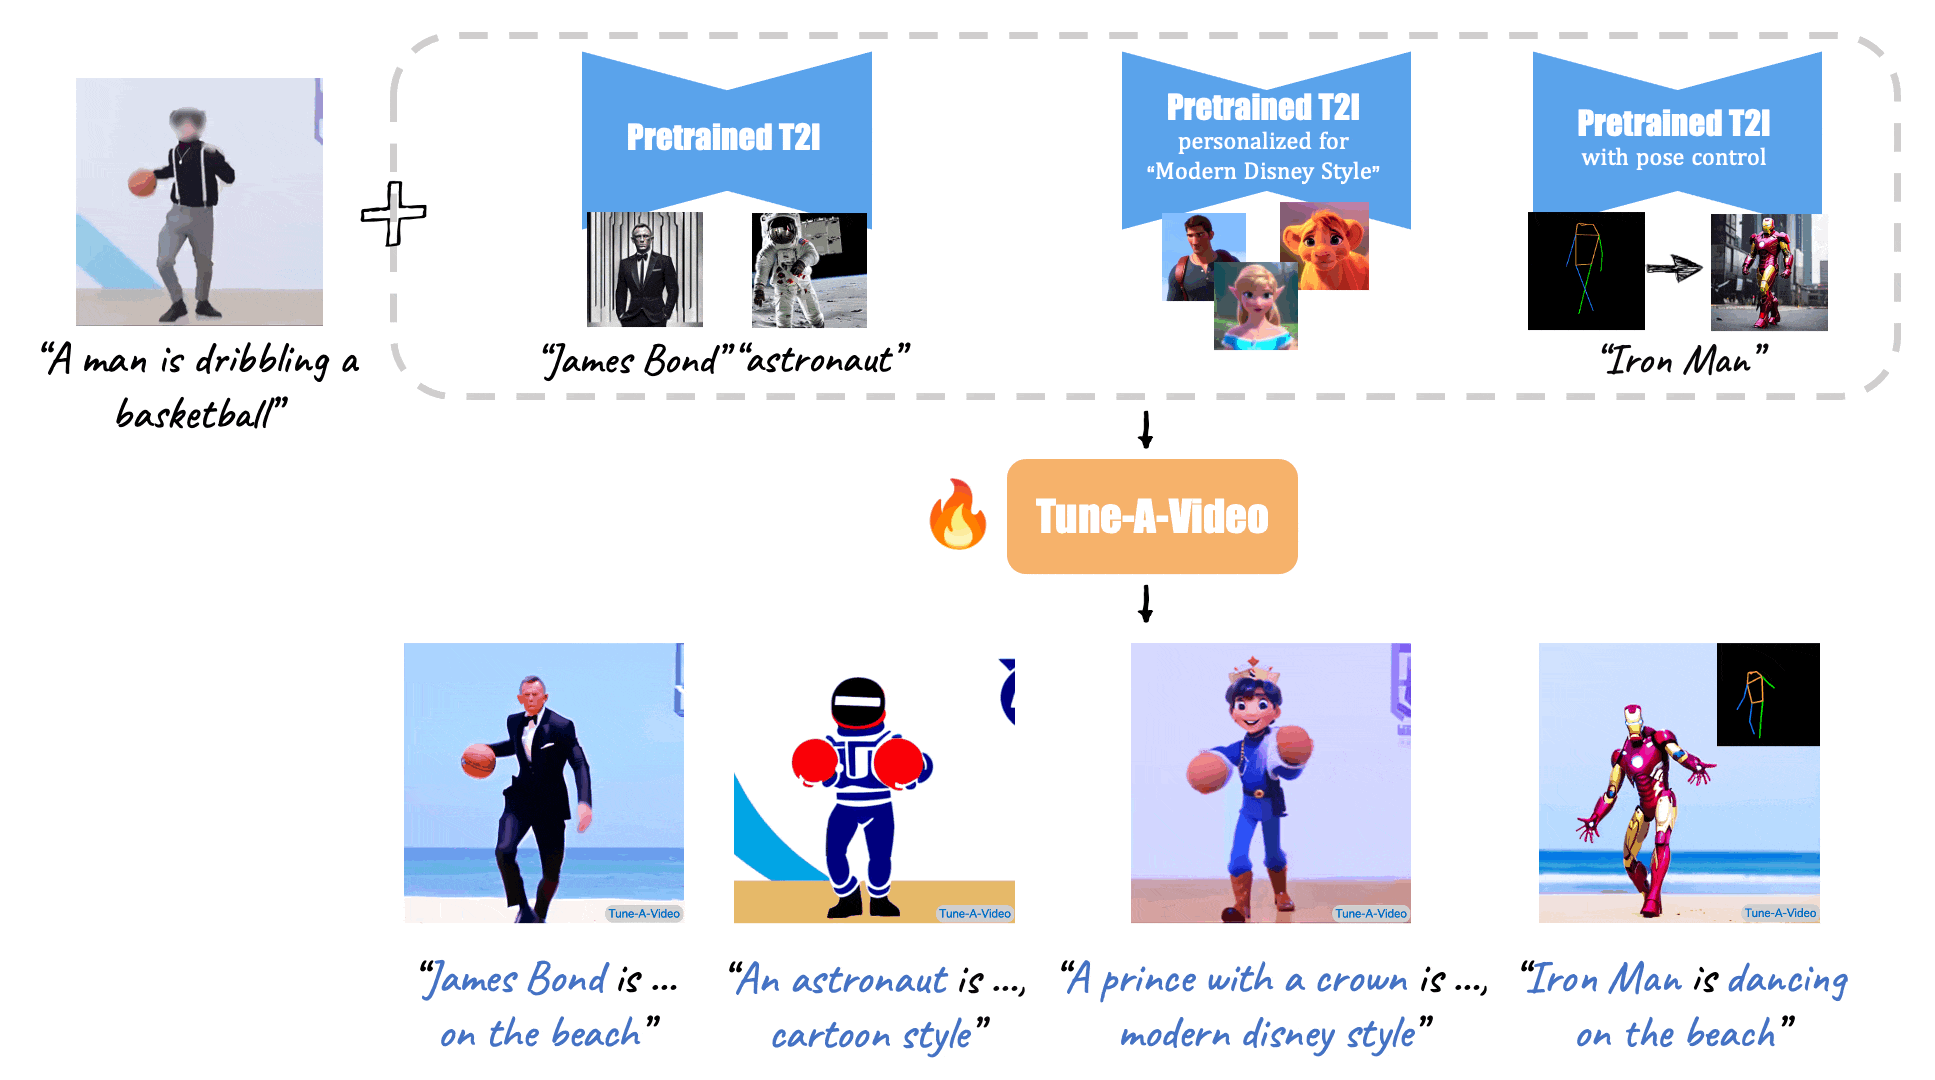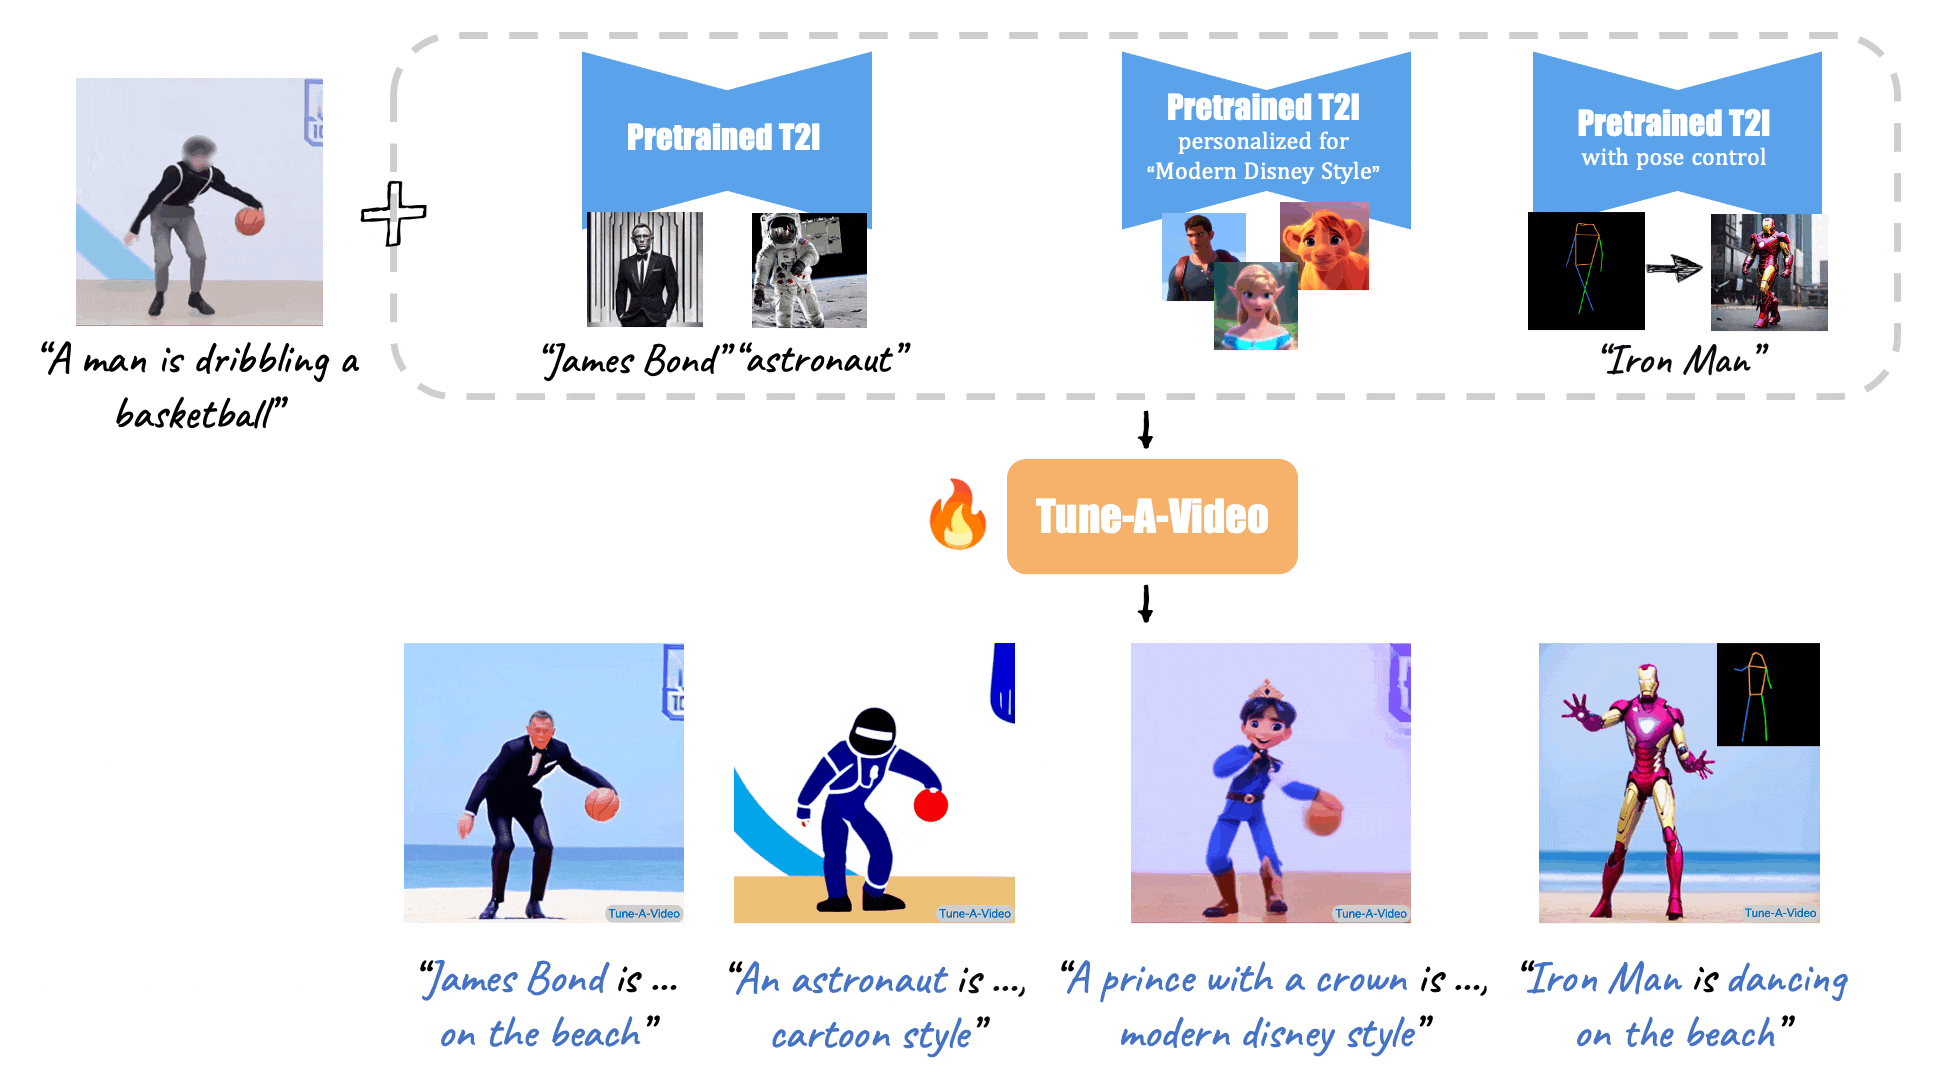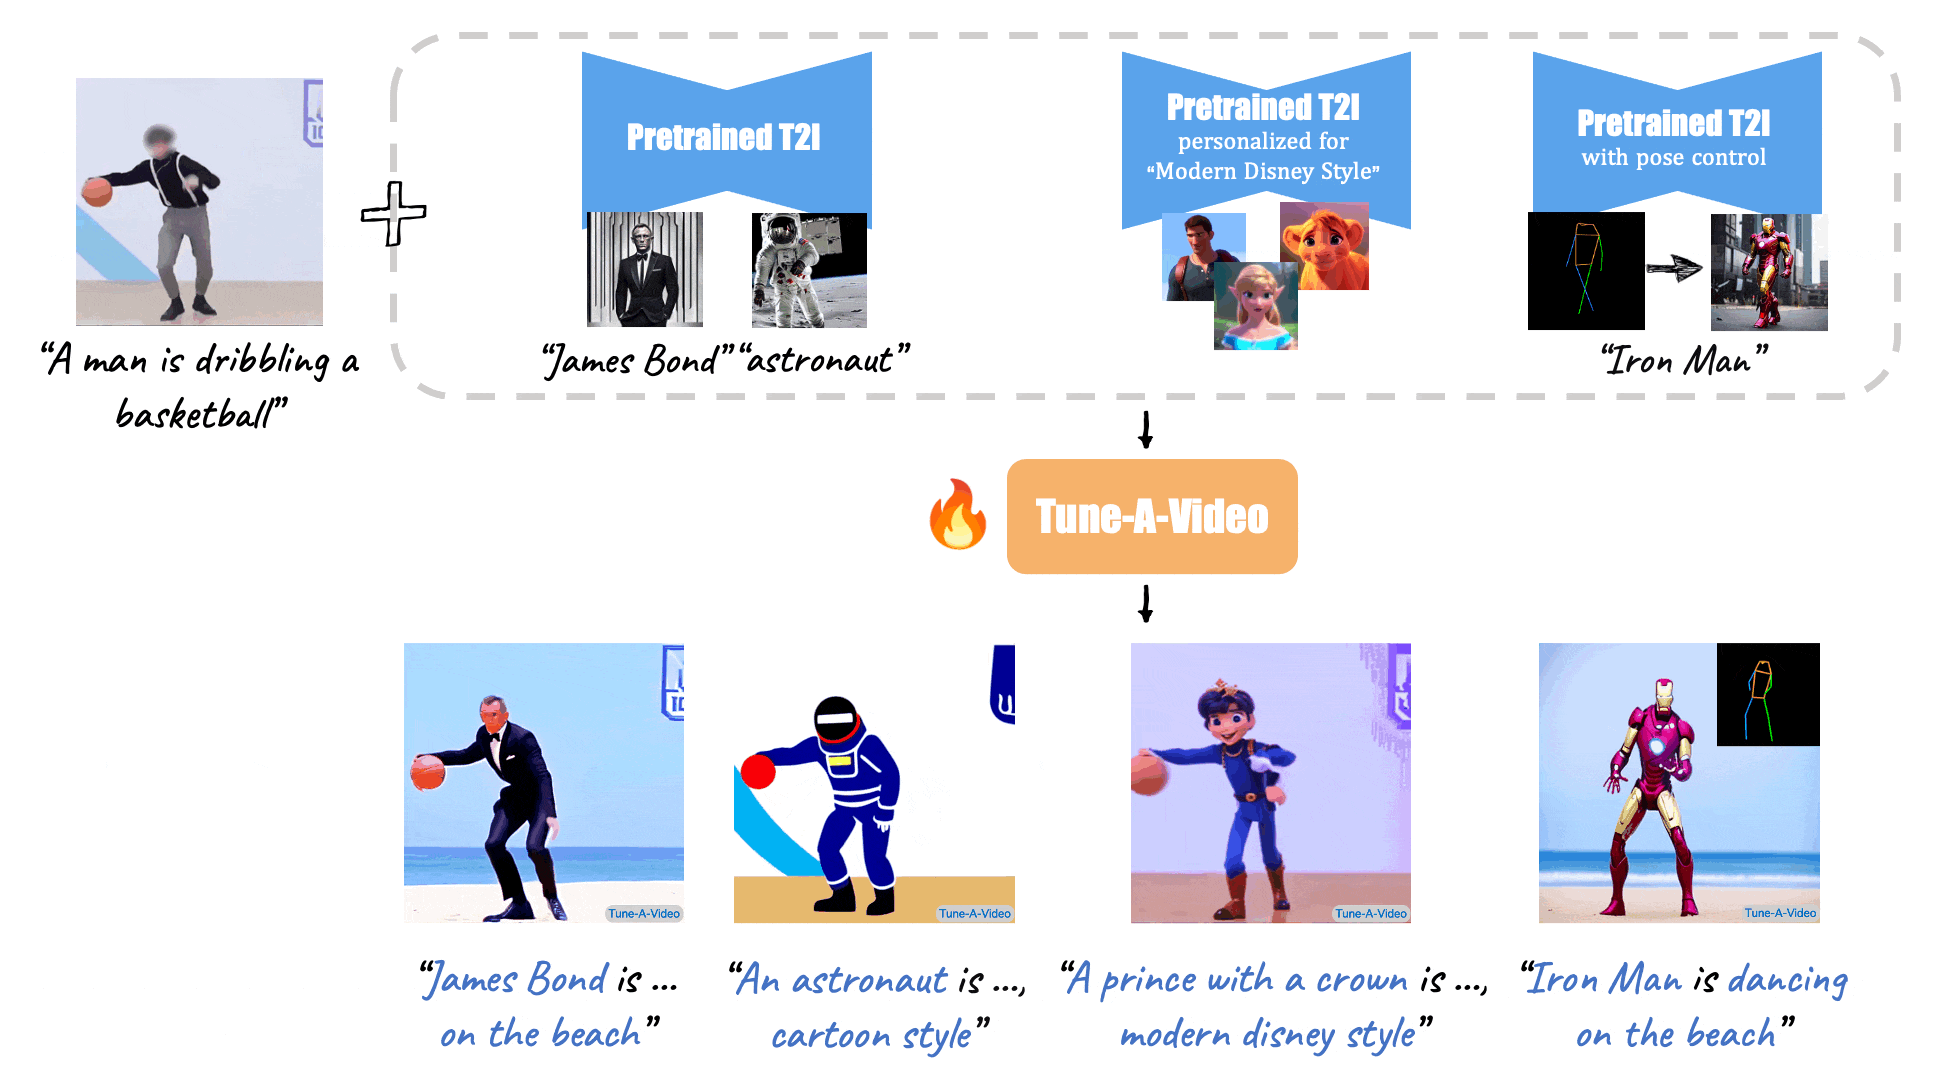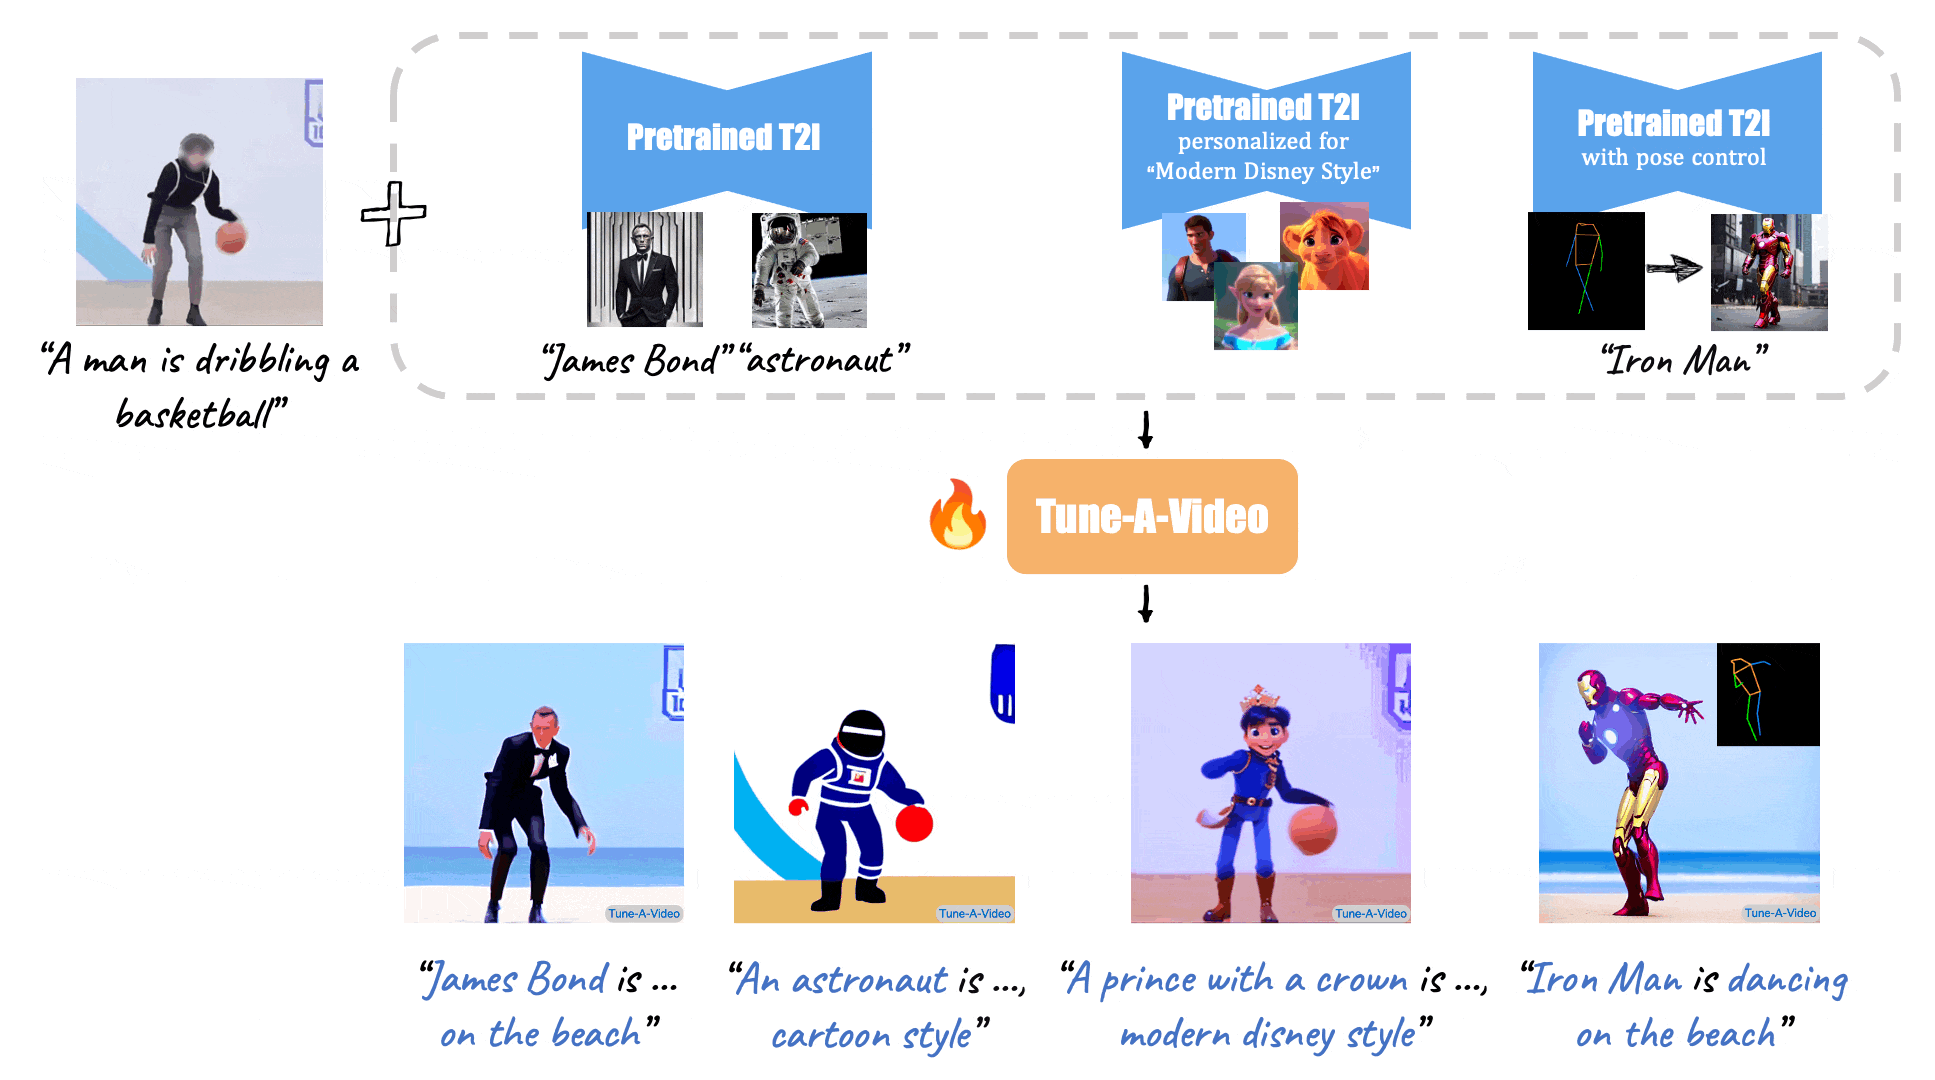


(Source: Make-A-Video, Tune-A-Video, and Fate/Zero.)
Table of Contents
- Open-source Toolboxes and Foundation Models
- Evaluation Benchmarks and Metrics
- Commercial Product
- Video Generation
- Efficient Video Generation
- Controllable Video Generation
- Character Customization
- Motion Customization
- Long Video / Film Generation
- Video Generation with 3D/Physical Prior
- Video Editing
- Human or Subject Motion
- Video Enhancement and Restoration
- Audio Synthesis for Video
- Talking Head Generation
- Reinforcement Learning for Video Generation
- Policy Learning
- Virtual Try-On
- 3D
- 4D
- Game Generation
- AI Safety
- Rendering with Virtual Engine
- Open-World Model
- Video Understanding
- Healthcare and Biology
- Other Applications
- Code-rendered Video Generation
Open-source Toolboxes and Foundation Models
-
Omni-Rewriter

Open agentic prompt-expansion harness for image/video generation (schema → validate → bounded repair → dialect render; H3/Seedance/Seedream/Qwen-Image). Expand ≠ generate. -
NanoI2V

A step-by-step teaching series for building an Image-to-Video model from scratch in PyTorch, covering 3D VAEs, DiT, Flow Matching, RoPE, and conditioning. -
FastVideo: A unified inference and post-training framework for accelerated video generation

-
Step-Video-T2V Technical Report: The Practice, Challenges, and Future of Video Foundation Model


-
HunyuanVideo: A Systematic Framework For Large Video Generative Models

-
Pyramidal Flow Matching for Efficient Video Generative Modeling

-
VideoCrafter: A Toolkit for Text-to-Video Generation and Editing


Evaluation Benchmarks and Metrics
-
LikePhys: Evaluating Intuitive Physics Understanding in Video Diffusion Models via Likelihood Preference (Oct., 2025)
-
Stable Cinemetrics: Structured Taxonomy and Evaluation for Professional Video Generation (Sep., 2025)
-
OpenS2V-Nexus: A Detailed Benchmark and Million-Scale Dataset for Subject-to-Video Generation (Mar., 2025)

-
VBench-2.0: Advancing Video Generation Benchmark Suite for Intrinsic Faithfulness (Mar., 2025)

-
Impossible Videos (Mar., 2025)

-
MEt3R: Measuring Multi-View Consistency in Generated Images (Jan., 2025)

-
Is Your World Simulator a Good Story Presenter? A Consecutive Events-Based Benchmark for Future Long Video Generation (Dec., 2024)

-
Evaluation Agent, Efficient and Promptable Evaluation Framework for Visual Generative Models (Dec., 2024)

-
Frechet Video Motion Distance: A Metric for Evaluating Motion Consistency in Videos (Jun., 2024)

-
T2V-CompBench: A Comprehensive Benchmark for Compositional Text-to-video Generation (Jun., 2024)

-
ChronoMagic-Bench: A Benchmark for Metamorphic Evaluation of Text-to-Time-lapse Video Generation (NeurIPS, 2024)

-
PEEKABOO: Interactive Video Generation via Masked-Diffusion (CVPR, 2024)

-
T2VScore: Towards A Better Metric for Text-to-Video Generation (Jan., 2024)

-
StoryBench: A Multifaceted Benchmark for Continuous Story Visualization (NeurIPS, 2023)

-
VBench: Comprehensive Benchmark Suite for Video Generative Models (Nov., 2023)
-
FETV: A Benchmark for Fine-Grained Evaluation of Open-Domain Text-to-Video Generation (Nov., 2023)

-
EvalCrafter: Benchmarking and Evaluating Large Video Generation Models (Oct., 2023)

-
Evaluation of Text-to-Video Generation Models: A Dynamics Perspective (Jul., 2024)

-
VidProM: A Million-scale Real Prompt-Gallery Dataset for Text-to-Video Diffusion Models (May., 2024)

-
Panda-70M: Captioning 70M Videos with Multiple Cross-Modality Teachers (CVPR, 2024)

-
ReLight My NeRF: A Dataset for Novel View Synthesis and Relighting of Real World Objects (CVPR, 2023)

Commercial Product
Video Generation
-
Helios: Real Real-Time Long Video Generation Model (Mar., 2026)

-
MOVA: Towards Scalable and Synchronized Video-Audio Generation (Feb., 2026)

-
VINO: A Unified Visual Generator with Interleaved OmniModal Context (Jan., 2026)

-
UltraViCo: Breaking Extrapolation Limits in Video Diffusion Transformers (Oct., 2025)

-
VISTA: A Test-Time Self-Improving Video Generation Agent (Oct., 2025 | CVPR 2026)
-
UniVideo: Unified Understanding, Generation, and Editing for Videos (Oct., 2025)

-
PUSA V1.0: Surpassing Wan-I2V with $500 Training Cost by Vectorized Timestep Adaptation (July., 2025)

-
LayerFlow : A Unified Model for Layer-aware Video Generation (May., 2025)

-
InfLVG: Reinforce Inference-Time Consistent Long Video Generation with GRPO (May., 2025)

-
Training-Free Efficient Video Generation via Dynamic Token Carving (May., 2025)
-
Turbo2K: Towards Ultra-Efficient and High-Quality 2K Video Synthesis (Apr., 2025)
-
MAGI-1: Autoregressive Video Generation at Scale (Apr., 2025)

-
SphereDiff: Tuning-free Omnidirectional Panoramic Image and Video Generation via Spherical Latent Representation (Apr., 2025)

-
Packing Input Frame Context in Next-Frame Prediction Models for Video Generation (Apr., 2025)

-
SkyReels-V2: Infinite-length Film Generative Model (Apr., 2025)

-
Seaweed-7B: Cost-Effective Training of Video Generation Foundation Model (Apr., 2025)
-
Aligning Text-to-Video Generation Models with Prompt Optimization (Mar., 2025)

-
Target-Aware Video Diffusion Models (Mar., 2025)

-
MagicComp: Training-free Dual-Phase Refinement for Compositional Video Generation (Mar., 2025)

-
Video-T1: Test-Time Scaling for Video Generation (Mar., 2025)

-
Temporal Regularization Makes Your Video Generator Stronger (Mar., 2025)
-
VACE: All-in-One Video Creation and Editing (Mar., 2025)

-
RIFLEx: A Free Lunch for Length Extrapolation in Video Diffusion Transformers (Feb., 2025)
-
DLFR-VAE: Dynamic Latent Frame Rate VAE for Video Generation (Feb., 2025)
-
Magic 1-For-1: Generating One Minute Video Clips within One Minute (Feb., 2025)

-
Lumina-Video: Efficient and Flexible Video Generation with Multi-scale Next-DiT (Feb., 2025)

-
Inference-Time Text-to-Video Alignment with Diffusion Latent Beam Search (Jan., 2025)

-
RepVideo: Rethinking Cross-Layer Representation for Video Generation (Jan., 2025)

-
Large Motion Video Autoencoding with Cross-modal Video VAE (Dec., 2024)
-
MotiF: Making Text Count in Image Animation with Motion Focal Loss (Dec., 2024)
-
VideoDPO: Omni-Preference Alignment for Video Diffusion Generation (Dec., 2024)
-
Autoregressive Video Generation without Vector Quantization (Dec., 2024)

-
AniDoc: Animation Creation Made Easier (Dec., 2024)

-
Video Diffusion Transformers are In-Context Learners (Dec., 2024)

-
Track4Gen: Teaching Video Diffusion Models to Track Points Improves Video Generation (Dec., 2024 | CVPR 2025)
-
Instructional Video Generation (Dec., 2024)
-
Mimir: Improving Video Diffusion Models for Precise Text Understanding (Dec., 2024)
-
Spatiotemporal Skip Guidance for Enhanced Video Diffusion Sampling (Dec., 2024)

-
Identity-Preserving Text-to-Video Generation by Frequency Decomposition (Nov., 2024)

-
WF-VAE: Enhancing Video VAE by Wavelet-Driven Energy Flow for Latent Video Diffusion Model (Nov., 2024)

-
VideoRepair: Improving Text-to-Video Generation via Misalignment Evaluation and Localized Refinement (Nov., 2024)

-
Enhancing Motion in Text-to-Video Generation with Decomposed Encoding and Conditioning (Oct., 2024 | NeurIPS 2024)

-
Improved Video VAE for Latent Video Diffusion Model (Oct., 2024)
-
Progressive Autoregressive Video Diffusion Models (Oct., 2024)

-
Real-Time Video Generation with Pyramid Attention Broadcast (Aug., 2024)

-
xGen-VideoSyn-1: High-fidelity Text-to-Video Synthesis with Compressed Representations (Aug., 2024)

-
CogVideoX: Text-to-video generation (Aug., 2024)

-
FreeLong: Training-Free Long Video Generation with SpectralBlend Temporal Attention (Aug., 2024)
-
VEnhancer: Generative Space-Time Enhancement for Video Generation (Jul., 2024)

-
Live2Diff: Live Stream Translation via Uni-directional Attention in Video Diffusion Models (Jul., 2024)

-
Video Diffusion Alignment via Reward Gradient (Jul., 2024)

-
ExVideo: Extending Video Diffusion Models via Parameter-Efficient Post-Tuning (Jun., 2024)
-
MimicMotion: High-Quality Human Motion Video Generation with Confidence-aware Pose Guidance (Jul., 2024)

-
Identifying and Solving Conditional Image Leakage in Image-to-Video Diffusion Model (Jun., 2024)

-
Video-Infinity: Distributed Long Video Generation (Jun., 2024)
-
MotionBooth: Motion-Aware Customized Text-to-Video Generation (Jun., 2024)
-
Text-Animator: Controllable Visual Text Video Generation (Jun., 2024)
-
UniAnimate: Taming Unified Video Diffusion Models for Consistent Human Image Animation (Jun., 2024)
-
T2V-Turbo: Breaking the Quality Bottleneck of Video Consistency Model with Mixed Reward Feedback (May, 2024)
-
Collaborative Video Diffusion: Consistent Multi-video Generation with Camera Control (May, 2024)
-
Human4DiT: Free-view Human Video Generation with 4D Diffusion Transformer (May, 2024)
-
FIFO-Diffusion: Generating Infinite Videos from Text without Training (May, 2024)

-
Vidu: a Highly Consistent, Dynamic and Skilled Text-to-Video Generator with Diffusion Models (May, 2024)
-
StoryDiffusion: Consistent Self-Attention for Long-Range Image and Video Generation (May, 2024)

-
TI2V-Zero: Zero-Shot Image Conditioning for Text-to-Video Diffusion Models (CVPR 2024)

-
ID-Animator: Zero-Shot Identity-Preserving Human Video Generation (Apr., 2024)

-
AnimateZoo: Zero-shot Video Generation of Cross-Species Animation via Subject Alignment (Apr., 2024)

-
MagicTime: Time-lapse Video Generation Models as Metamorphic Simulators (Apr., 2024)

-
TRIP: Temporal Residual Learning with Image Noise Prior for Image-to-Video Diffusion Models (CVPR 2024)
-
VSTAR: Generative Temporal Nursing for Longer Dynamic Video Synthesis (Mar., 2024)
-
StreamingT2V: Consistent, Dynamic, and Extendable Long Video Generation from Text (Mar., 2024)

-
Intention-driven Ego-to-Exo Video Generation (Mar., 2024)
-
VideoElevator: Elevating Video Generation Quality with Versatile Text-to-Image Diffusion Models (Mar., 2024)

-
Snap Video: Scaled Spatiotemporal Transformers for Text-to-Video Synthesis (Feb., 2024)
-
One-Shot Motion Customization of Text-to-Video Diffusion Models (Feb., 2024)
-
Magic-Me: Identity-Specific Video Customized Diffusion (Feb., 2024)

-
ConsistI2V: Enhancing Visual Consistency for Image-to-Video Generation (Feb., 2024)

-
Direct-a-Video: Customized Video Generation with User-Directed Camera Movement and Object Motion (Feb., 2024)
-
Video-LaVIT: Unified Video-Language Pre-training with Decoupled Visual-Motional Tokenization (Feb., 2024)

-
Boximator: Generating Rich and Controllable Motions for Video Synthesis (Feb., 2024)
-
Lumiere: A Space-Time Diffusion Model for Video Generation (Jan., 2024)
-
ActAnywhere: Subject-Aware Video Background Generation (Jan., 2024)
-
WorldDreamer: Towards General World Models for Video Generation via Predicting Masked Tokens (Jan., 2024)

-
CustomVideo: Customizing Text-to-Video Generation with Multiple Subjects (Jan., 2024)
-
UniVG: Towards UNIfied-modal Video Generation (Jan., 2024)
-
VideoCrafter2: Overcoming Data Limitations for High-Quality Video Diffusion Models (Jan., 2024)

-
360DVD: Controllable Panorama Video Generation with 360-Degree Video Diffusion Model (Jan., 2024)
-
RAVEN: Rethinking Adversarial Video Generation with Efficient Tri-plane Networks (Jan., 2024)
-
Latte: Latent Diffusion Transformer for Video Generation (Jan., 2024)

-
MagicVideo-V2: Multi-Stage High-Aesthetic Video Generation (Jan., 2024)
-
VideoDrafter: Content-Consistent Multi-Scene Video Generation with LLM (Jan., 2024)
-
FlashVideo: A Framework for Swift Inference in Text-to-Video Generation (Dec., 2023)
-
I2V-Adapter: A General Image-to-Video Adapter for Video Diffusion Models (Dec., 2023)
-
A Recipe for Scaling up Text-to-Video Generation with Text-free Videos (Dec., 2023)
-
PIA: Your Personalized Image Animator via Plug-and-Play Modules in Text-to-Image Models (Dec., 2023)

-
VideoPoet: A Large Language Model for Zero-Shot Video Generation (Dec., 2023)
-
InstructVideo: Instructing Video Diffusion Models with Human Feedback (Dec., 2023)

-
VideoLCM: Video Latent Consistency Model (Dec., 2023)
-
PEEKABOO: Interactive Video Generation via Masked-Diffusion (Dec., 2023)
-
FreeInit: Bridging Initialization Gap in Video Diffusion Models (Dec., 2023)

-
Photorealistic Video Generation with Diffusion Models (Dec., 2023)
-
Upscale-A-Video: Temporal-Consistent Diffusion Model for Real-World Video Super-Resolution (Dec., 2023)

-
DreaMoving: A Human Video Generation Framework based on Diffusion Models (Dec., 2023)

-
MotionCrafter: One-Shot Motion Customization of Diffusion Models (Dec., 2023)

-
AnimateZero: Video Diffusion Models are Zero-Shot Image Animators (Dec., 2023)

-
AVID: Any-Length Video Inpainting with Diffusion Model (Dec., 2023)

-
MTVG : Multi-text Video Generation with Text-to-Video Models (Dec., 2023)
-
DreamVideo: Composing Your Dream Videos with Customized Subject and Motion (Dec., 2023)
-
Hierarchical Spatio-temporal Decoupling for Text-to-Video Generation (Dec., 2023)
-
GenTron: Delving Deep into Diffusion Transformers for Image and Video Generation (CVPR 2024)
-
GenDeF: Learning Generative Deformation Field for Video Generation (Dec., 2023)

-
F3-Pruning: A Training-Free and Generalized Pruning Strategy towards Faster and Finer Text-to-Video Synthesis (Dec., 2023)
-
DreamVideo: High-Fidelity Image-to-Video Generation with Image Retention and Text Guidance (Dec., 2023)

-
LivePhoto: Real Image Animation with Text-guided Motion Control (Dec., 2023)

-
Fine-grained Controllable Video Generation via Object Appearance and Context (Dec., 2023)
-
VideoBooth: Diffusion-based Video Generation with Image Prompts (Dec., 2023)

-
StyleCrafter: Enhancing Stylized Text-to-Video Generation with Style Adapter (Dec., 2023)

-
MicroCinema: A Divide-and-Conquer Approach for Text-to-Video Generation (Nov., 2023)
-
ART•V: Auto-Regressive Text-to-Video Generation with Diffusion Models (Nov., 2023)

-
Smooth Video Synthesis with Noise Constraints on Diffusion Models for One-shot Video Tuning (Nov., 2023)

-
VideoAssembler: Identity-Consistent Video Generation with Reference Entities using Diffusion Model (Nov., 2023)
-
MotionZero:Exploiting Motion Priors for Zero-shot Text-to-Video Generation (Nov., 2023)
-
MagicAnimate: Temporally Consistent Human Image Animation using Diffusion Model (Nov., 2023)

-
FlowZero: Zero-Shot Text-to-Video Synthesis with LLM-Driven Dynamic Scene Syntax (Nov., 2023)

-
Sketch Video Synthesis (Nov., 2023)

-
Stable Video Diffusion: Scaling Latent Video Diffusion Models to Large Datasets (Nov., 2023)

-
Decouple Content and Motion for Conditional Image-to-Video Generation (Nov., 2023)
-
FusionFrames: Efficient Architectural Aspects for Text-to-Video Generation Pipeline (Nov., 2023)

-
Fine-Grained Open Domain Image Animation with Motion Guidance (Nov., 2023)

-
GPT4Motion: Scripting Physical Motions in Text-to-Video Generation via Blender-Oriented GPT Planning (Nov., 2023)

-
MagicDance: Realistic Human Dance Video Generation with Motions & Facial Expressions Transfer (Nov., 2023)

-
MoVideo: Motion-Aware Video Generation with Diffusion Models (Nov., 2023)
-
Make Pixels Dance: High-Dynamic Video Generation (Nov., 2023)
-
Emu Video: Factorizing Text-to-Video Generation by Explicit Image Conditioning (Nov., 2023)
-
Optimal Noise pursuit for Augmenting Text-to-Video Generation (Nov., 2023)
-
VideoDreamer: Customized Multi-Subject Text-to-Video Generation with Disen-Mix Finetuning (Nov., 2023)

-
SEINE: Short-to-Long Video Diffusion Model for Generative Transition and Prediction (Oct., 2023)

-
FreeNoise: Tuning-Free Longer Video Diffusion Via Noise Rescheduling (Oct., 2023)

-
DynamiCrafter: Animating Open-domain Images with Video Diffusion Priors (Oct., 2023)

-
LAMP: Learn A Motion Pattern for Few-Shot-Based Video Generation (Oct., 2023)

-
Show-1: Marrying Pixel and Latent Diffusion Models for Text-to-Video Generation (Sep., 2023)

-
MotionDirector: Motion Customization of Text-to-Video Diffusion Models (Sep., 2023)

-
LAVIE: High-Quality Video Generation with Cascaded Latent Diffusion Models (Sep., 2023)

-
Free-Bloom: Zero-Shot Text-to-Video Generator with LLM Director and LDM Animator (Sep., 2023)

-
Hierarchical Masked 3D Diffusion Model for Video Outpainting (Sep., 2023)
-
Reuse and Diffuse: Iterative Denoising for Text-to-Video Generation (Sep., 2023)

-
VideoGen: A Reference-Guided Latent Diffusion Approach for High Definition Text-to-Video Generation (Sep., 2023)
-
MagicAvatar: Multimodal Avatar Generation and Animation (Aug., 2023)

-
Empowering Dynamics-aware Text-to-Video Diffusion with Large Language Models (Aug., 2023)

-
SimDA: Simple Diffusion Adapter for Efficient Video Generation (Aug., 2023)

-
ModelScope Text-to-Video Technical Report (Aug., 2023)
-
Dual-Stream Diffusion Net for Text-to-Video Generation (Aug., 2023)
-
InternVid: A Large-scale Video-Text Dataset for Multimodal Understanding and Generation (Jul., 2023)

-
Animate-A-Story: Storytelling with Retrieval-Augmented Video Generation (Jul., 2023)

-
AnimateDiff: Animate Your Personalized Text-to-Image Diffusion Models without Specific Tuning (Jul., 2023)

-
DisCo: Disentangled Control for Referring Human Dance Generation in Real World (Jul., 2023)

-
Learn the Force We Can: Enabling Sparse Motion Control in Multi-Object Video Generation (Jun., 2023)

-
VideoComposer: Compositional Video Synthesis with Motion Controllability (Jun., 2023)

-
Probabilistic Adaptation of Text-to-Video Models (Jun., 2023)
-
Make-Your-Video: Customized Video Generation Using Textual and Structural Guidance (Jun., 2023)

-
Gen-L-Video: Multi-Text to Long Video Generation via Temporal Co-Denoising (May, 2023)

-
Cinematic Mindscapes: High-quality Video Reconstruction from Brain Activity (May, 2023)

-
Any-to-Any Generation via Composable Diffusion (May, 2023)

-
VideoFactory: Swap Attention in Spatiotemporal Diffusions for Text-to-Video Generation (May, 2023)
-
Preserve Your Own Correlation: A Noise Prior for Video Diffusion Models (May, 2023)
-
LaMD: Latent Motion Diffusion for Video Generation (Apr., 2023)
-
Align your Latents: High-Resolution Video Synthesis with Latent Diffusion Models (CVPR 2023)
-
Text2Performer: Text-Driven Human Video Generation (Apr., 2023)

-
Generative Disco: Text-to-Video Generation for Music Visualization (Apr., 2023)
-
Latent-Shift: Latent Diffusion with Temporal Shift (Apr., 2023)
-
DreamPose: Fashion Image-to-Video Synthesis via Stable Diffusion (Apr., 2023)

-
Follow Your Pose: Pose-Guided Text-to-Video Generation using Pose-Free Videos (Apr., 2023)

-
Physics-Driven Diffusion Models for Impact Sound Synthesis from Videos (CVPR 2023)

-
Seer: Language Instructed Video Prediction with Latent Diffusion Models (Mar., 2023)
-
Text2video-Zero: Text-to-Image Diffusion Models Are Zero-Shot Video Generators (Mar., 2023)

-
Conditional Image-to-Video Generation with Latent Flow Diffusion Models (CVPR 2023)

-
Decomposed Diffusion Models for High-Quality Video Generation (CVPR 2023)
-
Video Probabilistic Diffusion Models in Projected Latent Space (CVPR 2023)

-
Learning 3D Photography Videos via Self-supervised Diffusion on Single Images (Feb., 2023)
-
Structure and Content-Guided Video Synthesis With Diffusion Models (Feb., 2023)
-
Tune-A-Video: One-Shot Tuning of Image Diffusion Models for Text-to-Video Generation (ICCV 2023)
-
Mm-Diffusion: Learning Multi-Modal Diffusion Models for Joint Audio and Video Generation (CVPR 2023)

-
Magvit: Masked Generative Video Transformer (Dec., 2022)

-
VIDM: Video Implicit Diffusion Models (AAAI 2023)

-
Efficient Video Prediction via Sparsely Conditioned Flow Matching (Nov., 2022)

-
Latent Video Diffusion Models for High-Fidelity Video Generation With Arbitrary Lengths (Nov., 2022)

-
SinFusion: Training Diffusion Models on a Single Image or Video (Nov., 2022)
-
MagicVideo: Efficient Video Generation With Latent Diffusion Models (Nov., 2022)
-
Imagen Video: High Definition Video Generation With Diffusion Models (Oct., 2022)
-
Make-A-Video: Text-to-Video Generation without Text-Video Data (ICLR 2023)
-
Diffusion Models for Video Prediction and Infilling (TMLR 2022)

-
McVd: Masked Conditional Video Diffusion for Prediction, Generation, and Interpolation (NeurIPS 2022)
-
Video Diffusion Models (Apr., 2022)
-
Diffusion Probabilistic Modeling for Video Generation (Mar., 2022)


Efficient Video Generation
-
CachedSearch: Training-Free Cached Exploration for Test-Time Search in Video Diffusion (Jul., 2026)

-
SpargeAttn: Accurate Sparse Attention Accelerating Any Model Inference (Feb., 2025)
-
SageAttention2: Efficient Attention with Thorough Outlier Smoothing and Per-thread INT4 Quantization (Feb., 2025)
-
FlashVideo:Flowing Fidelity to Detail for Efficient High-Resolution Video Generation (Feb., 2025)

-
Fast Video Generation with Sliding Tile Attention (Feb, 2025)
-
Sparse VideoGen: Accelerating Video Diffusion Transformers with Spatial-Temporal Sparsity (Feb, 2025)
-
Diffusion Adversarial Post-Training for One-Step Video Generation (Jan, 2025)
-
From Slow Bidirectional to Fast Causal Video Generators (Dec., 2024)
-
SnapGen-V: Generating a Five-Second Video within Five Seconds on a Mobile Device (Dec., 2024)
-
Mobile Video Diffusion (Dec., 2024)
-
MoViE: Mobile Diffusion for Video Editing (Dec., 2024)
-
Individual Content and Motion Dynamics Preserved Pruning for Video Diffusion Models (Nov., 2024)
-
Adaptive Caching for Faster Video Generation with Diffusion Transformers (Nov., 2024)

-
Fast and Memory-Efficient Video Diffusion Using Streamlined Inference (Nov., 2024)
-
SageAttention: Accurate 8-Bit Attention for Plug-and-play Inference Acceleration (Oct., 2024)
Controllable Video Generation
-
LIFT: Layout-In-Future Video Generation under Large Viewpoint Change via On-Policy Self-Distillation (Sep., 2026)

-
ActionSplice: In-Flight Action Editing for Interactive World Models (Sep., 2026)

-
PhyCo: Learning Controllable Physical Priors for Generative Motion (CVPR 2026)

-
ID-Crafter: VLM-Grounded Online RL for Compositional Multi-Subject Video Generation (CVPR, 2026)

-
Video-As-Prompt: Unified Semantic Control for Video Generation (Nov, 2025)

-
EgoControl: Controllable Egocentric Video Generation via 3D Full-Body Poses (CVPR 2026)

-
Hand2World: Autoregressive Egocentric Interaction Generation via Free-Space Hand Gestures (Feb, 2026)
-
ATI: Any Trajectory Instruction for Controllable Video Generation (Jun., 2025)

-
TC-Light: Temporally Coherent Generative Rendering for Realistic World Transfer (Jun., 2025)

-
IllumiCraft: Unified Geometry and Illumination Diffusion for Controllable Video Generation (Jun., 2025)

-
Frame In-N-Out: Unbounded Controllable Image-to-Video Generation (May, 2025)
-
VideoPainter: Any-length Video Inpainting and Editing with Plug-and-Play Context Control (May, 2025 | SIGGRAPH 2025)

-
FlexiAct: Towards Flexible Action Control in Heterogeneous Scenarios (May, 2025 | SIGGRAPH 2025)

-
Dynamic Camera Poses and Where to Find Them (Apr., 2025)
-
GenDoP: Auto-regressive Camera Trajectory Generation as a Director of Photography (Apr., 2025)

-
OmniVDiff: Omni Controllable Video Diffusion for Generation and Understanding (Apr., 2025)

-
UniAnimate-DiT: Human Image Animation with Large-Scale Video Diffusion Transformer (Apr., 2025)

-
GenDoP: Auto-regressive Camera Trajectory Generation as a Director of Photography (Apr., 2025)
-
Beyond Static Scenes: Camera-controllable Background Generation for Human Motion (Apr., 2025)

-
SketchVideo: Sketch-based Video Generation and Editing (Apr., 2025)

-
Any2Caption:Interpreting Any Condition to Caption for Controllable Video Generation (Apr., 2025)
-
Reangle-A-Video: 4D Video Generation as Video-to-Video Translation (Mar., 2025)

-
DynamiCtrl: Rethinking the Basic Structure and the Role of Text for High-quality Human Image Animation (Mar., 2025)

-
HunyuanPortrait: Implicit Condition Control for Enhanced Portrait Animation (Mar., 2025)

-
Enabling Versatile Controls for Video Diffusion Models (Mar., 2025)

-
MagicMotion: Controllable Video Generation with Dense-to-Sparse Trajectory Guidance (Mar., 2025)

-
MusicInfuser: Making Video Diffusion Listen and Dance (Mar., 2025)

-
ReCamMaster: Camera-Controlled Generative Rendering from A Single Video (Mar., 2025)

-
CameraCtrl II: Dynamic Scene Exploration via Camera-controlled Video Diffusion Models (Mar., 2025)
-
[GEN3C: 3D-Informed World-Consistent Video Generation