FAIR's research platform for object detection research, implementing popular algorithms like Mask R-CNN and RetinaNet.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Category
Models
Subcategory
Foundation models, Vision models
Keywords
Inference optimization, Multimodal, Text-to-video, Video production
Stars
508
Forks
12
Contributors
3
Created date
2026-07-03
Updated date
2026-10-16
Stars in 1 day
2
Rank
4,317
Previous rank
7,078
Rank change
2,761
7-day stars rank
19,345
Previous 7-day stars rank
19,331
7-day stars rank change
-14
Total stars rank
19,113
Previous total stars rank
19,155
Total stars rank change
42
README summary
Vidu S Introduction Vidu S2 Vidu S2 extends real-time video generation beyond talking-head digital characters to high-resolution interactive avatars, live video editing, and immersive spatial video. It includes Vidu S2-Avatar for controllable character generation and Vidu S2-Editing for transforming live video streams. **720p real-time interactive avatars** Vidu S2-Avatar generates 720p video at 25–42 FPS, supports complex instructions such as dancing, and accepts new reference images at any moment during streaming. **Stable long
-horizon generation with Self-Replay Forcing** Self-Replay Forcing replays re-noised, self-generated trajectories during training to reduce error accumulation across streaming segments. **Real-time editing of live video** Vidu S2-Editing transforms incoming video streams using reference images, supporting style transfer, virtual try-on, character replacement, and background replacement while preserving source motion. **Real-time spatial video for immersive displays** Produces synchronized stereo views for immersive displays and VR headsets. **Efficient inference on low-cost GPUs** TurboDiffusion and
TurboServe combine efficient attention, low-bit GEMM, kernel optimizations, and multi-GPU pipelining for real-time inference. Vidu S1 Vidu S1 is a real-time interactive video generation model for voice-controlled digital characters. Users can guide generated video content at any moment through spoken instructions, enabling live interaction. **Real-time speech control over video content** Users can directly instruct digital characters to perform actions. **Infinite-length real-time interactive generation** Vidu S1 generates 540p video at up to **42
FPS** and can run on consumer GPUs. **Custom character images and voice tones** Vidu S1 supports real people, anime-style characters, pets, and other personalized avatars. Quick Links Vidu S2 **Try Vidu S2**: **Vidu S2 Paper**: Vidu S1 **Vidu S1 Paper**: Docs English **User Guide**: shengshu. cn/wiki/X7ZLwyLUzi461LkAlNpcTxs1nsy **API Documentation**: platform. com/vidu-stream/doc **Vidu S2-Avatar Quickstart**: platform. com/vidu-stream/doc/s2-avatar/realtime/quick-start **Vidu S2-Editing Quickstart**: platform. com/vidu-stream/doc/s2
-editing/quick-start Chinese **User Guide**: shengshu. cn/wiki/Fz8ywkzEwil84LkbCOKcxotMnvb **API Documentation**: platform. cn/vidu-stream/doc **Vidu S2-Avatar Quickstart**: platform. cn/vidu-stream/doc/s2-avatar/realtime/quick-start **Vidu S2-Editing Quickstart**: platform. cn/vidu-stream/doc/s2-editing/quick-start Agent Skill For agent-assisted API integration, use the Skill. In Claude Code, Codex, OpenClaw, or any agent that supports Skills, say directly: The agent will clone and install it into the proper Skills directory. Restart
the agent if required, then ask it to load for Vidu S2 API integration. Updates **[2026-09]**: Vidu S2 is now available to try at vidu. com/vidu-stream **[2026-07]**: Vidu S1 is now available. Citation If you find Vidu S useful for your research, please cite:
Frequently asked questions
How many stars and forks are recorded?
shengshu-ai/Vidu-S has 508 stars and 12 forks.
What is the repository rank?
shengshu-ai/Vidu-S is ranked 4,317.
Which repository is closest in rank?
shengshu-ai/Vidu-S is compared with bubbliiiing/segformer-pytorch, ranked 4,310 with 515 stars.
README
Vidu S
Introduction
Vidu S2
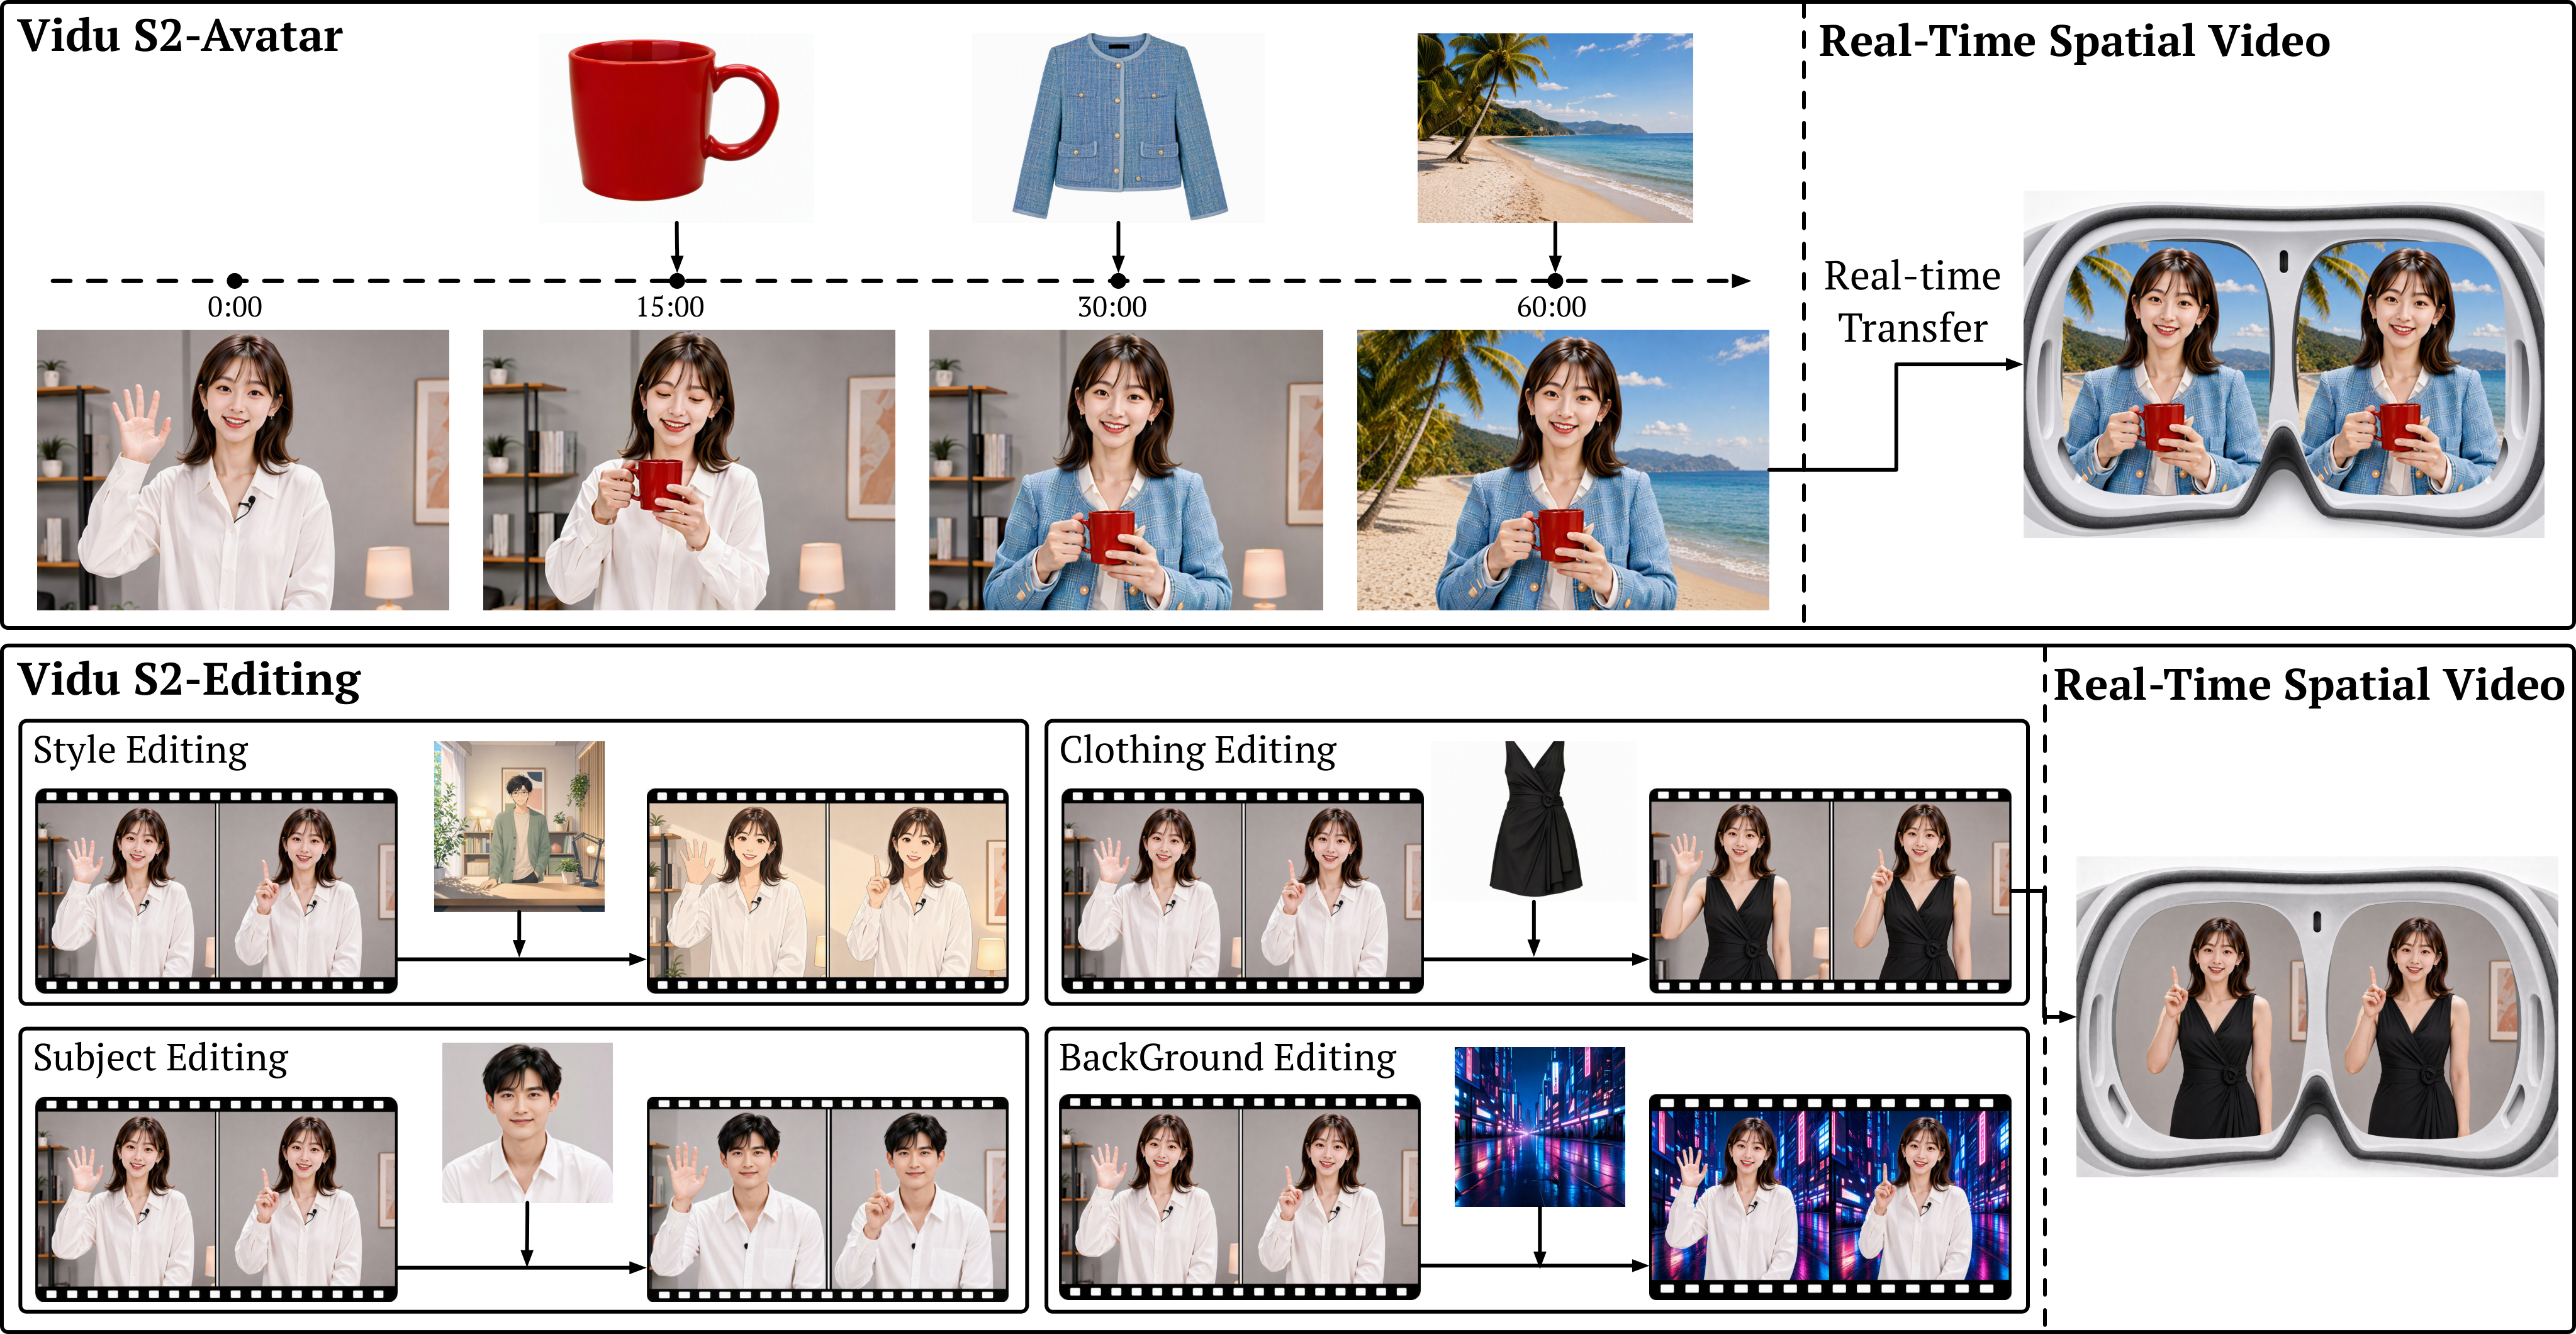
Vidu S2 extends real-time video generation beyond talking-head digital characters to high-resolution interactive avatars, live video editing, and immersive spatial video. It includes Vidu S2-Avatar for controllable character generation and Vidu S2-Editing for transforming live video streams.
Key breakthroughs:
720p real-time interactive avatars
Vidu S2-Avatar generates 720p video at 25–42 FPS, supports complex instructions such as dancing, and accepts new reference images at any moment during streaming.
Stable long-horizon generation with Self-Replay Forcing
Self-Replay Forcing replays re-noised, self-generated trajectories during training to reduce error accumulation across streaming segments.
Real-time editing of live video
Vidu S2-Editing transforms incoming video streams using reference images, supporting style transfer, virtual try-on, character replacement, and background replacement while preserving source motion.
Real-time spatial video for immersive displays
Produces synchronized stereo views for immersive displays and VR headsets.
Efficient inference on low-cost GPUs
TurboDiffusion and TurboServe combine efficient attention, low-bit GEMM, kernel optimizations, and multi-GPU pipelining for real-time inference.
Vidu S1
Vidu S1 is a real-time interactive video generation model for voice-controlled digital characters. Users can guide generated video content at any moment through spoken instructions, enabling live interaction.
Key breakthroughs:
Real-time speech control over video content
Users can directly instruct digital characters to perform actions.
Infinite-length real-time interactive generation
Vidu S1 generates 540p video at up to 42 FPS and can run on consumer GPUs.
Custom character images and voice tones
Vidu S1 supports real people, anime-style characters, pets, and other personalized avatars.
For agent-assisted API integration, use the vidu-s-api Skill. In Claude Code, Codex, OpenClaw, or any agent that supports Skills, say directly:
Install this skill: https://github.com/shengshu-ai/vidu-s-api/tree/main/skills/vidu-s-api
The agent will clone and install it into the proper Skills directory. Restart the agent if required, then ask it to load vidu-s-api for Vidu S2 API integration.
If you find Vidu S useful for your research, please cite:
@article{zhang2026vidus2,
  title={Vidu S2: Real-Time Interactive, Editable, and Spatial Video Generation},
  author={Zhang, Jintao and Jiang, Kai and Chen, Jintao and Wang, Xu and Liu, Deyuan and Li, Jungang and Chen, Dechuang and Lin, Ming and Zhou, Jingjiang and Jin, Haopeng and others},
  journal={arXiv preprint arXiv:2609.11638},
  year={2026}
}
@article{zhang2026vidus1,
  title={Vidu S1: A Real-Time Interactive Video Generation Model},
  author={Zhang, Jintao and Jiang, Kai and Chen, Jintao and Wang, Xu and Luo, Yang and Wang, Yuji and Chen, Dechuang and Li, Jungang and Ye, Chengyang and Chen, Marco and others},
  journal={arXiv preprint arXiv:2607.03118},
  year={2026}
}