DGM4: Detecting and Grounding Multi-Modal Media Manipulation and Beyond
[Rui Shao1,2](https://rshaojimmy.github.io/)
[Tianxing Wu2](https://tianxingwu.github.io/)
[Jianlong Wu1](https://jlwu1992.github.io/)
[Liqiang Nie1](https://liqiangnie.github.io/index.html)
[Ziwei Liu2](https://liuziwei7.github.io/)


1School of Computer Science and Technology, Harbin Institute of Technology (Shenzhen)


2S-Lab, Nanyang Technological University
[Project Page] | [Video] | [CVPR Paper] | [TPAMI Paper] | [Dataset]
If you find this work useful for your research, please kindly star our repo and cite our paper.
Updates
- [02/2024] Extension paper has been accepted by TPAMI.
- [01/2024] Dataset link has been updated with hugginface.
- [09/2023] Arxiv extension paper released.
- [04/2023] Trained checkpoint is updated.
- [04/2023] Arxiv paper released.
- [04/2023] Project page and video are released.
- [04/2023] Code and dataset are released.
Introduction
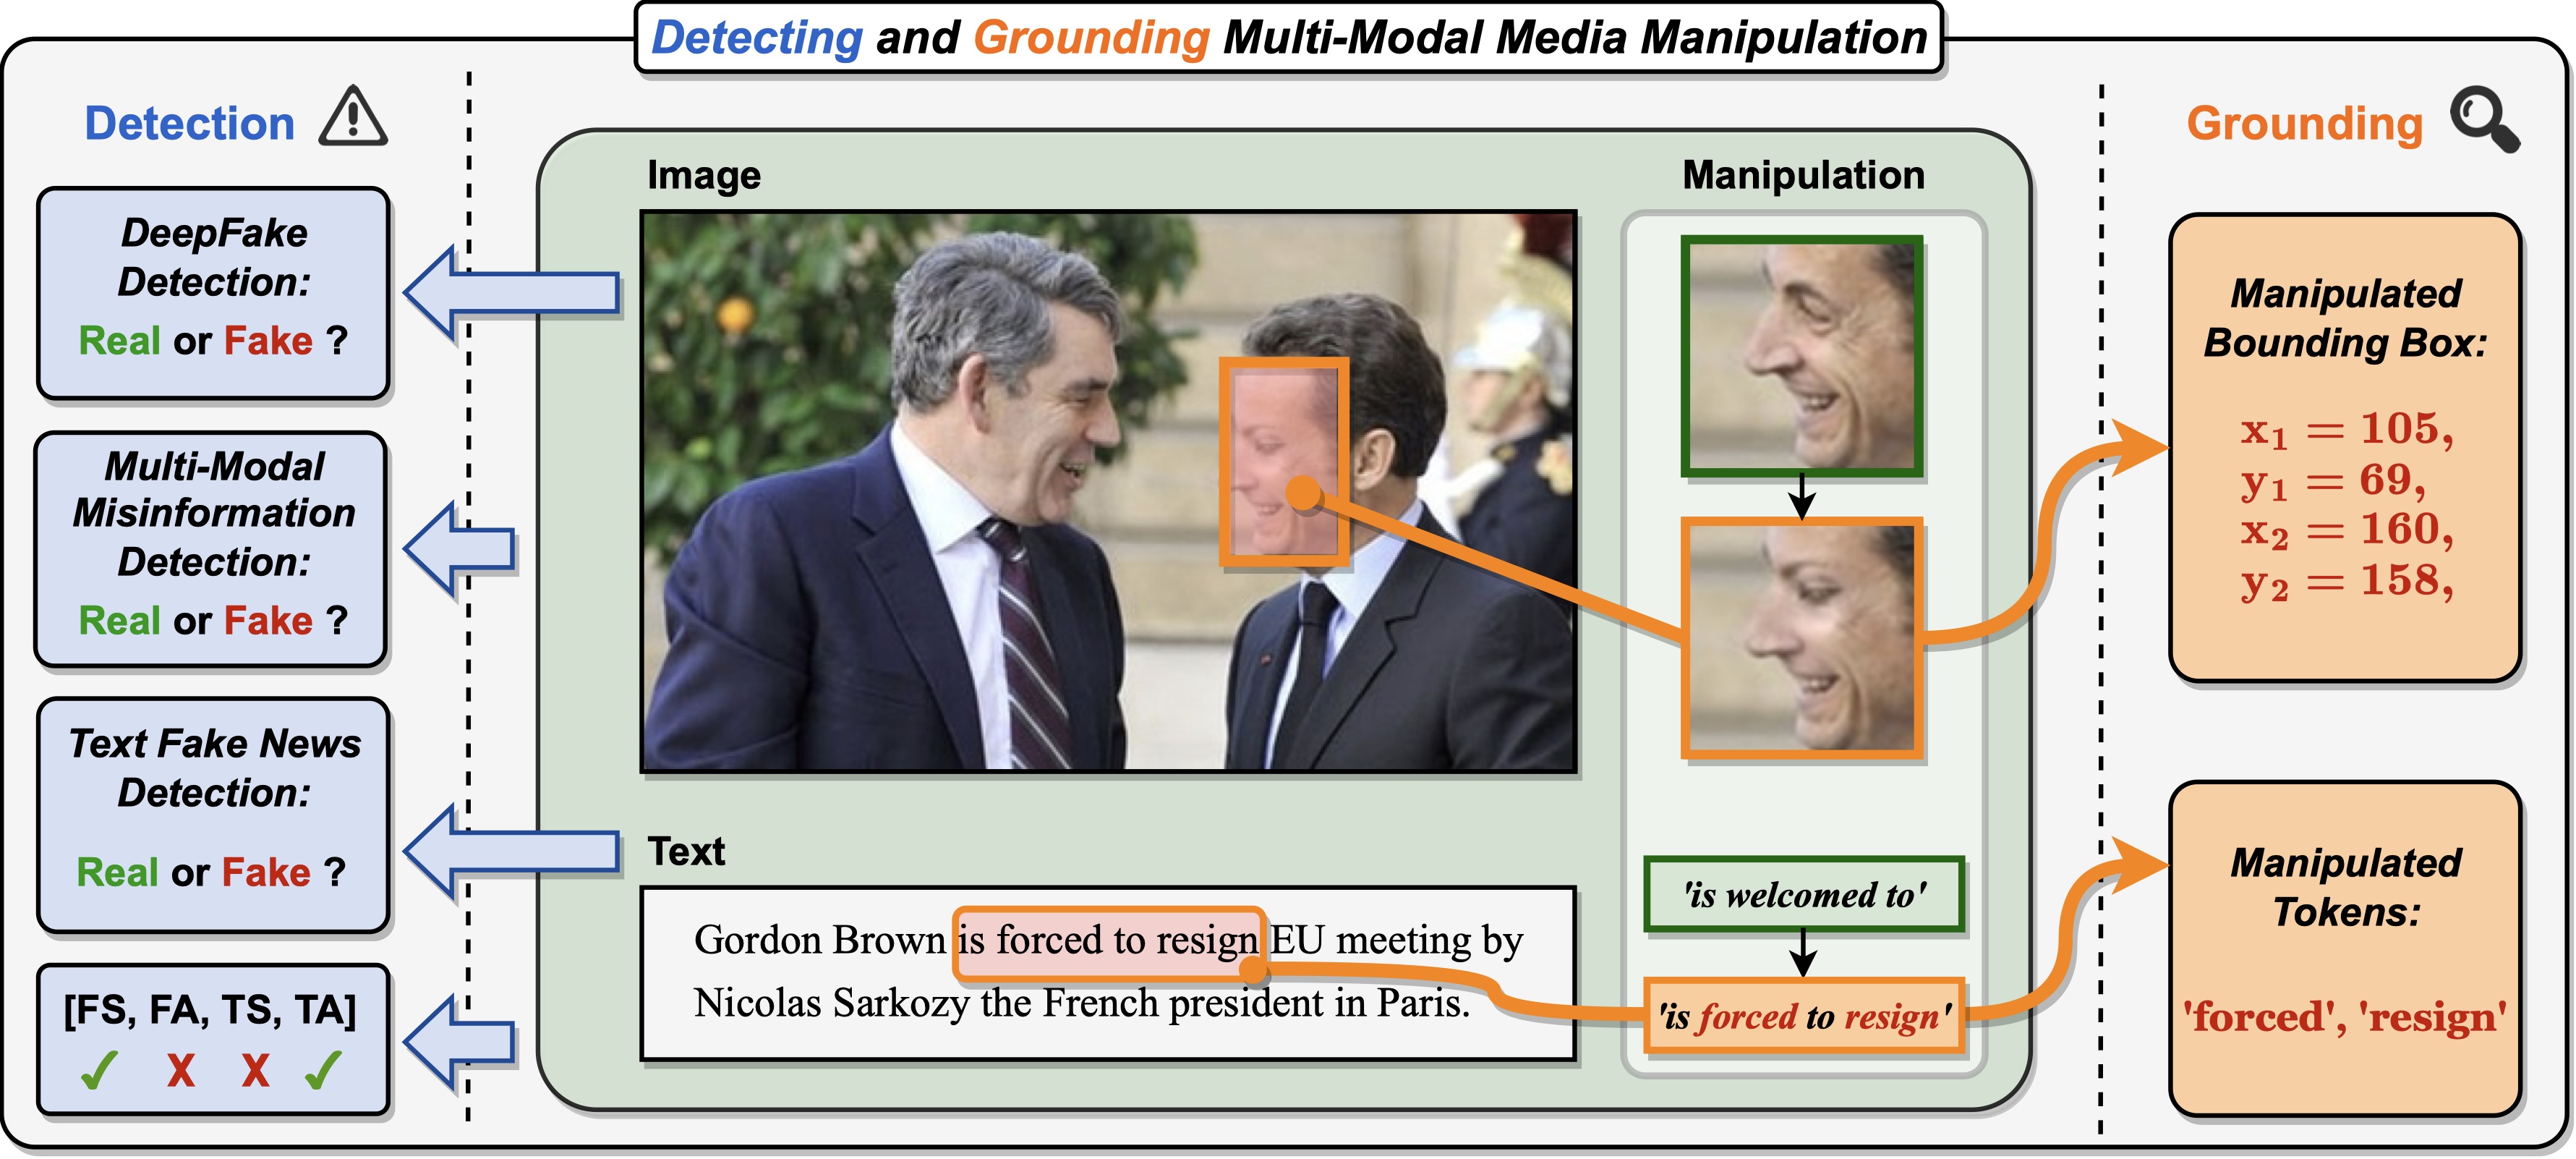
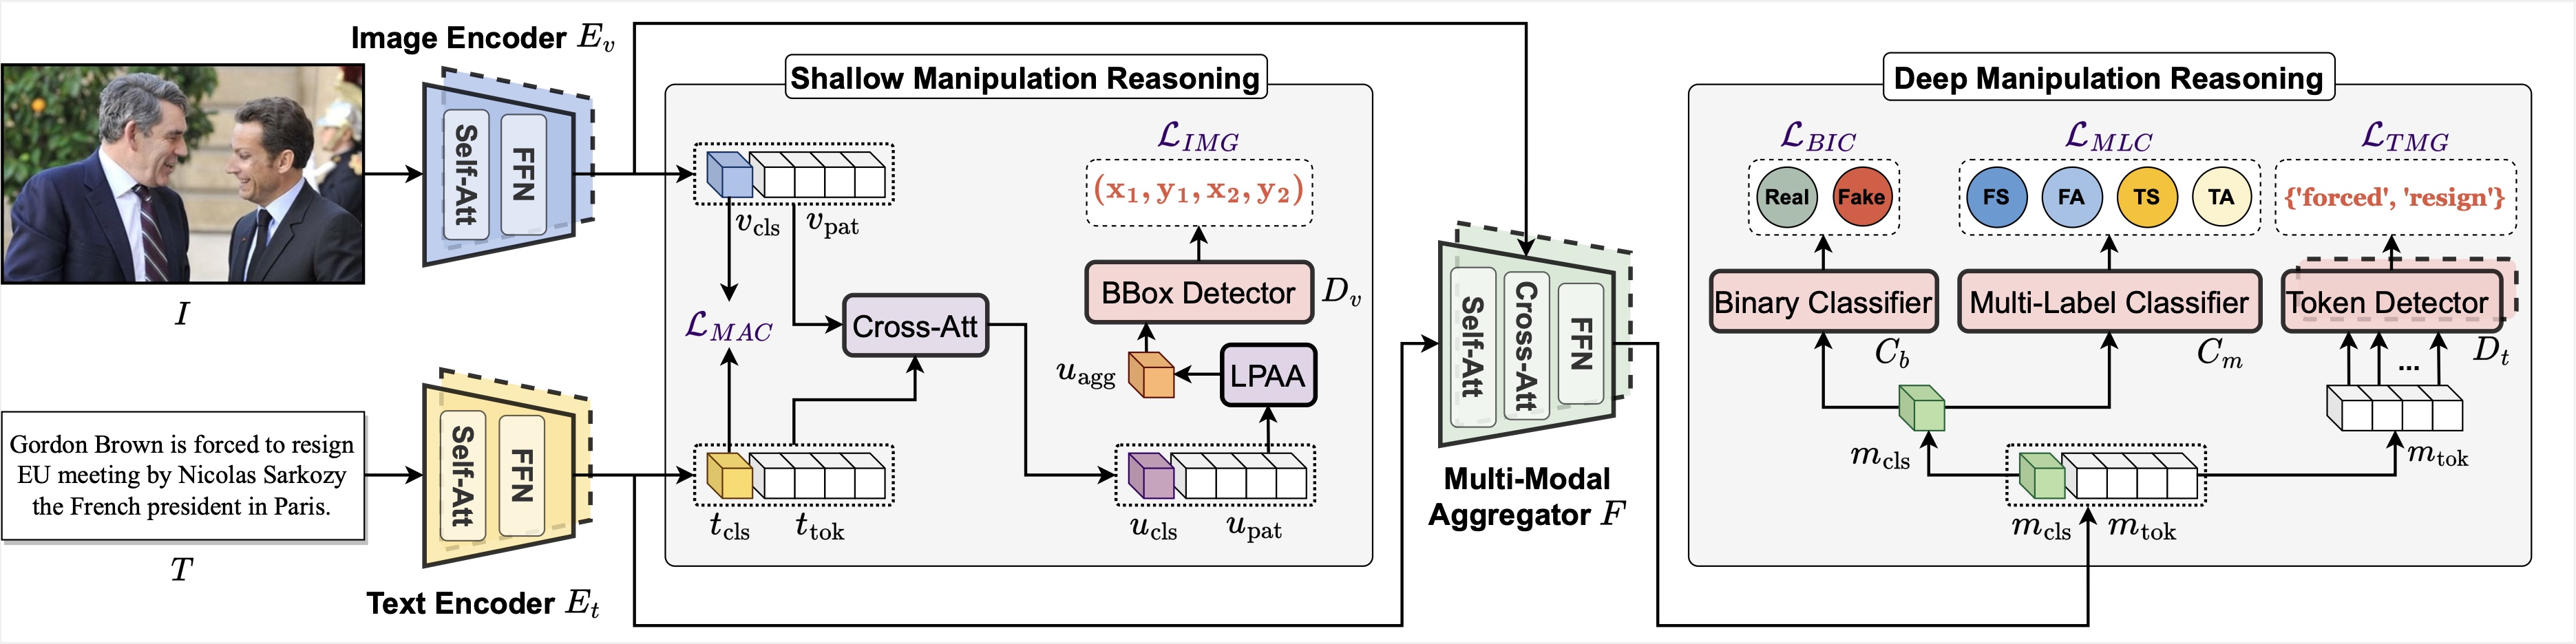
This is the official implementation of Detecting and Grounding Multi-Modal Media Manipulation. We highlight a new research problem for multi-modal fake media, namely Detecting and Grounding Multi-Modal Media Manipulation (DGM4). Different from existing single-modal forgery detection tasks, DGM4 aims to not only detect the authenticity of multi-modal media, but also ground the manipulated content (i.e., image bounding boxes and text tokens), which provide more comprehensive interpretation and deeper understanding about manipulation detection besides the binary classifcation. To faciliatate the study of DGM4, we construct the first large-scale DGM4 dataset, and propose a novel HierArchical Multi-modal Manipulation rEasoning tRansformer (HAMMER) to tackle the task.
The framework of the proposed HAMMER model:
Installation
Download
mkdir code
cd code
git clone https://github.com/rshaojimmy/MultiModal-DeepFake.git
cd MultiModal-DeepFake
Environment
We recommend using Anaconda to manage the python environment:
conda create -n DGM4 python=3.8
conda activate DGM4
conda install --yes -c pytorch pytorch=1.10.0 torchvision==0.11.1 cudatoolkit=11.3
pip install -r requirements.txt
conda install -c conda-forge ruamel_yaml
Dataset Preparation
A brief introduction
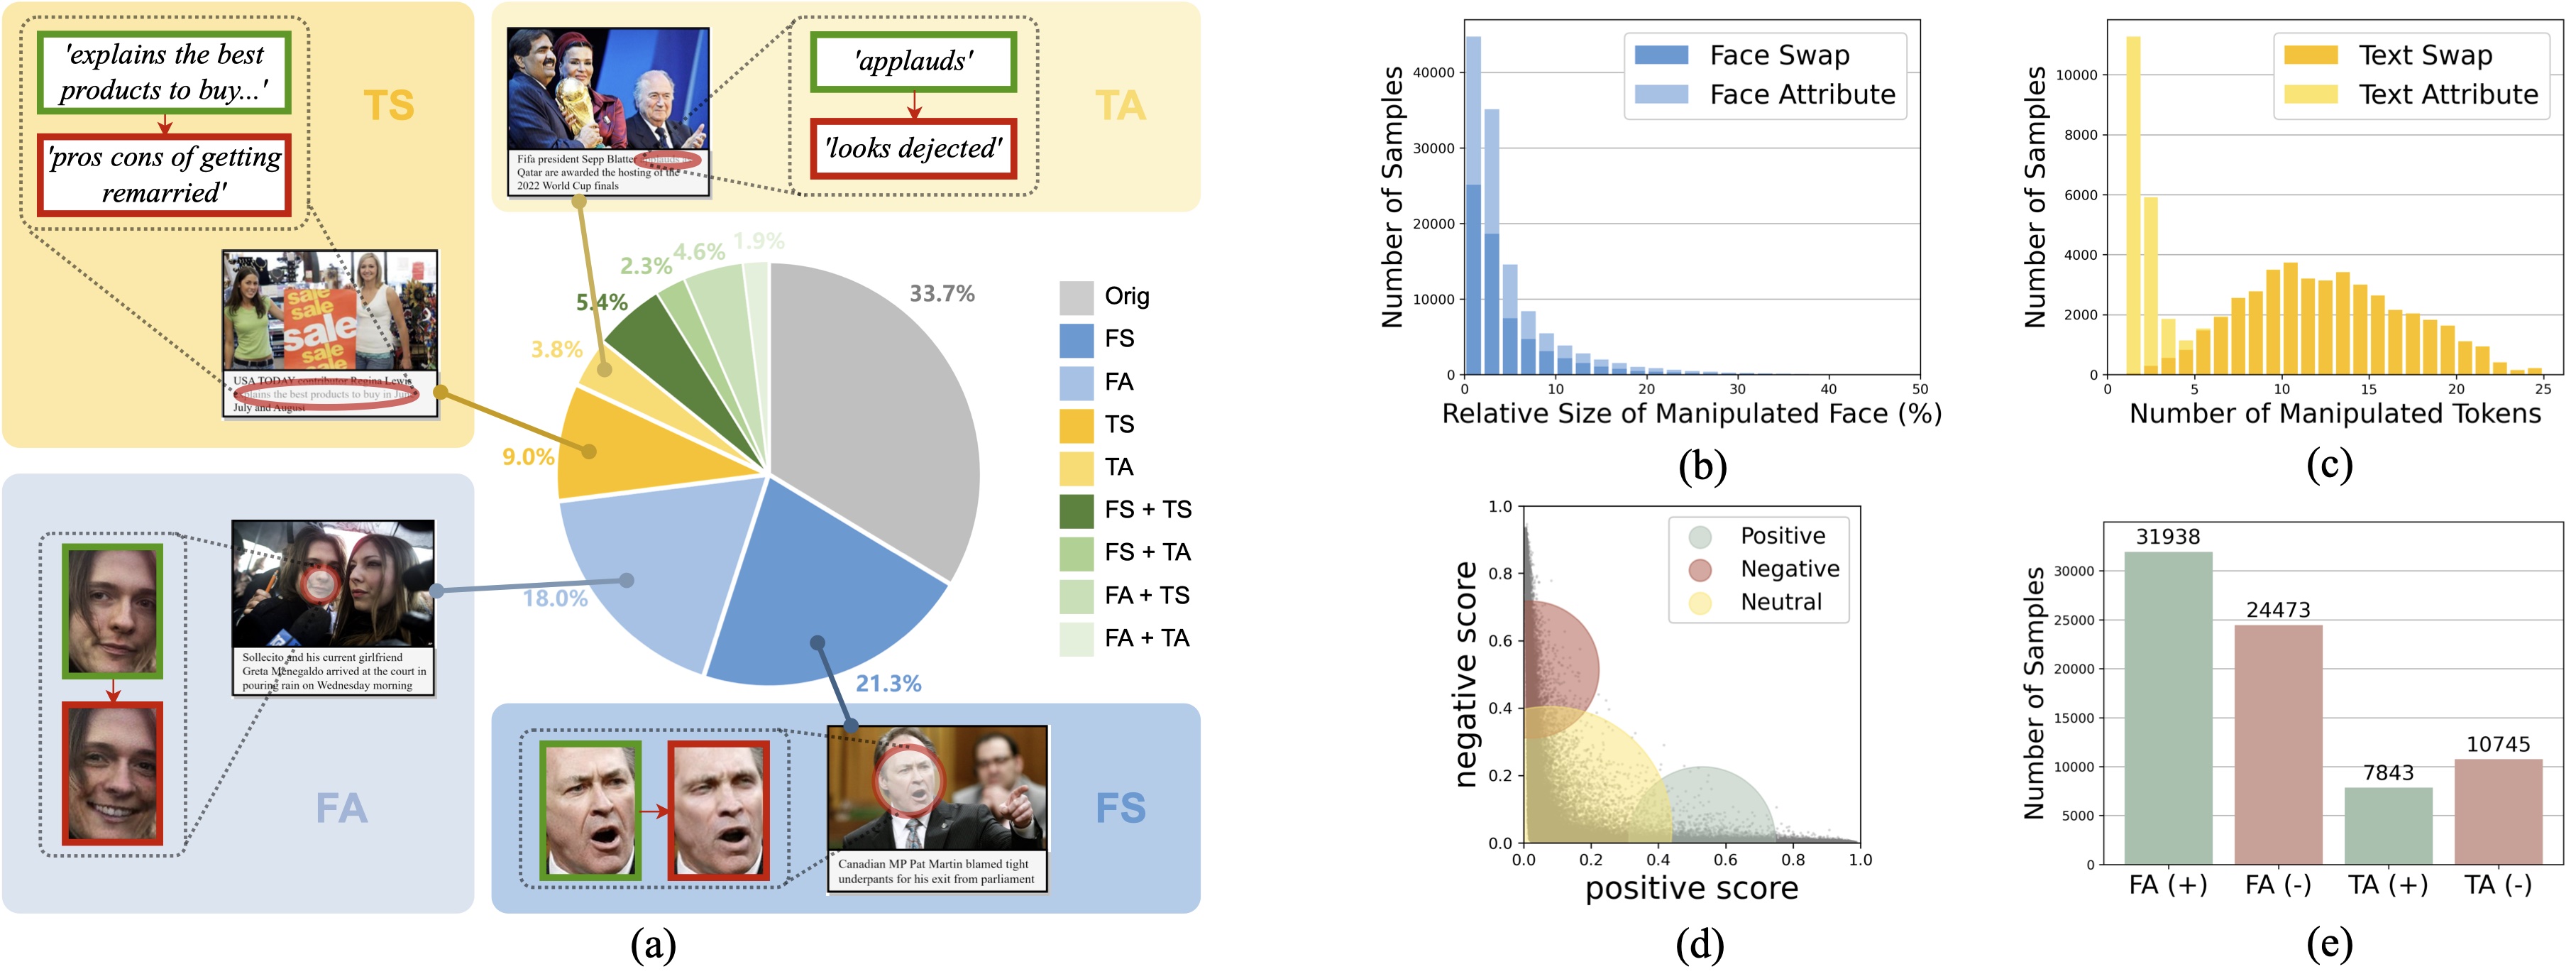
We present DGM4, a large-scale dataset for studying machine-generated multi-modal media manipulation. The dataset specifically focus on human-centric news, in consideration of its great public influence. We develop our dataset based on the VisualNews dataset, and form a total of 230k news samples, including 77,426 pristine image-text pairs and 152,574 manipulated pairs. The manipulated pairs contain:
- 66,722 Face Swap Manipulations (FS) (based on SimSwap and InfoSwap)
- 56,411 Face Attribute Manipulations (FA) (based on HFGI and StyleCLIP)
- 43,546 Text Swap Manipulations (TS) (using flair and Sentence-BERT)
- 18,588 Text Attribute Manipulations (TA) (based on B-GST)
Where 1/3 of the manipulated images and 1/2 of the manipulated text are combined together to form 32,693 mixed-manipulation pairs.
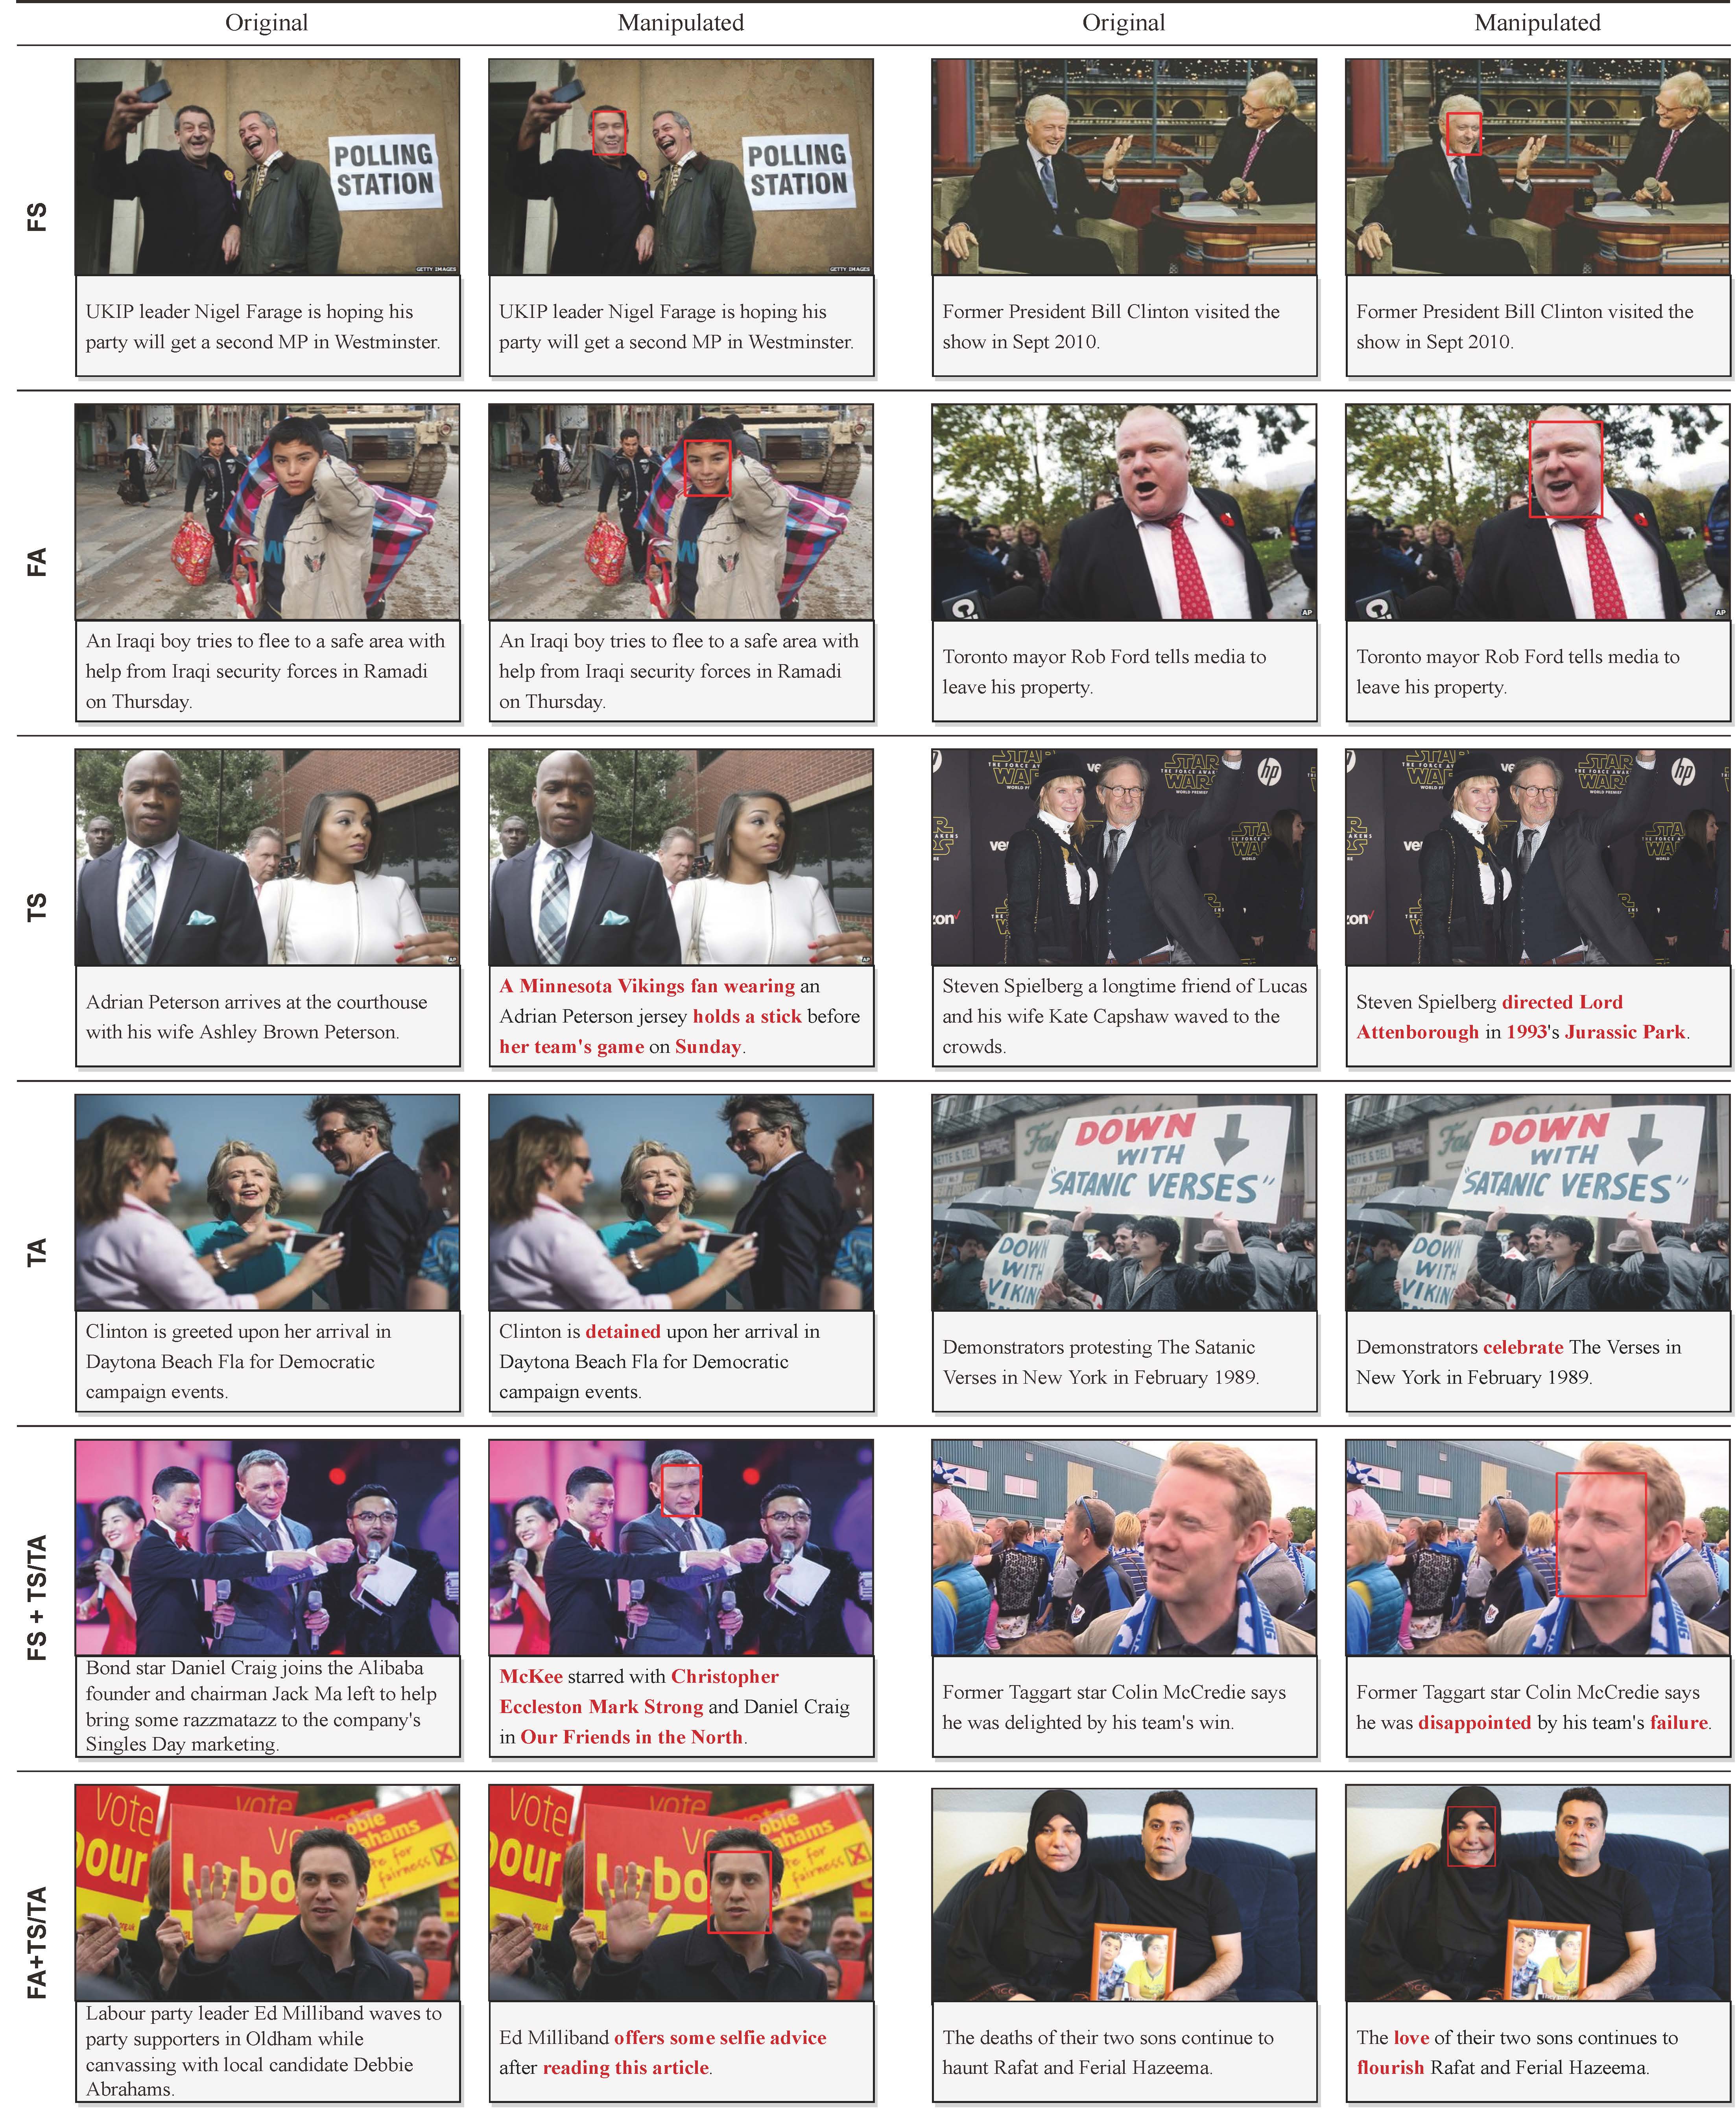
Here are the statistics and some sample image-text pairs:
Dataset Statistics:
Dataset Samples:
Annotations
Each iamge-text sample in the dataset is provided with rich annotations. For example, the annotation of a fake media sample with mixed-manipulation type (FA + TA) may look like this in the json file:
{
        "id": 768092,
        "image": "DGM4/manipulation/HFGI/768092-HFGI.jpg",
        "text": "British citizens David and Marco BulmerRizzi in Australia celebrate the day before an event in which David won",
        "fake_cls": "face_attribute&text_attribute",
        "fake_image_box": [
            155,
            61,
            267,
            207
        ],
        "fake_text_pos": [
            8,
            13,
            17
        ],
        "mtcnn_boxes": [
            [
                155,
                61,
                267,
                207
            ],
            [
                52,
                96,
                161,
                223
            ]
        ]
    }
Where id is the original news-id in the VisualNews Repository, image is the relative path of the manipulated image, text is the manipulated text caption, fake_cls indicates the manipulation type, fake_image_box is the manipulated bbox, fake_text_pos is the index of the manipulated tokens in the text string (in this case, corresponding to "celebrate", "event" and "won"), and mtcnn_boxes are the bboxes returned by MTCNN face detector. Note that the mtcnn_boxes is not used in both training and inference, we just kept this annotation for possible future usage.
Prepare data
Download the DGM4 dataset through this link: DGM4
Then download the pre-trained model through this link: ALBEF_4M.pth (refer to ALBEF)
Put the dataset into a ./datasets folder at the same root of ./code, and put the ALBEF_4M.pth checkpoint into ./code/MultiModel-Deepfake/. After unzip all sub files, the structure of the code and the dataset should be as follows:
./
├── code
│   └── MultiModal-Deepfake (this github repo)
│       ├── configs
│       │   └──...
│       ├── dataset
│       │   └──...
│       ├── models
│       │   └──...
│       ...
│       └── ALBEF_4M.pth
└── datasets
    └── DGM4
        ├── manipulation
        │   ├── infoswap
        │   |   ├── ...
        |   |   └── xxxxxx.jpg
        │   ├── simswap
        │   |   ├── ...
        |   |   └── xxxxxx.jpg
        │   ├── StyleCLIP
        │   |   ├── ...
        |   |   └── xxxxxx.jpg
        │   └── HFGI
        │       ├── ...
        |       └── xxxxxx.jpg
        ├── origin
        │   ├── gardian
        │   |   ├── ...
        |   |   ...
        |   |   └── xxxx
        │   |       ├── ...
        │   |       ...
        │   |       └── xxxxxx.jpg
        │   ├── usa_today
        │   |   ├── ...
        |   |   ...
        |   |   └── xxxx
        │   |       ├── ...
        │   |       ...
        │   |       └── xxxxxx.jpg
        │   ├── washington_post
        │   |   ├── ...
        |   |   ...
        |   |   └── xxxx
        │   |       ├── ...
        │   |       ...
        │   |       └── xxxxxx.jpg
        │   └── bbc
        │       ├── ...
        |       ...
        |       └── xxxx
        │           ├── ...
        │           ...
        │           └── xxxxxx.jpg
        └── metadata
            ├── train.json
            ├── test.json
            └── val.json
Training
Modify train.sh and run:
sh train.sh
You can change the network and optimization configurations by modifying the configuration file ./configs/train.yaml.
Testing
Modify test.sh and run:
sh test.sh
Benchmark Results
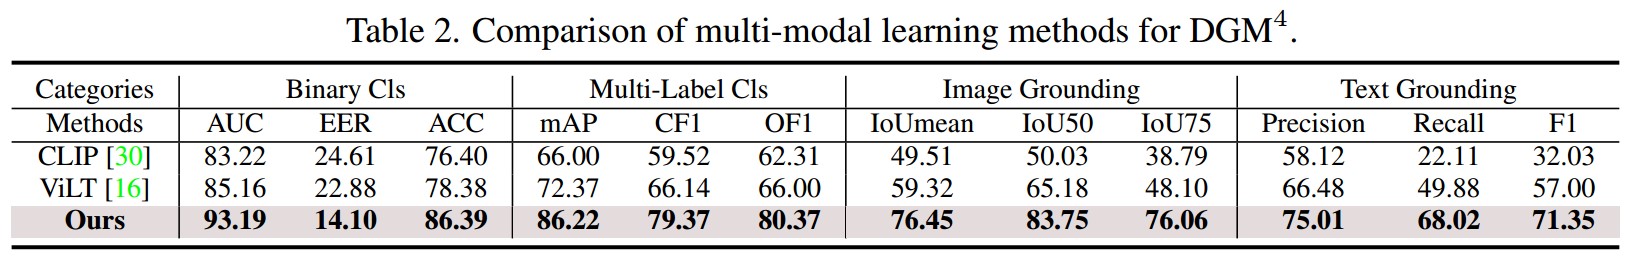
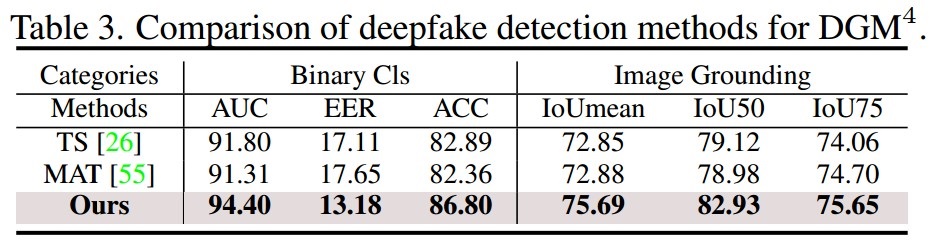
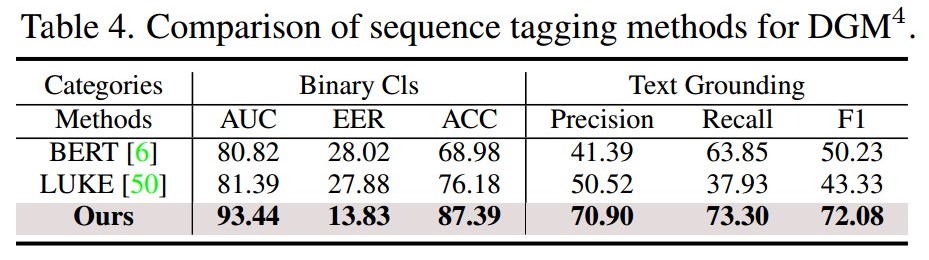
Here we list the performance comparison of SOTA multi-modal and single-modal methods and our method. Please refer to our paper for more details.
Model checkpoint
Checkpoint of our trained model (Ours) in Table 2: best-model-checkpoint
Visualization Results
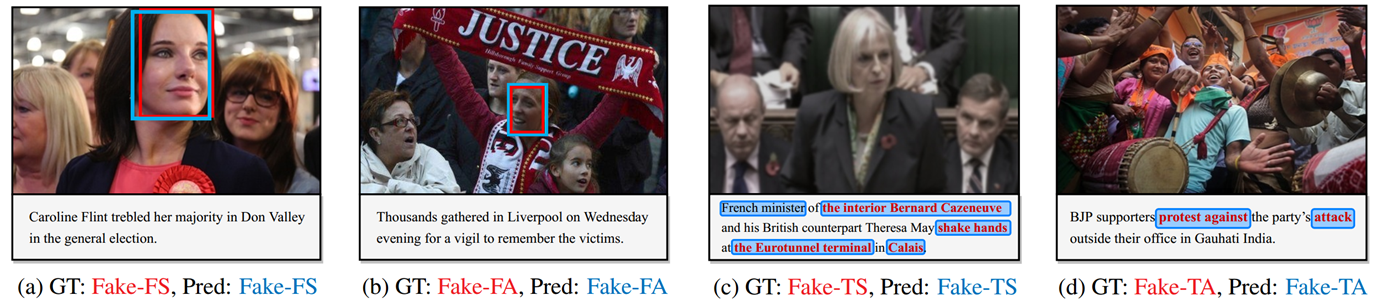
Visualization of detection and grounding results.
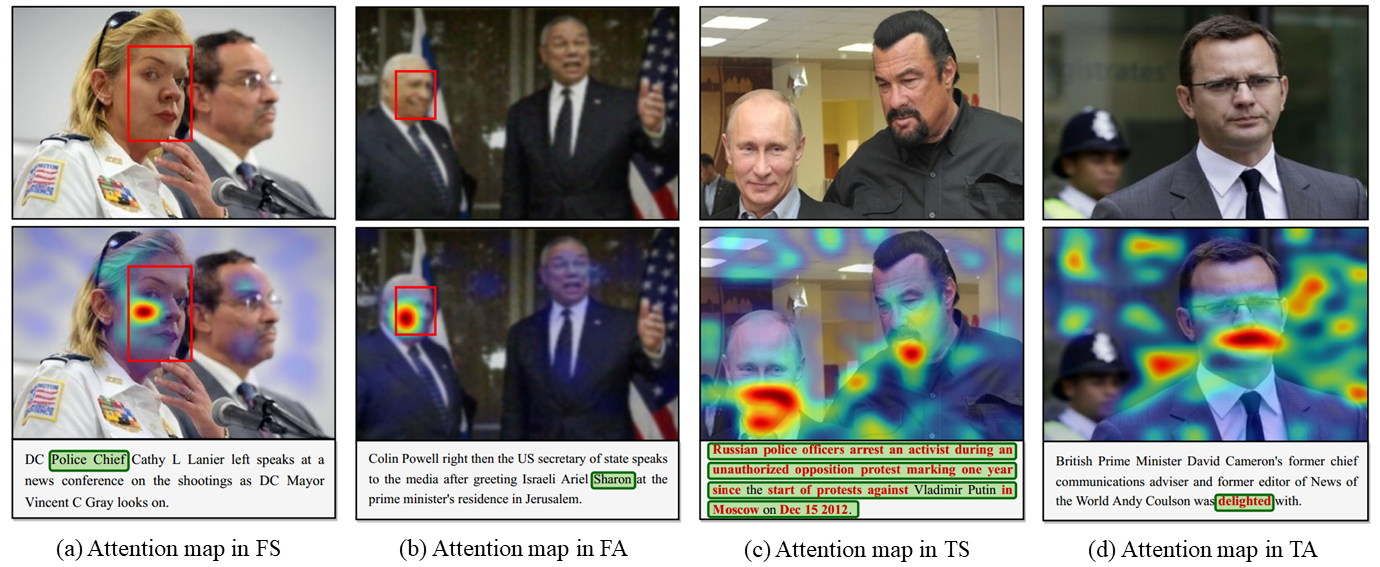
Visualization of attention map.
Citation
If you find this work useful for your research, please kindly cite our paper:
@inproceedings{shao2023dgm4,
    title={Detecting and Grounding Multi-Modal Media Manipulation},
    author={Shao, Rui and Wu, Tianxing and Liu, Ziwei},
    booktitle={IEEE Conference on Computer Vision and Pattern Recognition (CVPR)},
    year={2023}
}

@article{shao2024dgm4++,
  title={Detecting and Grounding Multi-Modal Media Manipulation and Beyond},
  author={Shao, Rui and Wu, Tianxing and Wu, Jianlong and Nie, Liqiang and Liu, Ziwei},
  journal={IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)},
  year={2024},
}
Acknowledgements
The codebase is maintained by Rui Shao and Tianxing Wu.
This project is built on the open source repository ALBEF. Thanks the team for their impressive work!