← Open Source
msgi

nlp-journey

Documents, papers and codes related to Natural Language Processing, including Topic Model, Word Embedding, Named Entity Recognition, Text Classificatin, Text Generation, Text Similarity, Machine Translation),etc.

ListsTool collectionsPaper collectionsPython
Open on GitHub
Momentum
+0stars in 24 hours0.0%
1.63k
Stars
375
Forks
+2
This week
1
Contributors
Created 2019-04-22 · Updated 2026-10-11 · #9824 today
Top developers
msgi

msgi/nlp-journey is ranked 9,824 with 1,629 stars.

Same-category comparison

msgi/nlp-journey is ranked 9,824 among these 8 peers; qingsongedu/awesome-AI-for-time-series-papers is ranked 9,820.

Same-category comparison
NameRankMetrics
travistangvh/ChatGPT-Data-Science-Prompts9,815
Stars:
1,635
Forks:
281
Description:
A repository of 60 useful data science prompts for ChatGPT.
AgaMiko/data-augmentation-review9,816
Stars:
1,634
Forks:
206
Description:
List of useful data augmentation resources. You will find here some not common techniques, libraries, links to GitHub repos, papers, and others.
kuanhungchen/awesome-tiny-object-detection9,819
Stars:
1,633
Forks:
208
Description:
🕶 A curated list of Tiny Object Detection papers and related resources.
qingsongedu/awesome-AI-for-time-series-papers9,820
Stars:
1,633
Forks:
145
Description:
A professional list of Papers, Tutorials, and Surveys on AI for Time Series in top AI conferences and journals.
HKUSTDial/NL2SQL_Handbook9,857
Language:
Python
Stars:
1,612
Forks:
96
Description:
This is a continuously updated handbook for readers to easily track the latest Text-to-SQL techniques in the literature and provide practical guidance for researchers and practitioners.
albarqouni/Deep-Learning-for-Medical-Applications9,858
Language:
TeX
Stars:
1,612
Forks:
502
Description:
Deep Learning Papers on Medical Image Analysis.
business-science/awesome-generative-ai-data-scientist9,888
Stars:
1,601
Forks:
264
Description:
A curated list of 100+ resources for building and deploying generative AI specifically focusing on helping you become a Generative AI Data Scientist with LLMs.
currentslab/awesome-vector-search9,906
Stars:
1,593
Forks:
136
Description:
Collections of vector search related libraries, service and research papers.
Key parameters and specifications
ParameterValue
LanguagePython
CategoryLists
SubcategoryTool collections, Paper collections
Stars1,629
Forks375
Contributors1
Created date2019-04-22
Updated date2026-10-11
Stars in 1 day0
Stars in 7 days2
Rank9,824
Previous rank9,860
Rank change36
7-day stars rank7,980
Previous 7-day stars rank8,021
7-day stars rank change41
Total stars rank7,555
Previous total stars rank7,549
Total stars rank change-6
CountryChina
README summary

BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. GPT-2: Language Models are Unsupervised Multitask Learners. Transformer-XL: Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context. XLNet: Generalized Autoregressive Pretraining for Language Understanding. RoBERTa: Robustly Optimized BERT Pretraining Approach. DistilBERT: a distilled version of BERT: smaller, faster, cheaper and lighter. ALBERT: A Lite BERT for Self-supervised Learning of Language Representations. T5: Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer. ELECTRA

: pre-training text encoders as discriminators rather than generators. GPT3: Language Models are Few-Shot Learners. Sequence to Sequence Learning with Neural Networks. Learning Phrase Representations using RNN Encoder-Decoder for Statistical Machine Translation. Residual Network(Deep Residual Learning for Image Recognition). Dropout(Improving neural networks by preventing co-adaptation of feature detectors). Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift. An overview of gradient descent optimization algorithms. Analysis Methods in Neural Language Processing: A Survey. Exploring

the Limits of Transfer Learning with a Unified Text-to-Text Transformer. A Review on Generative Adversarial Networks: Algorithms, Theory, and Applications. A Gentle Introduction to Deep Learning for Graphs. A Survey on Deep Learning for Named Entity Recognition. More Data, More Relations, More Context and More Openness: A Review and Outlook for Relation Extraction. Deep Learning Based Text Classification: A Comprehensive Review. Pre-trained Models for Natural Language Processing: A Survey. A Survey on Knowledge Graphs: Representation, Acquisition and

Applications. Pre-trained Models for Natural Language Processing: A Survey. Language Models are Unsupervised Multitask Learners. An Empirical Study of Smoothing Techniques for Language Modeling. Efficient Estimation of Word Representations in Vector Space. Distributed Representations of Sentences and Documents. Enriching Word Vectors with Subword Information(FastText). GloVe: Global Vectors for Word Representation. ELMo (Deep contextualized word representations). Pre-Training with Whole Word Masking for Chinese BERT. Bag of Tricks for Efficient Text Classification (FastText). Convolutional Neural Networks for Sentence Classification

. Attention-Based Bidirectional Long Short-Term Memory Networks for Relation Classification. A Deep Ensemble Model with Slot Alignment for Sequence-to-Sequence Natural Language Generation. SeqGAN: Sequence Generative Adversarial Nets with Policy Gradient. Learning to Rank Short Text Pairs with Convolutional Deep Neural Networks. Learning Text Similarity with Siamese Recurrent Networks. A Deep Architecture for Matching Short Texts. A Question-Focused Multi-Factor Attention Network for Question Answering. The Design and Implementation of XiaoIce, an Empathetic Social Chatbot. A Knowledge

-Grounded Neural Conversation Model. Sequential Matching Network A New Architecture for Multi-turn Response Selection in Retrieval-Based Chatbots. 6. Modeling Multi-turn Conversation with Deep Utterance Aggregation. 7. Multi-Turn Response Selection for Chatbots with Deep Attention Matching Network. 8. Deep Reinforcement Learning For Modeling Chit-Chat Dialog With Discrete Attributes. Learning Phrase Representations using RNN Encoder–Decoder for Statistical Machine Translation. Neural Machine Translation by Jointly Learning to Align and Translate. Transformer (Attention Is All You Need). Get

To The Point: Summarization with Pointer-Generator Networks. Deep Recurrent Generative Decoder for Abstractive Text Summarization. Distant Supervision for Relation

Frequently asked questions

How many stars and forks are recorded?

msgi/nlp-journey has 1,629 stars and 375 forks.

What is the repository rank?

msgi/nlp-journey is ranked 9,824.

What language and category are recorded?

msgi/nlp-journey has 1,629 stars, uses Python and belongs to Lists.

Which repository is closest in rank?

msgi/nlp-journey is compared with qingsongedu/awesome-AI-for-time-series-papers, ranked 9,820 with 1,633 stars.

README

nlp journey

0. llm chat
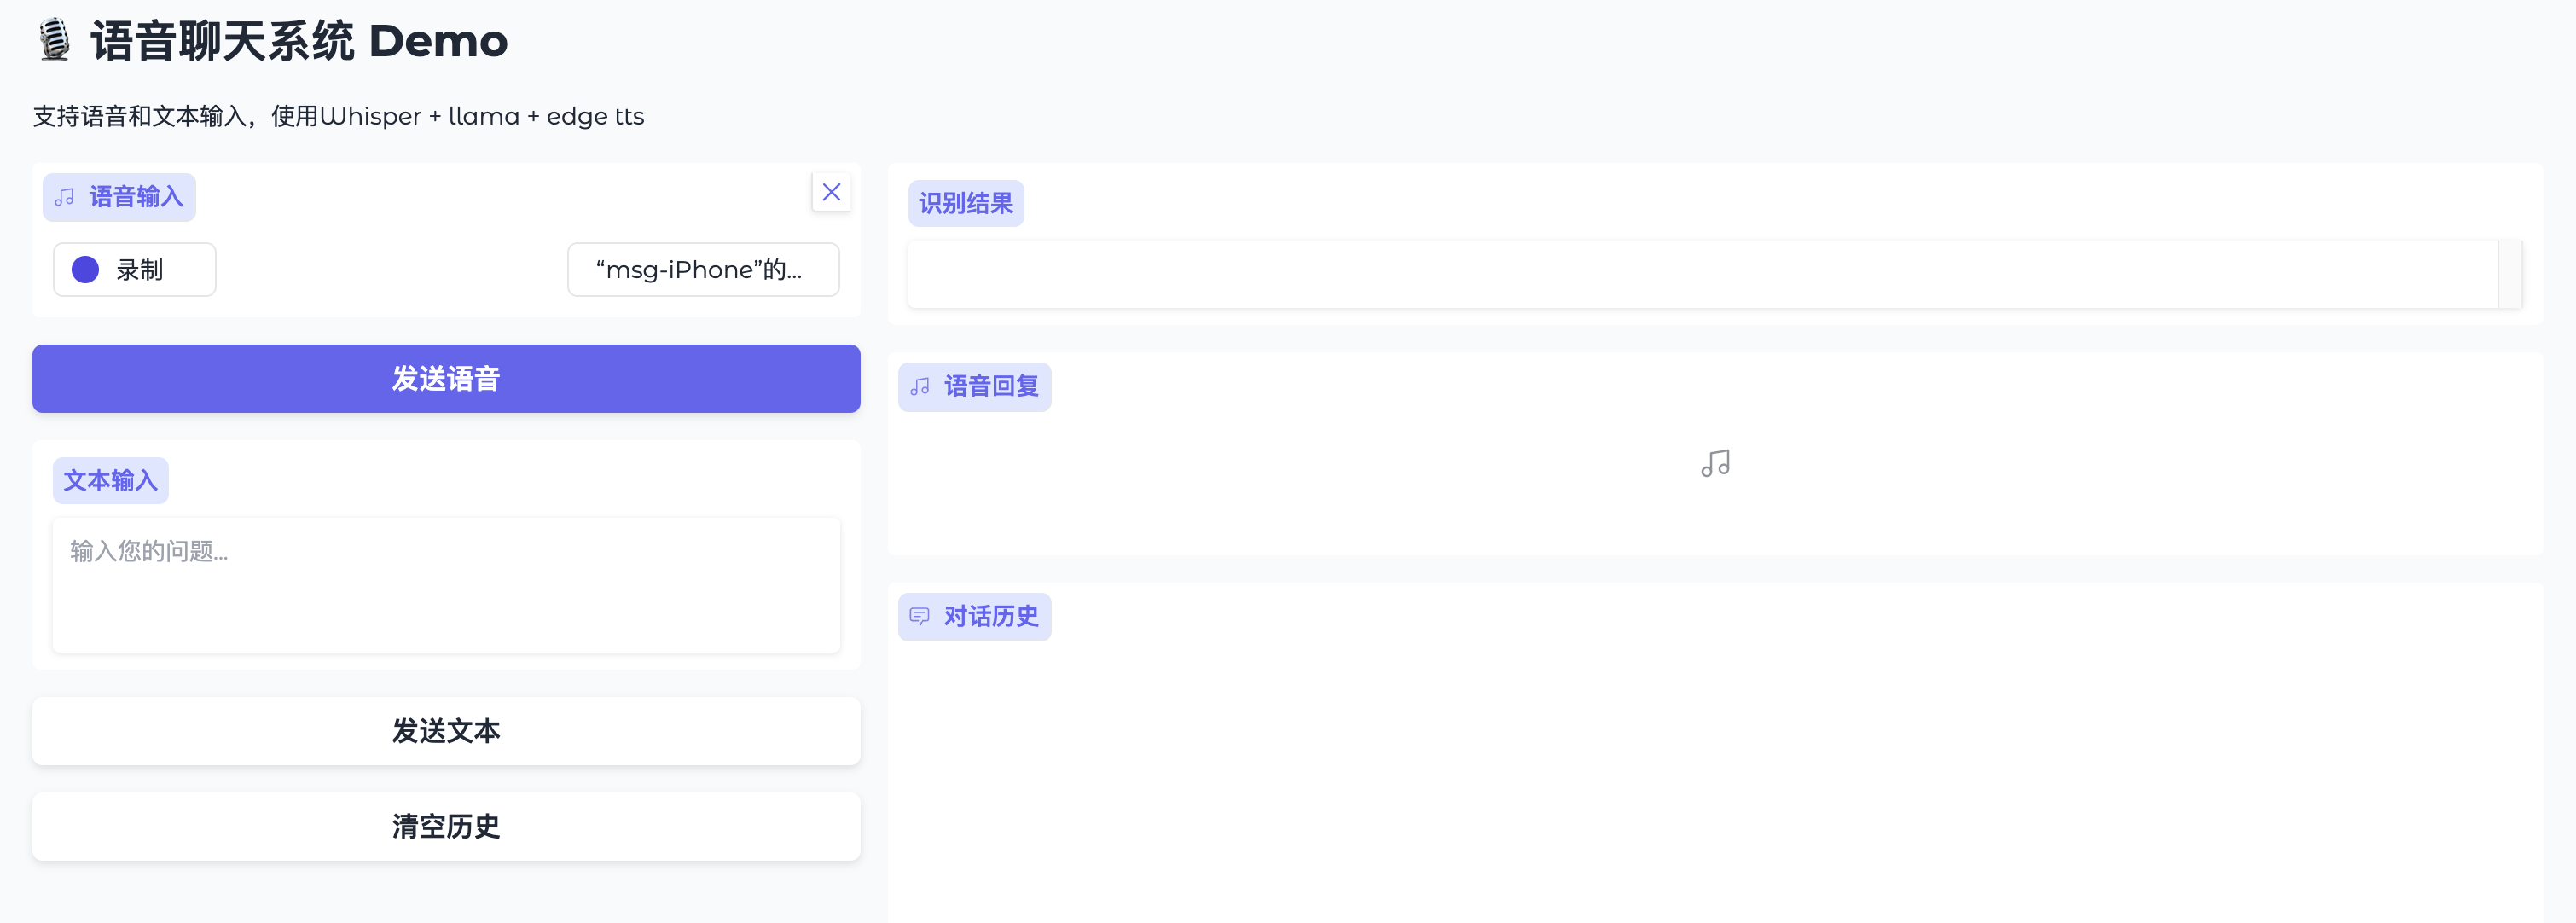
llm-chat

1. Books

  1. Handbook of Graphical Models. online
  2. Deep Learning. online
  3. Neural Networks and Deep Learning. online
  4. Speech and Language Processing. online

2. Papers

01) Transformer papers

  1. BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding. paper
  2. GPT-2: Language Models are Unsupervised Multitask Learners. paper
  3. Transformer-XL: Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context. paper
  4. XLNet: Generalized Autoregressive Pretraining for Language Understanding. paper
  5. RoBERTa: Robustly Optimized BERT Pretraining Approach. paper
  6. DistilBERT: a distilled version of BERT: smaller, faster, cheaper and lighter. paper
  7. ALBERT: A Lite BERT for Self-supervised Learning of Language Representations. paper
  8. T5: Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer. paper
  9. ELECTRA: pre-training text encoders as discriminators rather than generators. paper
  10. GPT3: Language Models are Few-Shot Learners. paper

02) Models

  1. LSTM(Long Short-term Memory). paper
  2. Sequence to Sequence Learning with Neural Networks. paper
  3. Learning Phrase Representations using RNN Encoder-Decoder for Statistical Machine Translation. paper
  4. Residual Network(Deep Residual Learning for Image Recognition). paper
  5. Dropout(Improving neural networks by preventing co-adaptation of feature detectors). paper
  6. Batch Normalization: Accelerating Deep Network Training by Reducing Internal Covariate Shift. paper

03) Summaries

  1. An overview of gradient descent optimization algorithms. paper
  2. Analysis Methods in Neural Language Processing: A Survey. paper
  3. Exploring the Limits of Transfer Learning with a Unified Text-to-Text Transformer. paper
  4. A Review on Generative Adversarial Networks: Algorithms, Theory, and Applications. paper
  5. A Gentle Introduction to Deep Learning for Graphs. paper
  6. A Survey on Deep Learning for Named Entity Recognition. paper
  7. More Data, More Relations, More Context and More Openness: A Review and Outlook for Relation Extraction. paper
  8. Deep Learning Based Text Classification: A Comprehensive Review. paper
  9. Pre-trained Models for Natural Language Processing: A Survey. paper
  10. A Survey on Contextual Embeddings. paper
  11. A Survey on Knowledge Graphs: Representation, Acquisition and Applications. paper
  12. Knowledge Graphs. paper
  13. Pre-trained Models for Natural Language Processing: A Survey. paper

04) Pre-training

  1. A Neural Probabilistic Language Model. paper
  2. word2vec Parameter Learning Explained. paper
  3. Language Models are Unsupervised Multitask Learners. paper
  4. An Empirical Study of Smoothing Techniques for Language Modeling. paper
  5. Efficient Estimation of Word Representations in Vector Space. paper
  6. Distributed Representations of Sentences and Documents. paper
  7. Enriching Word Vectors with Subword Information(FastText). paper
  8. GloVe: Global Vectors for Word Representation. online
  9. ELMo (Deep contextualized word representations). paper
  10. Pre-Training with Whole Word Masking for Chinese BERT. paper

05) Classification

  1. Bag of Tricks for Efficient Text Classification (FastText). paper
  2. Convolutional Neural Networks for Sentence Classification. paper
  3. Attention-Based Bidirectional Long Short-Term Memory Networks for Relation Classification. paper

06) Text generation

  1. A Deep Ensemble Model with Slot Alignment for Sequence-to-Sequence Natural Language Generation. paper
  2. SeqGAN: Sequence Generative Adversarial Nets with Policy Gradient. paper

07) Text Similarity

  1. Learning to Rank Short Text Pairs with Convolutional Deep Neural Networks. paper
  2. Learning Text Similarity with Siamese Recurrent Networks. paper
  3. A Deep Architecture for Matching Short Texts. paper

08) QA

  1. A Question-Focused Multi-Factor Attention Network for Question Answering. paper
  2. The Design and Implementation of XiaoIce, an Empathetic Social Chatbot. paper
  3. A Knowledge-Grounded Neural Conversation Model. paper
  4. Neural Generative Question Answering. paper
  5. Sequential Matching Network A New Architecture for Multi-turn Response Selection in Retrieval-Based Chatbots.paper
  6. Modeling Multi-turn Conversation with Deep Utterance Aggregation.paper
  7. Multi-Turn Response Selection for Chatbots with Deep Attention Matching Network.paper
  8. Deep Reinforcement Learning For Modeling Chit-Chat Dialog With Discrete Attributes. paper

09) NMT

  1. Learning Phrase Representations using RNN Encoder–Decoder for Statistical Machine Translation. paper
  2. Neural Machine Translation by Jointly Learning to Align and Translate. paper
  3. Transformer (Attention Is All You Need). paper

10) Summary

  1. Get To The Point: Summarization with Pointer-Generator Networks. paper
  2. Deep Recurrent Generative Decoder for Abstractive Text Summarization. paper

11) Relation extraction

  1. Distant Supervision for Relation Extraction via Piecewise Convolutional Neural Networks. paper
  2. Neural Relation Extraction with Multi-lingual Attention. paper
  3. FewRel: A Large-Scale Supervised Few-Shot Relation Classification Dataset with State-of-the-Art Evaluation. paper
  4. End-to-End Relation Extraction using LSTMs on Sequences and Tree Structures. paper

12) Large Language Models

  1. Training language models to follow instructions with human feedback. paper
  2. LLaMA: Open and Efficient Foundation Language Models. paper

3. Articles

  • TRANSFORMERS FROM SCRATCH. url
  • The Illustrated Transformer.url
  • Attention-based-model. url
  • Modern Deep Learning Techniques Applied to Natural Language Processing. url
  • Illustrated Guide to LSTM’s and GRU’s: A step by step explanation .url
  • Applying word2vec to Recommenders and Advertising. url

4. Github

Nearby in the ranking
Similar items