Muse - Pytorch
Implementation of Muse: Text-to-Image Generation via Masked Generative Transformers, in Pytorch
Please join if you are interested in helping out with the replication with the LAION community
Install
$ pip install muse-maskgit-pytorch
Usage
First train your VAE - VQGanVAE
import torch
from muse_maskgit_pytorch import VQGanVAE, VQGanVAETrainer

vae = VQGanVAE(
    dim = 256,
    codebook_size = 65536
)

# train on folder of images, as many images as possible

trainer = VQGanVAETrainer(
    vae = vae,
    image_size = 128,             # you may want to start with small images, and then curriculum learn to larger ones, but because the vae is all convolution, it should generalize to 512 (as in paper) without training on it
    folder = '/path/to/images',
    batch_size = 4,
    grad_accum_every = 8,
    num_train_steps = 50000
).cuda()

trainer.train()
Then pass the trained VQGanVAE and a Transformer to MaskGit
import torch
from muse_maskgit_pytorch import VQGanVAE, MaskGit, MaskGitTransformer

# first instantiate your vae

vae = VQGanVAE(
    dim = 256,
    codebook_size = 65536
).cuda()

vae.load('/path/to/vae.pt') # you will want to load the exponentially moving averaged VAE

# then you plug the vae and transformer into your MaskGit as so

# (1) create your transformer / attention network

transformer = MaskGitTransformer(
    num_tokens = 65536,       # must be same as codebook size above
    seq_len = 256,            # must be equivalent to fmap_size ** 2 in vae
    dim = 512,                # model dimension
    depth = 8,                # depth
    dim_head = 64,            # attention head dimension
    heads = 8,                # attention heads,
    ff_mult = 4,              # feedforward expansion factor
    t5_name = 't5-small',     # name of your T5
)

# (2) pass your trained VAE and the base transformer to MaskGit

base_maskgit = MaskGit(
    vae = vae,                 # vqgan vae
    transformer = transformer, # transformer
    image_size = 256,          # image size
    cond_drop_prob = 0.25,     # conditional dropout, for classifier free guidance
).cuda()

# ready your training text and images

texts = [
    'a child screaming at finding a worm within a half-eaten apple',
    'lizard running across the desert on two feet',
    'waking up to a psychedelic landscape',
    'seashells sparkling in the shallow waters'
]

images = torch.randn(4, 3, 256, 256).cuda()

# feed it into your maskgit instance, with return_loss set to True

loss = base_maskgit(
    images,
    texts = texts
)

loss.backward()

# do this for a long time on much data
# then...

images = base_maskgit.generate(texts = [
    'a whale breaching from afar',
    'young girl blowing out candles on her birthday cake',
    'fireworks with blue and green sparkles'
], cond_scale = 3.) # conditioning scale for classifier free guidance

images.shape # (3, 3, 256, 256)
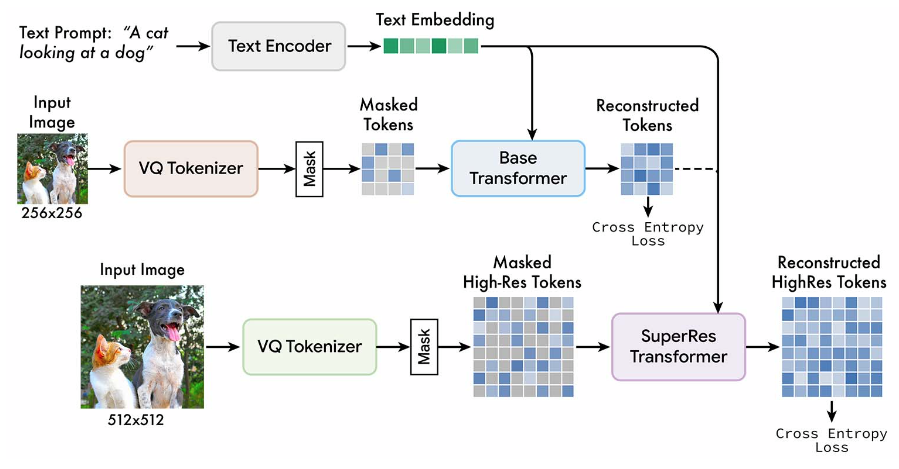
To train the super-resolution maskgit requires you to change 1 field on MaskGit instantiation (you will need to now pass in the cond_image_size, as the previous image size being conditioned on)
Optionally, you can pass in a different VAE as cond_vae for the conditioning low-resolution image. By default it will use the vae for both tokenizing the super and low resoluted images.
import torch
import torch.nn.functional as F
from muse_maskgit_pytorch import VQGanVAE, MaskGit, MaskGitTransformer

# first instantiate your ViT VQGan VAE
# a VQGan VAE made of transformers

vae = VQGanVAE(
    dim = 256,
    codebook_size = 65536
).cuda()

vae.load('./path/to/vae.pt') # you will want to load the exponentially moving averaged VAE

# then you plug the VqGan VAE into your MaskGit as so

# (1) create your transformer / attention network

transformer = MaskGitTransformer(
    num_tokens = 65536,       # must be same as codebook size above
    seq_len = 1024,           # must be equivalent to fmap_size ** 2 in vae
    dim = 512,                # model dimension
    depth = 2,                # depth
    dim_head = 64,            # attention head dimension
    heads = 8,                # attention heads,
    ff_mult = 4,              # feedforward expansion factor
    t5_name = 't5-small',     # name of your T5
)

# (2) pass your trained VAE and the base transformer to MaskGit

superres_maskgit = MaskGit(
    vae = vae,
    transformer = transformer,
    cond_drop_prob = 0.25,
    image_size = 512,                     # larger image size
    cond_image_size = 256,                # conditioning image size <- this must be set
).cuda()

# ready your training text and images

texts = [
    'a child screaming at finding a worm within a half-eaten apple',
    'lizard running across the desert on two feet',
    'waking up to a psychedelic landscape',
    'seashells sparkling in the shallow waters'
]

images = torch.randn(4, 3, 512, 512).cuda()

# feed it into your maskgit instance, with return_loss set to True

loss = superres_maskgit(
    images,
    texts = texts
)

loss.backward()

# do this for a long time on much data
# then...

images = superres_maskgit.generate(
    texts = [
        'a whale breaching from afar',
        'young girl blowing out candles on her birthday cake',
        'fireworks with blue and green sparkles',
        'waking up to a psychedelic landscape'
    ],
    cond_images = F.interpolate(images, 256),  # conditioning images must be passed in for generating from superres
    cond_scale = 3.
)

images.shape # (4, 3, 512, 512)
All together now
from muse_maskgit_pytorch import Muse

base_maskgit.load('./path/to/base.pt')

superres_maskgit.load('./path/to/superres.pt')

# pass in the trained base_maskgit and superres_maskgit from above

muse = Muse(
    base = base_maskgit,
    superres = superres_maskgit
)

images = muse([
    'a whale breaching from afar',
    'young girl blowing out candles on her birthday cake',
    'fireworks with blue and green sparkles',
    'waking up to a psychedelic landscape'
])

images # List[PIL.Image.Image]
Appreciation
-
StabilityAI for the sponsorship, as well as my other sponsors, for affording me the independence to open source artificial intelligence.
-
🤗 Huggingface for the transformers and accelerate library, both which are wonderful
Todo
-
[x] test end-to-end
-
[x] separate cond_images_or_ids, it is not done right
-
[x] add training code for vae
-
[x] add optional self-conditioning on embeddings
-
[x] combine with token critic paper, already implemented at Phenaki
-
[ ] hook up accelerate training code for maskgit
Citations
@inproceedings{Chang2023MuseTG,
    title   = {Muse: Text-To-Image Generation via Masked Generative Transformers},
    author  = {Huiwen Chang and Han Zhang and Jarred Barber and AJ Maschinot and Jos{\'e} Lezama and Lu Jiang and Ming-Hsuan Yang and Kevin P. Murphy and William T. Freeman and Michael Rubinstein and Yuanzhen Li and Dilip Krishnan},
    year    = {2023}
}
@article{Chen2022AnalogBG,
    title   = {Analog Bits: Generating Discrete Data using Diffusion Models with Self-Conditioning},
    author  = {Ting Chen and Ruixiang Zhang and Geo rey E. Hinton},
    journal = {ArXiv},
    year    = {2022},
    volume  = {abs/2208.04202}
}
@misc{jabri2022scalable,
    title   = {Scalable Adaptive Computation for Iterative Generation},
    author  = {Allan Jabri and David Fleet and Ting Chen},
    year    = {2022},
    eprint  = {2212.11972},
    archivePrefix = {arXiv},
    primaryClass = {cs.LG}
}
@article{Lezama2022ImprovedMI,
    title   = {Improved Masked Image Generation with Token-Critic},
    author  = {Jos{\'e} Lezama and Huiwen Chang and Lu Jiang and Irfan Essa},
    journal = {ArXiv},
    year    = {2022},
    volume  = {abs/2209.04439}
}
@inproceedings{Nijkamp2021SCRIPTSP,
    title   = {SCRIPT: Self-Critic PreTraining of Transformers},
    author  = {Erik Nijkamp and Bo Pang and Ying Nian Wu and Caiming Xiong},
    booktitle = {North American Chapter of the Association for Computational Linguistics},
    year    = {2021}
}
@inproceedings{dao2022flashattention,
    title   = {Flash{A}ttention: Fast and Memory-Efficient Exact Attention with {IO}-Awareness},
    author  = {Dao, Tri and Fu, Daniel Y. and Ermon, Stefano and Rudra, Atri and R{\'e}, Christopher},
    booktitle = {Advances in Neural Information Processing Systems},
    year    = {2022}
}
@misc{mentzer2023finite,
    title   = {Finite Scalar Quantization: VQ-VAE Made Simple},
    author  = {Fabian Mentzer and David Minnen and Eirikur Agustsson and Michael Tschannen},
    year    = {2023},
    eprint  = {2309.15505},
    archivePrefix = {arXiv},
    primaryClass = {cs.CV}
}
@misc{yu2023language,
    title   = {Language Model Beats Diffusion -- Tokenizer is Key to Visual Generation},
    author  = {Lijun Yu and José Lezama and Nitesh B. Gundavarapu and Luca Versari and Kihyuk Sohn and David Minnen and Yong Cheng and Agrim Gupta and Xiuye Gu and Alexander G. Hauptmann and Boqing Gong and Ming-Hsuan Yang and Irfan Essa and David A. Ross and Lu Jiang},
    year    = {2023},
    eprint  = {2310.05737},
    archivePrefix = {arXiv},
    primaryClass = {cs.CV}
}