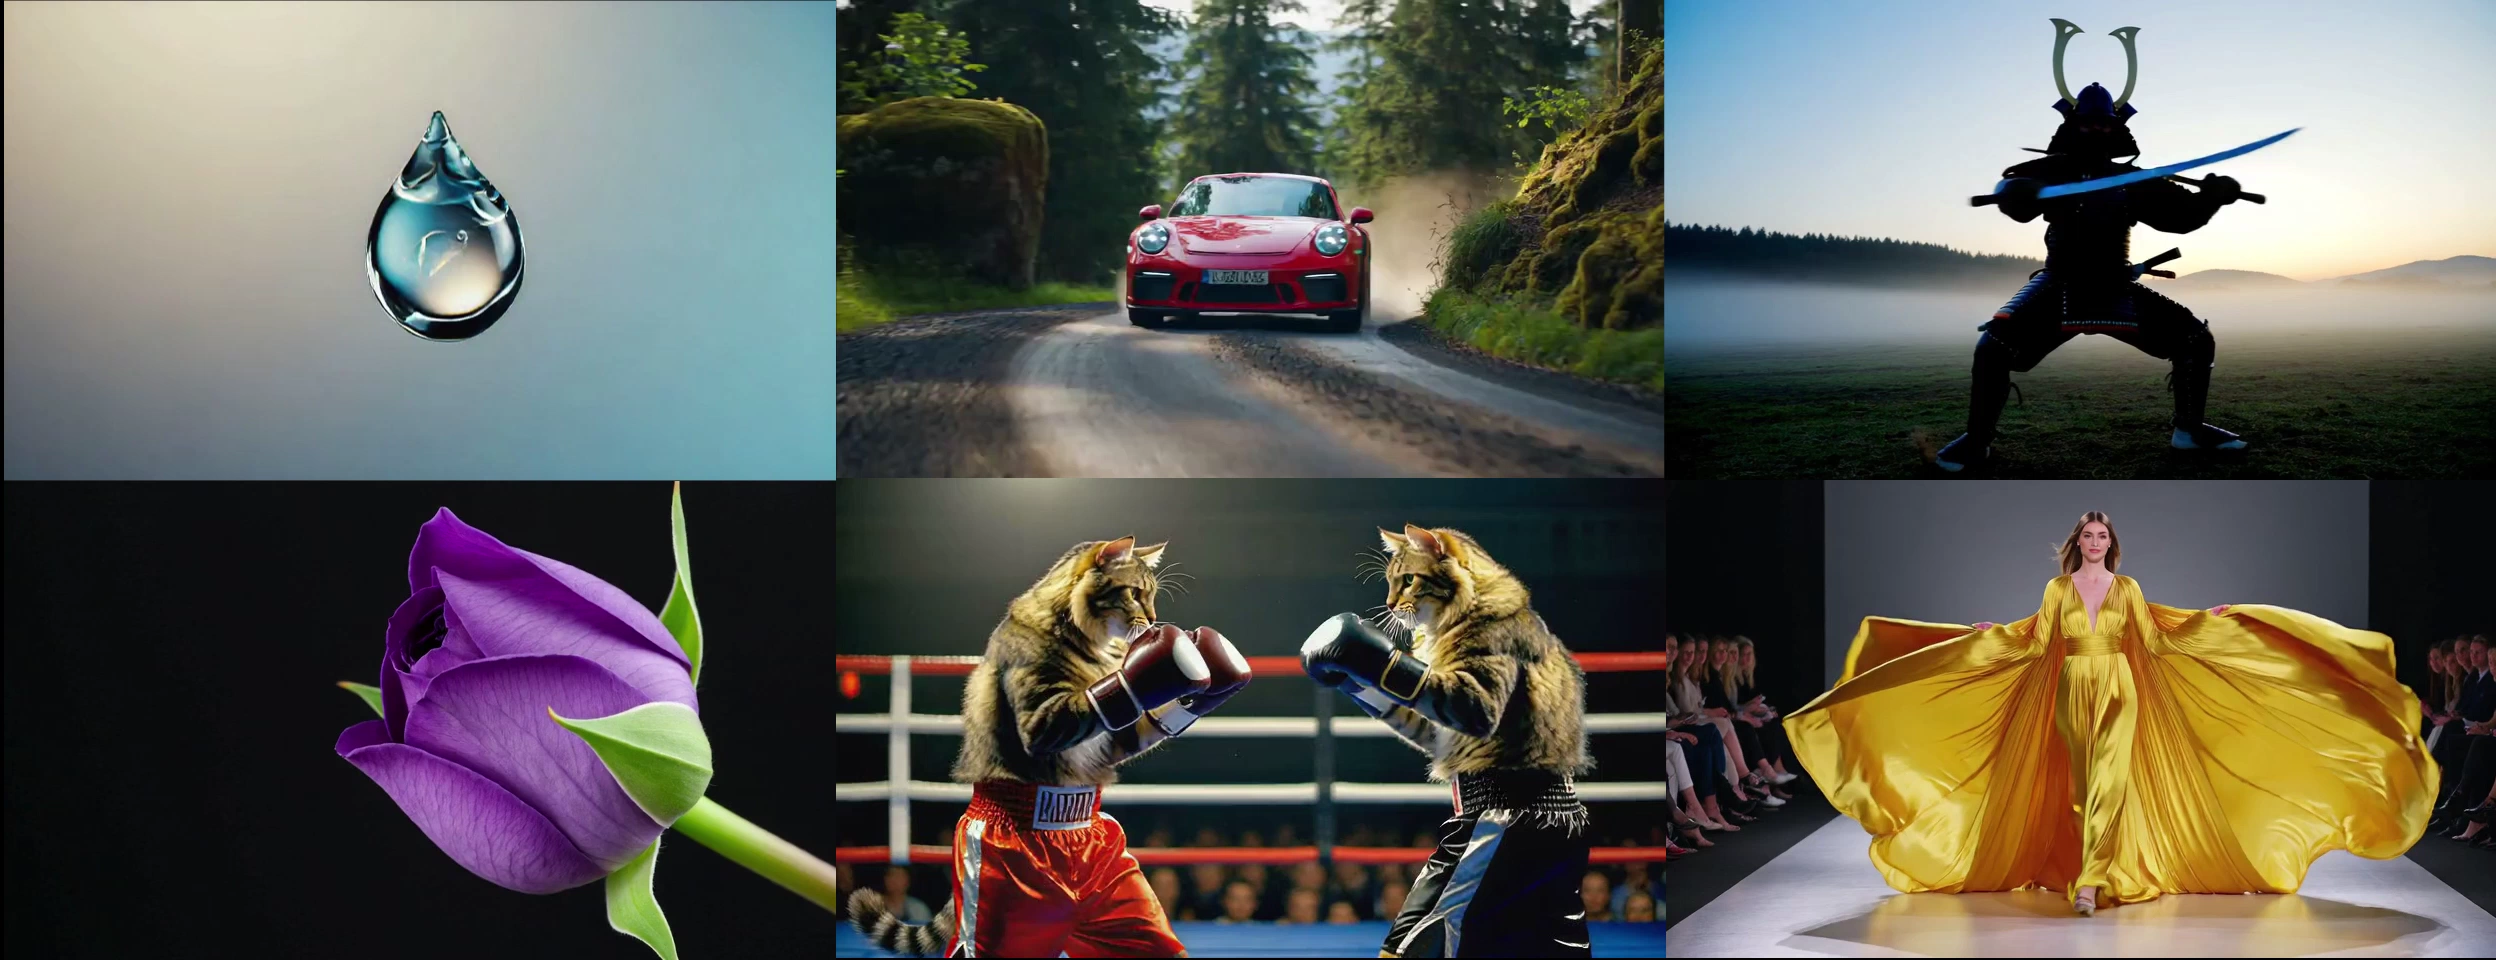
Krea Realtime 14B
Real-time video generation with 14B parameter diffusion model
Distilled from Wan 2.1 14B using Self-Forcing technique
Overview
This repository contains inference code for Krea-Realtime-14B, a real-time video diffusion model distilled from Wan 2.1 14B using the Self-Forcing distillation technique.
Self-Forcing converts traditional video diffusion models into autoregressive models, enabling real-time video generation. Scaling this technique to 14B parameters—over 10× larger than the original work—required significant memory optimizations and engineering breakthroughs.
This implementation is based on the Self-Forcing repository, starting from the LightX2V timestep distilled checkpoint.
📖 Technical Details: For a deep dive into the Self-Forcing technique and scaling challenges, see the official blog post.
Performance
- 11 fps text-to-video generation on NVIDIA B200 with 4 inference steps
- Optimized KV cache management (up to 25GB per GPU)
- Supports streaming and batch inference modes
Key Features
- Real-time video generation with 14B parameters
- WebSocket-based streaming server for live generation
- Offline batch sampling for high-quality outputs
- Multiple attention backends (Flash Attention 4, SageAttention)
- Video-to-video transformation capabilities
- Long-form video generation support
System Requirements
- GPU: NVIDIA GPU with 40GB+ VRAM recommended
- NVIDIA B200: 11 fps with 4 inference steps
- H100, RTX 5xxx series also supported
- OS: Linux (Ubuntu recommended)
- Python: 3.11+
- Storage: ~30GB for model checkpoints
Setup
1. Create Virtual Environment
uv sync
2. Install Attention Backend
For NVIDIA B200 GPUs (recommended):
uv pip install flash_attn --no-build-isolation
For H100/RTX 5xxx and other GPUs:
uv pip install libs/sageattention-2.2.1-cp311-cp311-linux_x86_64.whl
# Or alternatively:
bash install_sage.sh
Note: SageAttention 2++ and 3 have not been tested and may cause quality degradation.
3. Install FFmpeg
sudo apt update && sudo apt install ffmpeg
4. Download Model Checkpoints
# Base model
huggingface-cli download Wan-AI/Wan2.1-T2V-1.3B \
  --local-dir-use-symlinks False \
  --local-dir wan_models/Wan2.1-T2V-1.3B

# Krea Realtime model
huggingface-cli download krea/krea-realtime-video \
  krea-realtime-video-14b.safetensors \
  --local-dir checkpoints
Usage
Option 1: Real-time Server (release_server.py)
Launch a WebSocket server for real-time video generation with streaming output.
1. Configure Environment
export MODEL_FOLDER=wan_models
export CONFIG=configs/self_forcing_server_14b.yaml  # optional
export CUDA_VISIBLE_DEVICES=0
export DO_COMPILE=true  # Use torch.compile for better performance
2. Start Server
uvicorn release_server:app --host 0.0.0.0 --port 8000
3. Access Demo
- Health check:
curl http://localhost:8000/health - Web UI: Open
http://localhost:8000/in your browser - The demo interface (
templates/release_demo.html) allows you to:- Enter prompts
- Adjust generation parameters
- Stream frames in real-time over WebSocket
4. Configuration Options
DO_COMPILE=false- Disabletorch.compilefor faster startup but slower inferenceCONFIG- Path to custom config file
Stop the server with Ctrl+C.
Option 2: Offline Sampling (sample.py)
Generate videos offline without the WebSocket layer.
Basic Example
Create a script to generate videos:
# sample_run.py
from pathlib import Path
from release_server import GenerateParams
from sample import sample_videos

# Configure generation parameters
params = GenerateParams(
    prompt="",  # Will be overwritten per prompt
    width=832,
    height=480,
    num_blocks=9,
    seed=42,
    kv_cache_num_frames=3,
)

# Define prompts
prompts = [
    "A hyperrealistic close-up of ocean waves shimmering at sunset.",
    "A bustling neon-drenched alleyway with rain-soaked pavement.",
]

# Generate videos
sample_videos(
    prompts_list=prompts,
    config_path="configs/self_forcing_dmd_will_optims.yaml",
    output_dir="outputs/samples",
    params=params,
    save_videos=True,  # Requires ffmpeg
    fps=24,
)
Run
python sample_run.py
Key Details
- Model loading: Models are loaded lazily when
models=None. Reuse the returned models object for multiple calls to avoid reloading. - Output structure: Frames are saved to
output_dir/prompt_XXX/. Videos (ifsave_videos=True) are saved as MP4 files. - Additional helpers: Check
sample.pyforcreate_grid()andsample_single_video()utilities.
Repository Structure
├── release_server.py          # WebSocket server for real-time generation
├── sample.py                  # Offline batch sampling
├── v2v.py                     # Video-to-video utilities
├── configs/                   # Configuration files
├── demo_utils/                # VAE and utility functions
├── model/                     # Model implementations
├── pipeline/                  # Inference pipelines
├── utils/                     # Helper utilities
├── wan/                       # Wan model components
└── templates/                 # Web UI templates
Credits
This work is based on:
- Self-Forcing - Original distillation technique
- Wan 2.1 14B - Base text-to-video model
- LightX2V - Timestep distilled checkpoint
For technical details on the Self-Forcing scaling and optimization process, see our blog post.
License
This project is licensed under the Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International License - see the LICENSE.md file for details.
Citation
If you use this work, please cite:
@software{krea_realtime_14b,
  title={Krea Realtime 14B: Real-time Video Generation},
  author={Erwann Millon},
  year={2025},
  url={https://github.com/krea-ai/realtime-video}
}