ASearcher: An Open-Source Large-Scale Reinforcement Learning Project for Search Agents
| 📰 Paper | 🤗 Datasets | 🤗 Models |
Introduction
ASearcher is an open-source framework designed for large-scale online reinforcement learning (RL) training of search agents. Our mission is to advance Search Intelligence to expert-level performance. We are fully committed to open-source by releasing model weights, detailed training methodologies, and data synthesis pipelines. Additionally, we provide comprehensive guidance on building and training customized agents based on AReaL. ASearcher empowers developers to build their own high-performance search agents easily and cost-effectively.
ASearcher Highlights
- 🔁 Data Synthesis Agent: We introduce a prompt-based LLM agent that autonomously generates grounded, challenging, and highly uncertain QA pairs to enhance training diversity.
- ⚡ Fully Asynchronous Agentic RL: Our scalable agentic RL framework decouples trajectory collection from model training, eliminating GPU idle time and enabling efficient long-horizon RL training.
- 🌐 RL Enables Long-Horizon Search: Through RL training, ASearcher exhibits long-horizon search, with tool calls exceeding 100 rounds and generated tokens surpassing 400k during RL training.
- 🏆 Cutting-Edge Performance: With a simple agent design and no external LLMs, ASearcher achieves Avg@4 scores of 58.7, 51.1, and 74.5 on GAIA, xBench-DeepSearch, and Frames, respectively, surpassing other open-source search agents on the same 32B scale. ASearcher achieves Pass@4 scores of 74.7, 75.0, and 85.5 on GAIA, xBench-DeepSearch, and Frames.
- 📈 Substantial Improvement Through RL: RL training brings improvements of +15.0, +22.4, and +14.6 Avg@4 scores on GAIA, xBench-DeepSearch, and Frames, respectively.
- 🛠️ Fully Open-Source: We are committed to open-sourcing all components for agentic RL training, including datasets, data synthesis agent, training details, model weights, and detailed guidelines for customized agent development. The released models and data could be found at 🤗Huggingface .
📰 News & Updates:
- 2025-09-18: Training code and latest model for ASearcher-Web-QwQ are released! Checkout ASearcher-Web-QwQ-V2 and our training code for smooth large-scale agentic RL training!
- 2025-09-18: More clean & flexible training! ASearcher now uses AReaL as a package.
- 2025-08-30: ASearcher-Web-QwQ-V2 incoming! State-of-the-art search agent with improved training data and end-to-end agentic RL training. Model and data will be released soon.
- 2025-08-09: Our technical report is released.
- 2025-08-05: ASearcher is released, try asynchronous RL training and automatic QA synthesis to train an advanced search agent!🎉
Results Showcase
We evaluate our approach on challenging QA benchmarks (GAIA, xBench-DeepSearch, and Frames), which test advanced problem-solving abilities and web search strategies. These benchmarks are specifically designed to assess an agent's capability to interact with the real web and retrieve up-to-date information, often beyond the internal knowledge of LLMs.
Cutting-Edge Performance. Our agent, ASearcher-Web-QwQ-v2, achieves state-of-the-art performance among open-source agents, with the highest Avg@4 scores on GAIA and xBench. Additionally, we report Pass@4, which measures the ratio of questions where the agent finds the correct answer within four trials. ASearcher-Web-QwQ-v2 also outperforms existing open-source agents in terms of pass rate, further demonstrating its robustness.
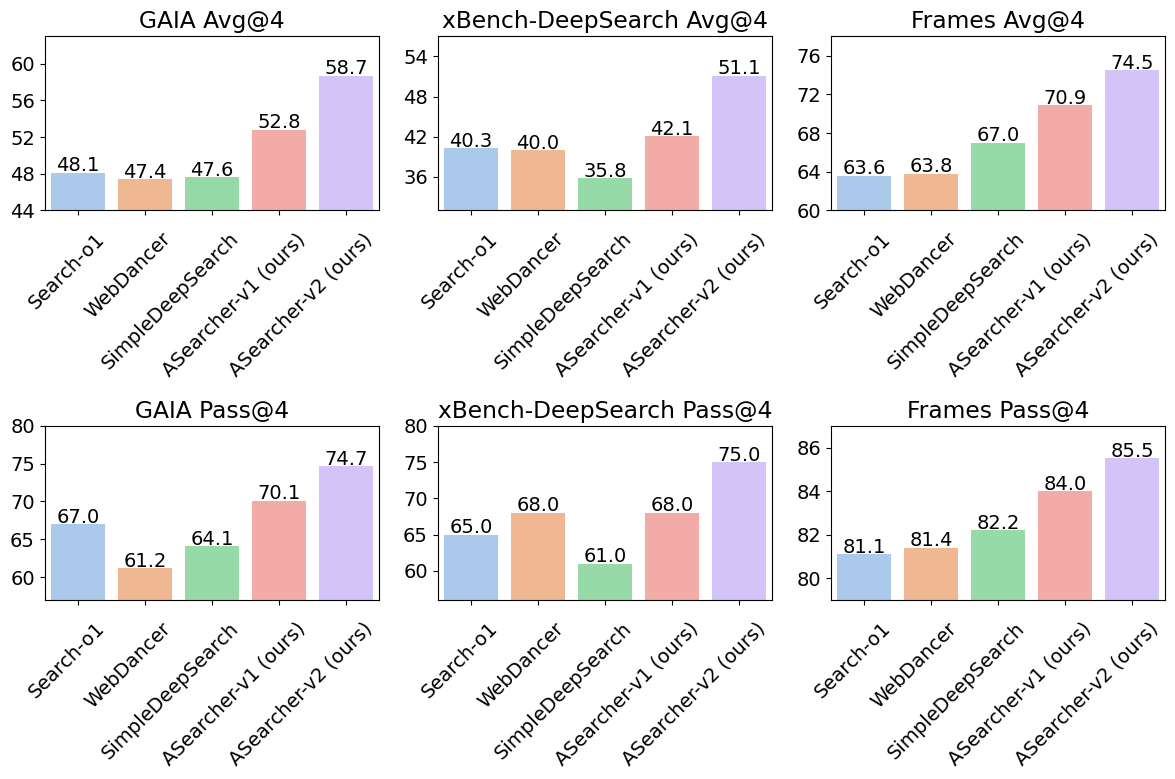
Fig.1 The performance of various methods based on 32B-scale models on GAIA, xBench-DeepSearch, and frames. Avg@4 and Pass@4 are reported
Substantial Improvements Through RL. When comparing performance before and after reinforcement learning (RL), ASearcher-Web-QwQ-v2 achieves improvements of +15.0, +22.4, and +14.6 on GAIA, xBench-DeepSearch, and Frames, respectively. In terms of pass rate (Pass@4), ASearcher-Web-QwQ-v2 also demonstrates significant gains—particularly on xBench-DeepSearch, where it shows a remarkable improvement of 22.4.
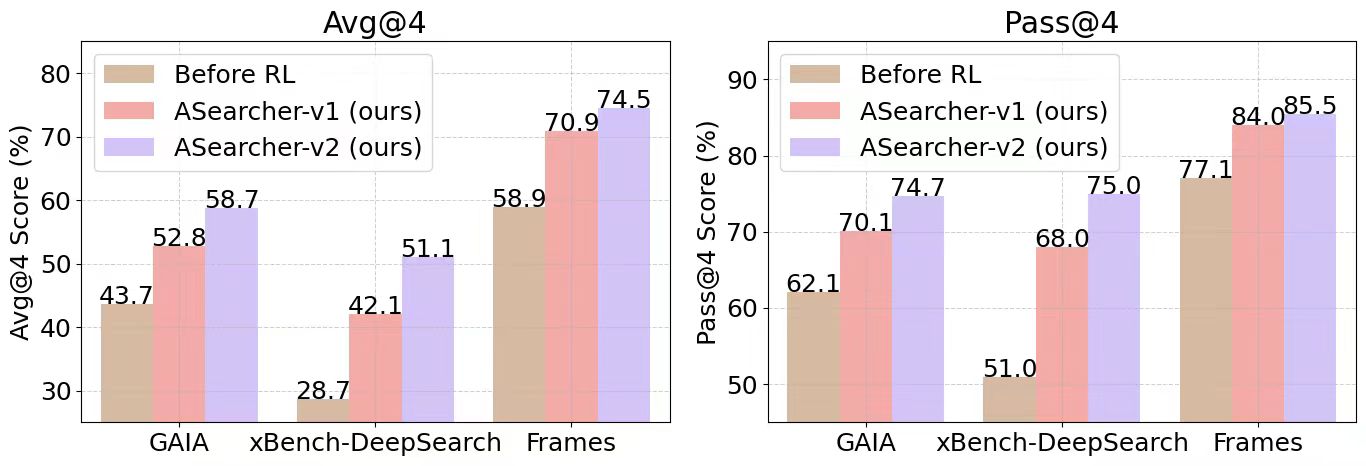
Fig.2 Comparison of the performance of QwQ-32B agent before and after RL Training.
Data Synthesis
We develop a prompt-based LLM agent designed to autonomously generate grounded, challenging, and highly uncertain QA pairs. The process begins with basic questions, which the agent then iteratively refines through two key strategies:
- Fuzzing: Increasing uncertainty by obscuring key details in the query.
- Context Injection: Augmenting questions with external facts retrieved via tools to deepen complexity.
Each generated question undergoes rigorous multi-stage validation:
- Quality Assurance: Checks for fluency, timeliness, and logical coherence.
- Difficulty Verification: Compares answers generated by an LRM against ground truth to ensure challenge.
- Answer Uniqueness Validation: Confirms that incorrect LRM answers are indeed invalid, preserving question integrity.
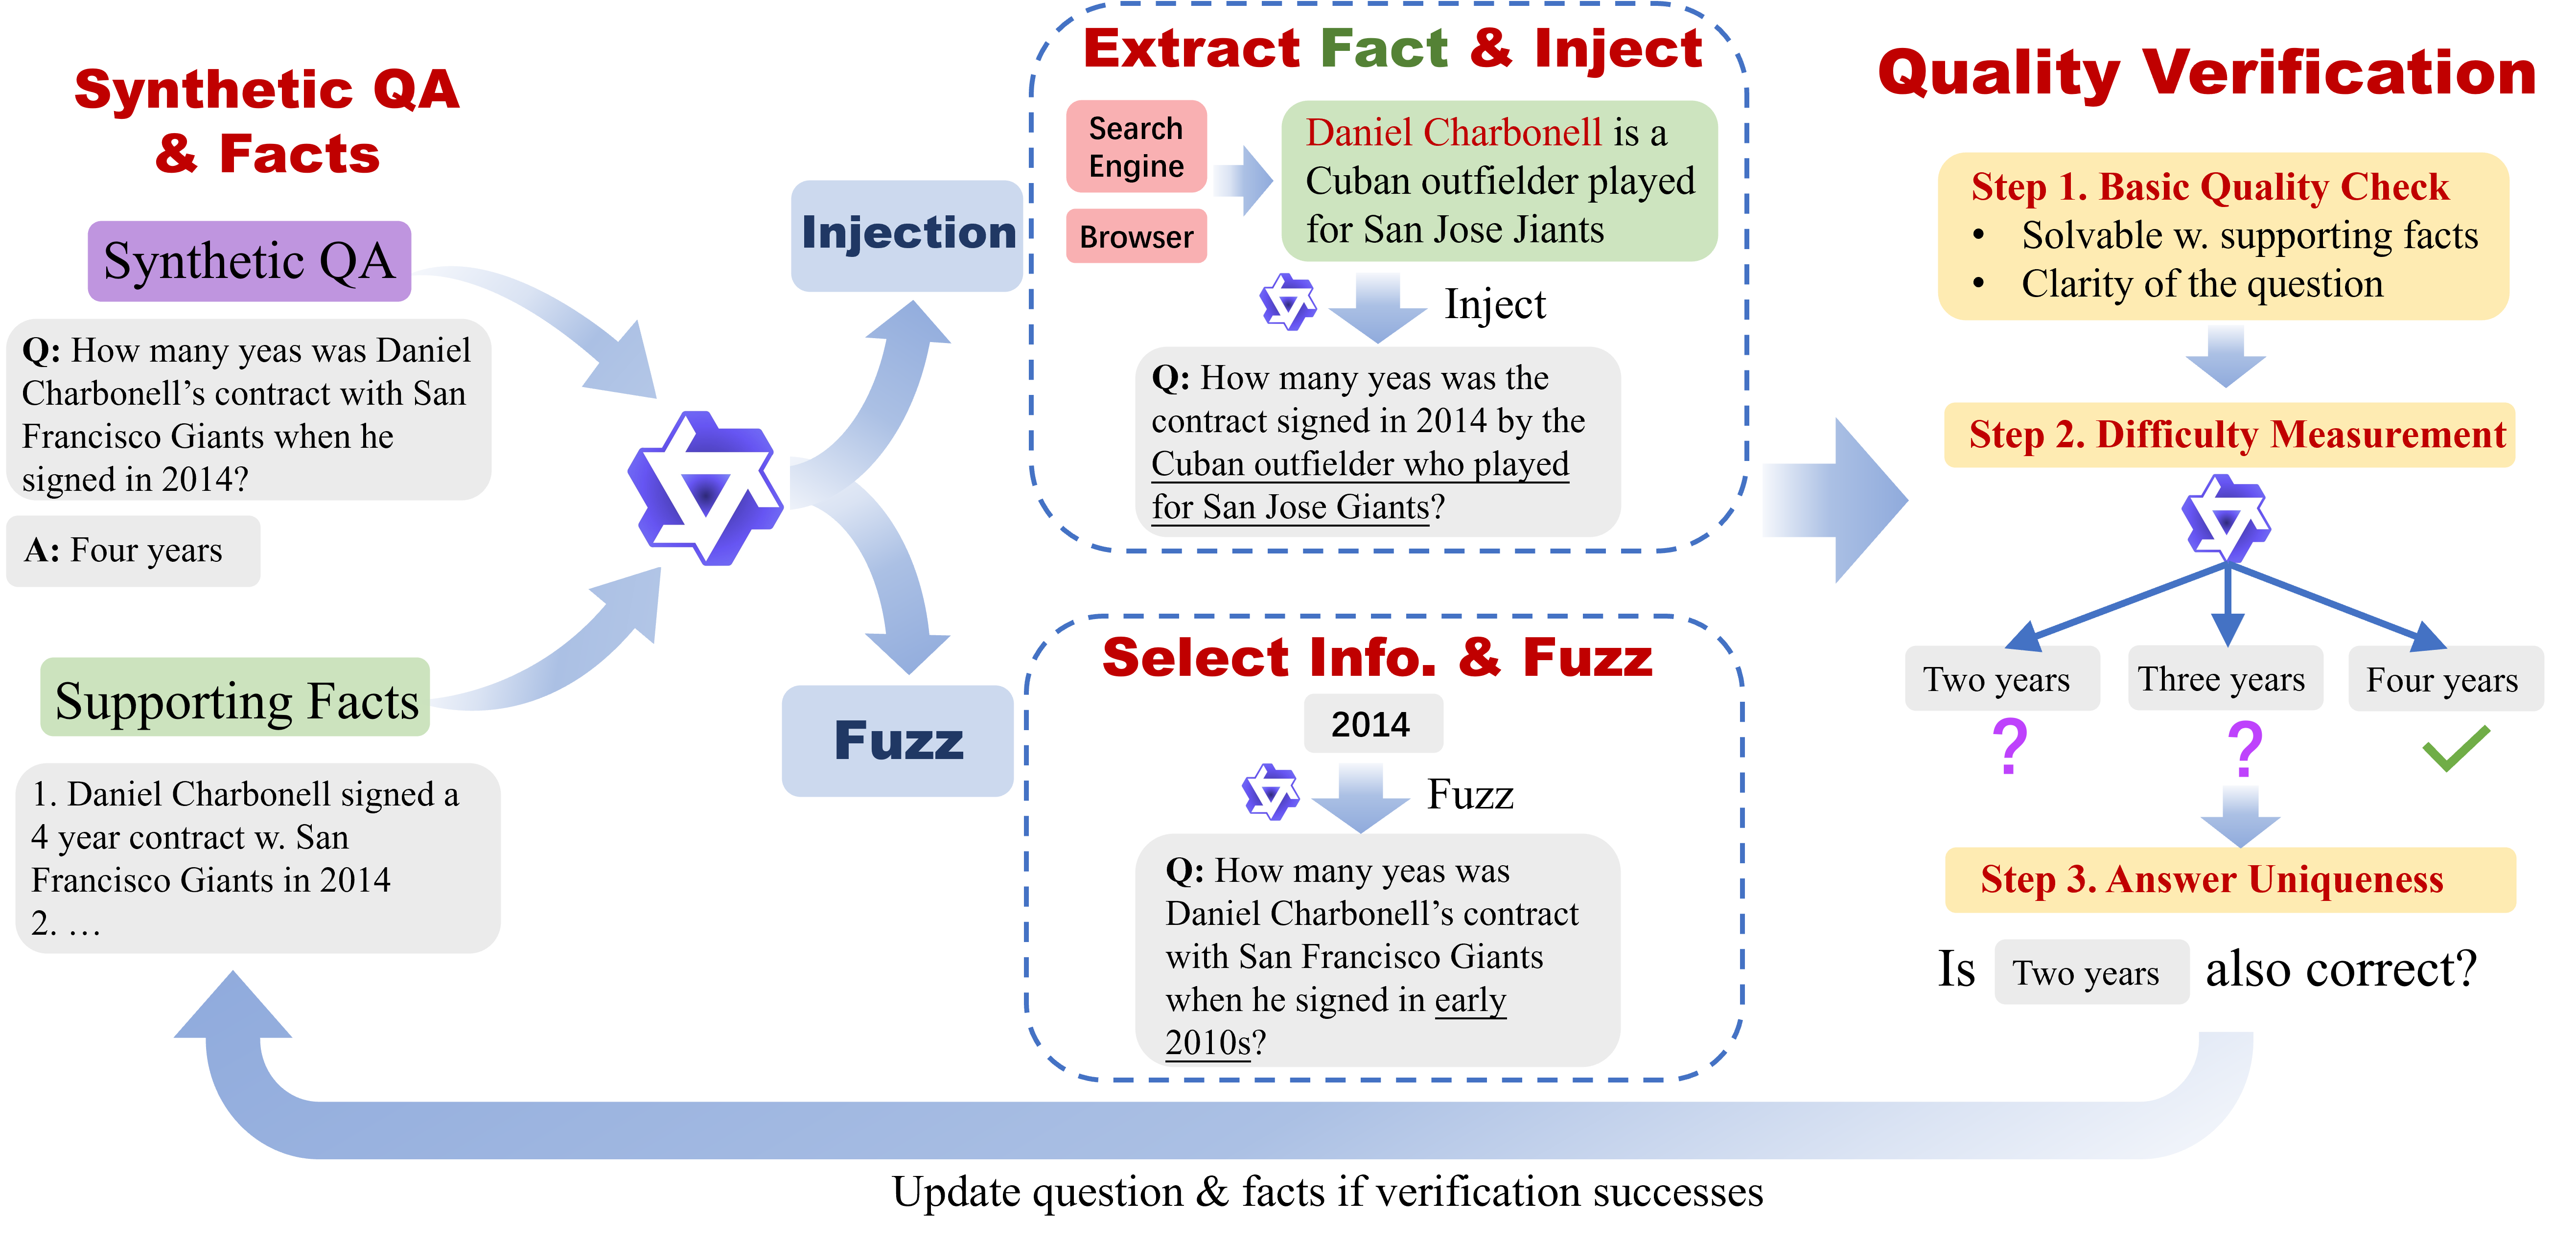
Fig.3 Data Synthesis Agent.
Fully Asynchronous Agentic RL training
Our analysis reveals significant variance in the execution time of agent trajectories. By examining the number of turns and generated tokens during RL training, we observe that lengthy trajectories can require dozens more turns than shorter ones. In terms of token generation, longer trajectories exceed their shorter counterparts by up to two orders of magnitude, as illustrated in the figure below.
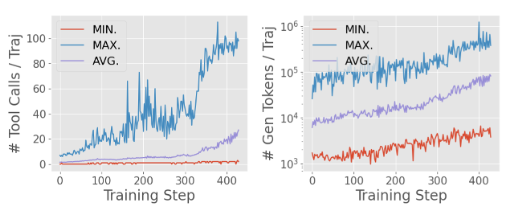
Fig.4 (Left) Number of turns versus training steps. (Right) Number of generated tokens versus training steps.
Fuly Asynchronous RL Training Enables Long-Horizon Tool Use. In batch-generation RL systems, a batch must wait for the longest trajectory to complete, resulting in significant GPU idle time. In contrast, fully asynchronous reinforcement learning (RL) eliminates this bottleneck by completely decoupling training from trajectory generation. This allows relaxed turn limits (e.g., 128 turns/trajectory), enabling agents to explore deeper search paths without sacrificing training efficiency. Remarkably, our agent, ASearcher-Web-QwQ, achieves extreme long-horizon search, with tool calls exceeding 100 turns and generated tokens surpassing 400k during RL training.
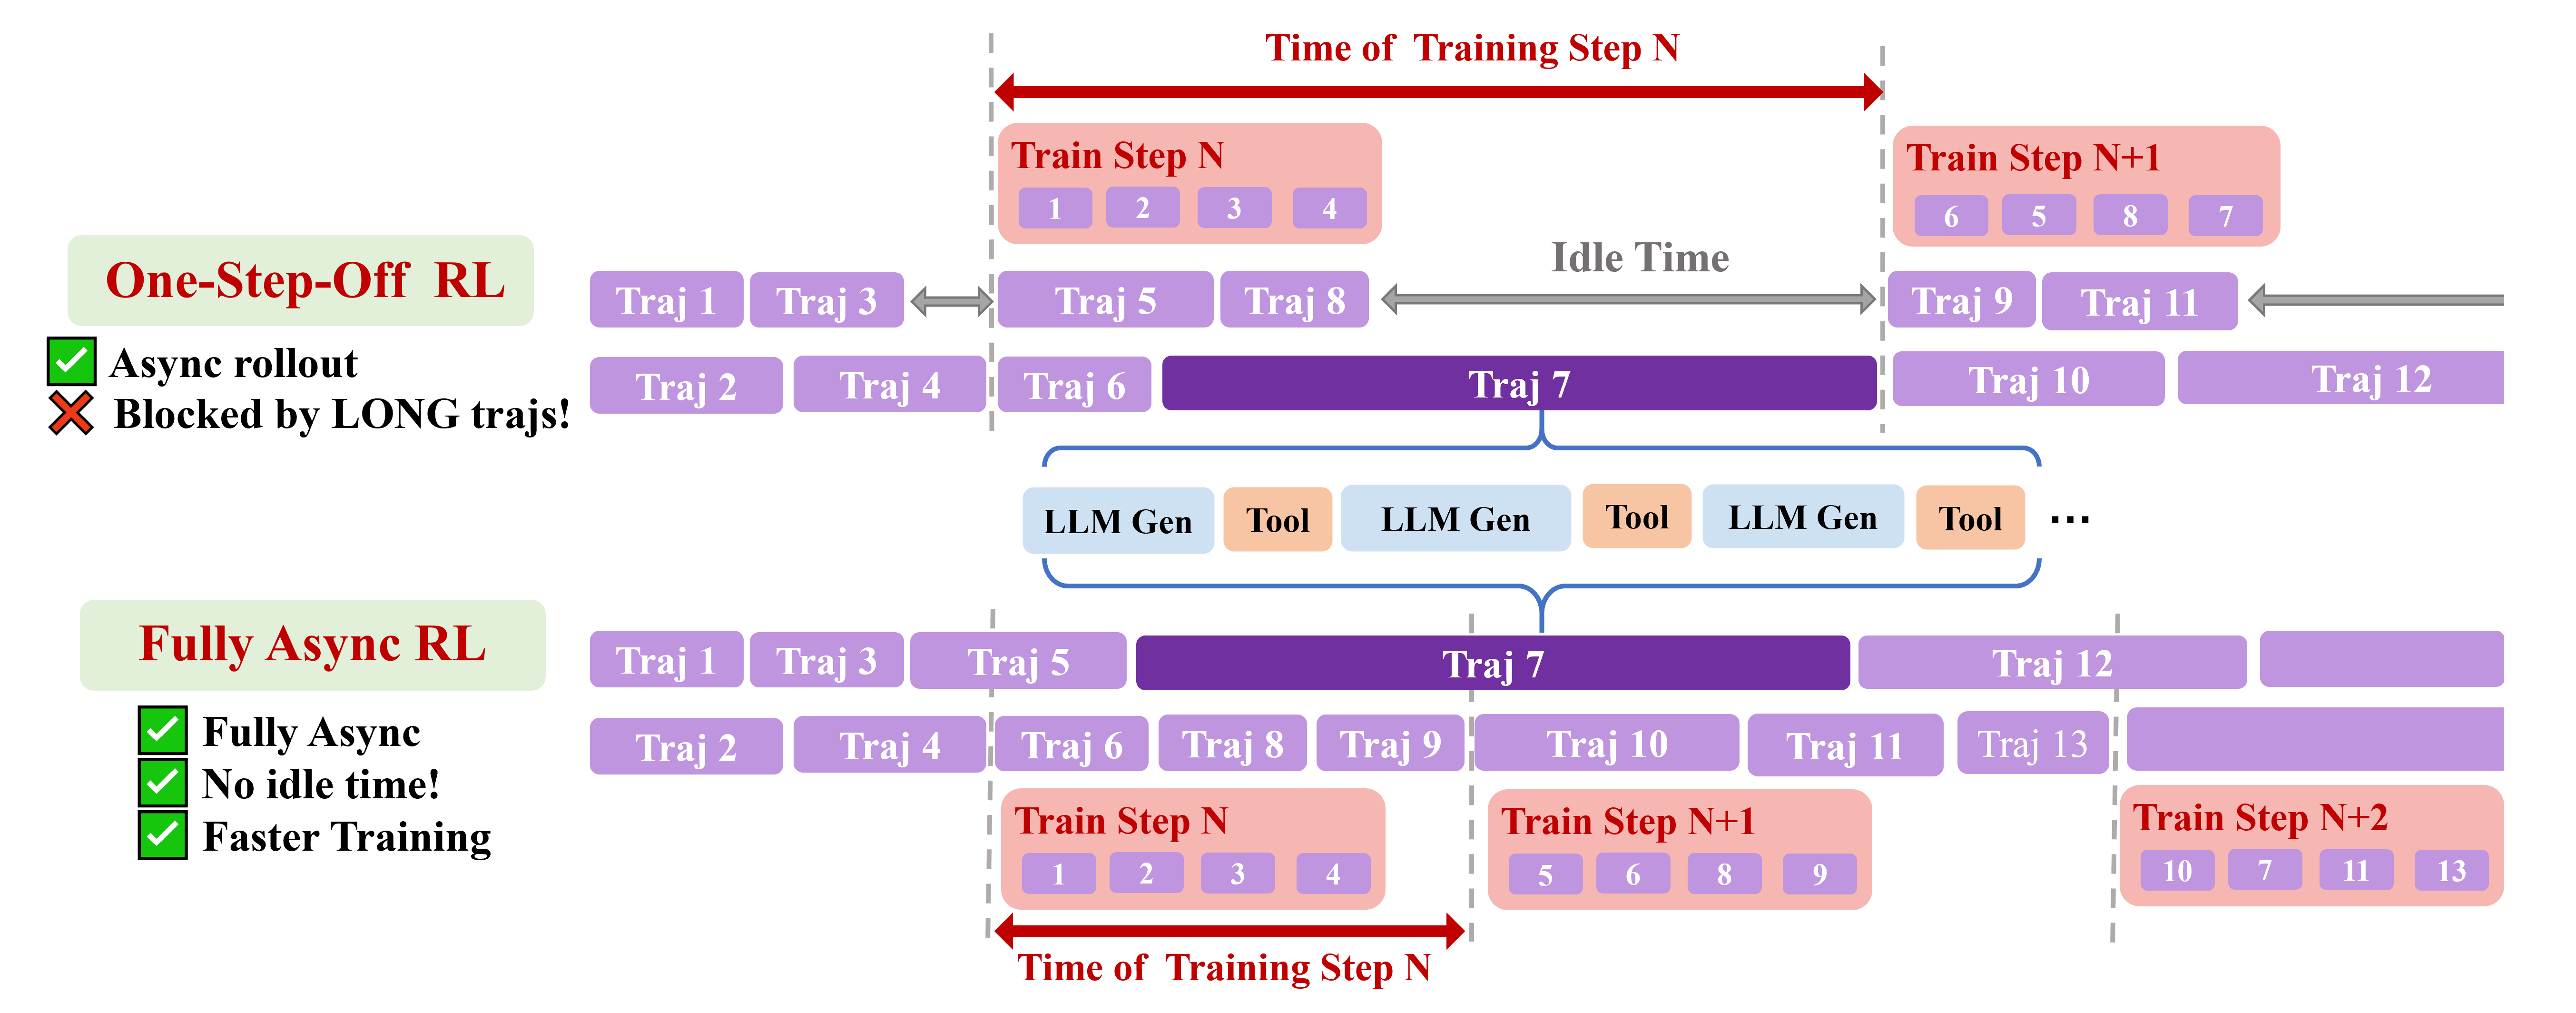
Fig.5 Illustration of full fully asynchronous RL Training.
Quick Start
Evaluation
To reproduce the results presented in Fig.2, please run the following script.
cd evaluation/

MODEL_PATH=/path/to/models
DATA_DIR=/path/to/test_set # Could be downloaded from [https://huggingface.co/datasets/inclusionAI/ASearcher-test-data]

DATA_NAMES=GAIA,xbench-deepsearch,Frames
AGENT_TYPE=asearcher-reasoning
PROMPT_TYPE=asearcher-reasoning
SEARCH_CLIENT_TYPE=async-web-search-access

SCRIPT_DIR="$(cd "$(dirname "${BASH_SOURCE[0]}")" &> /dev/null && pwd)"
PROJECT_ROOT="$(dirname "$SCRIPT_DIR")"

PYTHONPATH="${PROJECT_ROOT}:$PYTHONPATH" \
SERPER_API_KEY=${your_serper_api_key} \
JINA_API_KEY=${your_jina_api_key} \
TOKENIZERS_PARALLELISM=false \
python3 search_eval_async.py \
    --data_names ${DATA_NAMES} \
    --model_name_or_path ${MODEL_PATH}  \
    --output_dir ${MODEL_PATH} \
    --data_dir ${DATA_DIR} \
    --prompt_type $PROMPT_TYPE \
    --agent-type ${AGENT_TYPE} \
    --search-client-type ${SEARCH_CLIENT_TYPE} \
    --tensor_parallel_size 4 \
    --temperature 0.6 \
    --parallel-mode seed \
    --seed 1 \
    --use-jina \
    --llm_as_judge \
    --pass-at-k 1 \ # if you want get more stable result, please increase it
please also refer to the Evaluation doc for the detailed guideline.
Training
Fine-tuning a 7B model
1. Set Up the Environment
Please refer to https://inclusionai.github.io/AReaL/tutorial/installation.html#runtime-environment
2.1 Training a 7B model on 16 nodes (recommanded)
cd AReaL

export SERPER_API_KEY=YOUR_SERPER_API_KEY
export JINA_API_KEY=YOUR_JINA_API_KEY
python3 -m areal.launcher.ray ASearcher/train/asearcher.py \
    --config ASearcher/configs/asearcher_web_16nodes.yaml \
    experiment_name= \
    trial_name= \
    allocation_mode=sglang.d96p1t1+d32p1t1 \
    cluster.n_nodes=16 \
    cluster.n_gpus_per_node=8
2.2 Training a 7B model on a single node (might be slow)
cd AReaL

export SERPER_API_KEY=YOUR_SERPER_API_KEY
export JINA_API_KEY=YOUR_JINA_API_KEY

python3 -m areal.launcher.local ASearcher/train/asearcher.py \
    --config ASearcher/configs/asearcher_web.yaml \
    experiment_name= \
    trial_name=
Fine-tuning a QwQ-32B Agent
Step 1. Launch Qwen2.5-72B-Instruct for LLM-as-Judge:
python3 -m areal.launcher.ray ASearcher/train/asearcher_reasoning.py \
    --config ASearcher/configs/asearcher_web_qwq.yaml \
    experiment_name=asearcher-qwen72b-inst-server-only \
    trial_name=run1 \
    cluster.n_nodes=1 allocation_mode=sglang.d2t4p1 \
    actor.path=Qwen/Qwen2.5-72B-Instruct
Step 2. Launch QwQ-32B agent training:
python3 -m areal.launcher.ray \
    ASearcher/train/asearcher_reasoning.py \
    --config ASearcher/configs/asearcher_web_qwq.yaml \
    experiment_name=asearcher-qwq-train \
    trial_name=run1 cluster.n_nodes=6 allocation_mode=sglang.d2t8+d4t8 \
    actor.path=Qwen/QwQ-32B \
    train_dataset.path=path_to_ASearcher-LRM-35k \
    judge_engine.experiment_name=asearcher-qwen72b-inst-server-only \
    judge_engine.trial_name=run1
please also refer to the Training doc for the detailed guideline.
Launch demo
Please refer Demo documentation to see how to launch an asearcher visualization demo.
(Optional) Customization
Please refer to our guideline for more information about building a custom agent.
(Optional) Data Synthesis
The data synthesis agent is provided in qa_synthesis/qa_synthesis_agent.py. To run the agent for synthesizing QA, you need to,
- Download related data, including the Wikipedia 2018 webpages, and a list of sampled links
- Launch SGLang servers for two models:
QwQ-32BandQwen2.5-72B-instruct - Run
python3 qa_synthesis/qa_synthesis_agent.pyto synthesize high-quality QAs!
Acknowledgements
We would like to acknowledge that the primary contributors to this work are from the RL Lab at Ant Research and the Institute for Interdisciplinary Information Sciences at Tsinghua University.
Our team has also received invaluable assistance from the following groups:
- The AWorld team at Ant Group for sharing their experience in agent development
- The Super Computing Technology (SCT) team at Ant Group, particularly for their specialized knowledge in large-scale cluster management and operations
We are also grateful for the foundational work and inspiration provided by the research community, including but not limited to Search-o1, Search-R1 and WebAgent.
Citation
Please cite our work if you find our work useful!
@misc{gao2025turnsunlockinglonghorizonagentic,
      title={Beyond Ten Turns: Unlocking Long-Horizon Agentic Search with Large-Scale Asynchronous RL},
      author={Jiaxuan Gao and Wei Fu and Minyang Xie and Shusheng Xu and Chuyi He and Zhiyu Mei and Banghua Zhu and Yi Wu},
      year={2025},
      eprint={2508.07976},
      archivePrefix={arXiv},
      primaryClass={cs.CL},
      url={https://arxiv.org/abs/2508.07976},
}