GraphRAG4OpenWebUI integrates Microsoft's GraphRAG technology into Open WebUI, providing a versatile information retrieval API. It combines local, global, and web searches for advanced Q&A systems and search engines. This tool simplifies graph-based retrieval integration in open web environments.
Make Codex cheaper without making it dumber with DeepSeek.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Language
Python
Category
AI Engineering
Subcategory
Give agent tools
Keywords
Databases, Text-to-SQL
Stars
606
Forks
52
Contributors
1
Created date
2023-05-21
Updated date
2026-08-29
Stars in 1 day
0
Stars in 7 days
0
Rank
16,203
Previous rank
15,993
Rank change
-210
7-day stars rank
15,402
Previous 7-day stars rank
15,410
7-day stars rank change
8
Total stars rank
16,663
Previous total stars rank
16,636
Total stars rank change
-27
Country
China
README summary
ChatDB: Augmenting LLMs with Databases as Their Symbolic Memory Paper | Project Page This is the official repository of the paper: **ChatDB: Augmenting LLMs with Databases as Their Symbolic Memory**. **We will continuously add new features to this code repository. ** Large language models (LLMs) with memory are computationally universal. However, mainstream LLMs are not taking full advantage of memory, and the designs are heavily influenced by biological brains. Due to their approximate nature and proneness to the accumulation of errors, conventional
neural memory mechanisms cannot support LLMs to simulate complex reasoning. In this paper, we seek inspiration from modern computer architectures to augment LLMs with symbolic memory for complex multi-hop reasoning. Such a symbolic memory framework is instantiated as an LLM and a set of SQL databases, where the LLM generates SQL instructions to manipulate the SQL databases. We validate the effectiveness of the proposed memory framework on a synthetic dataset requiring complex reasoning. Quick Start Install dependencies Add keys
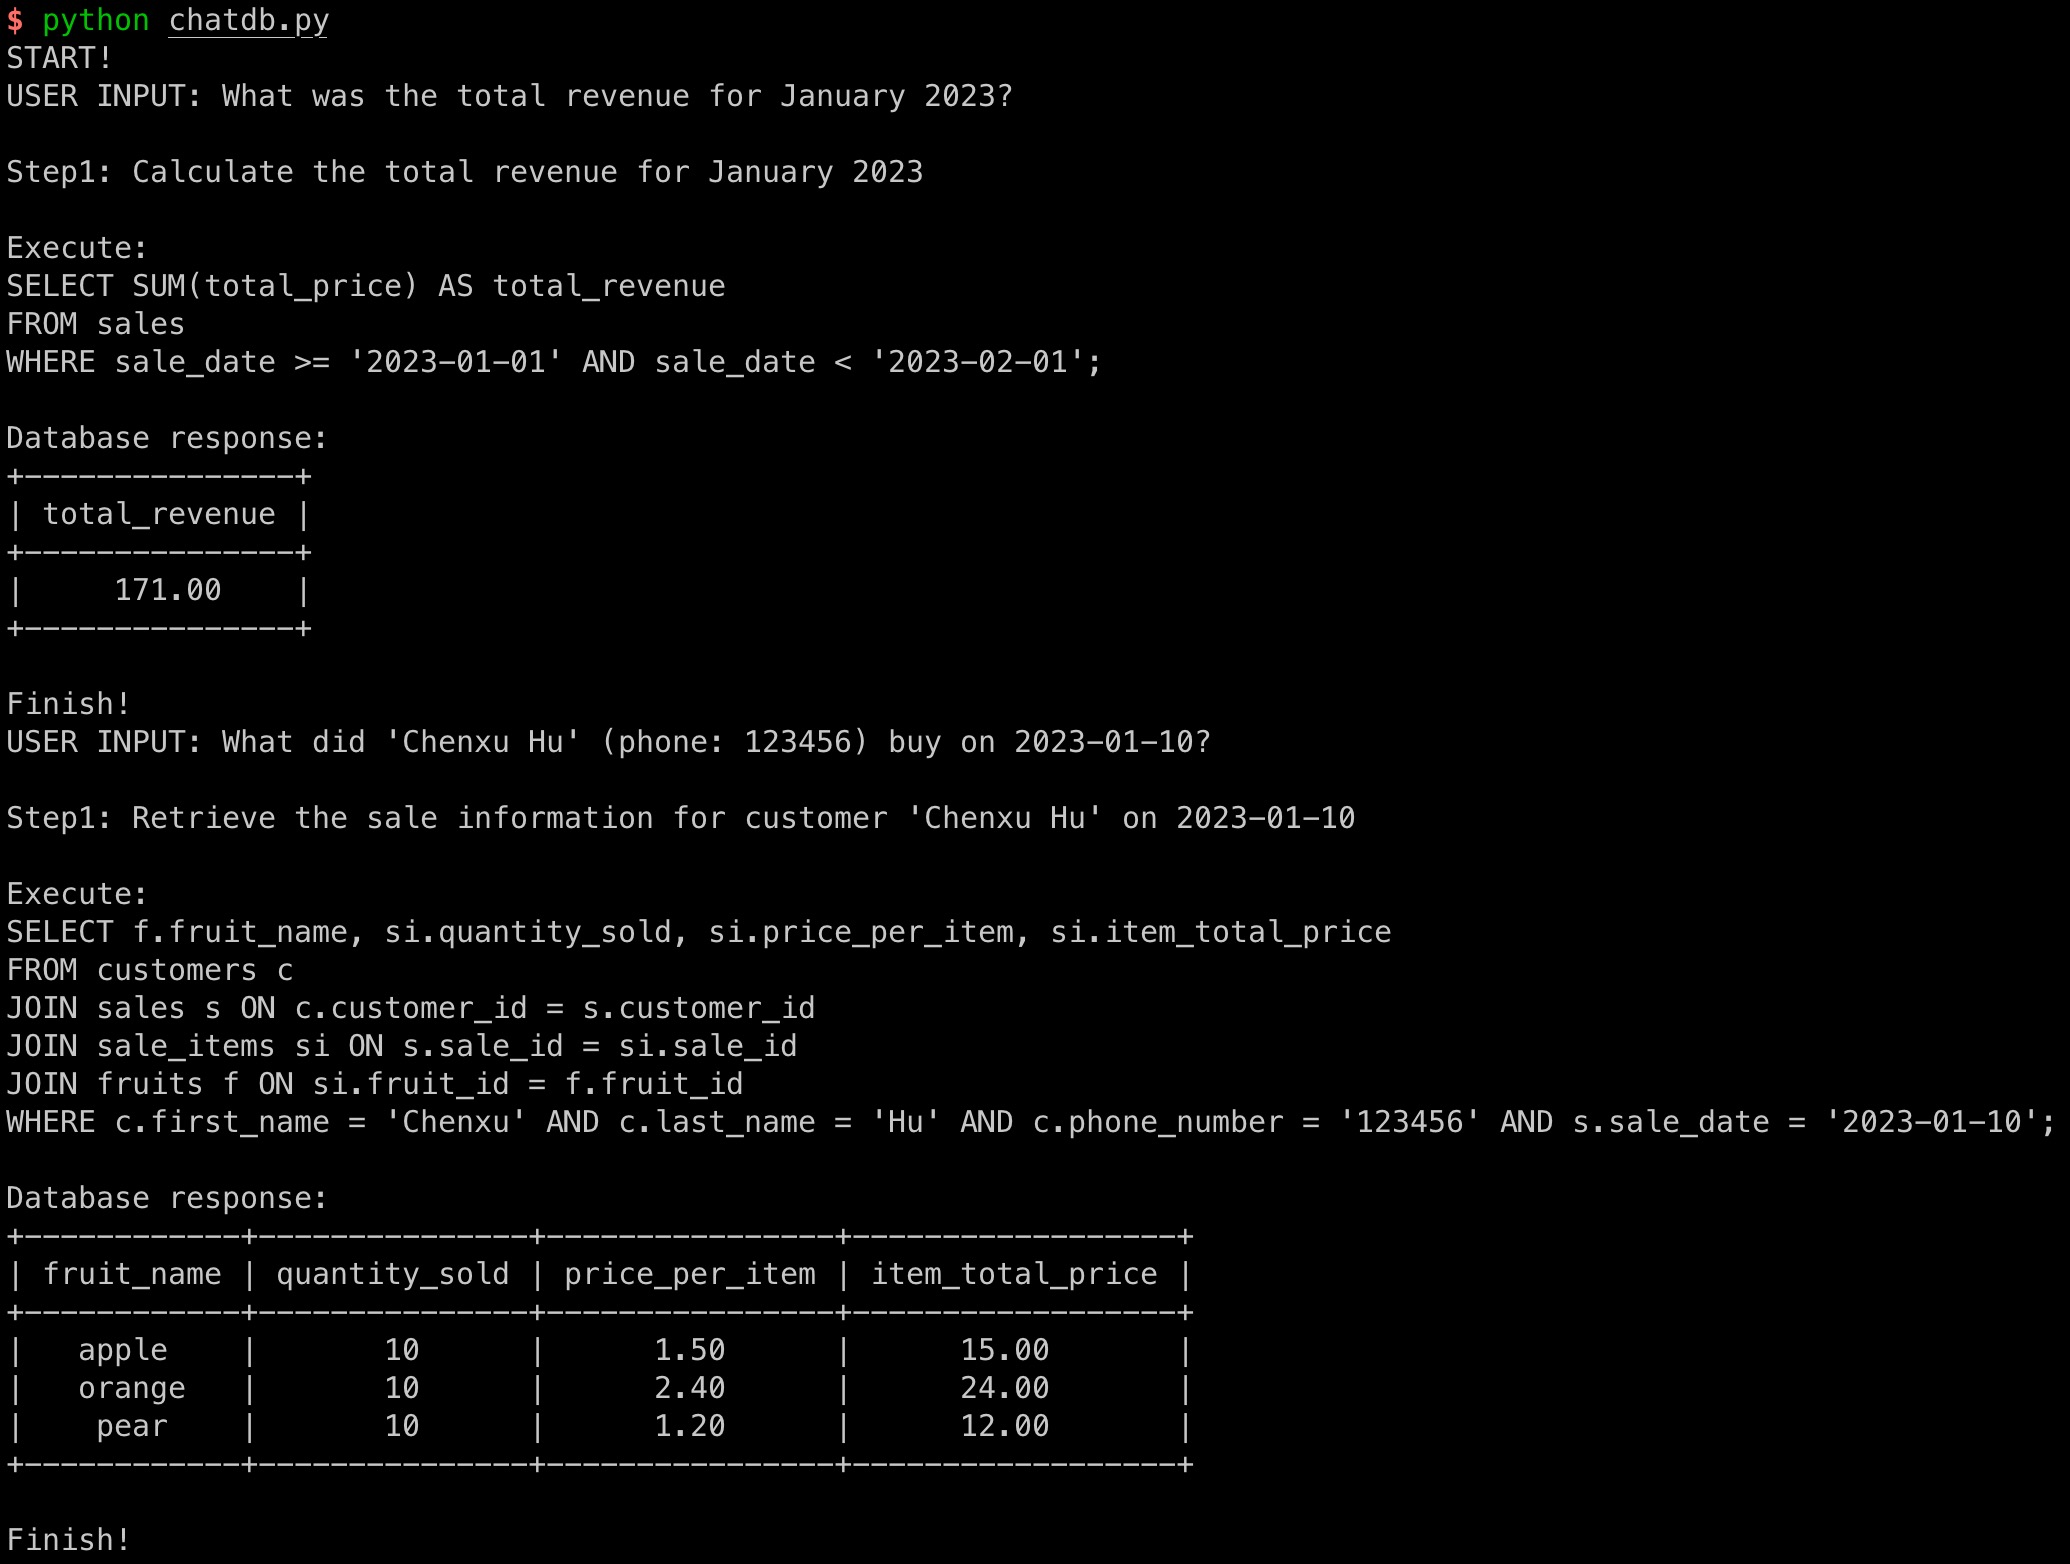
A minimal CLI demo in a fruit shop scenario The CLI demo looks as follows. Citation If you find our work useful for your research, please consider citing the paper:
Frequently asked questions
How many stars and forks are recorded?
huchenxucs/ChatDB has 606 stars and 52 forks.
What is the repository rank?
huchenxucs/ChatDB is ranked 16,203.
What language and category are recorded?
huchenxucs/ChatDB has 606 stars, uses Python and belongs to AI Engineering.
Which repository is closest in rank?
huchenxucs/ChatDB is compared with enginebai/PyMessager, ranked 16,202 with 606 stars.
README
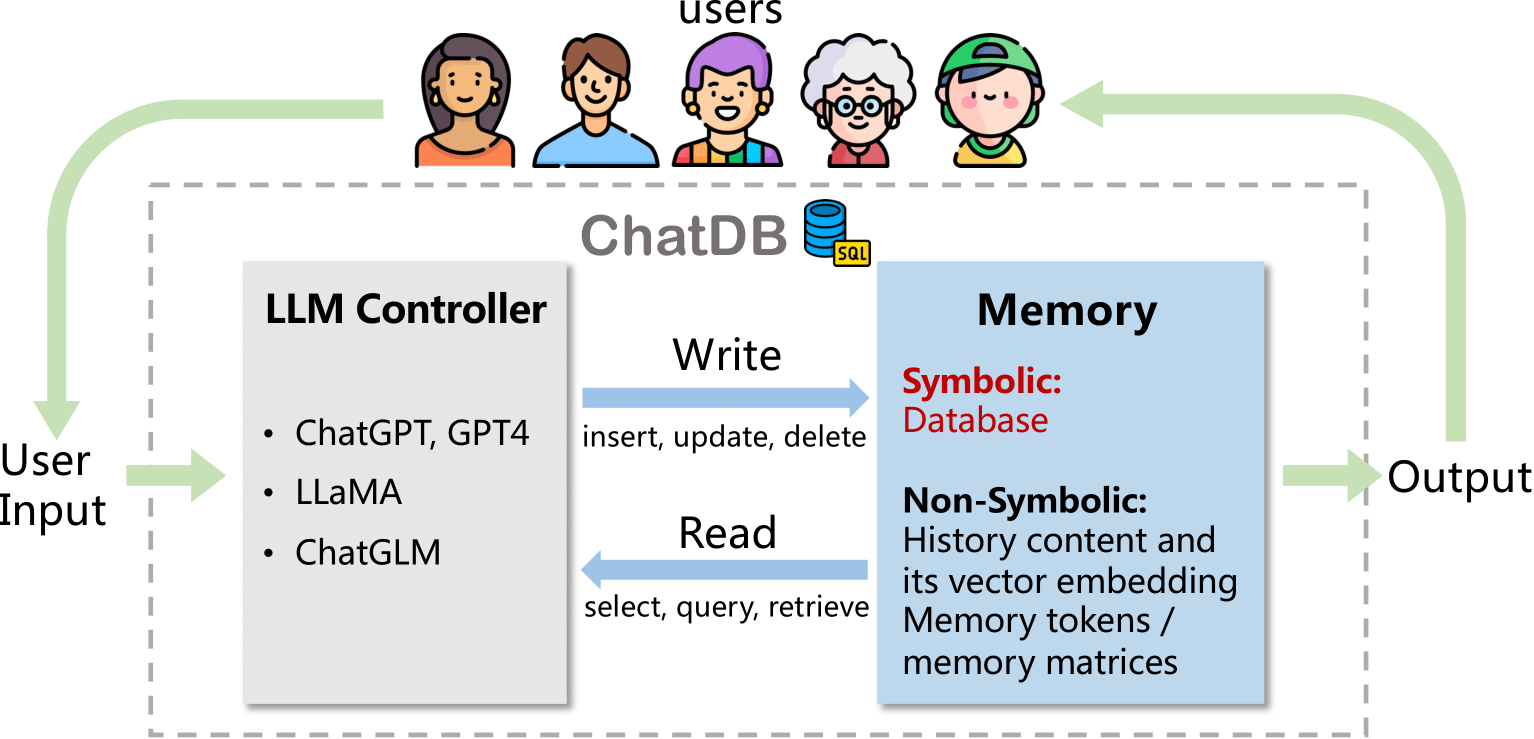
ChatDB: Augmenting LLMs with Databases as Their Symbolic Memory
This is the official repository of the paper: ChatDB: Augmenting LLMs with Databases as Their Symbolic Memory.
We will continuously add new features to this code repository. Please stay tuned!
Large language models (LLMs) with memory are computationally universal.
However, mainstream LLMs are not taking full advantage of memory, and the designs are heavily influenced by biological brains.
Due to their approximate nature and proneness to the accumulation of errors, conventional neural memory mechanisms cannot support LLMs to simulate complex reasoning.
In this paper, we seek inspiration from modern computer architectures to augment LLMs with symbolic memory for complex multi-hop reasoning.
Such a symbolic memory framework is instantiated as an LLM and a set of SQL databases, where the LLM generates SQL instructions to manipulate the SQL databases.
We validate the effectiveness of the proposed memory framework on a synthetic dataset requiring complex reasoning.
cp .env.template .env
# add OPENAI_API_KEY and MYSQL_PASSWORD
A minimal CLI demo in a fruit shop scenario
python chatdb.py
The CLI demo looks as follows.
Citation
If you find our work useful for your research, please consider citing the paper:
@misc{hu2023chatdb,
      title={ChatDB: Augmenting LLMs with Databases as Their Symbolic Memory},
      author={Chenxu Hu and Jie Fu and Chenzhuang Du and Simian Luo and Junbo Zhao and Hang Zhao},
      year={2023},
      eprint={2306.03901},
      archivePrefix={arXiv},
      primaryClass={cs.AI}
}