Code for "Audio-driven Talking Face Video Generation with Learning-based Personalized Head Pose" (Arxiv 2020) and "Predicting Personalized Head Movement From Short Video and Speech Signal" (TMM 2022).
[CVPR 2024] X-Adapter: Adding Universal Compatibility of Plugins for Upgraded Diffusion Model.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Language
Python
Category
Models
Subcategory
Audio/Speech models
Keywords
Audio production
Stars
777
Forks
46
Contributors
2
Created date
2024-02-20
Updated date
2026-10-14
Stars in 1 day
0
Stars in 7 days
1
Rank
13,935
Previous rank
6,439
Rank change
-7,496
7-day stars rank
10,712
Previous 7-day stars rank
10,768
7-day stars rank change
56
Total stars rank
13,672
Previous total stars rank
13,645
Total stars rank change
-27
Country
Poland
README summary
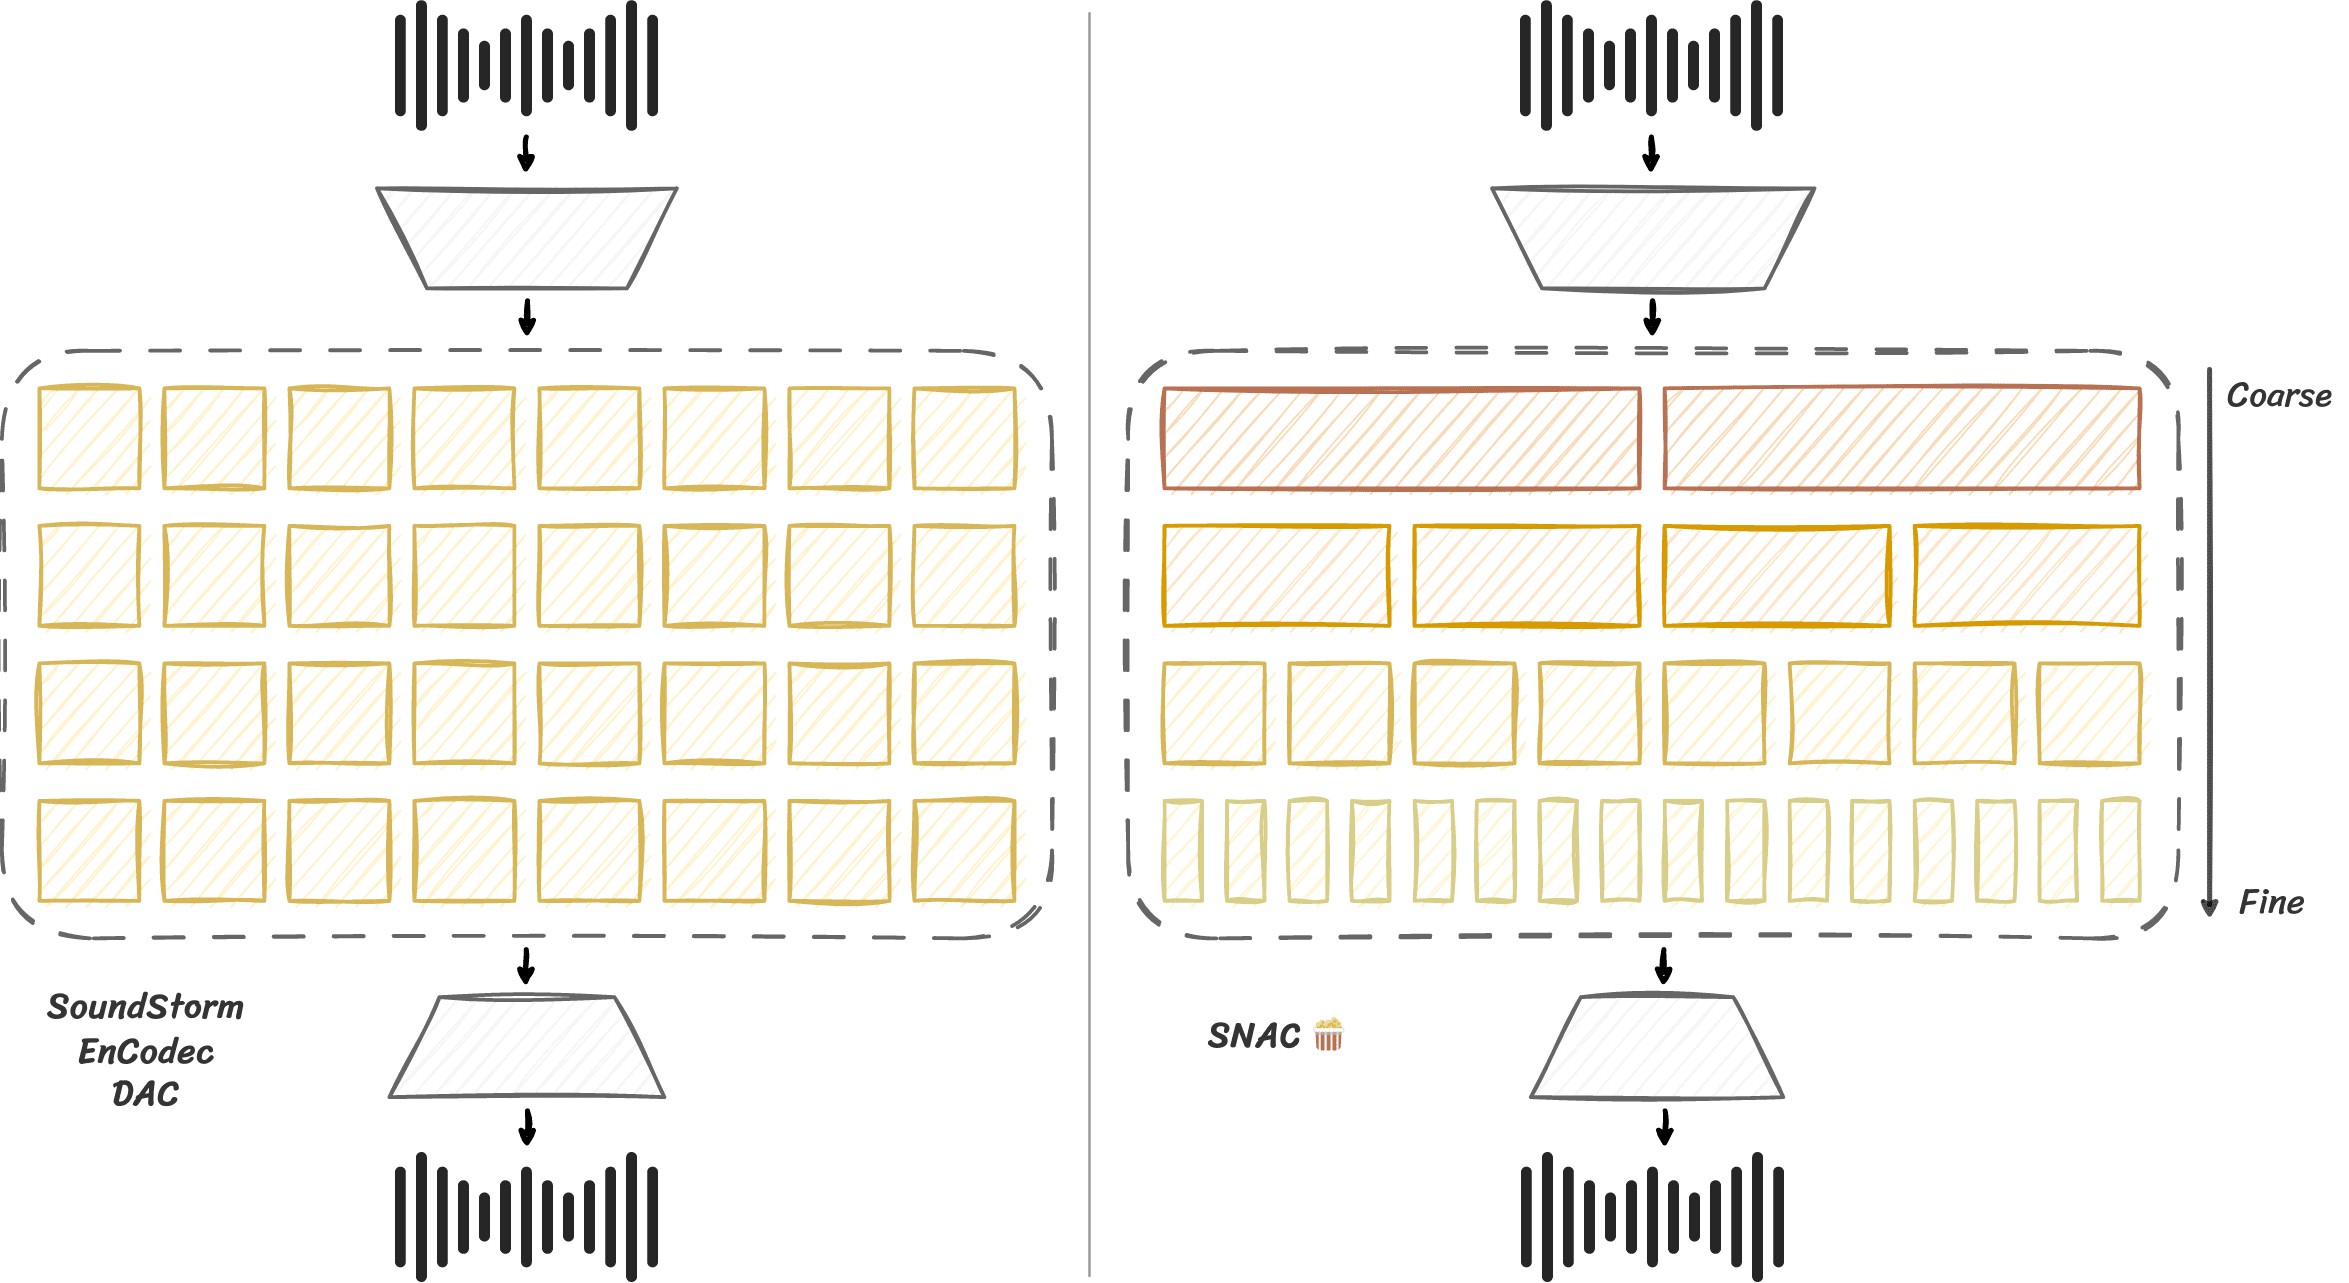
SNAC 🍿 Multi-**S**cale **N**eural **A**udio **C**odec (SNAC) compresses audio into discrete codes at a low bitrate. However, SNAC introduces a simple change where coarse tokens are sampled less frequently, covering a broader time span (see the image on the right). This can not only save on bitrate, but more importantly this might be very useful for language modeling approaches to audio generation. with coarse tokens of ~10 Hz and a context window of 2048 you can
effectively model a consistent structure of an audio track for ~3 minutes. Pretrained models Currently, all models support only single audio channel (mono). 8 M | 🗣️ Speech | | hubertsiuzdak/snac_32khz | 1. 5 M | 🎸 Music / Sound Effects | | hubertsiuzdak/snac_44khz | 2. 5 M | 🎸 Music / Sound Effects | Usage Install it using: To encode (and decode) audio with SNAC in Python, use the following code: You can also encode and reconstruct in a single call: ⚠️ Note that is a list of token sequences of
variable lengths, each corresponding to a different temporal resolution. Acknowledgements Module definitions are adapted from the Descript Audio Codec. Citation If this code contributes to your research, please cite our work:
Frequently asked questions
How many stars and forks are recorded?
hubertsiuzdak/snac has 777 stars and 46 forks.
What is the repository rank?
hubertsiuzdak/snac is ranked 13,935.
What language and category are recorded?
hubertsiuzdak/snac has 777 stars, uses Python and belongs to Models.
Which repository is closest in rank?
hubertsiuzdak/snac is compared with youngwanLEE/centermask2, ranked 13,928 with 778 stars.
README
SNAC 🍿
Multi-Scale Neural Audio Codec (SNAC) compresses audio into discrete codes at a low bitrate. For more information, read the paper: https://arxiv.org/abs/2410.14411
SNAC encodes audio into hierarchical tokens similarly to SoundStream, EnCodec, and DAC (see the image
on the left). However, SNAC introduces a simple change where coarse tokens are sampled less frequently,
covering a broader time span (see the image on the right).
This can not only save on bitrate, but more importantly this might be very useful for language modeling approaches to
audio generation. E.g. with coarse tokens of ~10 Hz and a context window of 2048 you can effectively model a
consistent structure of an audio track for ~3 minutes.
Pretrained models
Currently, all models support only single audio channel (mono).