MorphNet: Fast & Simple Resource-Constrained Learning of Deep Network Structure
[TOC]
New: FiGS: Fine-Grained Stochastic Architecture Search
FiGS, is a probabilistic approach to channel regularization that we introduced
in Fine-Grained Stochastic Architecture Search.
It outperforms our previous regularizers and can be used as either a pruning algorithm or
a full fledged Differentiable Architecture Search method. This is the recommended
way to apply MorphNet. In the below documentation it is
referred to as the LogisticSigmoid regularizer.
What is MorphNet?
MorphNet is a method for learning deep network structure during training. The key principle is continuous relaxation of the network-structure learning problem. In short, the MorphNet regularizer pushes the influence of filters down, and once they are small enough, the corresponding output channels are marked for removal from the network.
Specifically, activation sparsity is induced by adding regularizers that target the consumption of specific resources such as FLOPs or model size. When the regularizer loss is added to the training loss and their sum is minimized via stochastic gradient descent or a similar optimizer, the learning problem becomes a constrained optimization of the structure of the network, under the constraint represented by the regularizer. The method was first introduced in our CVPR 2018, paper "MorphNet: Fast & Simple Resource-Constrained Learning of Deep Network Structure". A overview of the approach as well as device-specific latency regularizers were prestend in GTC 2019. [slides, recording: YouTube, GTC on-demand]. Our new, probabilistic, approach to pruning is called FiGS, and is detailed in Fine-Grained Stochastic Architecture Search.
Usage
Suppose you have a working convolutional neural network for image classification but want to shrink the model to satisfy some constraints (e.g., memory, latency). Given an existing model (the “seed network”) and a target criterion, MorphNet will propose a new model by adjusting the number of output channels in each convolution layer.
Note that MorphNet does not change the topology of the network -- the proposed model will have the same number of layers and connectivity pattern as the seed network.
To use MorphNet, you must:
-
Choose a regularizer from
morphnet.network_regularizers. The choice is based on- your target cost (e.g., FLOPs, latency)
- Your ability to add new layers to your model:
- Add
our probabilistic gating operation after any layer you wish to prune, and
use the
LogisticSigmoidregularizers. [recommended] - If you are unable to add new layers, select regularizer type based on
your network architecture: use
Gammaregularizer if the seed network has BatchNorm; useGroupLassootherwise [deprecated].
- Add
our probabilistic gating operation after any layer you wish to prune, and
use the
Note: If you use BatchNorm, you must enable the scale parameters (“gamma variables”), i.e., by setting
scale=Trueif you are usingtf.keras.layers.BatchNormalization.Note: If you are using
LogisticSigmoiddon't forget to add the probabilistic gating op! See below for example. -
Initialize the regularizer with a threshold and the output boundary ops and (optionally) the input boundary ops of your model.
MorphNet regularizer crawls your graph starting from the output boundary, and applies regularization to some of the ops it encounters. When it encounters any of the input boundary ops, it does not crawl past them (the ops in the input boundary are not regularized). The threshold determines which output channels can be eliminated.
-
Add the regularization term to your loss.
As always, regularization loss must be scaled. We recommend to search for the scaling hyperparameter (regularization strength) along a logarithmic scale spanning a few orders of magnitude around
1/(initial cost). For example, if the seed network starts with 1e9 FLOPs, explore regularization strength around 1e-9.Note: MorphNet does not currently add the regularization loss to the tf.GraphKeys.REGULARIZATION_LOSSES collection; this choice is subject to revision.
Note: Do not confuse
get_regularization_term()(the loss you should add to your training) withget_cost()(the estimated cost of the network if the proposed structure is applied). -
Train the model.
Note: We recommend using a fixed learning rate (no decay) for this step, though this is not strictly necessary.
-
Save the proposed model structure with the
StructureExporter.The exported files are in JSON format. Note that as the training progresses, the proposed model structure will change. There are no specific guidelines on the stopping time, although you would likely want to wait for the regularization loss (reported via summaries) to stabilize.
-
(Optional) Create summary ops to monitor the training progress through TensorBoard.
-
Modify your model using the
StructureExporteroutput. -
Retrain the model from scratch without the MorphNet regularizer.
Note: Use the standard values for all hyperparameters (such as the learning rate schedule).
-
(Optional) Uniformly expand the network to adjust the accuracy vs. cost trade-off as desired. Alternatively, this step can be performed before the structure learning step.
We refer to the first round of training as structure learning and the second round as retraining.
To summarize, the key hyperparameters for MorphNet are:
- Regularization strength
- Alive threshold
Note that the regularizer type is not a hyperparameter because it's uniquely determined by the metric of interest (FLOPs, latency) and the presence of BatchNorm.
Regularizer Types
Regularizer classes can be found under network_regularizers/ directory. They
are named by the algorithm they use and the target cost they attempt to
minimize. For example, LogisticSigmoidFlopsRegularizer uses a
Logistic-Sigmoid probabilistic method to to regularize the FLOP cost
and GammaModelSizeRegularizer uses the batch norm gamma in
order to regularize the model size cost.
Regularizer Algorithms
- [NEW] LogisticSigmoid is designed to control any model type, but requires
adding simple
gating layersto your model. - GroupLasso is designed for models without batch norm.
- Gamma is designed for models with batch norm; it requires that batch norm scale is enabled.
Regularizer Target Costs
- Flops targets the FLOP count of the inference network.
- Model Size targets the number of weights of the network.
- Latency optimizes for the estimated inference latency of the network, based on the specific hardware characteristics.
Examples
Adding a FLOPs Regularizer
The example below demonstrates how to use MorphNet to reduce the number of FLOPs
in your model. In this example, the regularizer will traverse the graph
starting with logits, and will not go past any op that is earlier in the graph
than the inputs or labels; this allows to specify the subgraph for MorphNet to optimize.
from morph_net.network_regularizers import flop_regularizer
from morph_net.tools import structure_exporter

def build_model(inputs, labels, is_training, ...):
  gated_relu = activation_gating.gated_relu_activation()

  net = tf.layers.conv2d(inputs, kernel=[5, 5], num_outputs=256)
  net = gated_relu(net, is_training=is_training)

  ...
  ...

  net = tf.layers.conv2d(net, kernel=[3, 3], num_outputs=1024)
  net = gated_relu(net, is_training=is_training)

  logits = tf.reduce_mean(net, [1, 2])
  logits = tf.layers.dense(logits, units=1024)
  return logits

inputs, labels = preprocessor()
logits = build_model(inputs, labels, is_training=True, ...)

network_regularizer = flop_regularizer.LogisticSigmoidFlopsRegularizer(
    output_boundary=[logits.op],
    input_boundary=[inputs.op, labels.op],
    alive_threshold=0.1  # Value in [0, 1]. This default works well for most cases.
)
regularization_strength = 1e-10
regularizer_loss = (network_regularizer.get_regularization_term() * regularization_strength)

model_loss = tf.nn.sparse_softmax_cross_entropy_with_logits(labels, logits)

optimizer = tf.train.MomentumOptimizer(learning_rate=0.01, momentum=0.9)

train_op = optimizer.minimize(model_loss + regularizer_loss)
You should monitor the progress of structure learning training via Tensorboard. In particular, you should consider adding a summary that computes the current MorphNet regularization loss and the cost if the currently proposed structure is adopted.
tf.summary.scalar('RegularizationLoss', regularizer_loss)
tf.summary.scalar(network_regularizer.cost_name, network_regularizer.get_cost())
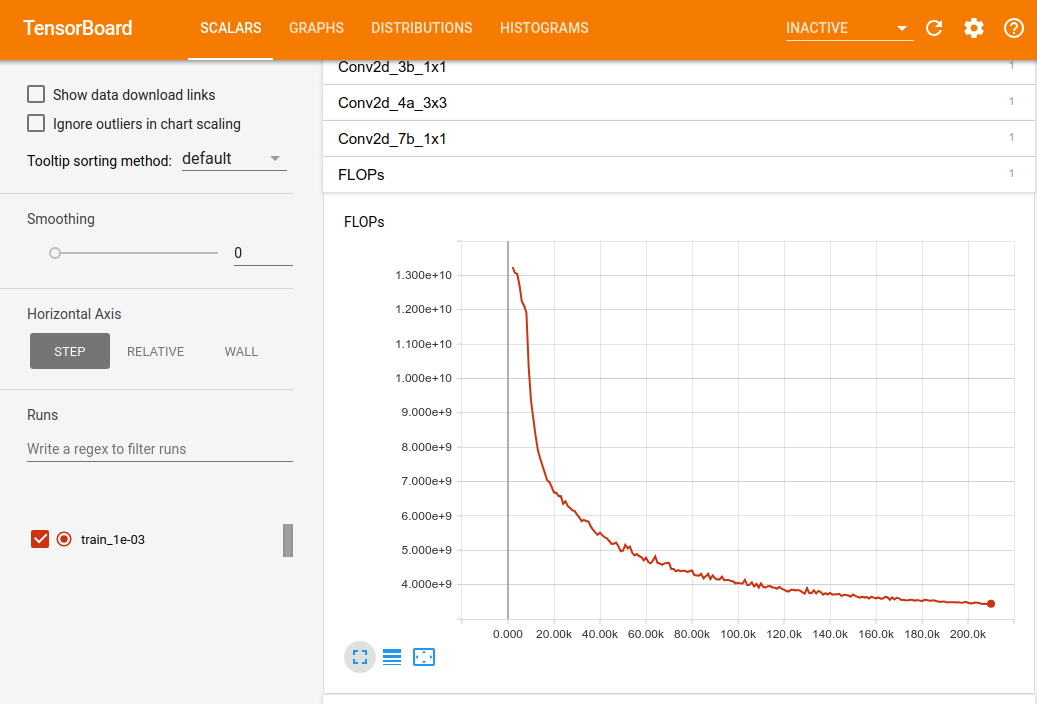
Larger values of regularization_strength will converge to smaller effective
FLOP count. If regularization_strength is large enough, the FLOP count will
collapse to zero. Conversely, if it is small enough, the FLOP count will remain
at its initial value and the network structure will not vary. The
regularization_strength parameter is your knob to control where you want to be
on the price-performance curve. The alive_threshold parameter is used for
determining when an activation is alive.
Extracting the Architecture Learned by MorphNet
During training, you should save a JSON file that contains the learned structure of the network, that is the count of activations in a given layer kept alive (as opposed to removed) by MorphNet.
exporter = structure_exporter.StructureExporter(
    network_regularizer.op_regularizer_manager)

with tf.Session() as sess:
  tf.global_variables_initializer().run()
  for step in range(max_steps):
    _, structure_exporter_tensors = sess.run([train_op, exporter.tensors])
    if (step % 1000 == 0):
      exporter.populate_tensor_values(structure_exporter_tensors)
      exporter.create_file_and_save_alive_counts(train_dir, step)
Misc
Contact: morphnet@google.com
Maintainers
- Elad Eban, github: eladeban
- Andrew Poon, github: ayp-google
- Yair Movshovitz-Attias, github: yairmov
- Max Moroz, github: pkch
Contributors
- Ariel Gordon, github: gariel-google.