← Open Source
getomni-ai

benchmark

OCR Benchmark.

AI EngineeringTest & guardTypeScript
Open on GitHub
Momentum
+0stars in 24 hours0.0%
639
Stars
57
Forks
+0
This week
0
Contributors
Created 2024-12-16 · Updated 2026-10-07 · #15691 today

getomni-ai/benchmark is ranked 15,691 with 639 stars.

Same-category comparison

getomni-ai/benchmark is ranked 15,691 among these 8 peers; evancohen/sonus is ranked 15,690.

Same-category comparison
NameRankMetrics
Fullive-AI/Anima15,669
Language:
Python
Stars:
640
Forks:
39
harsha-iiiv/openapi-mcp-generator15,676
Language:
TypeScript
Stars:
640
Forks:
86
Description:
A tool that converts OpenAPI specifications to MCP server.
eastreams/loong15,689
Language:
Rust
Stars:
639
Forks:
104
evancohen/sonus15,690
Language:
JavaScript
Stars:
639
Forks:
75
Description:
:speech_balloon: /so.nus/ STT (speech to text) for Node with offline hotword detection.
antfu/shiki-stream15,708
Language:
HTML
Stars:
638
Forks:
20
Description:
Streaming highlighting with Shiki. Useful for highlighting text streams like LLM outputs.
sandbaseai/sandbase-harness15,717
Language:
TypeScript
Stars:
638
Forks:
78
Description:
Local-first, self-hosted AI agent runtime and MCP bridge with sandboxed sessions, memory, credentials, audit/replay, and a local Console.
Cjbuilds/Codex-Orchestration15,721
Language:
Python
Stars:
637
Forks:
62
Description:
Bring any model to Codex, assign them any role, use them in /goal or any workflow.
HenryXiaoYang/wechat-openclaw-channel15,722
Language:
TypeScript
Stars:
637
Forks:
143
Key parameters and specifications
ParameterValue
LanguageTypeScript
CategoryAI Engineering
SubcategoryTest & guard
KeywordsDocument understanding, Evals, OCR, Unstructured data extraction
Stars639
Forks57
Contributors0
Created date2024-12-16
Updated date2026-10-07
Stars in 1 day0
Stars in 7 days0
Rank15,691
Previous rank15,497
Rank change-194
7-day stars rank15,130
Previous 7-day stars rank19,162
7-day stars rank change4,032
Total stars rank15,996
Previous total stars rank15,974
Total stars rank change-22
README summary

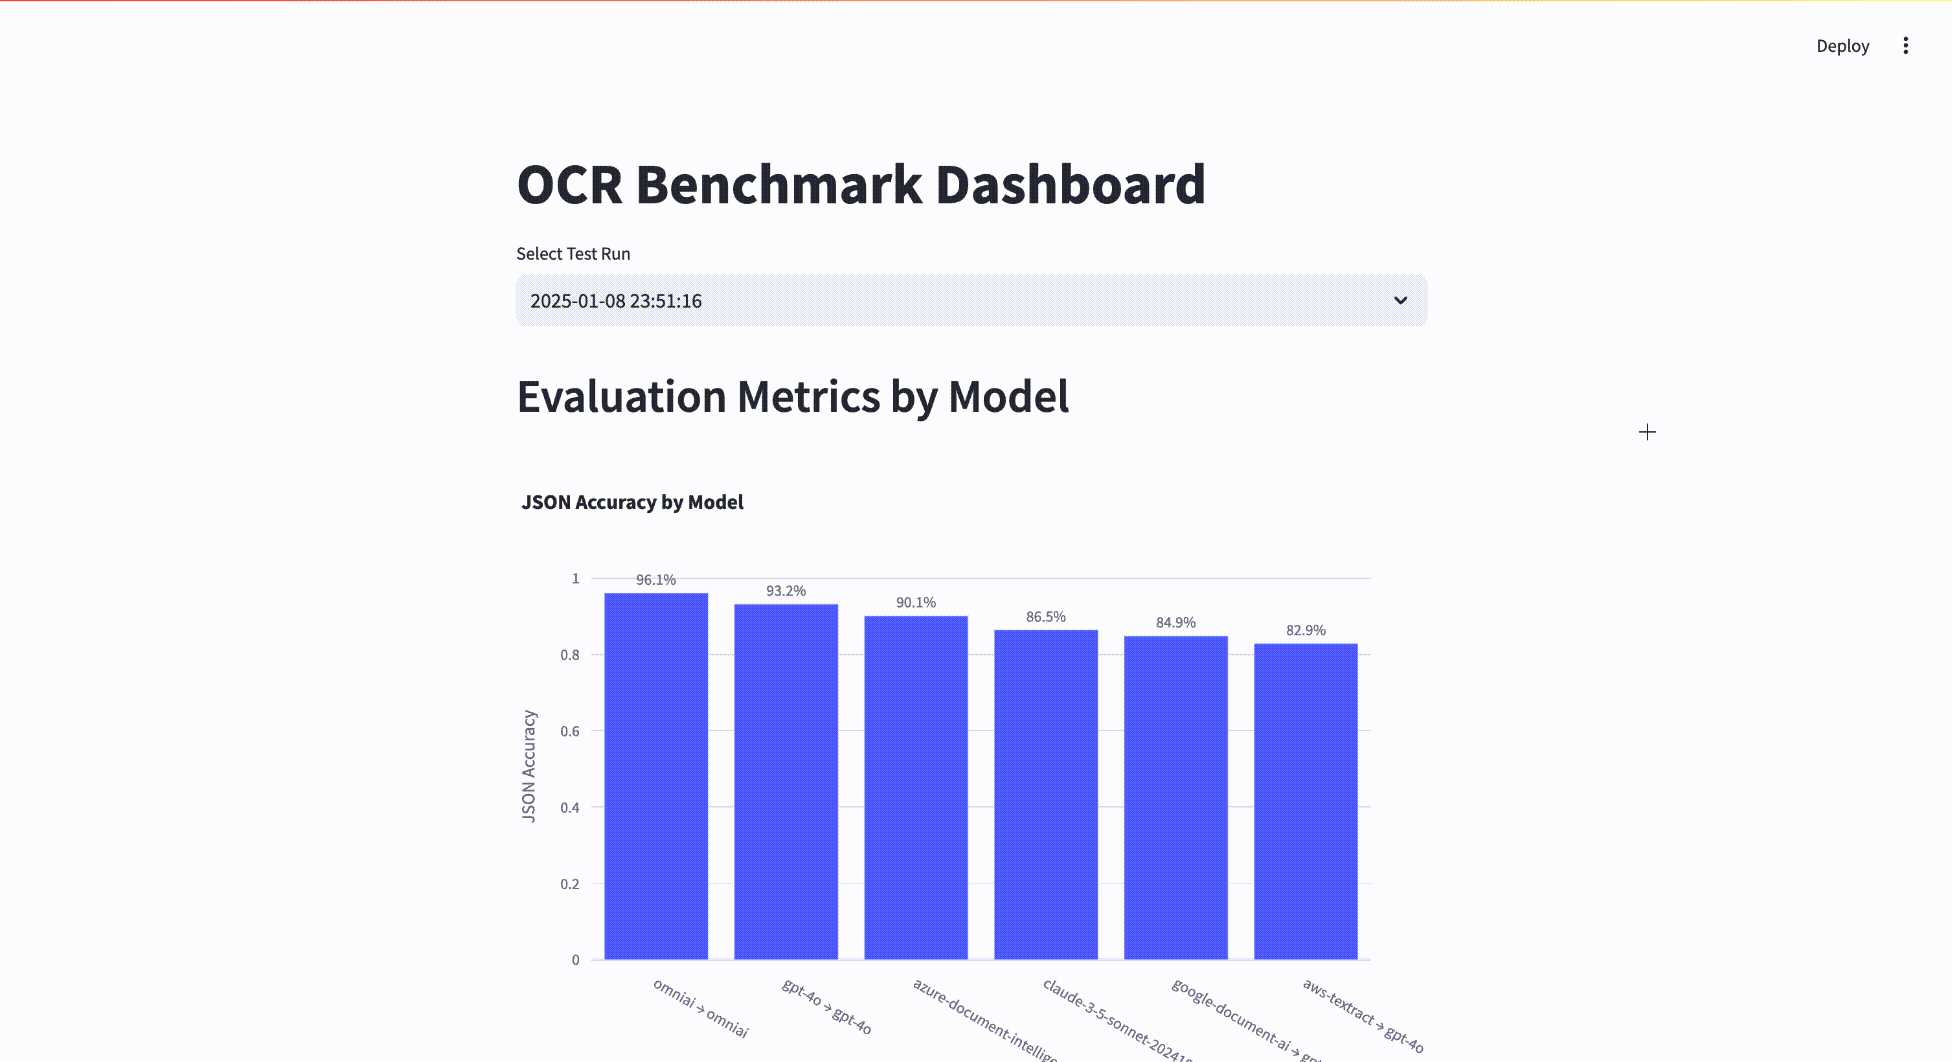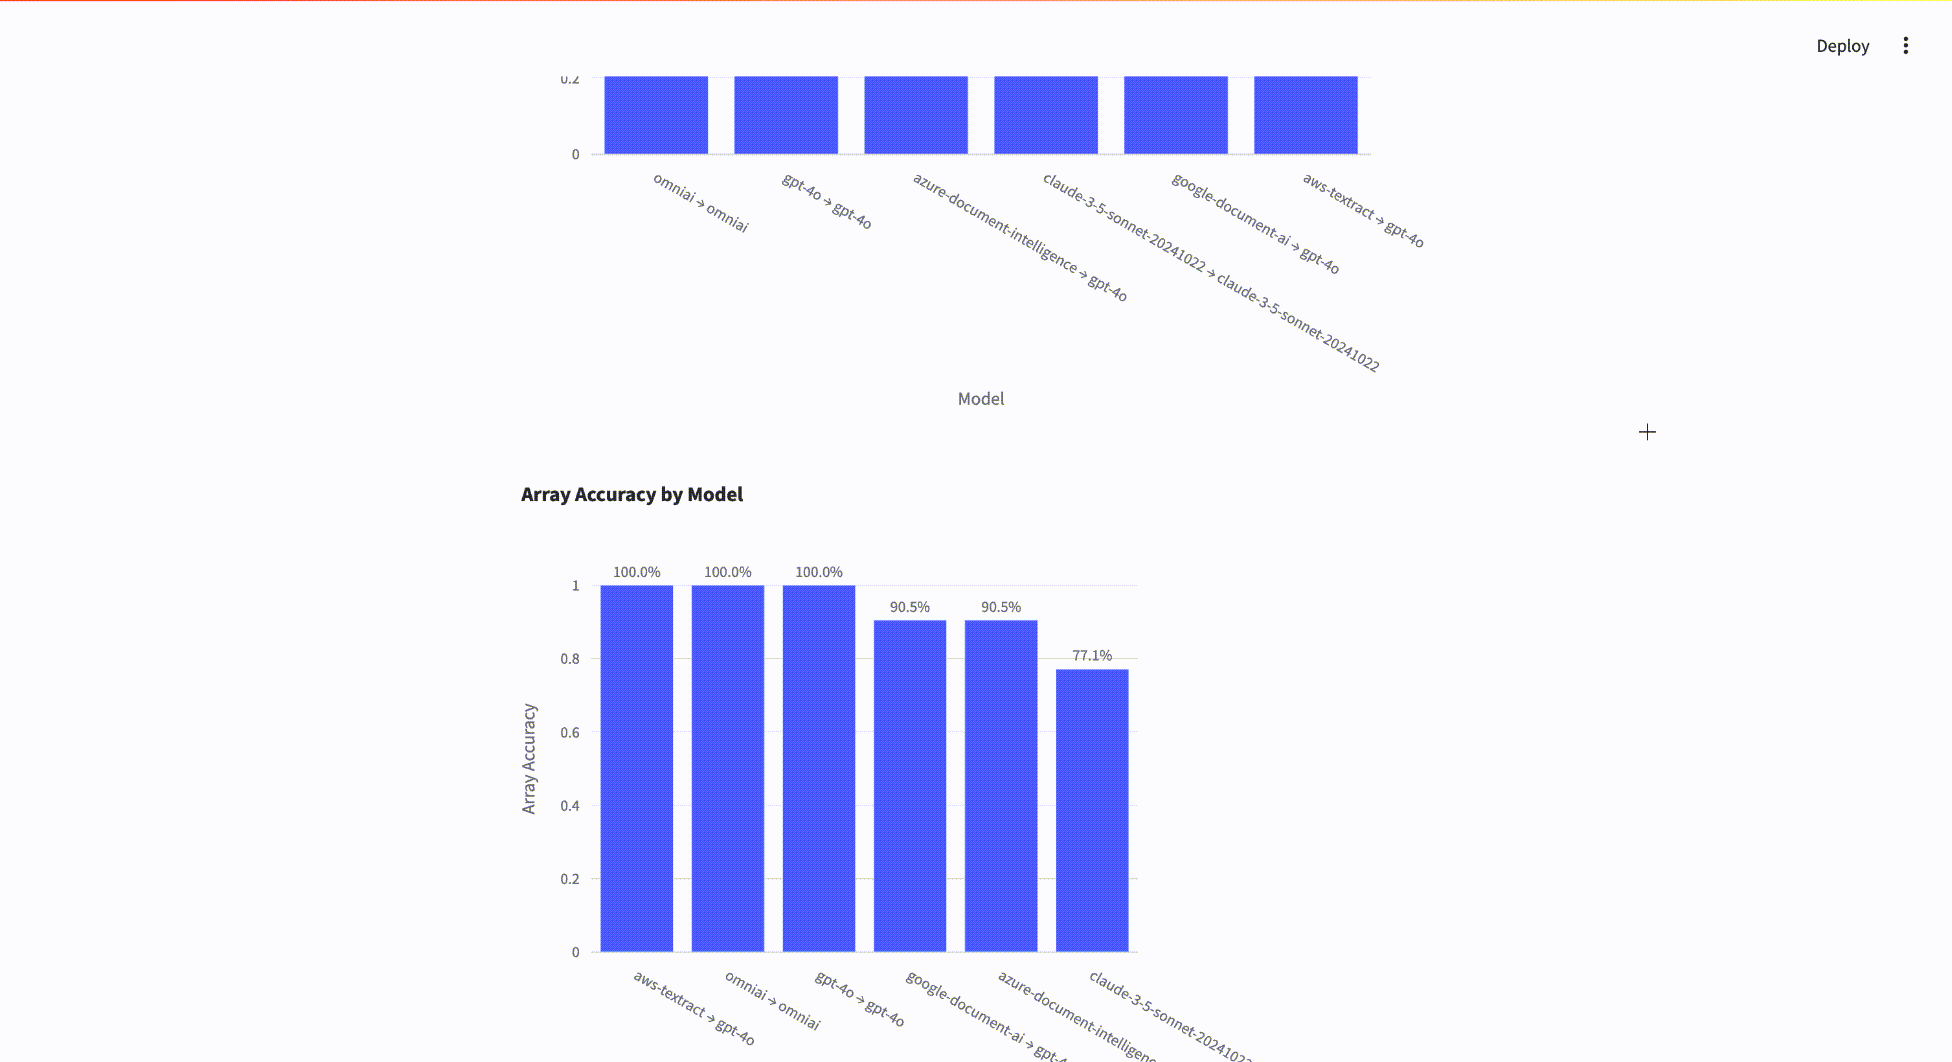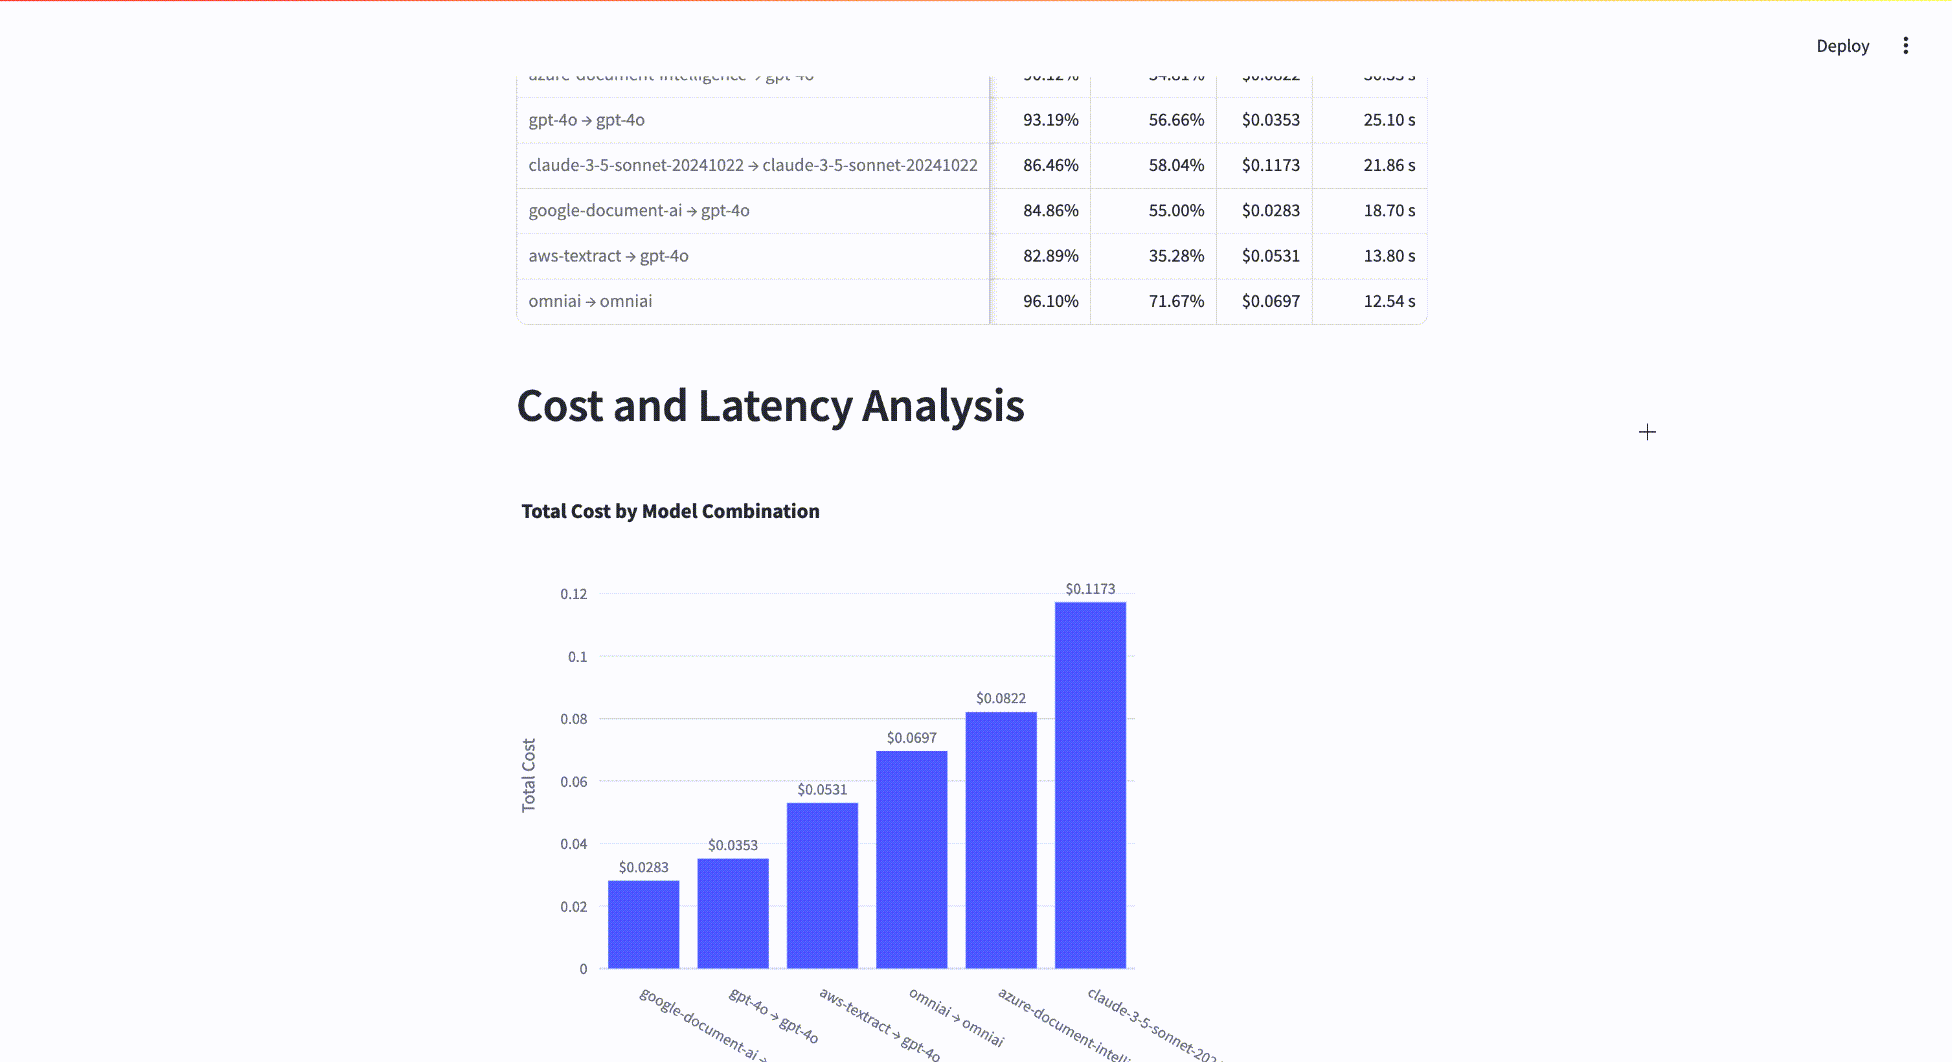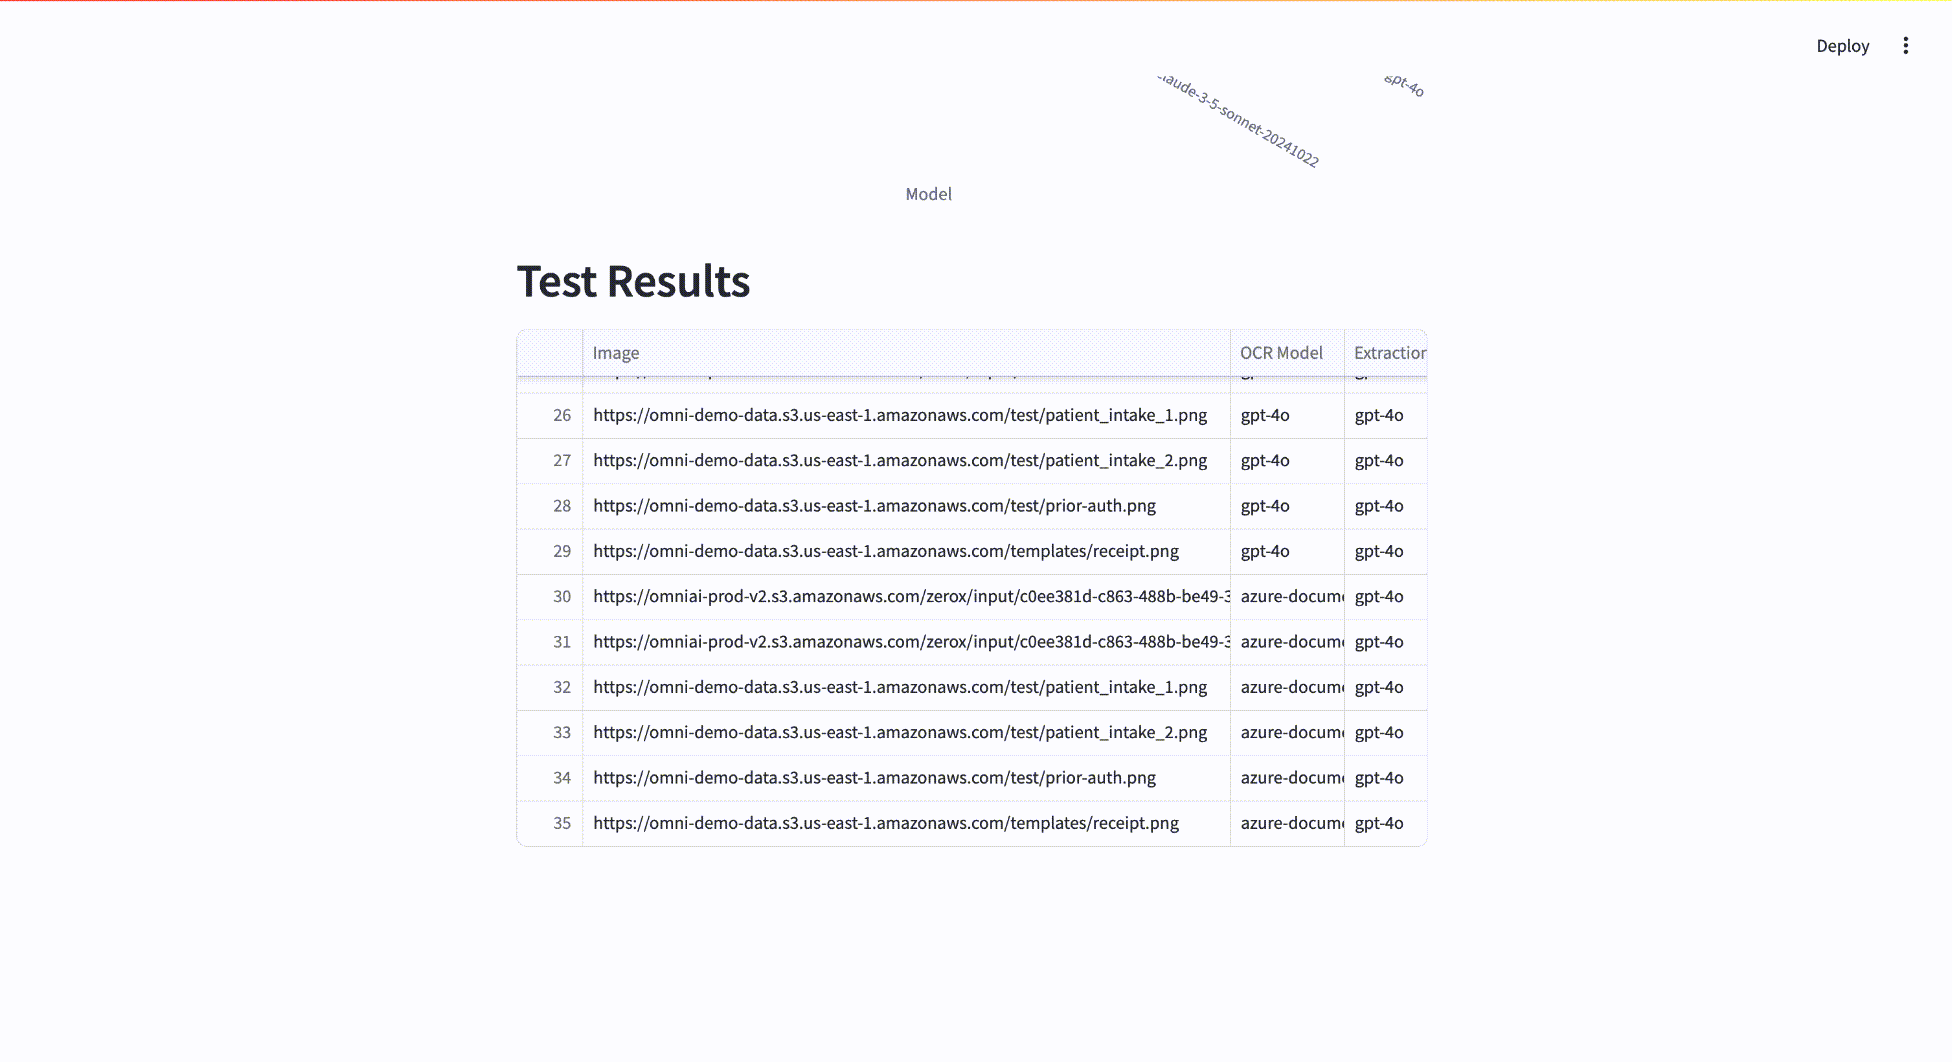
Omni OCR Benchmark A benchmarking tool that compares OCR and data extraction capabilities of different large multimodal models such as gpt-4o, evaluating both text and json extraction accuracy. The goal of this benchmark is to publish a comprehensive benchmark of OCRaccuracy across traditional OCR providers and multimodal Language Models. The evaluation dataset and methodologies are all Open Source, and we encourage expanding this benchmark to encompass any additional providers. **Open Source LLM Benchmark Results (Mar 2025)** | **Dataset** **Benchmark Results

(Feb 2025)** | **Dataset** Methodology The primary goal is to evaluate JSON extraction from documents. To evaluate this, the Omni benchmark runs Document ⇒ OCR ⇒ Extraction . Measuring how well a model can OCR a page, and return that content in a format that an LLM can parse. Evaluation Metrics JSON accuracy We use a modified json-diff to identify differences between predicted and ground truth JSON objects. ts file to see the exact implementation. Accuracy is calculated as: Text similarity While the

primary benchmark metric is JSON accuracy, we have included levenshtein distance as a measurement of text similarity between extracted and ground truth text. Lower distance indicates higher similarity. Note this scoring method heavily penalizes accurate text that does not conform to the exact layout of the ground truth data. In the example below, an LLM could decode both blocks of text without any issue. All the information is 100% accurate, but slight rearrangements of the header text (address, phone number

, etc. ) result in a large difference on edit distance scoring. Clone the repo and install dependencies: 2. For local data, add individual files to the folder. Set up API keys in for the models you want to test. Supported models To enable specific models, create a file in the directory. You can view configuration for each model in the src/models/ folder. For Google Document AI, you need to include in the folder. Benchmark Dashboard You can use benchmark dashboard

to easily view the results of each test run. Check out the dashboard documentation for more details. License This project is licensed under the MIT License - see the LICENSE file for details.

Frequently asked questions

How many stars and forks are recorded?

getomni-ai/benchmark has 639 stars and 57 forks.

What is the repository rank?

getomni-ai/benchmark is ranked 15,691.

What language and category are recorded?

getomni-ai/benchmark has 639 stars, uses TypeScript and belongs to AI Engineering.

Which repository is closest in rank?

getomni-ai/benchmark is compared with evancohen/sonus, ranked 15,690 with 639 stars.

README

Omni OCR Benchmark

A benchmarking tool that compares OCR and data extraction capabilities of different large multimodal models such as gpt-4o, evaluating both text and json extraction accuracy. The goal of this benchmark is to publish a comprehensive benchmark of OCRaccuracy across traditional OCR providers and multimodal Language Models. The evaluation dataset and methodologies are all Open Source, and we encourage expanding this benchmark to encompass any additional providers.

Open Source LLM Benchmark Results (Mar 2025) | Dataset

Benchmark Results (Feb 2025) | Dataset

Methodology

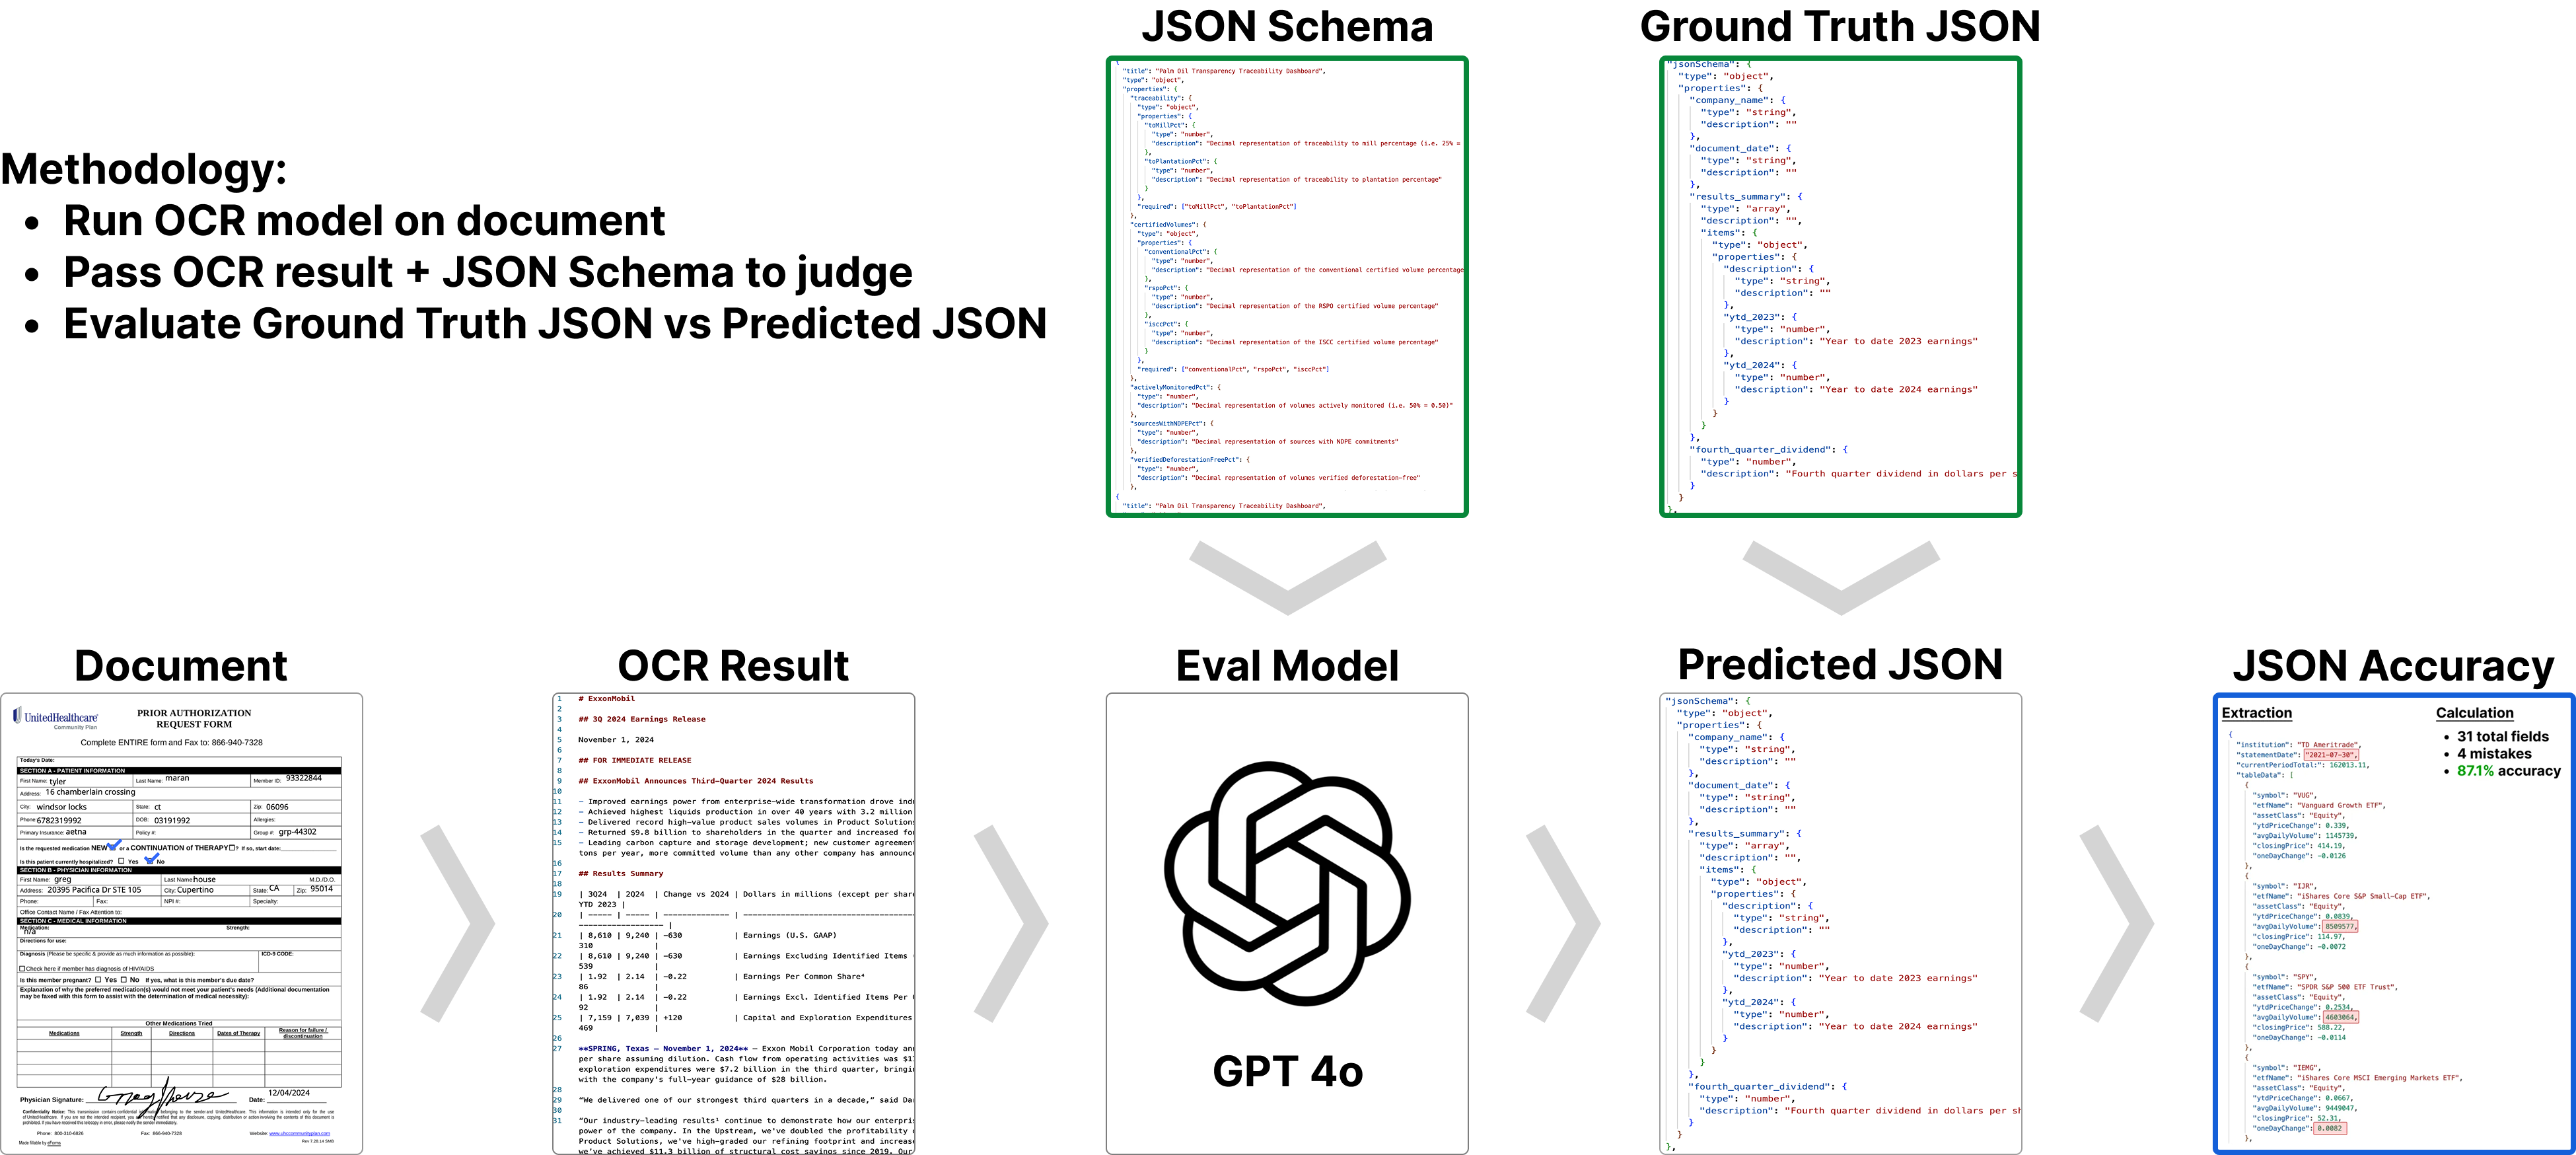
The primary goal is to evaluate JSON extraction from documents. To evaluate this, the Omni benchmark runs Document ⇒ OCR ⇒ Extraction. Measuring how well a model can OCR a page, and return that content in a format that an LLM can parse.
Evaluation Metrics

JSON accuracy

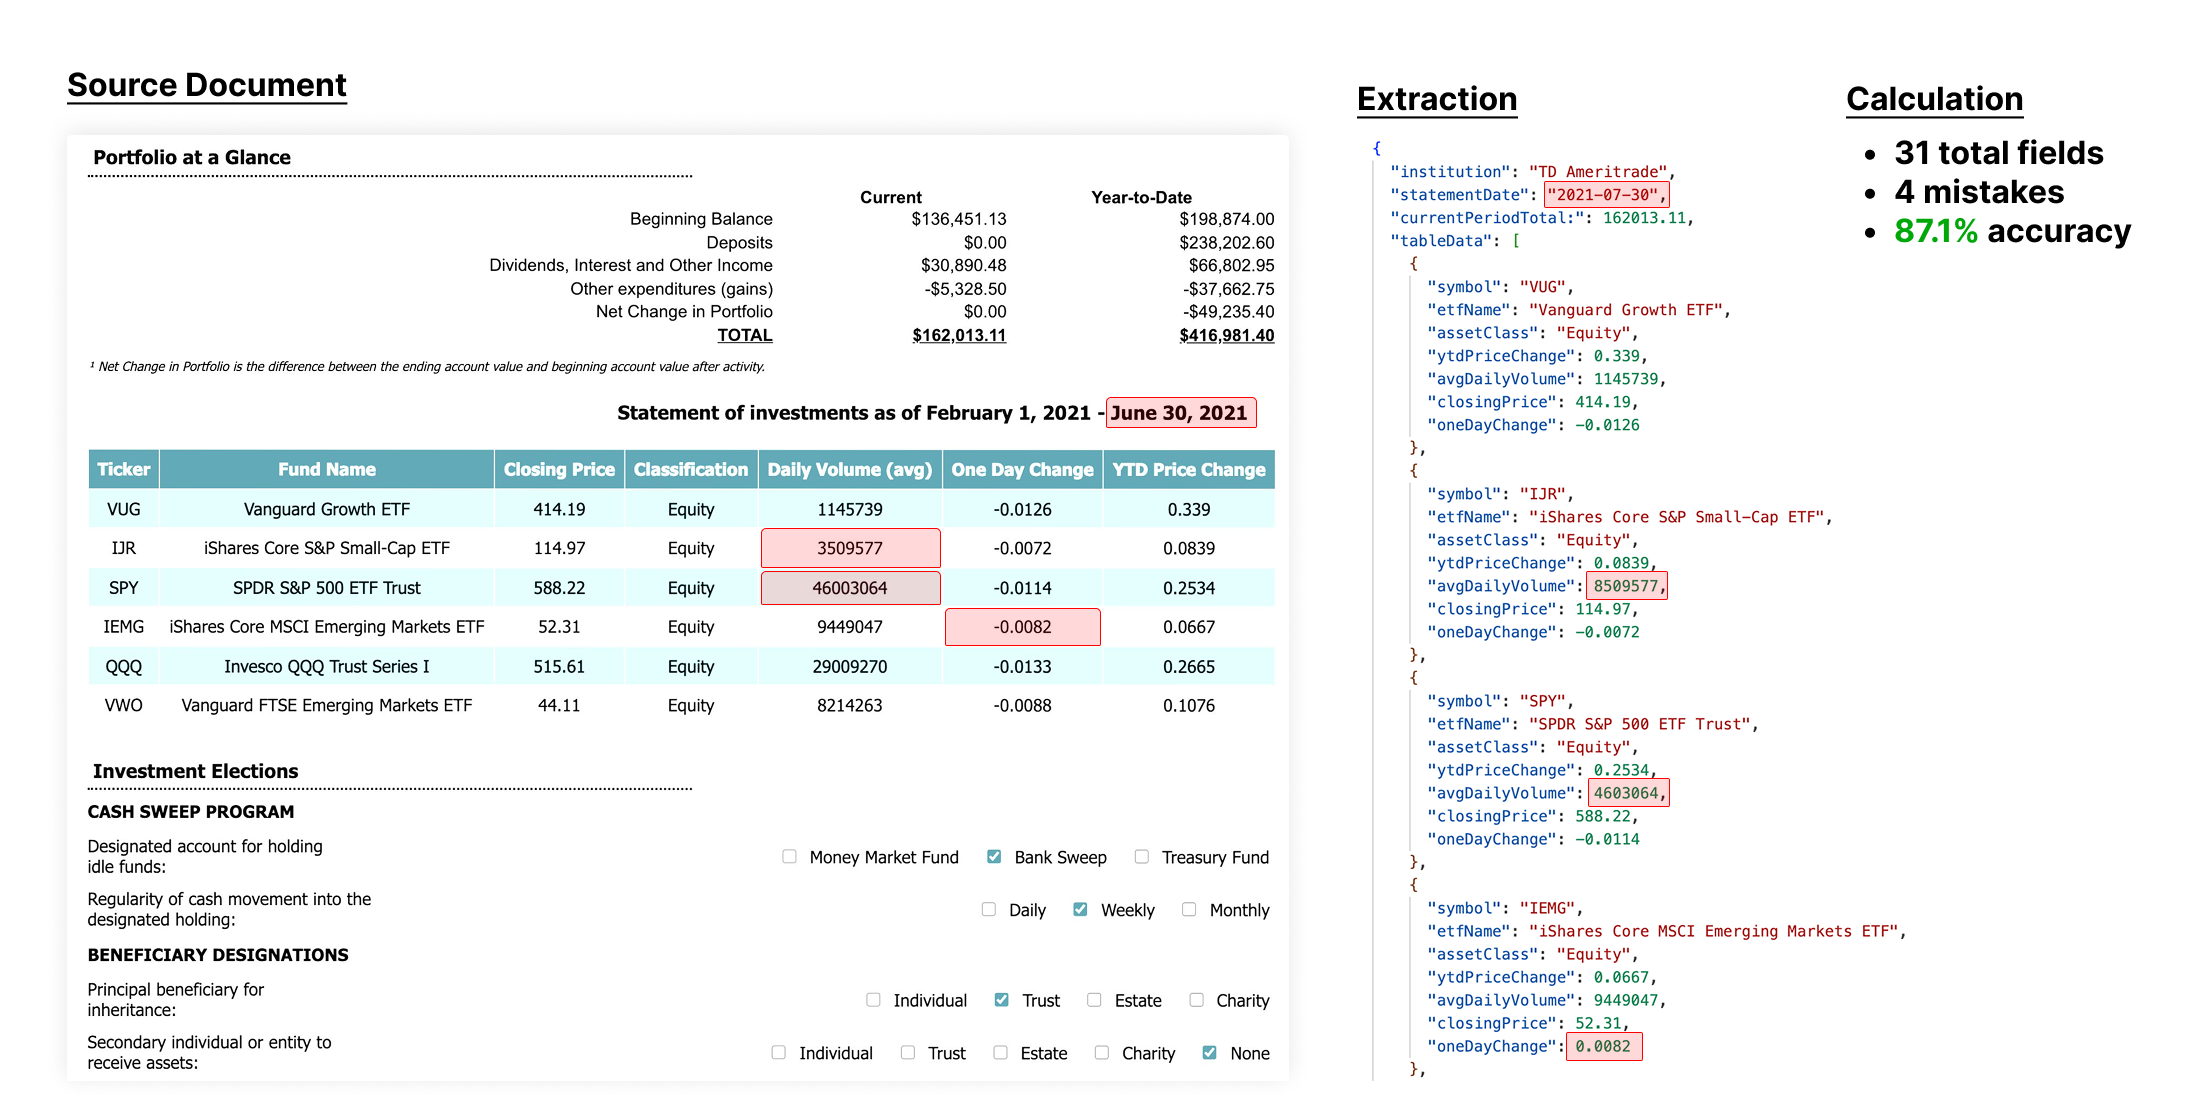
We use a modified json-diff to identify differences between predicted and ground truth JSON objects. You can review the evaluation/json.ts file to see the exact implementation. Accuracy is calculated as:

\text{Accuracy} = 1 - \frac{\text{number of difference fields}}{\text{total fields}}
Text similarity

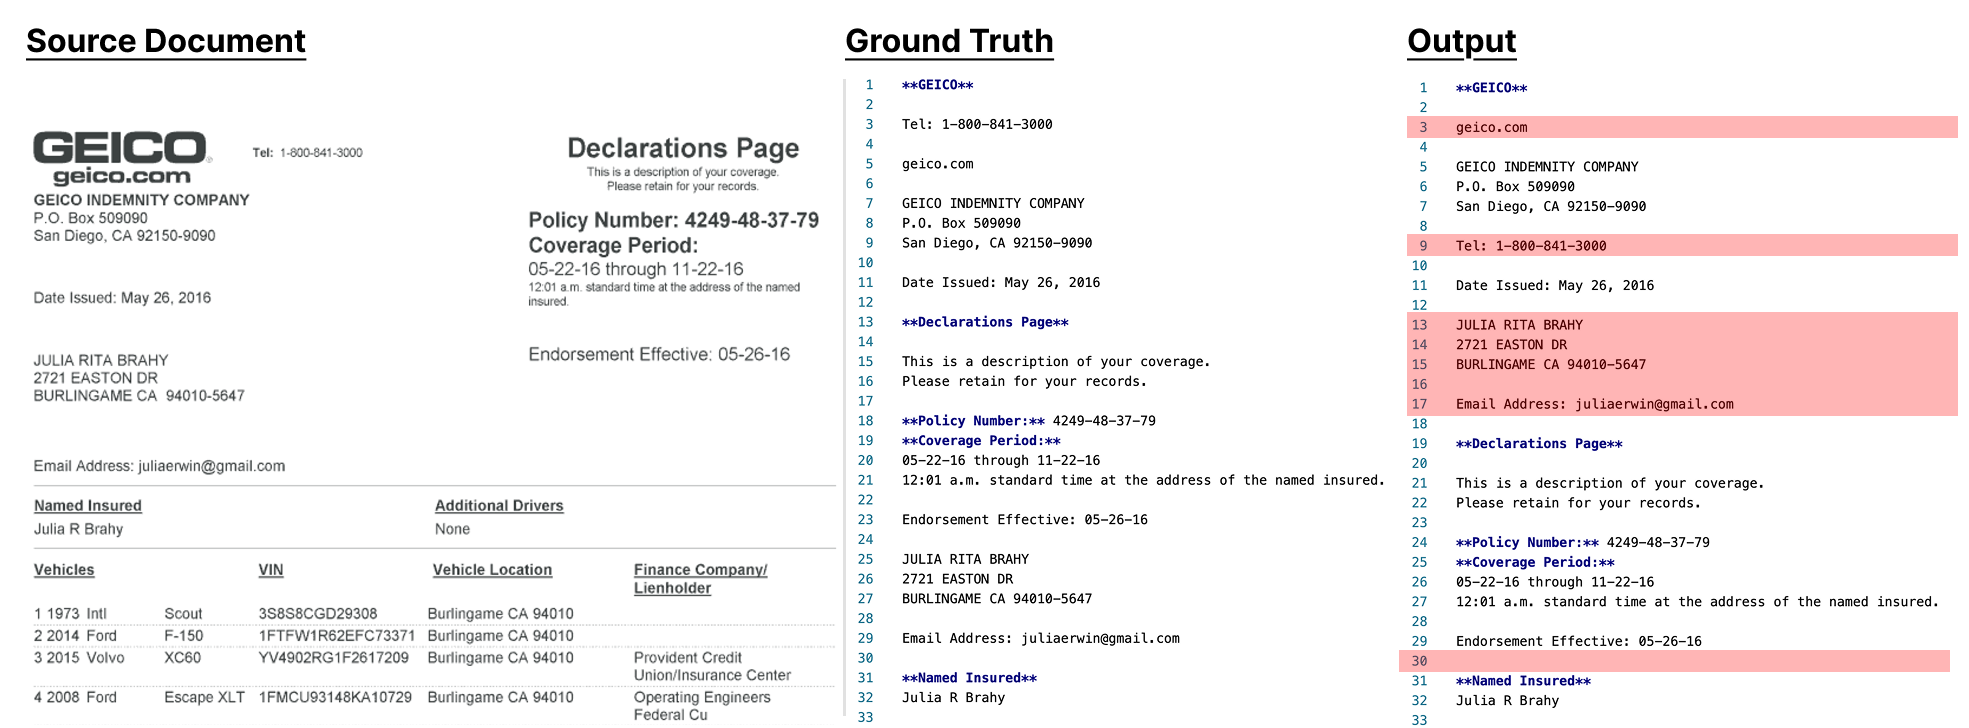
While the primary benchmark metric is JSON accuracy, we have included levenshtein distance as a measurement of text similarity between extracted and ground truth text. Lower distance indicates higher similarity. Note this scoring method heavily penalizes accurate text that does not conform to the exact layout of the ground truth data.

In the example below, an LLM could decode both blocks of text without any issue. All the information is 100% accurate, but slight rearrangements of the header text (address, phone number, etc.) result in a large difference on edit distance scoring.
Running the benchmark

  1. Clone the repo and install dependencies: npm install
  2. Prepare your test data
    1. For local data, add individual files to the data folder.
    2. To pull from a DB, add DATABASE_URL in your .env
  3. Copy the models.example.yaml file to models.yaml. Set up API keys in .env for the models you want to test. Check out the supported models here.
  4. Run the benchmark: npm run benchmark
  5. Results will be saved in the results//results.json file.

Supported models

To enable specific models, create a models.yaml file in the src directory. Check out the models.example.yaml file for the required variables.

models:
  - ocr: gemini-2.0-flash-001 # The model to use for OCR
    extraction: gpt-4o # The model to use for JSON extraction

  - ocr: gpt-4o
    extraction: gpt-4o
    directImageExtraction: true # Whether to use the model's native image extraction capabilities

You can view configuration for each model in the src/models/ folder.

Closed-source LLMs

Model Provider Models OCR JSON Extraction Required ENV Variables
Anthropic claude-3-5-sonnet-20241022 ✅ ✅ ANTHROPIC_API_KEY
OpenAI gpt-4o ✅ ✅ OPENAI_API_KEY
Gemini gemini-2.0-flash-001, gemini-1.5-pro, gemini-1.5-flash ✅ ✅ GOOGLE_GENERATIVE_AI_API_KEY
Mistral mistral-ocr ✅ ❌ MISTRAL_API_KEY
OmniAI omniai ✅ ✅ OMNIAI_API_KEY, OMNIAI_API_URL

Open-source LLMs

Model Provider Models OCR JSON Extraction Required ENV Variables
Gemma 3 google/gemma-3-27b-it ✅ ❌
Qwen 2.5 qwen2.5-vl-32b-instruct, qwen2.5-vl-72b-instruct ✅ ❌
Llama 3.2 meta-llama/Llama-3.2-11B-Vision-Instruct-Turbo, meta-llama/Llama-3.2-90B-Vision-Instruct-Turbo ✅ ❌
ZeroX zerox ✅ ✅ OPENAI_API_KEY

Cloud OCR Providers

Model Provider Models OCR JSON Extraction Required ENV Variables
AWS aws-text-extract ✅ ❌ AWS_ACCESS_KEY_ID, AWS_SECRET_ACCESS_KEY, AWS_REGION
Azure azure-document-intelligence ✅ ❌ AZURE_DOCUMENT_INTELLIGENCE_ENDPOINT, AZURE_DOCUMENT_INTELLIGENCE_KEY
Google google-document-ai ✅ ❌ GOOGLE_LOCATION, GOOGLE_PROJECT_ID, GOOGLE_PROCESSOR_ID, GOOGLE_APPLICATION_CREDENTIALS_PATH
Unstructured unstructured ✅ ❌ UNSTRUCTURED_API_KEY
  • LLMS are instructed to use the following system prompts for OCR and JSON extraction.
  • For Google Document AI, you need to include google_credentials.json in the data folder.

Benchmark Dashboard

You can use benchmark dashboard to easily view the results of each test run. Check out the dashboard documentation for more details.

License

This project is licensed under the MIT License - see the LICENSE file for details.

Nearby in the ranking
Similar items