Monocular, One-stage, Regression of Multiple 3D People and their 3D positions & trajectories in camera & global coordinates. ROMP[ICCV21], BEV[CVPR22], TRACE[CVPR2023].
Step-Audio 2 is an end-to-end multi-modal large language model designed for industry-strength audio understanding and speech conversation.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Language
Python
Category
Models
Subcategory
Vision models
Stars
1,537
Forks
228
Contributors
2
Created date
2021-03-25
Updated date
2026-10-09
Stars in 1 day
0
Stars in 7 days
-1
Rank
10,060
Previous rank
10,082
Rank change
22
7-day stars rank
17,108
Previous 7-day stars rank
17,103
7-day stars rank change
-5
Total stars rank
7,935
Previous total stars rank
7,928
Total stars rank change
-7
Country
South Korea
README summary
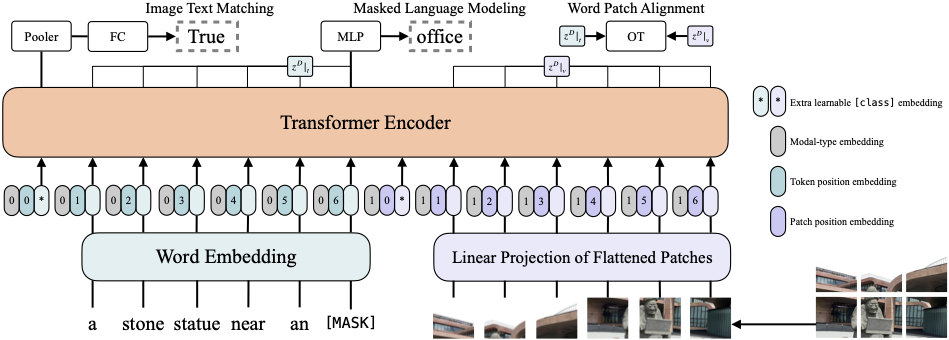
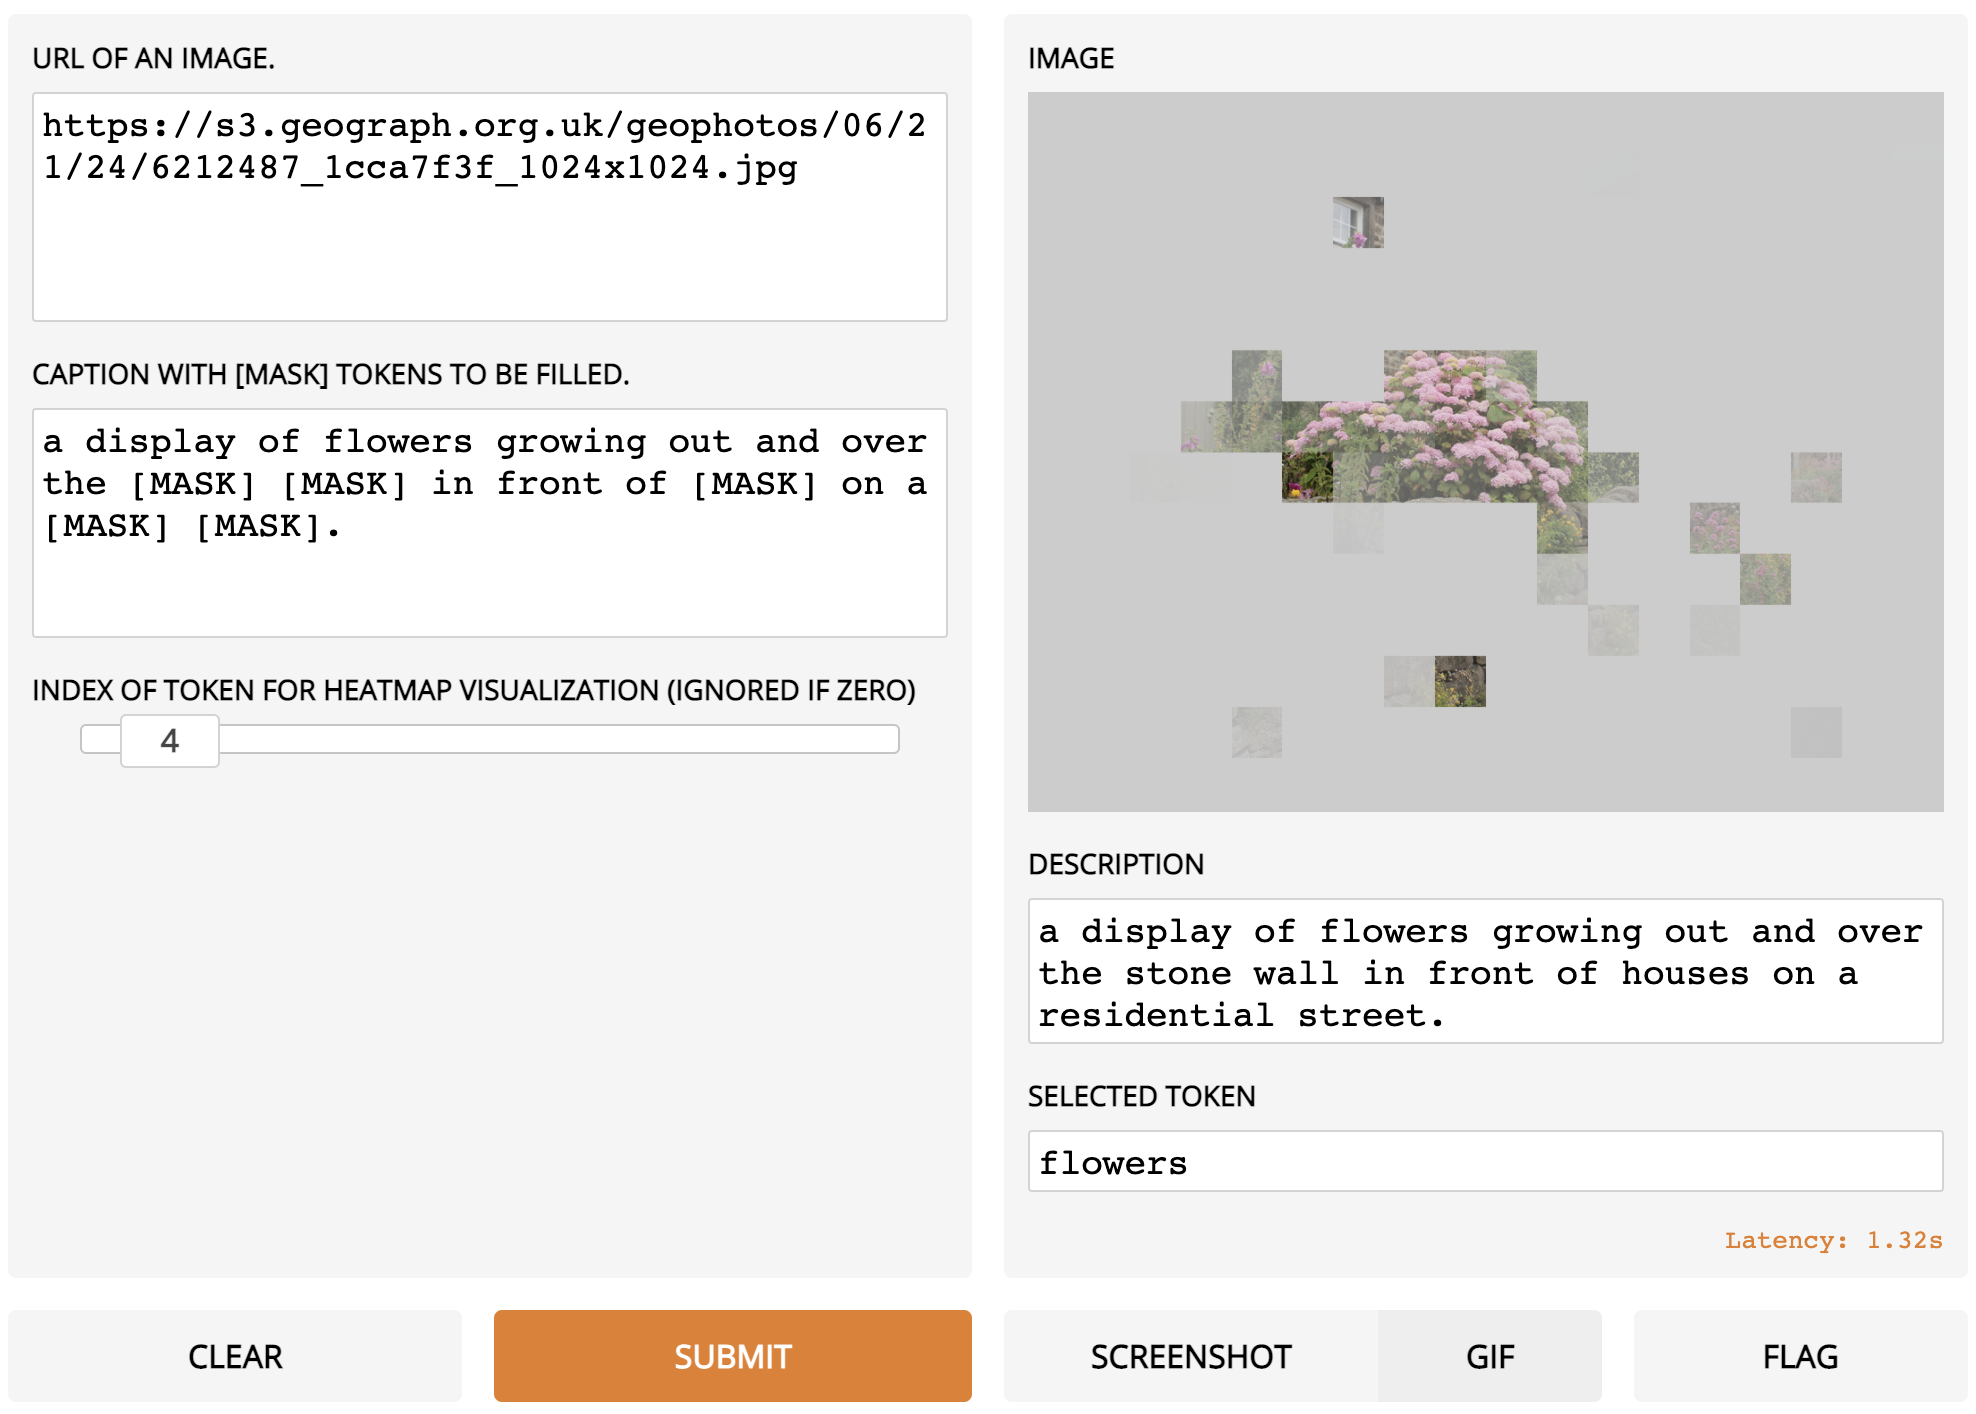
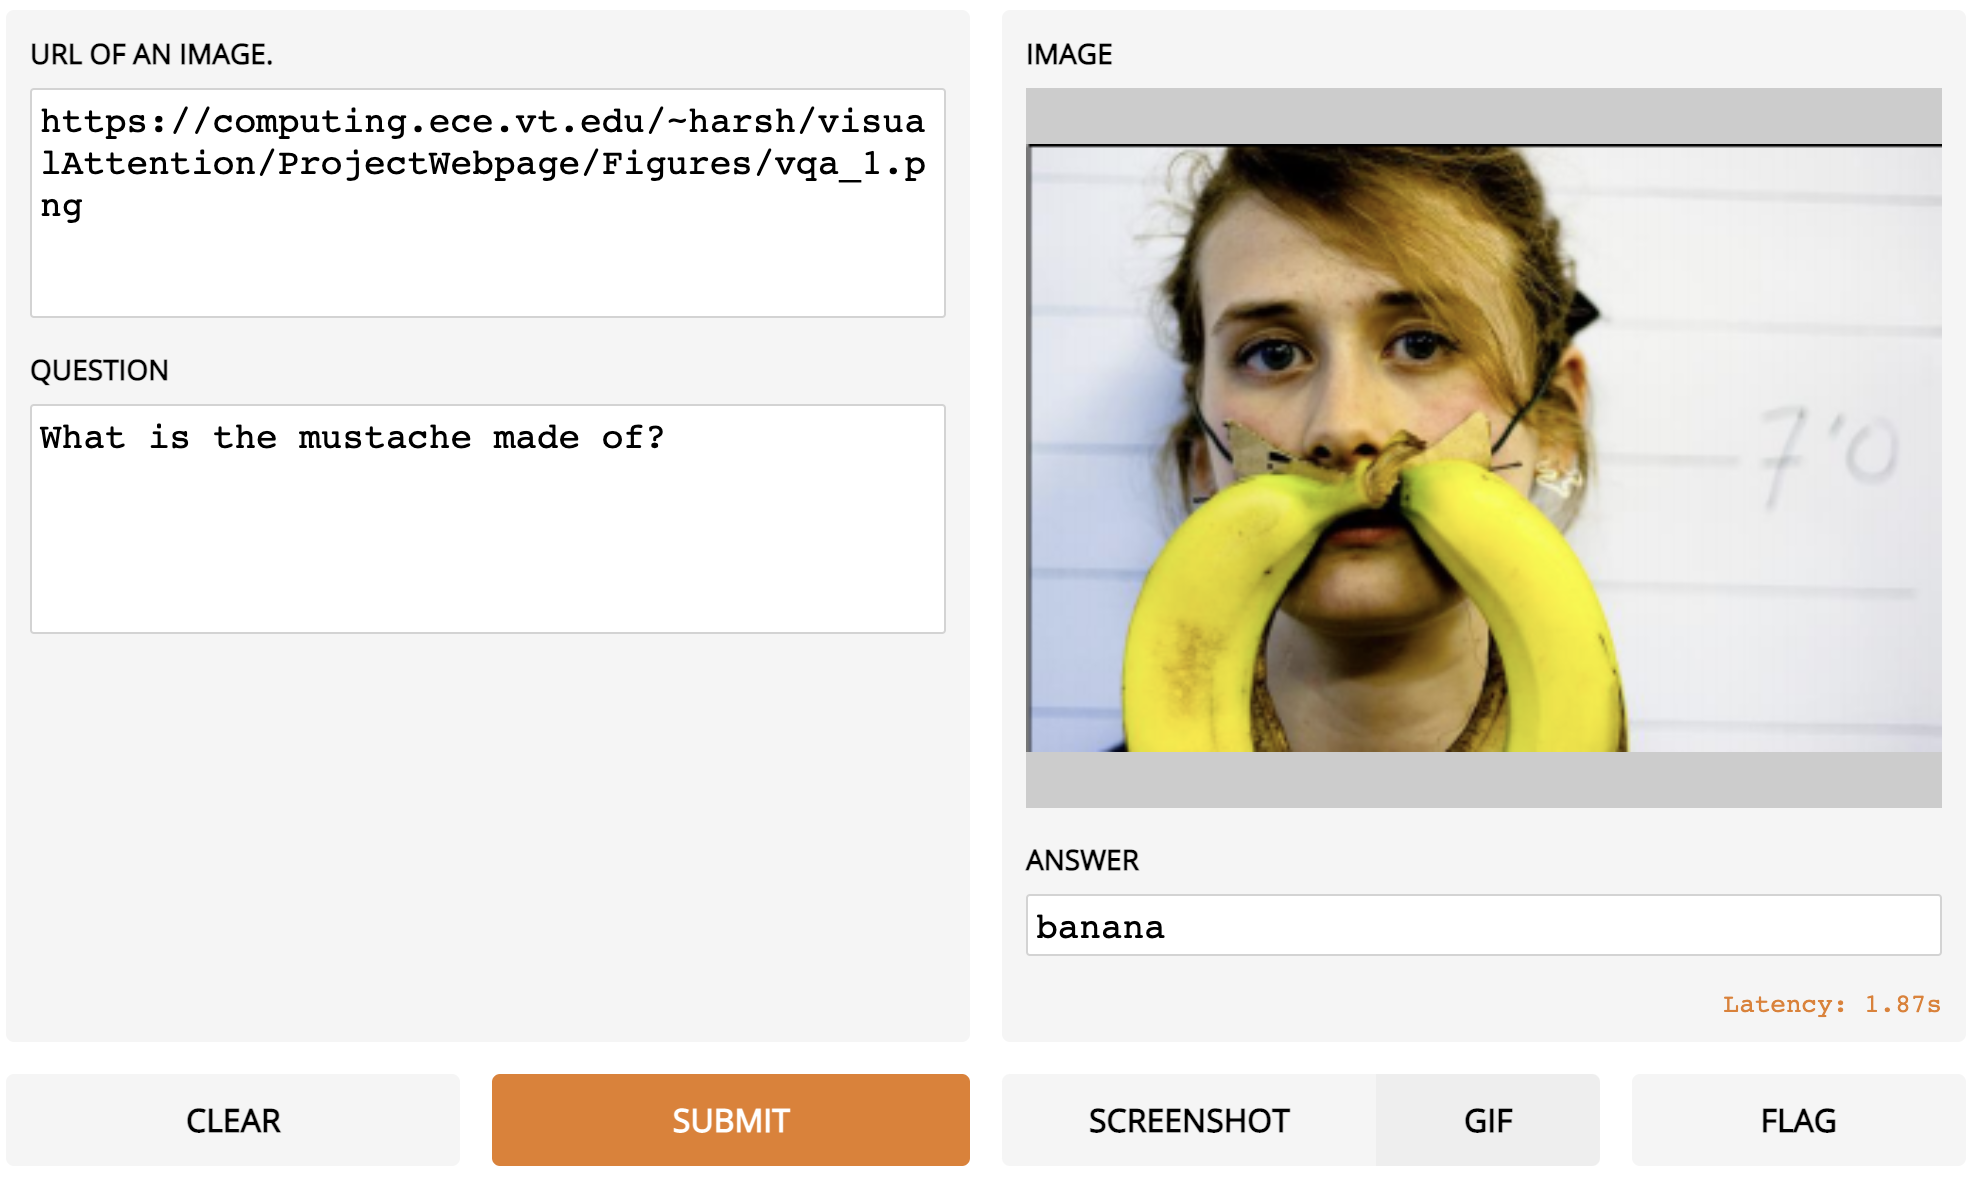
ViLT-B/32 Pretrained with MLM+ITM for 200k steps on GCC+SBU+COCO+VG (ViLT-B/32 200k) link 2. ViLT-B/32 200k finetuned on VQAv2 link 3. ViLT-B/32 200k finetuned on NLVR2 link 4. ViLT-B/32 200k finetuned on COCO IR/TR link 5. ViLT-B/32 200k finetuned on F30K IR/TR link Out-of-the-box MLM + Visualization Demo Out-of-the-box VQA Demo Dataset Preparation See Train New Models See
Evaluation See Citation If you use any part of this code and pretrained weights for your own purpose, please cite our paper. Contact for Issues Wonjae Kim Bokyung Son Ildoo Kim
Frequently asked questions
How many stars and forks are recorded?
dandelin/ViLT has 1,537 stars and 228 forks.
What is the repository rank?
dandelin/ViLT is ranked 10,060.
What language and category are recorded?
dandelin/ViLT has 1,537 stars, uses Python and belongs to Models.
Which repository is closest in rank?
dandelin/ViLT is compared with google-research/big_transfer, ranked 10,051 with 1,541 stars.
pip install gradio==1.6.4
python demo.py with num_gpus=<0 if you have no gpus else 1> load_path="/vilt_200k_mlm_itm.ckpt"

ex)
python demo.py with num_gpus=0 load_path="weights/vilt_200k_mlm_itm.ckpt"
Out-of-the-box VQA Demo
pip install gradio==1.6.4
python demo_vqa.py with num_gpus=<0 if you have no gpus else 1> load_path="/vilt_vqa.ckpt" test_only=True

ex)
python demo_vqa.py with num_gpus=0 load_path="weights/vilt_vqa.ckpt" test_only=True
If you use any part of this code and pretrained weights for your own purpose, please cite our paper.
@InProceedings{pmlr-v139-kim21k,
  title = 	 {ViLT: Vision-and-Language Transformer Without Convolution or Region Supervision},
  author =       {Kim, Wonjae and Son, Bokyung and Kim, Ildoo},
  booktitle = 	 {Proceedings of the 38th International Conference on Machine Learning},
  pages = 	 {5583--5594},
  year = 	 {2021},
  editor = 	 {Meila, Marina and Zhang, Tong},
  volume = 	 {139},
  series = 	 {Proceedings of Machine Learning Research},
  month = 	 {18--24 Jul},
  publisher =    {PMLR},
  pdf = 	 {http://proceedings.mlr.press/v139/kim21k/kim21k.pdf},
  url = 	 {http://proceedings.mlr.press/v139/kim21k.html},
  abstract = 	 {Vision-and-Language Pre-training (VLP) has improved performance on various joint vision-and-language downstream tasks. Current approaches to VLP heavily rely on image feature extraction processes, most of which involve region supervision (e.g., object detection) and the convolutional architecture (e.g., ResNet). Although disregarded in the literature, we find it problematic in terms of both (1) efficiency/speed, that simply extracting input features requires much more computation than the multimodal interaction steps; and (2) expressive power, as it is upper bounded to the expressive power of the visual embedder and its predefined visual vocabulary. In this paper, we present a minimal VLP model, Vision-and-Language Transformer (ViLT), monolithic in the sense that the processing of visual inputs is drastically simplified to just the same convolution-free manner that we process textual inputs. We show that ViLT is up to tens of times faster than previous VLP models, yet with competitive or better downstream task performance. Our code and pre-trained weights are available at https://github.com/dandelin/vilt.}
}