← Open Source
chinhsuanwu

mobilevit-pytorch

A PyTorch implementation of "MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer".

ModelsVision modelsPython
Open on GitHub
Momentum
+0stars in 24 hours0.0%
580
Stars
74
Forks
+0
This week
1
Contributors
Created 2021-10-07 · Updated 2026-09-29 · #16643 today
Top developers
chinhsuanwu

chinhsuanwu/mobilevit-pytorch is ranked 16,643 with 580 stars.

Same-category comparison

chinhsuanwu/mobilevit-pytorch is ranked 16,643 among these 8 peers; Doby-Xu/WithAnyone is ranked 16,636.

Same-category comparison
NameRankMetrics
JAMESYJL/ShapeLLM-Omni16,613
Language:
Python
Stars:
581
Forks:
30
Description:
[NeurIPS 2025 Spotlight] A Native Multimodal LLM for 3D Generation and Understanding.
SkyworkAI/SkyReels-A116,616
Language:
Python
Stars:
581
Forks:
61
Description:
SkyReels-A1: Expressive Portrait Animation in Video Diffusion Transformers.
SkyworkAI/SkyReels-V316,617
Language:
Python
Stars:
581
Forks:
93
Description:
SkyReels V3: Multimodal Video Generation Model.
Doby-Xu/WithAnyone16,636
Language:
Python
Stars:
580
Forks:
25
Description:
✨ [ICLR'26] WithAnyone is capable of generating high-quality, controllable, and ID consistent images.
Vchitect/VEnhancer16,653
Language:
Python
Stars:
579
Forks:
33
Description:
Official codes of VEnhancer: Generative Space-Time Enhancement for Video Generation.
microsoft/multiview-human-pose-estimation-pytorch16,663
Language:
Python
Stars:
579
Forks:
89
Description:
This is an official Pytorch implementation of "Cross View Fusion for 3D Human Pose Estimation, ICCV 2019".
Babelscape/rebel16,665
Language:
Python
Stars:
578
Forks:
76
Description:
REBEL is a seq2seq model that simplifies Relation Extraction (EMNLP 2021).
SkyworkAI/Vitron16,671
Language:
Python
Stars:
578
Forks:
34
Description:
NeurIPS 2024 Paper: A Unified Pixel-level Vision LLM for Understanding, Generating, Segmenting, Editing.
Key parameters and specifications
ParameterValue
LanguagePython
CategoryModels
SubcategoryVision models
KeywordsComputer vision, Model architecture
Stars580
Forks74
Contributors1
Created date2021-10-07
Updated date2026-09-29
Stars in 1 day0
Stars in 7 days0
Rank16,643
Previous rank16,433
Rank change-210
7-day stars rank15,644
Previous 7-day stars rank15,649
7-day stars rank change5
Total stars rank17,241
Previous total stars rank17,215
Total stars rank change-26
CountryCanada
README summary

MobileViT Overview This is a PyTorch implementation of MobileViT specified in "MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer", arXiv 2021. 👉 Check out CoAtNet if you are interested in other **Convolution + Transformer** models. Usage Citation Credits Code adapted from MobileNetV2 and ViT.

Frequently asked questions

How many stars and forks are recorded?

chinhsuanwu/mobilevit-pytorch has 580 stars and 74 forks.

What is the repository rank?

chinhsuanwu/mobilevit-pytorch is ranked 16,643.

What language and category are recorded?

chinhsuanwu/mobilevit-pytorch has 580 stars, uses Python and belongs to Models.

Which repository is closest in rank?

chinhsuanwu/mobilevit-pytorch is compared with Doby-Xu/WithAnyone, ranked 16,636 with 580 stars.

README

MobileViT

Overview

This is a PyTorch implementation of MobileViT specified in "MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer", arXiv 2021.
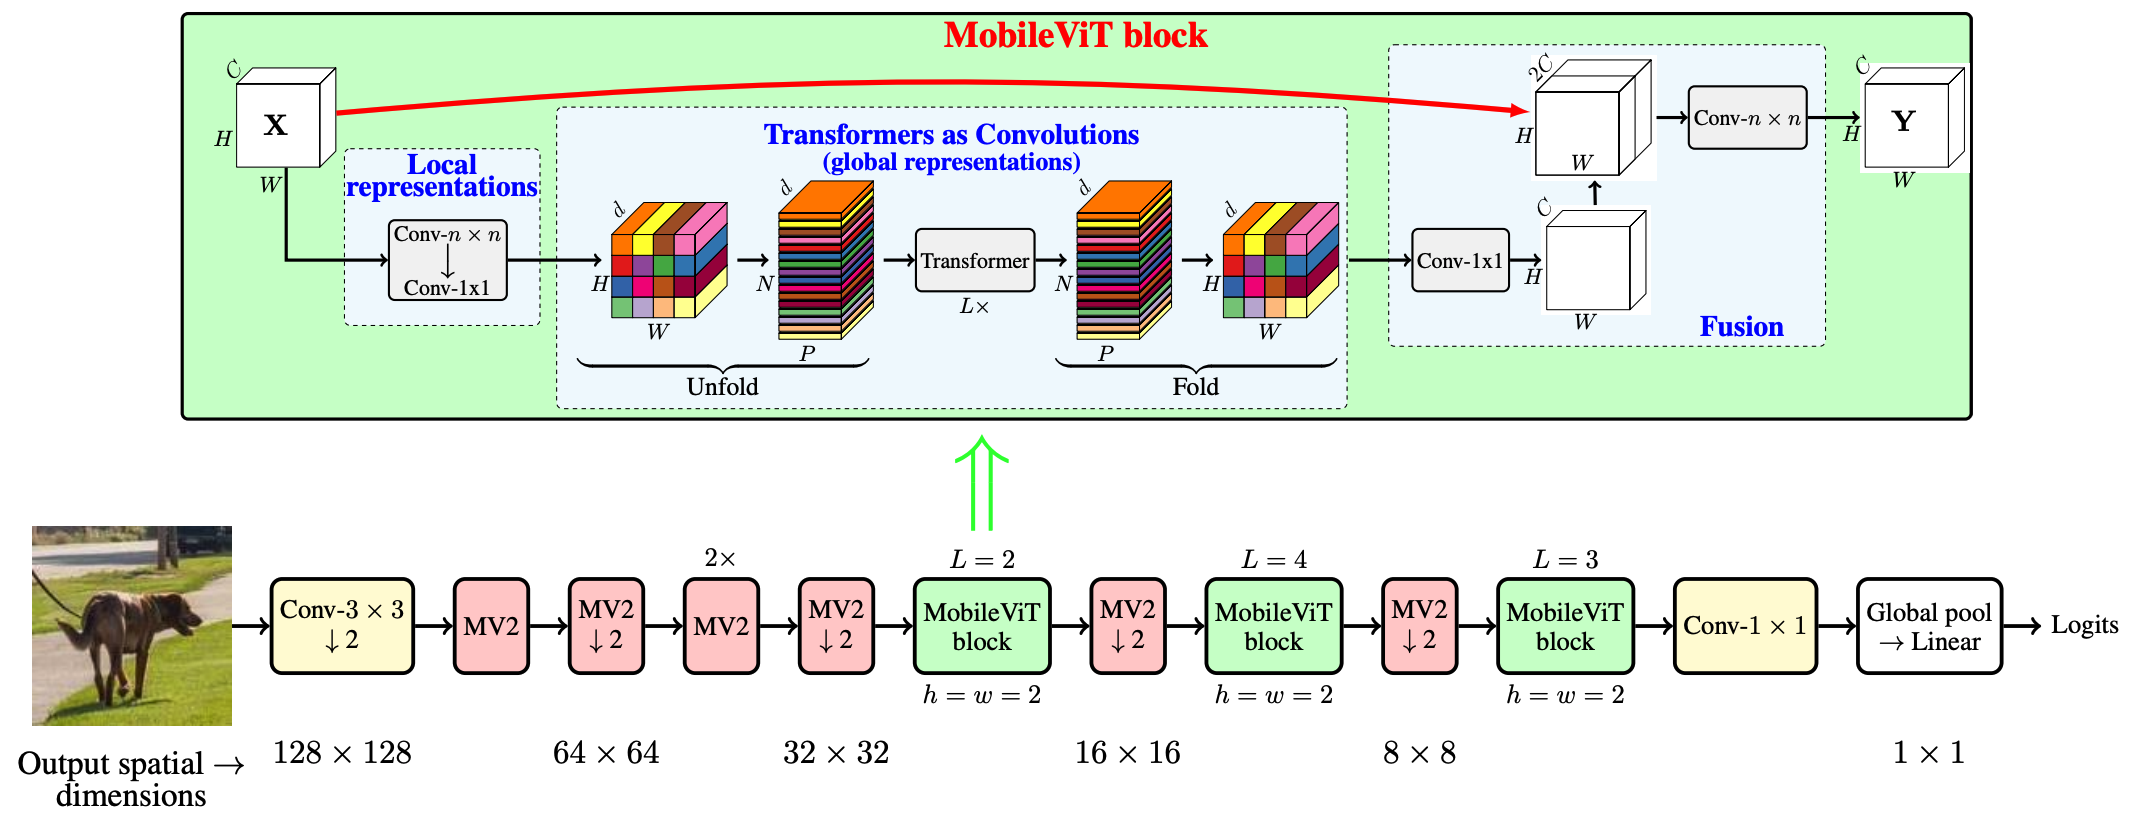
👉 Check out CoAtNet if you are interested in other Convolution + Transformer models.

Usage

import torch
from mobilevit import mobilevit_xxs

img = torch.randn(1, 3, 256, 256)
vit = mobilevit_xxs()
out = vit(img)

Citation

@article{mehta2021mobilevit,
  title={MobileViT: Light-weight, General-purpose, and Mobile-friendly Vision Transformer},
  author={Mehta, Sachin and Rastegari, Mohammad},
  journal={arXiv preprint arXiv:2110.02178},
  year={2021}
}

Credits

Code adapted from MobileNetV2 and ViT.

Nearby in the ranking
Similar items