← Open Source
bytedance

DreamID-V

[ECCV 2026 Oral] DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer.

ModelsVision modelsPython
Open on GitHub
Momentum
+0stars in 24 hours0.0%
694
Stars
96
Forks
+4
This week
2
Contributors
Created 2025-12-17 · Updated 2026-10-14 · #14898 today
Top developers
Guoxu1233superhero-7

bytedance/DreamID-V is ranked 14,898 with 694 stars.

Same-category comparison

bytedance/DreamID-V is ranked 14,898 among these 8 peers; SimonZeng7108/efficientsam3 is ranked 14,895.

Same-category comparison
NameRankMetrics
huyvnphan/PyTorch_CIFAR1014,865
Language:
Python
Stars:
697
Forks:
161
Description:
Pretrained TorchVision models on CIFAR10 dataset (with weights).
MeiGen-AI/OPSD-V14,880
Language:
Python
Stars:
695
Forks:
46
Description:
On-Policy Self-Distillation for Post-Training Few-Step Autoregressive Video Generators.
stepfun-ai/NextStep-114,891
Language:
Python
Stars:
695
Forks:
26
Description:
[🚀 ICLR 2026 Oral] NextStep-1: SOTA Autogressive Image Generation with Continuous Tokens. A research project developed by the StepFun’s Multimodal Intelligence team.
SimonZeng7108/efficientsam314,895
Language:
Jupyter Notebook
Stars:
694
Forks:
59
Description:
EfficientSAM3 compresses SAM3 into lightweight, edge-friendly models via progressive knowledge distillation for fast promptable concept segmentation and tracking.
TIGER-AI-Lab/VLM2Vec14,911
Language:
Python
Stars:
693
Forks:
65
Description:
This repo contains the code for "VLM2Vec / MMEB" [ICLR 2025], "VLM2Vec-V2 / MMEB-V2" [TMLR 2026], and "MMEB-V3" [COLM 2026].
Giphy/celeb-detection-oss14,925
Language:
Python
Stars:
692
Forks:
68
Description:
GIPHY's Open-Source Celebrity Detection Deep Learning Model.
PRBonn/LiDAR-MOS14,926
Language:
Python
Stars:
692
Forks:
112
Description:
(LMNet) Moving Object Segmentation in 3D LiDAR Data: A Learning-based Approach Exploiting Sequential Data (RAL/IROS 2021).
IEIT-Yuan/Yuan-2.014,992
Language:
Python
Stars:
687
Forks:
83
Description:
Yuan 2.0 Large Language Model.
Key parameters and specifications
ParameterValue
LanguagePython
CategoryModels
SubcategoryVision models
KeywordsImage production
Stars694
Forks96
Contributors2
Created date2025-12-17
Updated date2026-10-14
Stars in 1 day0
Stars in 7 days4
Rank14,898
Previous rank4,338
Rank change-10,560
7-day stars rank6,408
Previous 7-day stars rank4,868
7-day stars rank change-1,540
Total stars rank14,975
Previous total stars rank14,946
Total stars rank change-29
CountryChina
README summary

DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer 🌐 Project Page | 📜 Arxiv | 🤗 Models | 🤗 IDBench-V(Comming) | 🤗 IDBench-Omni **DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer** Xu Guo * , Fulong Ye * , Xinghui Li * , Pengqi Tu, Pengze Zhang, Qichao Sun, Songtao Zhao † , Xiangwang Hou † Qian He * Equal contribution, † Corresponding author Tsinghua University | Intelligent Creation Team, ByteDance 🔥 News [05/01/2026] 🎉 Our omni version DreamID
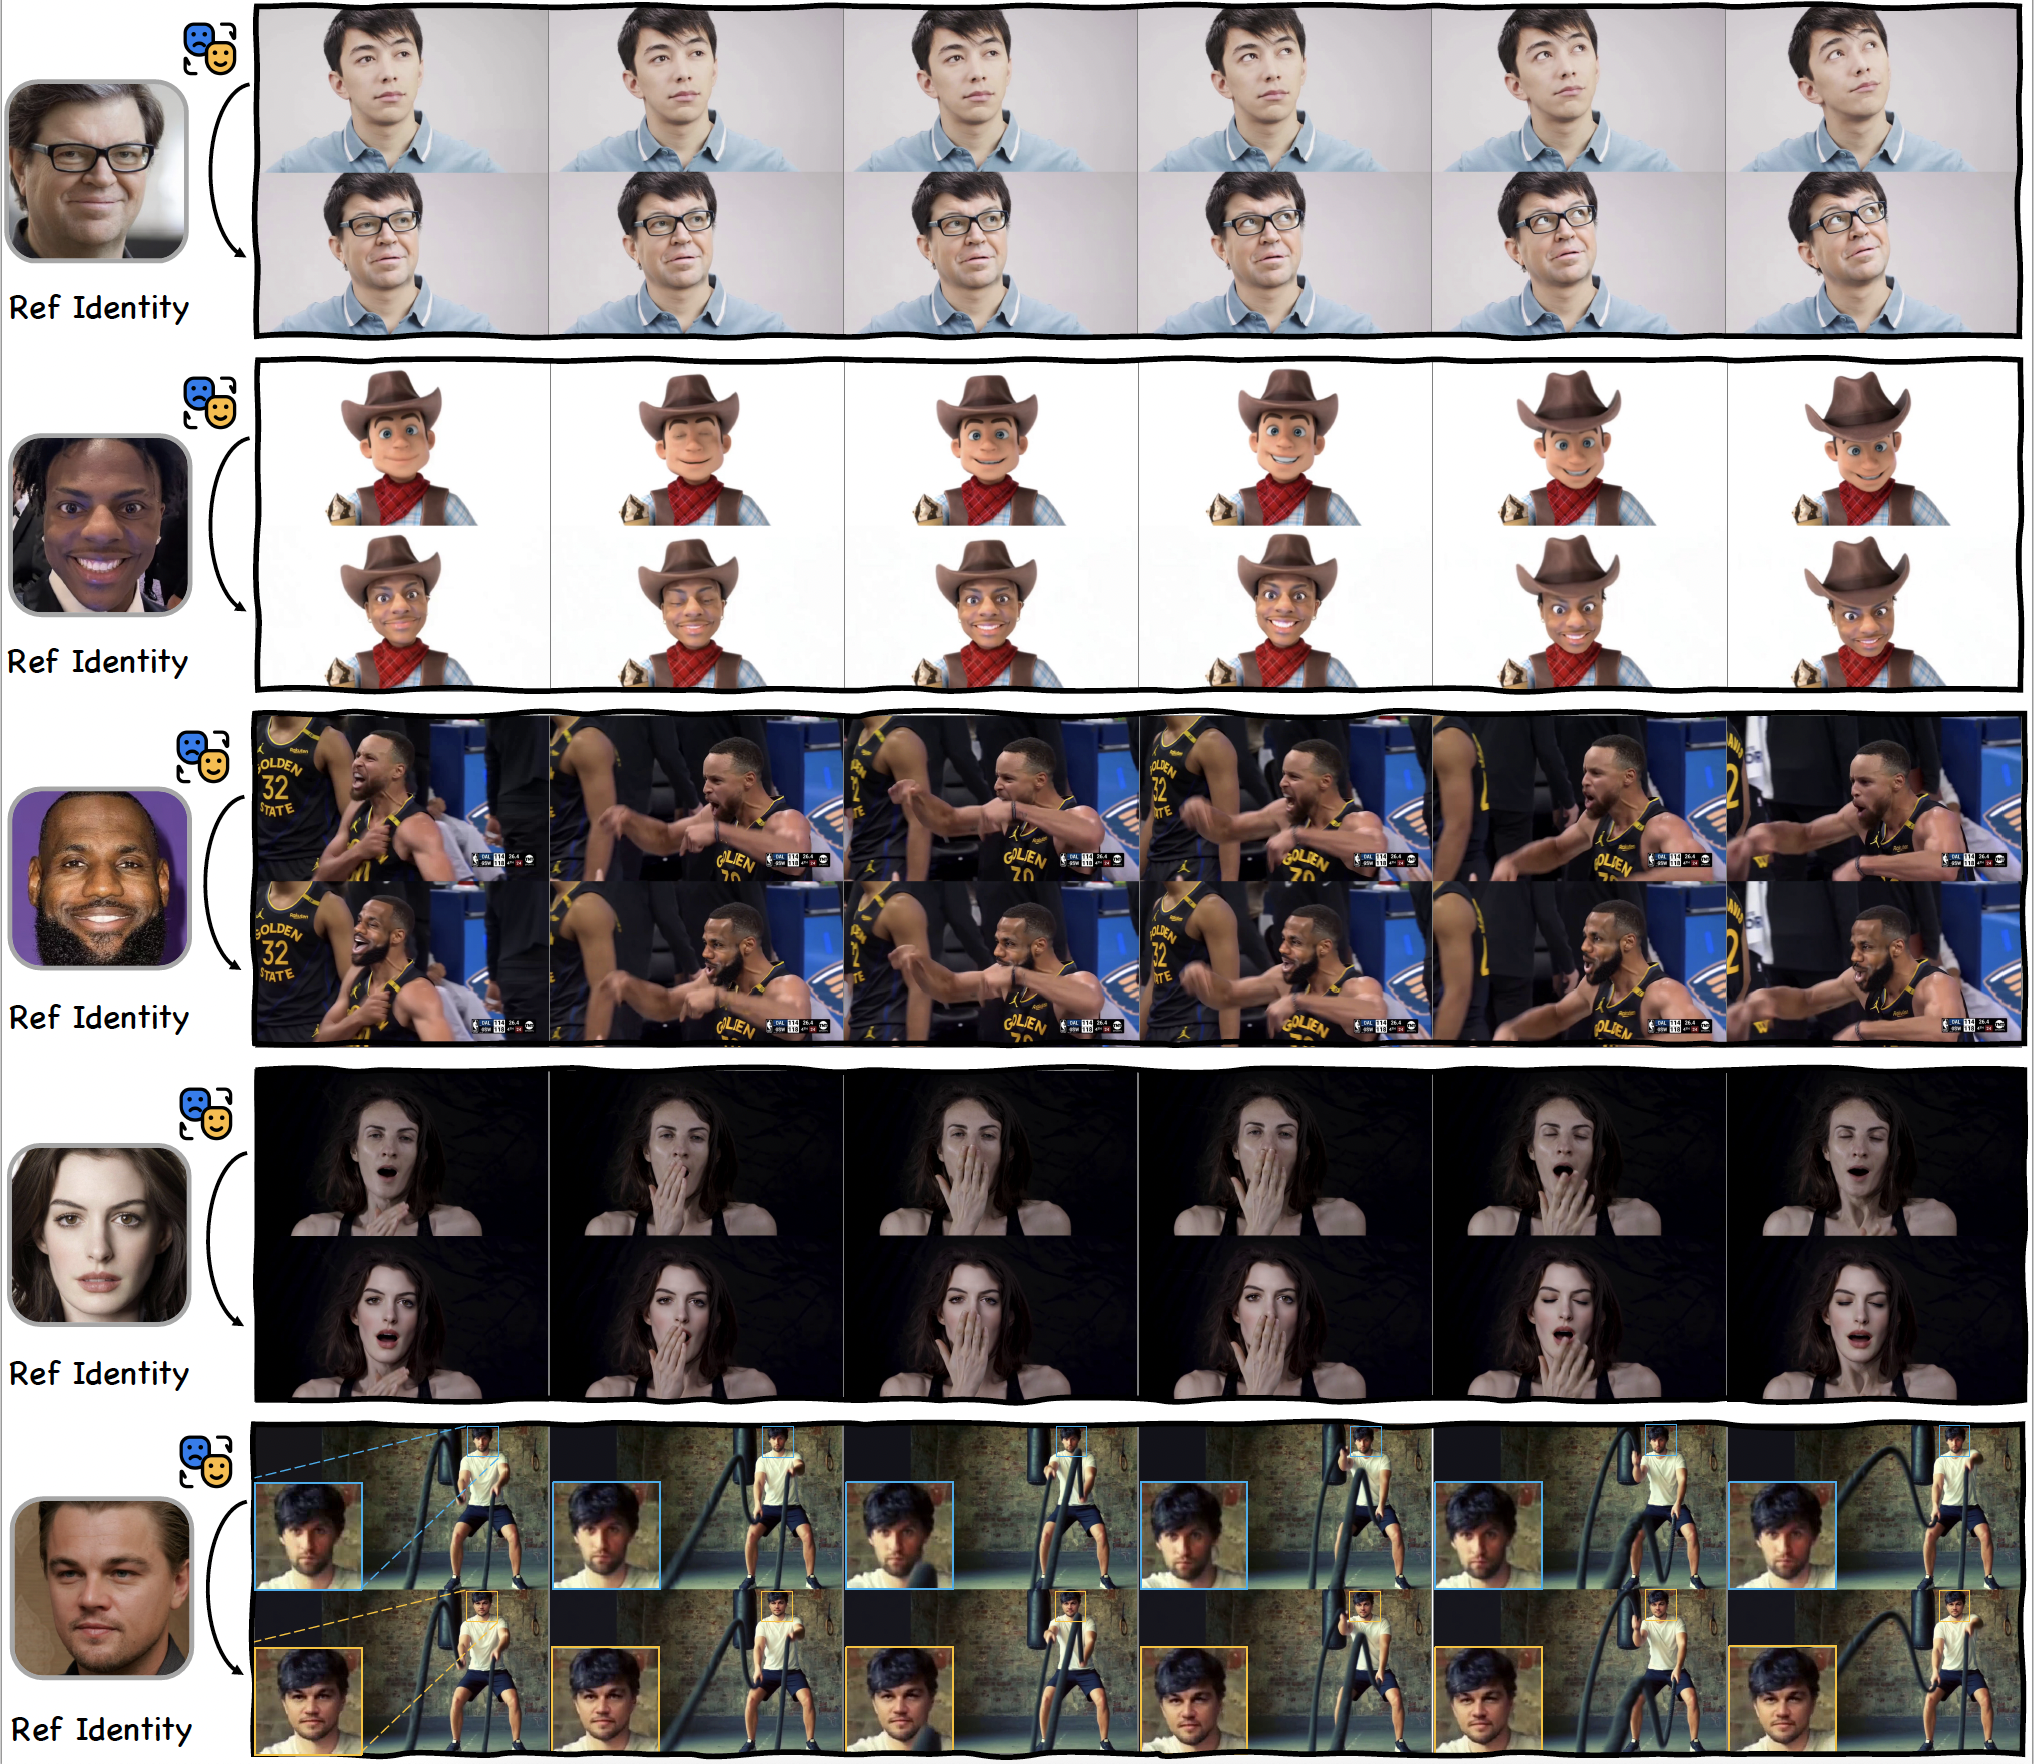
-Omni is accepted by ICML 2026! [01/13/2026] 🔥 Thanks Goldlionren for supporting the DreamID-V Faster ComfyUI. [01/12/2026] 🔥 We released DreamID-V-Wan-1. 3B-Faster, achieving a 1x inference speed boost with lower VRAM usage! [01/11/2026] 🔥 Thanks Goldlionren for supporting the 16GB VRAM GPUs version ComfyUI. [01/10/2026] 🔥 We released DreamID-V-Wan-1. 3B-DWPose with enhanced pose detection stability! [01/08/2026] 🔥 Thanks HM-RunningHub for supporting ComfyUI. [12/17/2025

] 🔥 Our project is released! [08/11/2025] 🎉 Our image version DreamID is accepted by SIGGRAPH Asia 2025! 💡 Usage Tips **Reference Image Preparation**: Please upload **cropped face images** (recommended resolution: 512x512) as reference. Avoid using full-body photos to ensure optimal identity preservation. **Inference Steps**: For simple scenes, you can reduce the sampling steps to **20** to significantly decrease inference time. *Note*: Our internal model based on Seedance1. 0 achieves high quality in under 8 steps. **Best Quality**: For the highest

fidelity results, we recommend using a resolution of **1280x720**. **Enhanced Pose Detection**: We have resolved the previous pose detection issue by introducing **DreamID-V-Wan-1. This significantly improves stability and robustness in pose extraction. 1 | 🤗 Huggingface | VAE & Text encoder Installation Install dependencies: DreamID-V-Wan-1. 3B-Faster Please ensure you have downloaded dreamidv_faster. pth and the DWPose estimation models are placed in the correct directory. Single-GPU inference Multi-GPU inference using FSDP + xDiT USP DreamID-V

-Wan-1. 3B-DWPose Please ensure the pose estimation models are placed in the correct directory as follows: Single-GPU inference Multi-GPU inference using FSDP + xDiT USP DreamID-V-Wan-1. 3B-MediaPipe Single-GPU inference Multi-GPU inference using FSDP + xDiT USP 👍 Acknowledgements Our work builds upon and is greatly inspired by several outstanding open-source projects, including Wan2. 1, Phantom, OpenHumanVid, Follow-Your-Emoji, DWPose. We sincerely thank the authors and contributors of these projects for generously

sharing their excellent codes and ideas. 📧 Contact If you have any comments or questions regarding this open-source project, please open a new issue or contact Xu Guo and Fulong Ye. ⚠️ Ethics Statement This project, **DreamID-V**, is intended for **academic research and technical demonstration purposes only**. **Prohibited Use**: Users are strictly prohibited from using this codebase to generate content that is illegal, defamatory, pornographic, harmful, or infringes upon the privacy and rights of others. **Responsibility**: Users bear full responsibility

for the content they generate. The authors and contributors of this project assume no liability for any misuse or consequences

Frequently asked questions

How many stars and forks are recorded?

bytedance/DreamID-V has 694 stars and 96 forks.

What is the repository rank?

bytedance/DreamID-V is ranked 14,898.

What language and category are recorded?

bytedance/DreamID-V has 694 stars, uses Python and belongs to Models.

Which repository is closest in rank?

bytedance/DreamID-V is compared with SimonZeng7108/efficientsam3, ranked 14,895 with 694 stars.

README

DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer

🌐 Project Page | 📜 Arxiv | 🤗 Models | 🤗 IDBench-V(Comming) | 🤗 IDBench-Omni

DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer

Xu Guo * , Fulong Ye * , Xinghui Li *, Pengqi Tu, Pengze Zhang, Qichao Sun, Songtao Zhao †, Xiangwang Hou † Qian He

  • Equal contribution, † Corresponding author

Tsinghua University | Intelligent Creation Team, ByteDance

🔥 News

  • [05/01/2026] 🎉 Our omni version DreamID-Omni is accepted by ICML 2026!
  • [01/13/2026] 🔥 Thanks Goldlionren for supporting the DreamID-V Faster ComfyUI.
  • [01/12/2026] 🔥 We released DreamID-V-Wan-1.3B-Faster, achieving a 1x inference speed boost with lower VRAM usage!
  • [01/11/2026] 🔥 Thanks Goldlionren for supporting the 16GB VRAM GPUs version ComfyUI.
  • [01/10/2026] 🔥 We released DreamID-V-Wan-1.3B-DWPose with enhanced pose detection stability!
  • [01/08/2026] 🔥 Thanks HM-RunningHub for supporting ComfyUI.
  • [01/06/2026] 🔥 Our paper is released!
  • [01/05/2026] 🔥 Our code is released!
  • [12/17/2025] 🔥 Our project is released!
  • [08/11/2025] 🎉 Our image version DreamID is accepted by SIGGRAPH Asia 2025!

💡 Usage Tips

  • Reference Image Preparation: Please upload cropped face images (recommended resolution: 512x512) as reference. Avoid using full-body photos to ensure optimal identity preservation.
  • Inference Steps: For simple scenes, you can reduce the sampling steps to 20 to significantly decrease inference time.

    Note: Our internal model based on Seedance1.0 achieves high quality in under 8 steps. Feel free to experience it at CapCut.

  • Best Quality: For the highest fidelity results, we recommend using a resolution of 1280x720.
  • Enhanced Pose Detection: We have resolved the previous pose detection issue by introducing DreamID-V-Wan-1.3B-DWPose. This significantly improves stability and robustness in pose extraction.

⚡️ Quickstart

Model Preparation

Models Download Link Notes
DreamID-V 🤗 Huggingface Supports 480P & 720P
Wan-2.1 🤗 Huggingface VAE & Text encoder

Installation

Install dependencies:

# Ensure torch >= 2.4.0
pip install -r requirements.txt

DreamID-V-Wan-1.3B-Faster

Please ensure you have downloaded dreamidv_faster.pth and the DWPose estimation models are placed in the correct directory.

DreamID-V/
└── pose/
    └── models/
        ├── dw-ll_ucoco_384.onnx 
        └── yolox_l.onnx         
  • Single-GPU inference
python generate_dreamidv_faster.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv_faster.pth path  \
    --sample_steps 16 \
    --base_seed 42
  • Multi-GPU inference using FSDP + xDiT USP
pip install "xfuser>=0.4.1"
torchrun --nproc_per_node=2 generate_dreamidv_faster.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv_faster.pth path  \
    --sample_steps 16 \
    --dit_fsdp \
    --t5_fsdp \
    --ulysses_size 2 \
    --ring_size 1 \
    --base_seed 42

DreamID-V-Wan-1.3B-DWPose

Please ensure the pose estimation models are placed in the correct directory as follows:

DreamID-V/
└── pose/
    └── models/
        ├── dw-ll_ucoco_384.onnx 
        └── yolox_l.onnx         
  • Single-GPU inference
python generate_dreamidv_dwpose.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv.pth path  \
    --sample_steps 20 \
    --base_seed 42
  • Multi-GPU inference using FSDP + xDiT USP
pip install "xfuser>=0.4.1"
torchrun --nproc_per_node=2 generate_dreamidv_dwpose.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv.pth path  \
    --sample_steps 20 \
    --dit_fsdp \
    --t5_fsdp \
    --ulysses_size 2 \
    --ring_size 1 \
    --base_seed 42

DreamID-V-Wan-1.3B-MediaPipe

  • Single-GPU inference
python generate_dreamidv.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv.pth path  \
    --sample_steps 20 \
    --base_seed 42
  • Multi-GPU inference using FSDP + xDiT USP
pip install "xfuser>=0.4.1"
torchrun --nproc_per_node=2 generate_dreamidv.py \
    --size 832*480 \
    --ckpt_dir wan2.1-1.3B path \
    --dreamidv_ckpt dreamidv.pth path  \
    --sample_steps 20 \
    --dit_fsdp \
    --t5_fsdp \
    --ulysses_size 2 \
    --ring_size 1 \
    --base_seed 42

👍 Acknowledgements

Our work builds upon and is greatly inspired by several outstanding open-source projects, including Wan2.1, Phantom, OpenHumanVid, Follow-Your-Emoji, DWPose. We sincerely thank the authors and contributors of these projects for generously sharing their excellent codes and ideas.

📧 Contact

If you have any comments or questions regarding this open-source project, please open a new issue or contact Xu Guo and Fulong Ye.

⚠️ Ethics Statement

This project, DreamID-V, is intended for academic research and technical demonstration purposes only.

  • Prohibited Use: Users are strictly prohibited from using this codebase to generate content that is illegal, defamatory, pornographic, harmful, or infringes upon the privacy and rights of others.
  • Responsibility: Users bear full responsibility for the content they generate. The authors and contributors of this project assume no liability for any misuse or consequences arising from the use of this software.
  • AI Labeling: We strongly recommend marking generated videos as "AI-Generated" to prevent misinformation. By using this software, you agree to adhere to these guidelines and applicable local laws.

⭐ Citation

If you find our work helpful, please consider citing our paper and leaving valuable stars

@article{guo2026dreamidv,
  title   = {DreamID-V: Bridging the Image-to-Video Gap for High-Fidelity Face Swapping via Diffusion Transformer},
  author  = {Guo, Xu and Ye, Fulong and Li, Xinghui and Tu, Pengqi and Zhang, Pengze and Sun, Qichao and Zhao, Songtao and Hou, Xiangwang and He, Qian},
  journal = {arXiv preprint arXiv:2601.01425},
  year    = {2026}
}

Star History

Nearby in the ranking
Similar items