Mistral: A strong, northwesterly wind: Framework for transparent and accessible large-scale language model training, built with Hugging Face 🤗 Transformers.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Language
Python
Category
Model Development
Subcategory
Architecture
Keywords
Computer vision
Stars
583
Forks
47
Contributors
5
Created date
2023-05-20
Updated date
2026-10-14
Stars in 1 day
0
Stars in 7 days
2
Rank
16,583
Previous rank
16,373
Rank change
-210
7-day stars rank
8,773
Previous 7-day stars rank
7,413
7-day stars rank change
-1,360
Total stars rank
17,166
Previous total stars rank
17,137
Total stars rank change
-29
Country
China
README summary
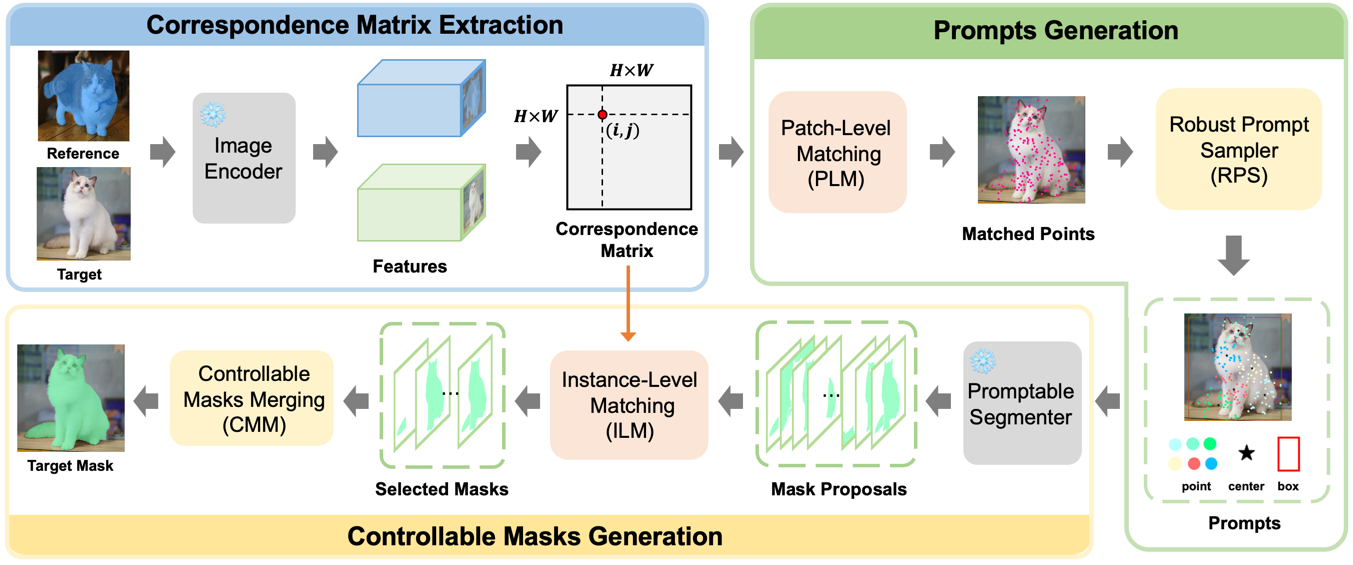
Matcher: Segment Anything with One Shot Using All-Purpose Feature Matching Yang Liu 1* , Muzhi Zhu 1* , Hengtao Li 1* , Hao Chen 1 , Xinlong Wang 2 , Chunhua Shen 1 1 Zhejiang University, 2 Beijing Academy of Artificial Intelligence ICLR 2024 🚀 Overview 📖 Description Powered by large-scale pre-training, vision foundation models exhibit significant potential in open-world image understanding. However, unlike large language models that excel at directly tackling various language tasks, vision foundation models require a task-specific model
structure followed by fine-tuning on specific tasks. In this work, we present **Matcher**, a novel perception paradigm that utilizes off-the-shelf vision foundation models to address various perception tasks. Matcher can segment anything by using an in-context example without training. Additionally, we design three effective components within the Matcher framework to collaborate with these foundation models and unleash their full potential in diverse perception tasks. Matcher demonstrates impressive generalization performance across various segmentation tasks, all without training
. Our visualization results further showcase the open-world generality and flexibility of Matcher when applied to images in the wild. 1 Matcher has been accepted to ICLR 2024! 1 Matcher supports Semantic-SAM for better part segmentation. 1 Release code of one-shot semantic segmentation and one-shot part segmentation tasks. 📖 Recommanded Works SINE: A Simple Image Segmentation Framework via In-Context Examples. DiffewS: Unleashing the Potential of the Diffusion Model in Few-shot Semantic Segmentation. 👻 Getting Started See Preparing
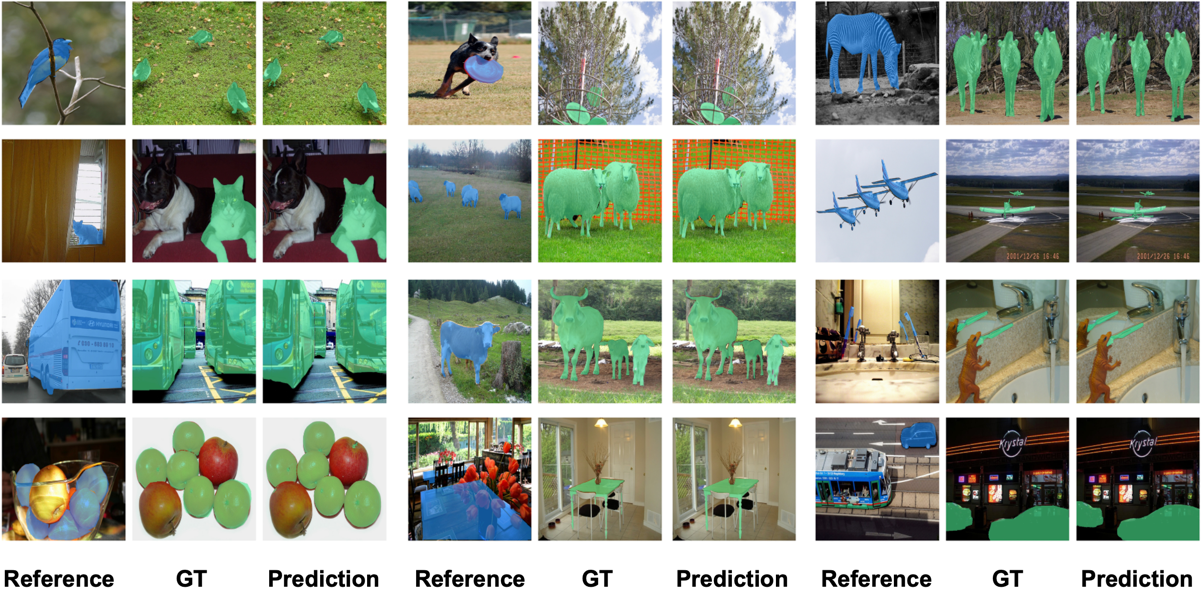
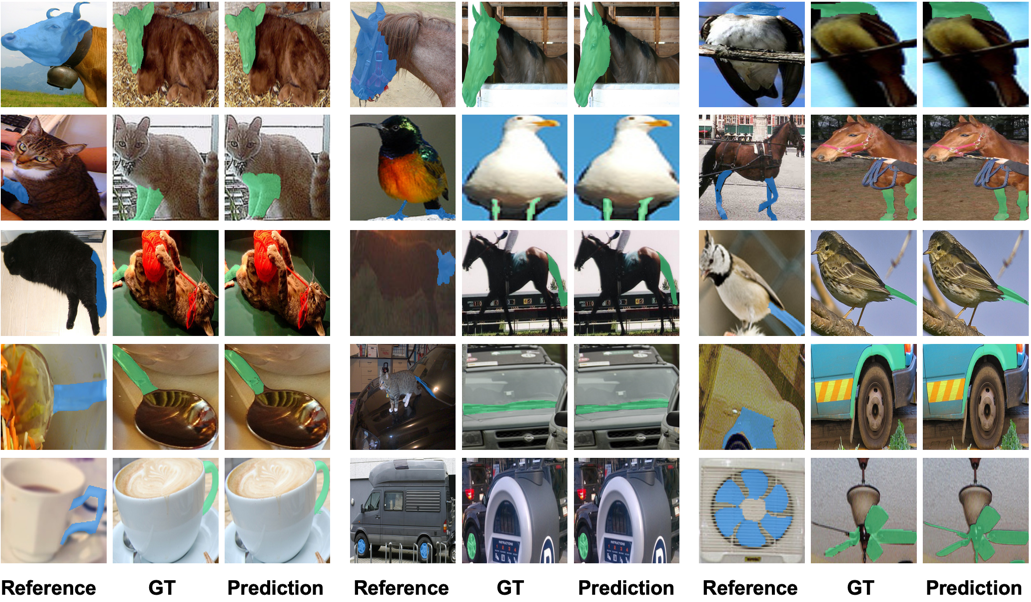
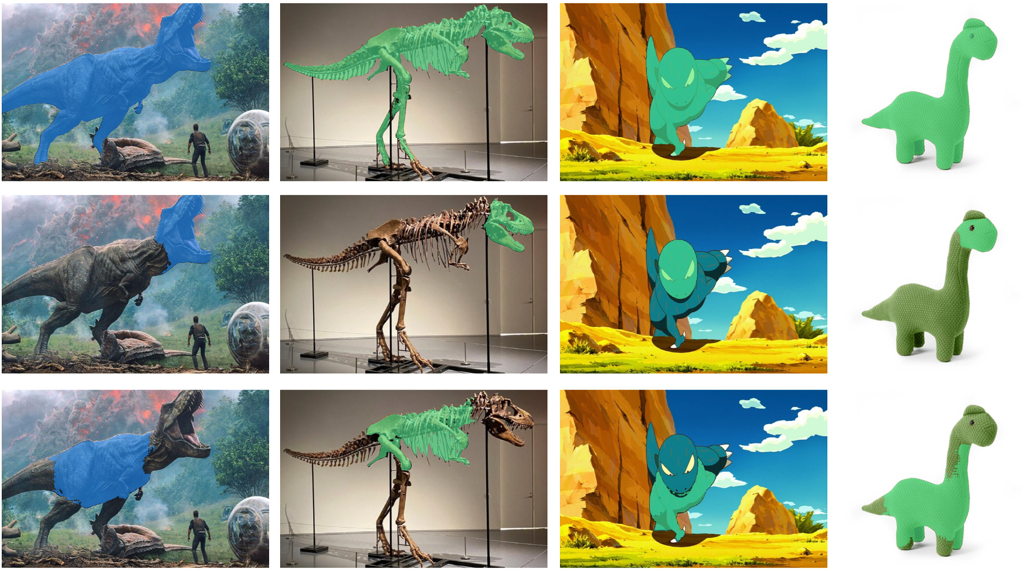
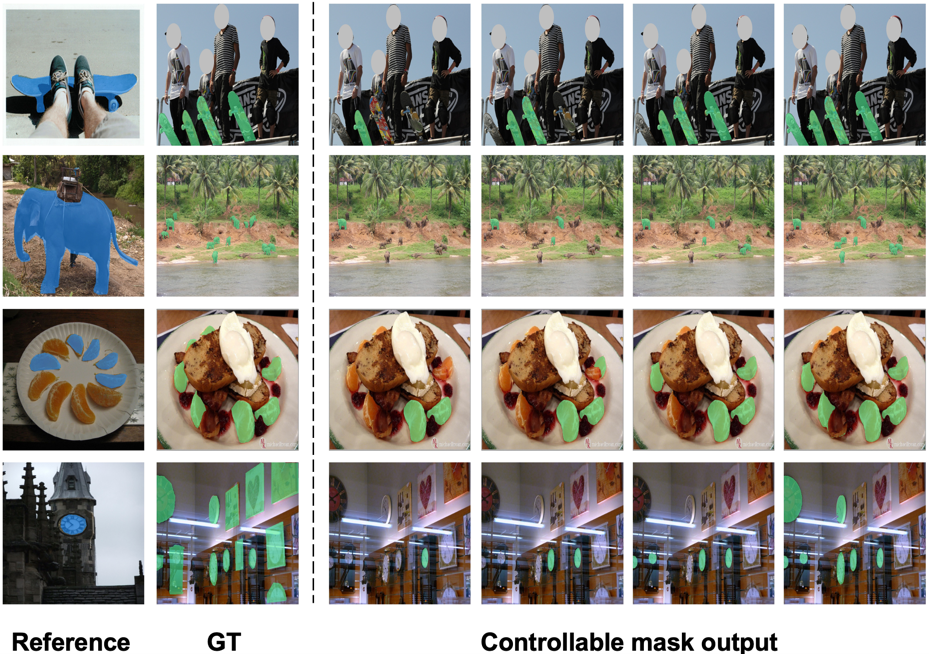
Datasets for Matcher. 🖼️ Demo One-Shot Semantic Segmantation One-Shot Object Part Segmantation Cross-Style Object and Object Part Segmentation Controllable Mask Output Video Object Segmentation 🎫 License For academic use, this project is licensed under the 2-clause BSD License. For commercial use, please contact Chunhua Shen. 🖊️ Citation If you find this project useful in your research, please consider to cite: Acknowledgement SAM, DINOv2, SegGPT, HSNet, Semantic-SAM and detectron2.
Frequently asked questions
How many stars and forks are recorded?
aim-uofa/Matcher has 583 stars and 47 forks.
What is the repository rank?
aim-uofa/Matcher is ranked 16,583.
What language and category are recorded?
aim-uofa/Matcher has 583 stars, uses Python and belongs to Model Development.
Which repository is closest in rank?
aim-uofa/Matcher is compared with OysterQAQ/ACG2vec, ranked 16,582 with 583 stars.
README
Matcher: Segment Anything with One Shot Using All-Purpose Feature Matching
Powered by large-scale pre-training, vision foundation models exhibit significant potential in open-world image understanding. However, unlike large language models that excel at directly
tackling various language tasks, vision foundation models require a task-specific model structure followed by fine-tuning on specific tasks. In this work, we present Matcher,
a novel perception paradigm that utilizes off-the-shelf vision foundation models to address various perception tasks. Matcher can segment anything by using an in-context example without training.
Additionally, we design three effective components within the Matcher framework to collaborate with these foundation models and unleash their full potential in diverse perception tasks.
Matcher demonstrates impressive generalization performance across various segmentation tasks, all without training. Our visualization results further showcase the open-world generality and flexibility of Matcher when applied to images in the wild.
If you find this project useful in your research, please consider to cite:
@article{liu2023matcher,
  title={Matcher: Segment Anything with One Shot Using All-Purpose Feature Matching},
  author={Liu, Yang and Zhu, Muzhi and Li, Hengtao and Chen, Hao and Wang, Xinlong and Shen, Chunhua},
  journal={arXiv preprint arXiv:2305.13310},
  year={2023}
}