|
Action recognition |
va-cnn, st-gcn, mars, ax_action_recognition, driver-action-recognition-adas, action_clip |
 |
Anomaly detection |
mahalanobisad, spade-pytorch, padim, patchcore, glass |
|
Audio language model |
qwen_audio |
|
Audio processing |
Audio classification: crnn_audio_classification, audioset_tagging_cnn, transformer-cnn-emotion-recognition, microsoft clap, clap |
| Music enhancement: hifigan, deep music enhancer |
|
|
| Music generation: pytorch_wavenet |
|
|
| Noise reduction: rnnoise, voicefilter, unet_source_separation, demucs, dtln, voicesplit, audiosep |
|
|
| Phoneme alignment: narabas |
|
|
| Pitch detection: crepe |
|
|
| Speaker diarization: pyannote-audio, auto_speech, wespeaker |
|
|
| Speech to text: deepspeech2, whisper, reazon_speech, distil-whisper, sensevoice, reazon_speech2, kotoba-whisper, lite-whisper |
|
|
| Text to speech: pytorch-dc-tts, tacotron2, vall-e-x, Bert-VITS2, gpt-sovits, gpt-sovits-v2, cosyvoice2, gpt-sovits-v3, gpt-sovits-v2-pro, qwen3-tts |
|
|
| Voice activity detection: silero-vad |
|
|
| Voice conversion: rvc |
|
|
 |
Autonomous driving |
bevformer, segformer, uniad |
 |
Background removal |
deep-image-matting, indexnet, U-2-Net, u2net-portrait-matting, u2net-human-seg, cascade_psp, rembg, gfm, modnet, background_matting_v2, dis_seg |
 |
Crowd counting |
crowdcount-cascaded-mtl, c-3-framework |
 |
Deep fashion |
fashionai-key-points-detection, person-attributes-recognition-crossroad, clothing-detection, mmfashion, mmfashion_tryon, mmfashion_retrieval |
 |
Depth estimation |
fcrn-depthprediction, monodepth2, fast-depth, midas, hitnet, lap-depth, mobilestereonet, crestereo, zoe_depth, depth_anything, depth_anything_v2, depth_pro, depth_anything_v3 |
 |
Diffusion |
Text to image: latent-diffusion-txt2img, stable-diffusion-txt2img, anything_v3, control_net, sdxl, latent-consistency-models, sd-turbo, sdxl-turbo, depth_anything_controlnet, latentsync |
| Text to audio: riffusion |
|
|
| Others: latent-diffusion-inpainting, latent-diffusion-superresolution, DA-CLIP, marigold |
|
|
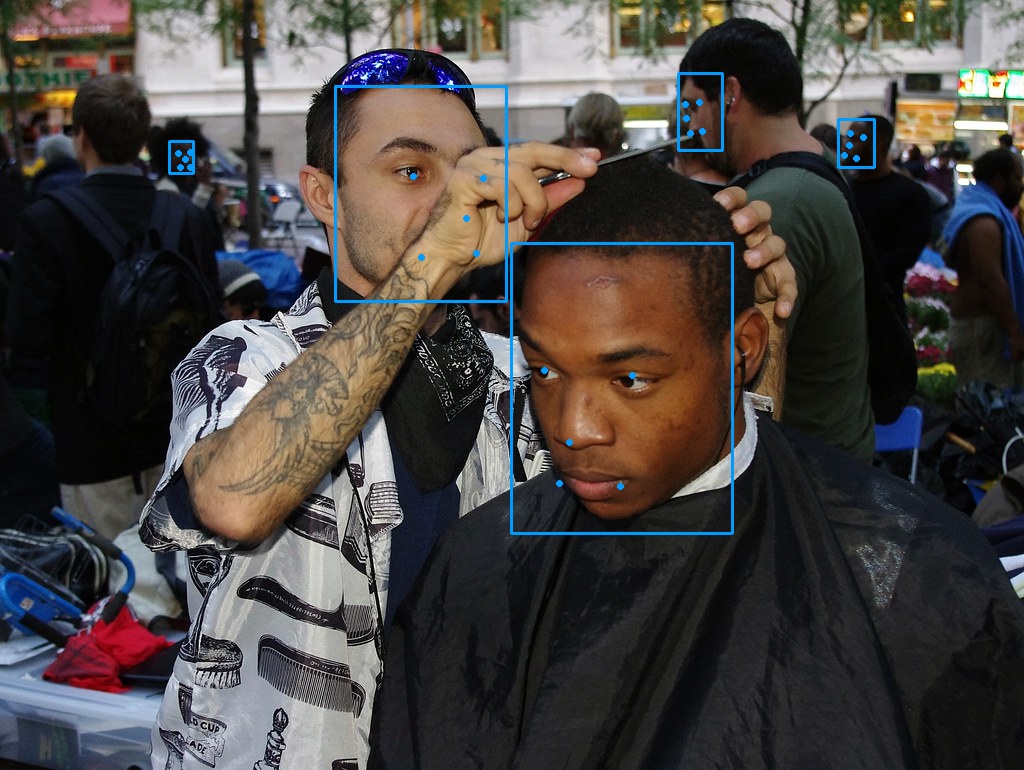 |
Face detection |
mtcnn, yolov1-face, face-detection-adas, retinaface, blazeface, yolov3-face, face-mask-detection, dbface, anime-face-detector |
 |
Face identification |
facenet_pytorch, insightface, vggface2, arcface, cosface |
 |
Face recognition |
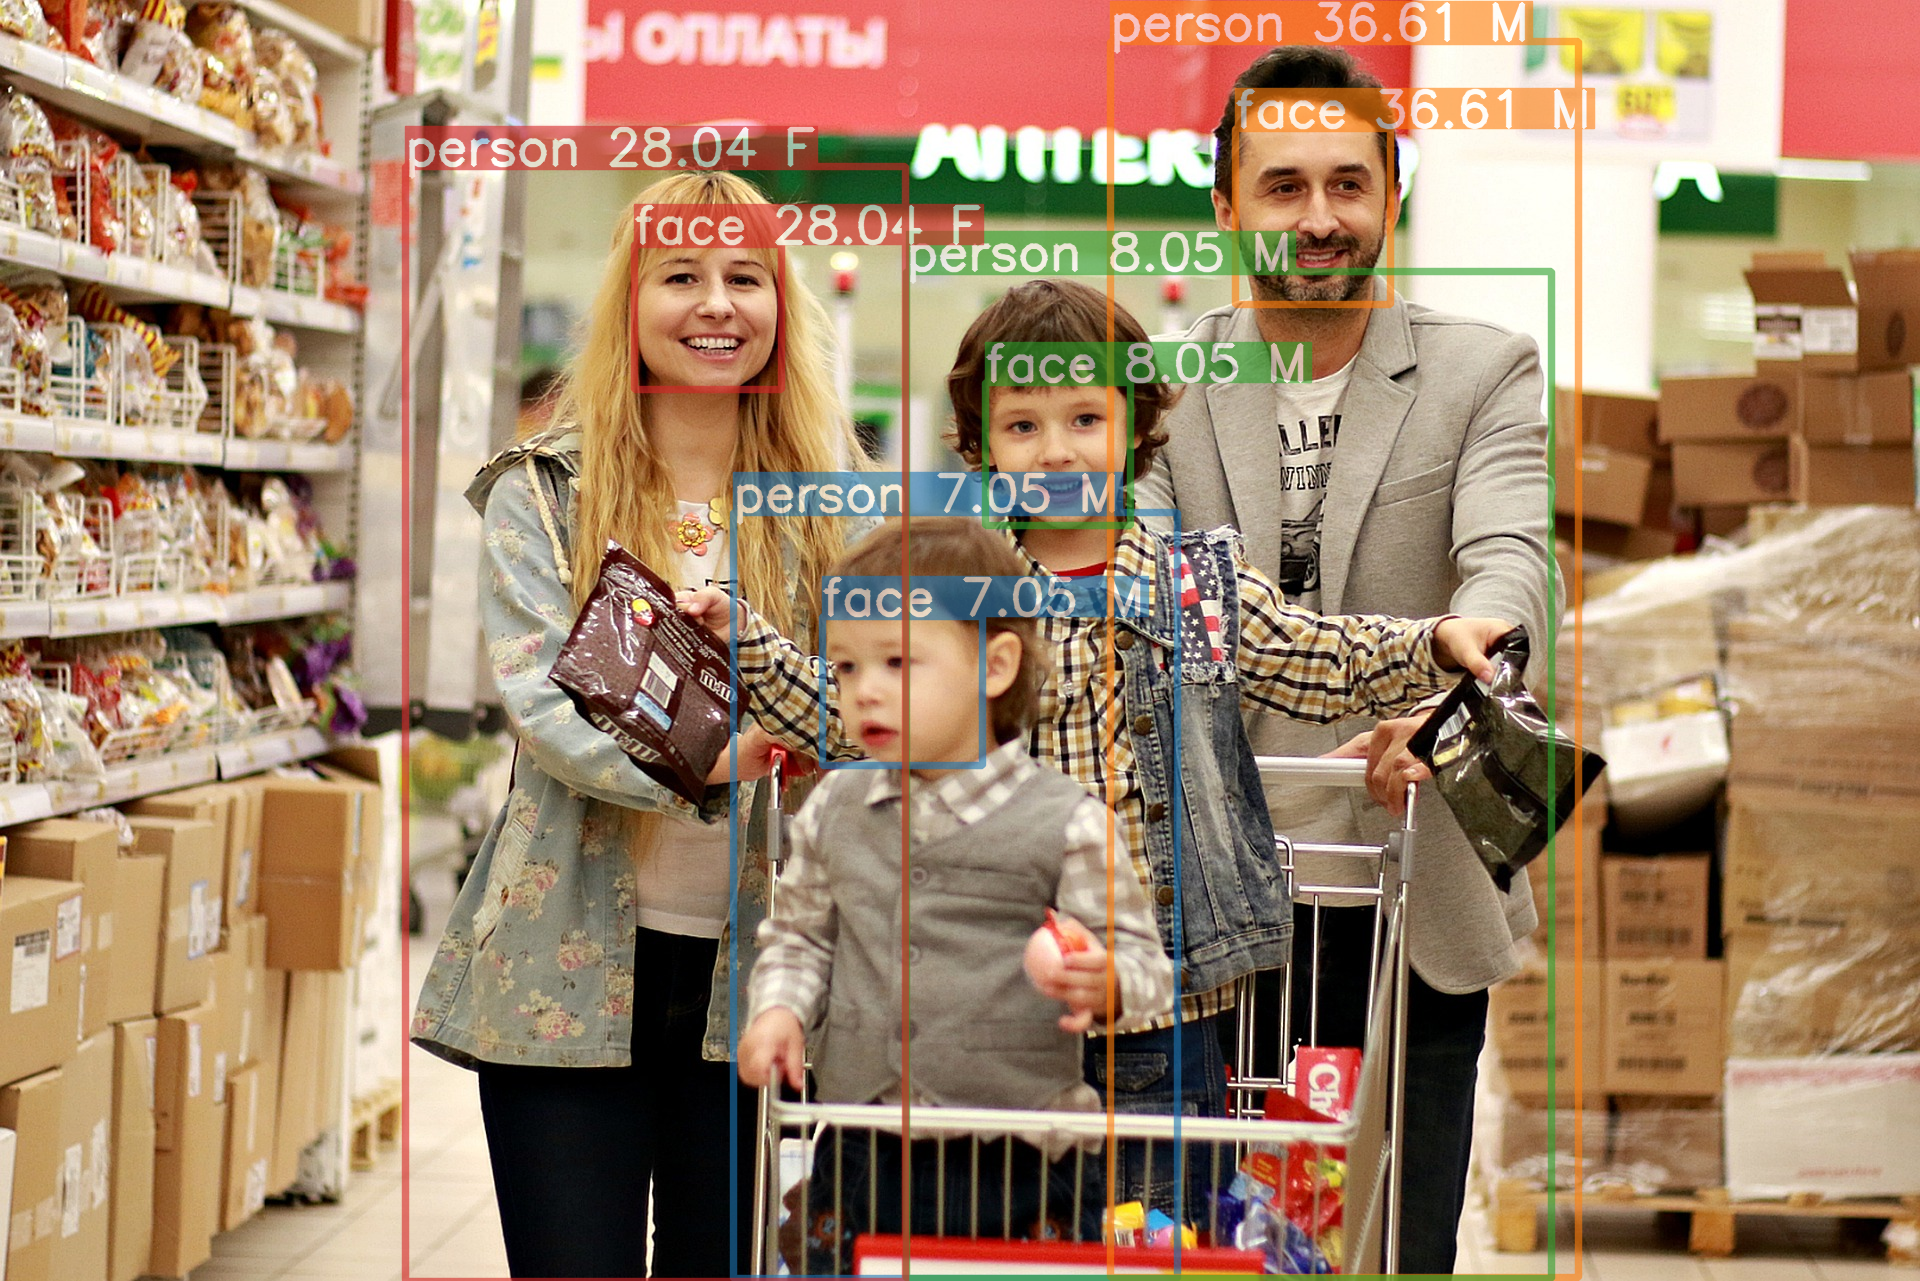
Age gender estimation: face_classification, age-gender-recognition-retail, mivolo, ailia_age_gender |
| Emotion recognition: ferplus, hsemotion |
|
|
| Gaze estimation: gazeml, mediapipe_iris, gazelle, ax_gaze_estimation |
|
|
| Head pose estimation: hopenet, 6d_repnet, L2CS_Net, 6d_repnet_360 |
|
|
| Keypoint detection: face_alignment, prnet, facemesh, facial_feature, 3ddfa, facemesh_v2 |
|
|
| Others: face-anti-spoofing, ax_facial_features |
|
|
 |
Face restoration |
gfpgan, codeformer |
 |
Face swapping |
deepfacelive, sber-swap, facefusion |
 |
Feature extraction |
dinov3 |
 |
Frame interpolation |
cain, rife, flavr, film |
 |
Generative adversarial networks |
pytorch-gan, lipgan, council-gan, sam, encoder4editing, restyle-encoder, SadTalker, live_portrait |
 |
Hand detection |
hand_detection_pytorch, yolov3-hand, blazepalm |
 |
Hand recognition |
hand3d, v2v-posenet, minimal-hand, blazehand, hands_segmentation_pytorch |
 |
Image captioning |
illustration2vec, image_captioning_pytorch, blip2 |
 |
Image classification |
CNN: alexnet, vgg16, googlenet, resnet18, resnet50, inceptionv3, inceptionv4, wide_resnet50, mobilenetv2, mobilenetv3, efficientnet, efficientnetv2, imagenet21k, mlp_mixer, volo, convnext, mobileone |
| Transformer: vit, clip, swin-transformer, japanese-clip, japanese-stable-clip-vit-l-16, siglip-multilingual, clip-japanese-base, siglip2 |
|
|
| Specific task: weather-prediction-from-image, partialconv |
|
|
 |
Image inpainting |
inpainting-with-partial-conv, deepfillv2, inpainting_gmcnn, 3d-photo-inpainting, lama |
 |
Image manipulation |
colorization, cnngeometric_pytorch, style2paints, deblur_gan, pytorch-superpoint, noise2noise, dfe, illnet, dewarpnet, deep_white_balance, u2net_portrait, invertible_denoising_network, dfm, fbcnn, dehamer, lightglue, docshadow |
 |
Image quality assessment |
aesthetic-predictor |
 |
Image restoration |
nafnet |
 |
Image segmentation |
pytorch-fcn, pytorch-enet, tusimple-DUC, pytorch-unet, deeplabv3, pspnet-hair-segmentation, swiftnet, hrnet_segmentation, hair_segmentation, paddleseg, human_part_segmentation, semantic-segmentation-mobilenet-v3, suim, yet-another-anime-segmenter, dense_prediction_transformers, group_vit, pp_liteseg, anime-segmentation, yolov8-seg, segment-anything, grounded_sam, fast_sam, mobile_sam, edge_sam, segment-anything-2, yolov11-seg, segment-anything-3.1 |
 |
Landmark classification |
places365, landmarks_classifier_asia |
 |
Line segment detection |
dexined, mlsd |
 |
Low light image enhancement |
agllnet, drbn_skf |
|
Natural language processing |
Bert: bert, bert_maskedlm, bert_question_answering |
| Embedding: sentence_transformers_japanese, multilingual-e5, glucose, qwen3-embedding, ruri-v3, embeddinggemma |
|
|
| Error corrector: bert_insert_punctuation, bertjsc, t5_whisper_medical |
|
|
| Grapheme to phoneme: g2p_en, g2pw, soundchoice-g2p |
|
|
| Named entity recognition: bert_ner, t5_base_japanese_ner, bert_ner_japanese |
|
|
| Reranker: cross_encoder_mmarco, japanese-reranker-cross-encoder, ruri-v3-reranker |
|
|
| Sentence generation: gpt2, rinna_gpt2 |
|
|
| Sentiment analysis: bert_sentiment_analysis, bert_tweets_sentiment |
|
|
| Summarize: bert_sum_ext, presumm, t5_base_japanese_title_generation, t5_base_summarization |
|
|
| Translation: fugumt-en-ja, fugumt-ja-en |
|
|
| Zero shot classification: bert_zero_shot_classification, multilingual-minilmv2 |
|
|
|
Network intrusion detection |
bert-network-packet-flow-header-payload, falcon-adapter-network-packet |
 |
Neural rendering |
nerf, TripoSR |
|
NSFW detector |
clip-based-nsfw-detector |
 |
Object detection |
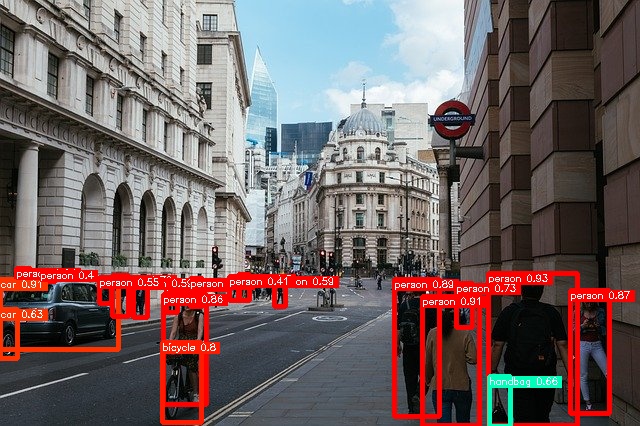
CNN: yolov1-tiny, yolov2, yolov2-tiny, maskrcnn, yolov3, yolov3-tiny, mobilenet_ssd, m2det, centernet, yolact, efficientdet, pedestrian_detection, crowd_det, yolov4, yolov4-tiny, yolov5, poly_yolo, nanodet, yolor, yolox, picodet, yolox-ti-lite, yolov7, fastest-det, yolov, yolov6, damo_yolo, yolov8, yolox_body_head_hand_face, yolov9, yolov10, yolov11, yolov12 |
| Transformer: detr, glip, dab-detr, detic, groundingdino, rt-detr-v2 |
|
|
| Specific target: traffic-sign-detection, sku110k-densedet, footandball, qrcode_wechatqrcode, mobile_object_localizer, layout_parsing |
|
|
 |
Object detection 3d |
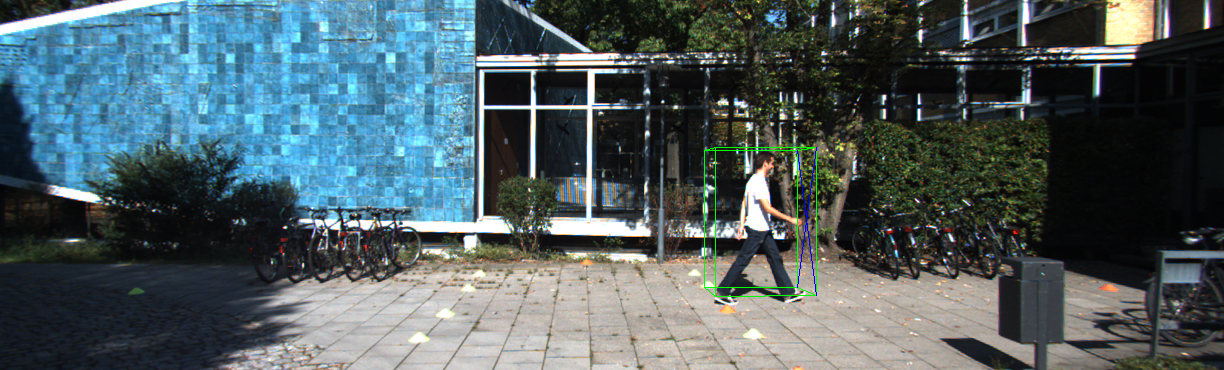
3d_bbox, d4lcn, egonet, mediapipe_objectron, 3d-object-detection.pytorch, did_m3d |
 |
Object tracking |
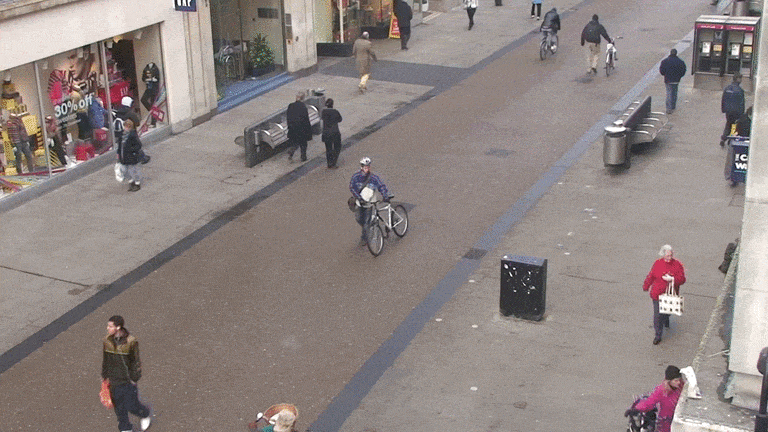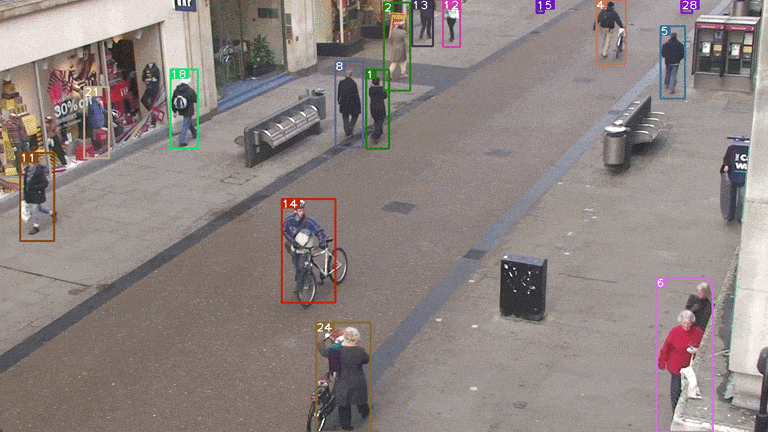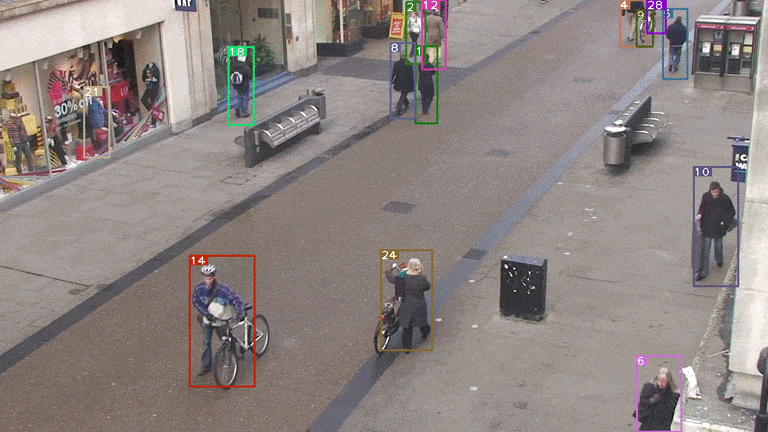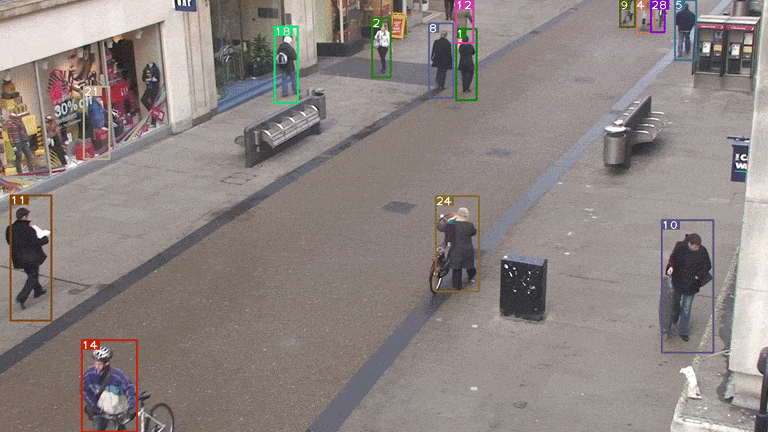
deepsort, person_reid_baseline_pytorch, abd_net, deepsort_vehicle, qd-3dt, centroids-reid, siam-mot, bytetrack, strong_sort, samurai |
 |
Optical flow estimation |
raft, cotracker3 |
 |
Point segmentation |
pointnet_pytorch |
 |
Pose estimation |
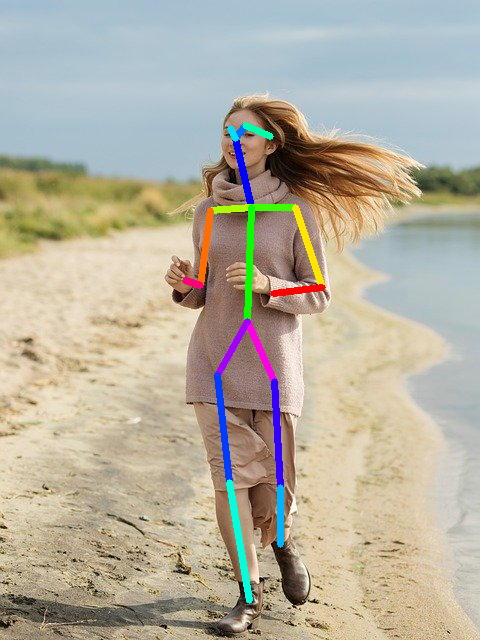
openpose, posenet, pose_resnet, lightweight-human-pose-estimation, animalpose, efficientpose, blazepose, mediapipe_holistic, movenet, ap-10k, e2pose |
 |
Pose estimation 3d |
pose-hg-3d, 3d-pose-baseline, lightweight-human-pose-estimation-3d, 3dmppe_posenet, gast, blazepose-fullbody, mediapipe_pose_world_landmarks |
 |
Road detection |
road-segmentation-adas, codes-for-lane-detection, ultra-fast-lane-detection, polylanenet, roneld, lstr, yolop, cdnet, hybridnets |
 |
Rotation prediction |
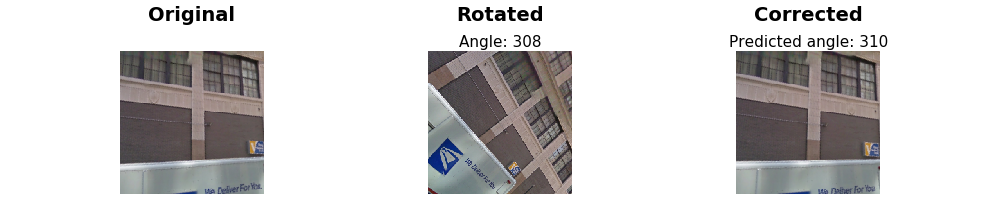
rotnet |
 |
Style transfer |
adain, pix2pixHD, beauty_gan, psgan, animeganv2, EleGANt |
 |
Super resolution |
srresnet, edsr, han, real-esrgan, swinir, rcan-it, Hat, SPAN |
 |
Text detection |
east, pixel_link, craft_pytorch |
 |
Text recognition |
etl, crnn.pytorch, deep-text-recognition-benchmark, easyocr, paddleocr, donut, ndlocr_text_recognition, paddleocr_v3 |
|
Time-series forecasting |
informer2020, timesfm, moirai, chronos2 |
 |
Vehicle recognition |
vehicle-attributes-recognition-barrier, vehicle-license-plate-detection-barrier |
 |
Vision language model |
llava, florence2, mobilevlm, llava-jp, qwen2_vl, qwen2.5_vl, qwen3_vl |
|
Commercial model |
acculus-pose |