VisTR: End-to-End Video Instance Segmentation with Transformers
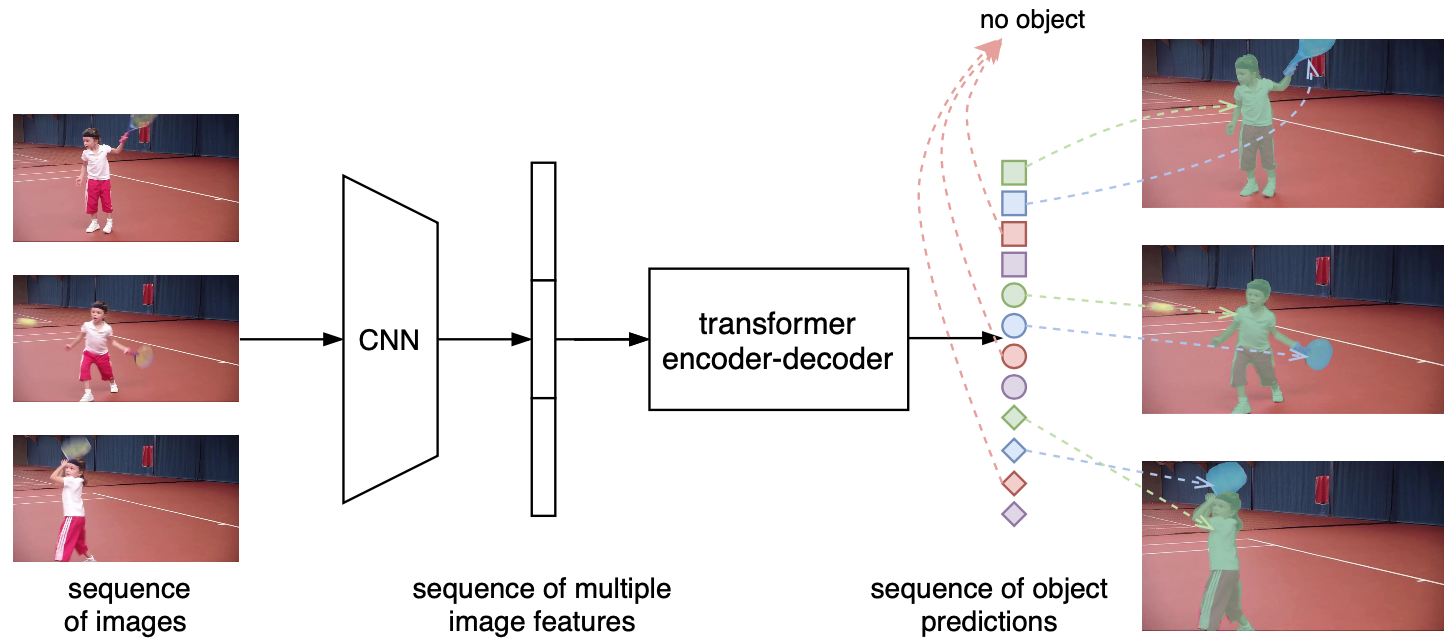
This is the official implementation of the VisTR paper:
Installation
We provide instructions how to install dependencies via conda. First, clone the repository locally:
git clone https://github.com/Epiphqny/vistr.git
Then, install PyTorch 1.6 and torchvision 0.7:
conda install pytorch==1.6.0 torchvision==0.7.0
Install pycocotools
conda install cython scipy
pip install -U 'git+https://github.com/cocodataset/cocoapi.git#subdirectory=PythonAPI'
pip install git+https://github.com/youtubevos/cocoapi.git#"egg=pycocotools&subdirectory=PythonAPI"
Compile DCN module(requires GCC>=5.3, cuda>=10.0)
cd models/dcn
python setup.py build_ext --inplace
Preparation
Download and extract 2019 version of YoutubeVIS train and val images with annotations from CodeLab or YoutubeVIS. We expect the directory structure to be the following:
VisTR
├── data
│   ├── train
│   ├── val
│   ├── annotations
│   │   ├── instances_train_sub.json
│   │   ├── instances_val_sub.json
├── models
...
Download the pretrained DETR models Google Drive BaiduYun(passcode:alge) on COCO and save it to the pretrained path.
Training
Training of the model requires at least 32g memory GPU, we performed the experiment on 32g V100 card. (As the training resolution is limited by the GPU memory, if you have a larger memory GPU and want to perform the experiment, please contact with me, thanks very much)
To train baseline VisTR on a single node with 8 gpus for 18 epochs, run:
python -m torch.distributed.launch --nproc_per_node=8 --use_env main.py --backbone resnet101/50 --ytvos_path /path/to/ytvos --masks --pretrained_weights /path/to/pretrained_path
Inference
python inference.py --masks --model_path /path/to/model_weights --save_path /path/to/results.json
Models
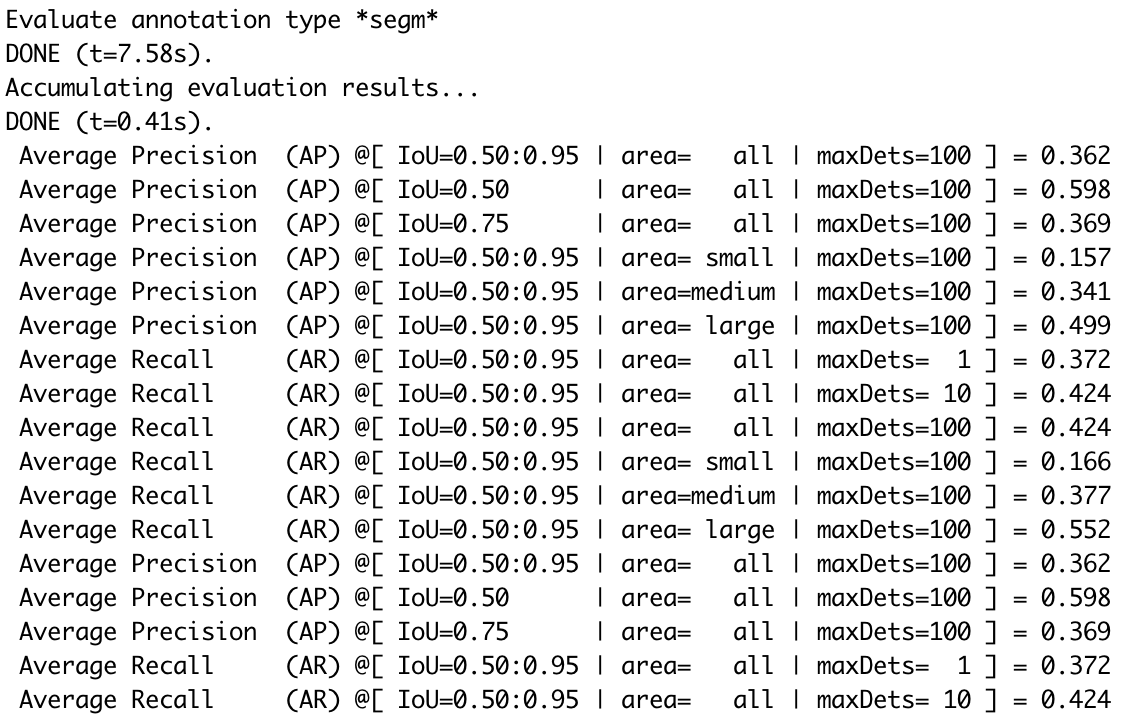
We provide baseline VisTR models, and plan to include more in future. AP is computed on YouTubeVIS dataset by submitting the result json file to the CodeLab system, and inference time is calculated by pure model inference time (without data-loading and post-processing).
name
backbone
FPS
mask AP
model
result json zip
detailed AP
0
VisTR
R50
69.9
36.2
1
VisTR
R101
57.7
40.1

License
VisTR is released under the Apache 2.0 license. Please see the LICENSE file for more information.
Acknowledgement
We would like to thank the DETR open-source project for its awesome work, part of the code are modified from its project.
Citation
Please consider citing our paper in your publications if the project helps your research. BibTeX reference is as follow.
@inproceedings{wang2020end,
  title={End-to-End Video Instance Segmentation with Transformers},
  author={Wang, Yuqing and Xu, Zhaoliang and Wang, Xinlong and Shen, Chunhua and Cheng, Baoshan and Shen, Hao and Xia, Huaxia},
  booktitle =  {Proc. IEEE Conf. Computer Vision and Pattern Recognition (CVPR)},
  year={2021}
}