Gradient Centralization
Gradient Centralization: A New Optimization Technique for Deep Neural Networks
Introduction
- Gradient Centralization (GC) is a simple and effective optimization technique for Deep Neural Networks (DNNs), which operates directly on gradients by centralizing the gradient vectors to have zero mean. It can both speedup training process and improve the final generalization performance of DNNs. GC is very simple to implement and can be easily embedded into existing gradient based DNN optimizers with only few lines of code. It can also be directly used to finetune the pre-trained DNNs. Please refer to the algorithm-GC to obtain the codes of more advanced optimizers.
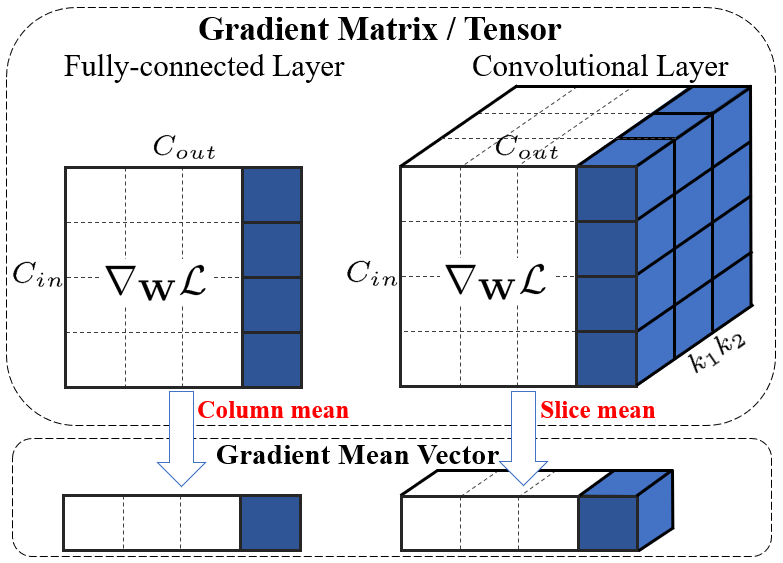
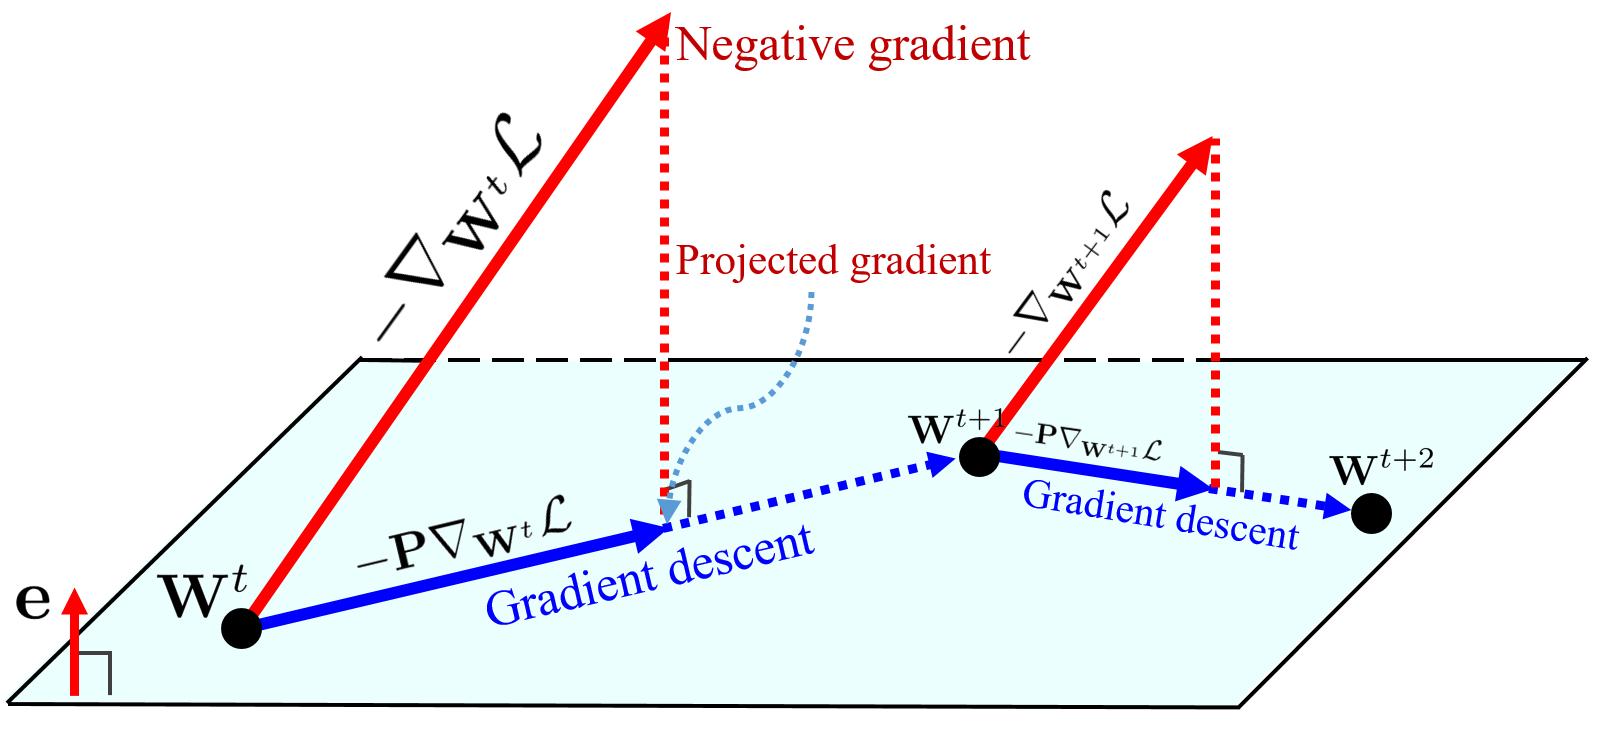
- GC can be viewed as a projected gradient descent method with a constrained loss function. The Lipschitzness of the constrained loss function and its gradient is better so that the training process becomes more efficient and stable. Our experiments on various applications, including
general image classification,fine-grained image classification,detection and segmentationandPerson ReIDdemonstrate that GC can consistently improve the performance of DNN learning.
- The optimizers are provided in the files:
SGD.py,Adam.pyandAdagrad.py, including SGD_GC, SGD_GCC, SGDW_GCC, Adam_GC, Adam_GCC, Adam_GCC2, AdamW_GCC, AdamW_GCC2 and Adagrad_GCC. The optimizers with "_GC" use GC for both Conv layers and FC layers, and the optimizers with "_GCC" use GC only for Conv layers. For adaptive learning rate methods, keeping mean of weight vector unchanged usually works better. Please refer to Adam_GCC2 and AdamW_GCC2. We can use the following codes to import SGD_GC:
from SGD import SGD_GC
Update
-
2020/04/07:Release a pytorch implementation of optimizers with GC, and provide some examples on classification task, including general image classification (Mini-ImageNet, CIFAR100 and ImageNet) and Fine-grained image classification (FGVC Aircraft, Stanford Cars, Stanford Dogs and CUB-200-2011).
-
2020/04/14:Release the code of GC on MMdetection and update some tables of experimental results.
-
2020/05/07:Release the code of GC on Person ReID and show some results on Market1501.
-
2020/08/08:Release the code of some advanced optimizers with GC.
Citation
@article{GradientCentra,
  title={Gradient-Centralization: A New Optimization Technique for Deep Neural Networks},
  author={Hongwei Yong and Jianqiang Huang and Xiansheng Hua and Lei Zhang},
  booktitle={the European Conference on Conputer Vision},
  year={2020}
}
Link to the other implementation of GC
- Gradient Centralization in TensorFlow
https://github.com/Rishit-dagli/Gradient-Centralization-TensorFlow - Gradient Centralization in Ranger optimizer
https://github.com/lessw2020/Ranger-Deep-Learning-Optimizer
Experiments
General Image Classification
- Mini-ImageNet
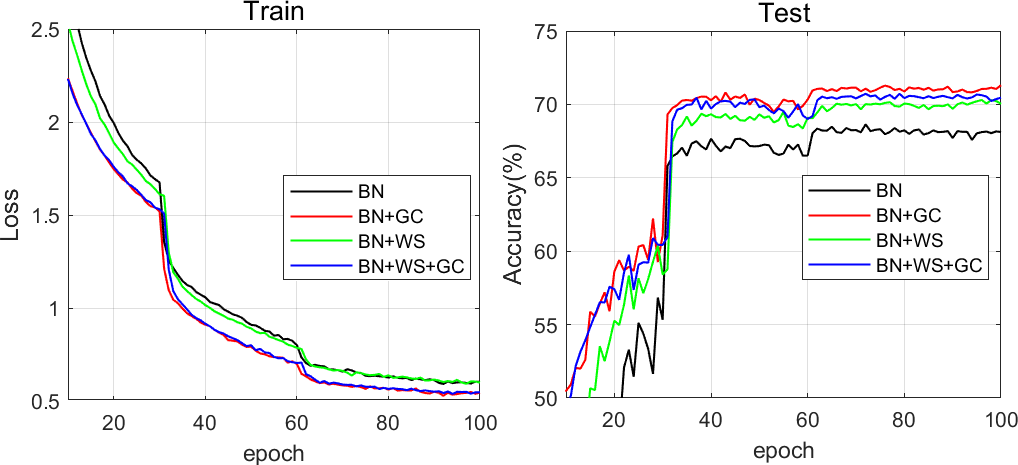
The codes are in GC_code/Mini_ImageNet. The split dataset can be downloaded from here (Google drive) or here (Baidu drive, safe code: 1681). The following figure is training loss (left) and testing accuracy (right) curves vs. training epoch on the Mini-ImageNet. The ResNet50 is used as the DNN model. The compared optimization techniques include BN, BN+GC, BN+WS and BN+WS+GC.
- CIFAR100
The codes are in GC_code/CIFAR100.
- ImageNet
The codes are in GC_code/ImageNet. The following table is the Top-1 error rates on ImageNet w/o GC and w/ GC:
| Backbone | R50BN | R50GN | R101BN | R101GN |
|---|---|---|---|---|
| w/o GC | 23.71 | 24.50 | 22.37 | 23.34 |
| w/ GC | 23.21 | 23.53 | 21.82 | 22.14 |
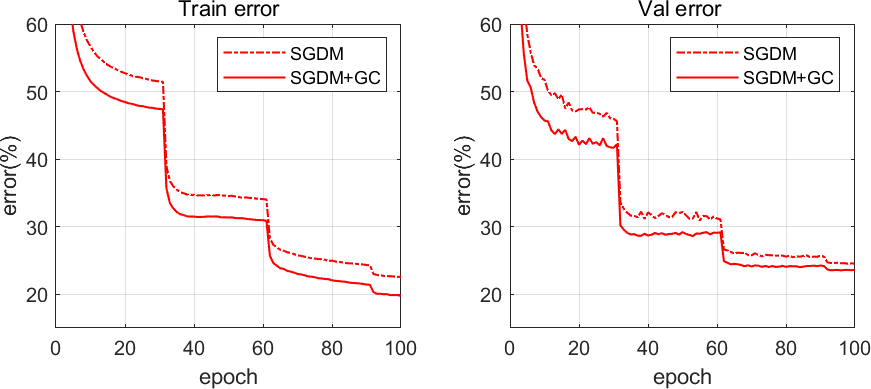
The following figure is the training error (left) and validation error (right) curves vs. training epoch on ImageNet. The DNN model is ResNet50 with GN.
Fine-grained Image Classification
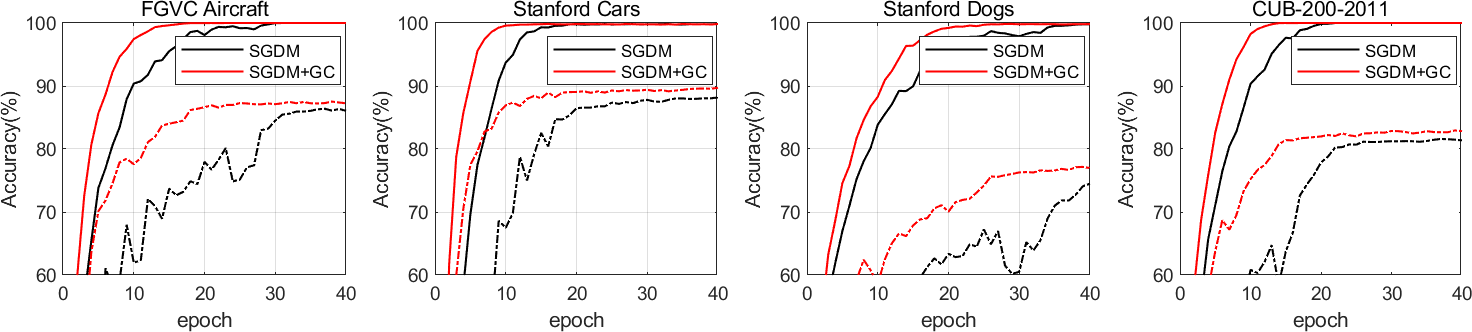
The codes are in GC_code/Fine-grained_classification. The preprocessed dataset can be downloaded from here. The following table is the testing accuracies on the four fine-grained image classification datasets with ResNet50:
| Datesets | FGVC Aircraft | Stanford Cars | Stanford Dogs | CUB-200-2011 |
|---|---|---|---|---|
| w/o GC | 86.62 | 88.66 | 76.16 | 82.07 |
| w/ GC | 87.77 | 90.03 | 78.23 | 83.40 |
The following figure is the training accuracy (solid line) and testing accuracy (dotted line) curves vs. training epoch on four fine-grained image classification datasets:
Objection Detection and Segmentation
The codes are in MMdetection. Please let SGD.py in MMdetection\tools\, and update MMdetection\tools\train.py. Then if you want use SGD_GC optimizer, just update optimizer in the configs file. For example, if we want use SGD_GC to optimize Faster_RCNN with ResNet50 backbone and FPN, we update the 151th line in MMdetection/configs/faster_rcnn_r50_fpn_1x.py. The following table is the detection results on COCO by using Faster-RCNN and FPN with various backbone models:
| Method | Backbone | AP | AP.5 | AP.75 | Backbone | AP | AP.5 | AP.75 |
|---|---|---|---|---|---|---|---|---|
| w/o GC | R50 | 36.4 | 58.4 | 39.1 | X101-32x4d | 40.1 | 62.0 | 43.8 |
| w/ GC | R50 | 37.0 | 59.0 | 40.2 | X101-32x4d | 40.7 | 62.7 | 43.9 |
| w/o GC | R101 | 38.5 | 60.3 | 41.6 | X101-64x4d | 41.3 | 63.3 | 45.2 |
| w/ GC | R101 | 38.9 | 60.8 | 42.2 | X101-64x4d | 41.6 | 63.8 | 45.4 |
The following table is the detection and segmentation results on COCO by using Mask-RCNN and FPN with various backbone models:
| Method | Backbone | APb | APb.5 | APb.75 | APm | APm.5 | APm.75 |
|---|---|---|---|---|---|---|---|
| w/o GC | R50 | 37.4 | 59.0 | 40.6 | 34.1 | 55.5 | 36.1 |
| w/ GC | R50 | 37.9 | 59.6 | 41.2 | 34.7 | 56.1 | 37.0 |
| w/o GC | R101 | 39.4 | 60.9 | 43.3 | 35.9 | 57.7 | 38.4 |
| w/ GC | R101 | 40.0 | 61.5 | 43.7 | 36.2 | 58.1 | 38.7 |
| w/o GC | X101-32x4d | 41.1 | 62.8 | 45.0 | 37.1 | 59.4 | 39.8 |
| w/ GC | X101-32x4d | 41.6 | 63.1 | 45.5 | 37.4 | 59.8 | 39.9 |
| w/o GC | X101-64x4d | 42.1 | 63.8 | 46.3 | 38.0 | 60.6 | 40.9 |
| w/ GC | X101-64x4d | 42.8 | 64.5 | 46.8 | 38.4 | 61.0 | 41.1 |
| w/o GC | R50 (4c1f) | 37.5 | 58.2 | 41.0 | 33.9 | 55.0 | 36.1 |
| w/ GC | R50 (4c1f) | 38.4 | 59.5 | 41.8 | 34.6 | 55.9 | 36.7 |
| w/o GC | R101GN | 41.1 | 61.7 | 44.9 | 36.9 | 58.7 | 39.3 |
| w/ GC | R101GN | 41.7 | 62.3 | 45.3 | 37.4 | 59.3 | 40.3 |
| w/o GC | R50GN+WS | 40.0 | 60.7 | 43.6 | 36.1 | 57.8 | 38.6 |
| w/ GC | R50GN+WS | 40.6 | 61.3 | 43.9 | 36.6 | 58.2 | 39.1 |
Person ReId
The codes are in PersonReId. Please let SGD.py in reid-strong-baseline\tools\, and update reid-strong-baseline\solver\build.py. For Market1501, please use SGD_GCC algorithm with
learning rate 0.03 or 0.02 and weight decay 0.002. For example, you can change the '.sh' file with the following codes:
python3 tools/train.py --config_file='configs/softmax_triplet_with_center.yml' MODEL.DEVICE_ID "('0')" DATASETS.NAMES "('market1501')" DATASETS.ROOT_DIR "('/home/yonghw/data/reid/')" OUTPUT_DIR "('out_dir/market1501/test')" SOLVER.OPTIMIZER_NAME "('SGD_GCC')" SOLVER.BASE_LR "(0.03)" SOLVER.WEIGHT_DECAY "(0.002)" SOLVER.WEIGHT_DECAY_BIAS "(0.002)"
The results of Market1501 without reranking are shown in the following table:
| Method | Backbone | MAP | Top 1 |
|---|---|---|---|
| Adam* | R18 | 77.8 | 91.7 |
| SGD_GCC | R18 | 81.3 | 92.7 |
| Adam* | R50 | 85.9 | 94.5 |
| SGD_GCC | R50 | 86.6 | 94.8 |
| Adam* | R101 | 87.1 | 94.5 |
| SGD_GCC | R101 | 87.9 | 95.0 |
The results with * are reported by the authors in reid-strong-baseline. Our reproduced results are slightly lower than the results provided by the authors.