Self-Supervised Learning with Vision Transformers
By Zhenda Xie*, Yutong Lin*, Zhuliang Yao, Zheng Zhang, Qi Dai, Yue Cao and Han Hu
This repo is the official implementation of "Self-Supervised Learning with Swin Transformers".
A important feature of this codebase is to include Swin Transformer as one of the backbones, such that we can evaluate the transferring performance of the learnt representations on down-stream tasks of object detection and semantic segmentation. This evaluation is usually not included in previous works due to the use of ViT/DeiT, which has not been well tamed for down-stream tasks.
It currently includes code and models for the following tasks:
Self-Supervised Learning and Linear Evaluation: Included in this repo. See get_started.md for a quick start.
Transferring Performance on Object Detection/Instance Segmentation: See Swin Transformer for Object Detection.
Transferring Performance on Semantic Segmentation: See Swin Transformer for Semantic Segmentation.
Highlights
- Include down-stream evaluation: the
first workto evaluate the transferring performance on down-stream tasks for SSL using Transformers - Small tricks: significantly less tricks than previous works, such as MoCo v3 and DINO
- High accuracy on ImageNet-1K linear evaluation: 72.8 vs 72.5 (MoCo v3) vs 72.5 (DINO) using DeiT-S/16 and 300 epoch pre-training
Updates
05/13/2021
- Self-Supervised models with DeiT-Small on ImageNet-1K (MoBY-DeiT-Small-300Ep-Pretrained, MoBY-DeiT-Small-300Ep-Linear) are provided.
- The supporting code and config for self-supervised learning with DeiT-Small are provided.
05/11/2021
Initial Commits:
- Self-Supervised Pre-training models on ImageNet-1K (MoBY-Swin-T-300Ep-Pretrained, MoBY-Swin-T-300Ep-Linear) are provided.
- The supported code and models for self-supervised pre-training and ImageNet-1K linear evaluation, COCO object detection and ADE20K semantic segmentation are provided.
Introduction
MoBY: a self-supervised learning approach by combining MoCo v2 and BYOL
MoBY (the name MoBY stands for MoCo v2 with BYOL) is initially described in arxiv, which is a combination of two popular self-supervised learning approaches: MoCo v2 and BYOL. It inherits the momentum design, the key queue, and the contrastive loss used in MoCo v2, and inherits the asymmetric encoders, asymmetric data augmentations and the momentum scheduler in BYOL.
MoBY achieves reasonably high accuracy on ImageNet-1K linear evaluation: 72.8% and 75.3% top-1 accuracy using DeiT and Swin-T, respectively, by 300-epoch training. The performance is on par with recent works of MoCo v3 and DINO which adopt DeiT as the backbone, but with much lighter tricks.
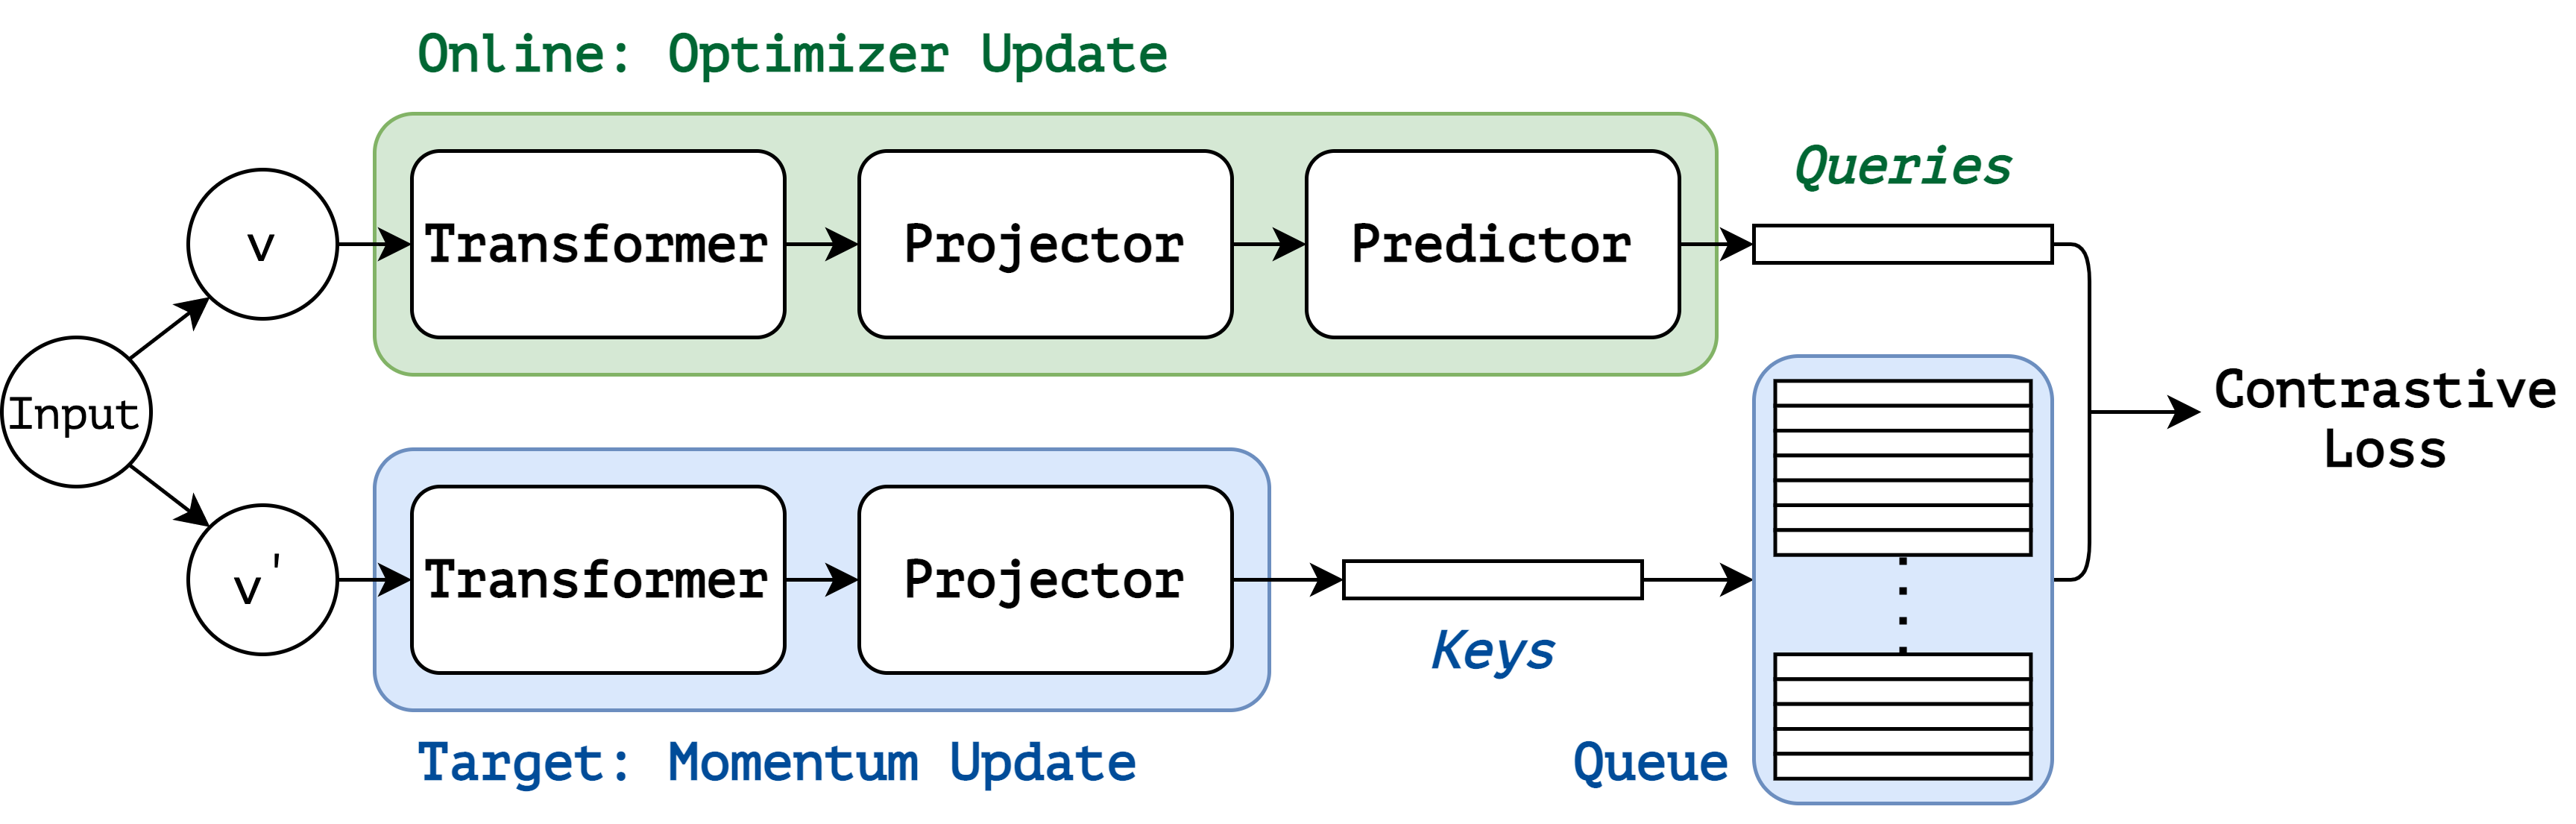
Swin Transformer as a backbone
Swin Transformer (the name Swin stands for Shifted window) is initially described in arxiv, which capably serves as a general-purpose backbone for computer vision. It achieves strong performance on COCO object detection (58.7 box AP and 51.1 mask AP on test-dev) and ADE20K semantic segmentation (53.5 mIoU on val), surpassing previous models by a large margin.
We involve Swin Transformer as one of backbones to evaluate the transferring performance on down-stream tasks such as object detection. This differentiate this codebase with other approaches studying SSL on Transformer architectures.
ImageNet-1K linear evaluation
| Method | Architecture | Epochs | Params | FLOPs | img/s | Top-1 Accuracy | Pre-trained Checkpoint | Linear Checkpoint |
|---|---|---|---|---|---|---|---|---|
| Supervised | Swin-T | 300 | 28M | 4.5G | 755.2 | 81.2 | Here | |
| MoBY | Swin-T | 100 | 28M | 4.5G | 755.2 | 70.9 | TBA | |
| MoBY1 | Swin-T | 100 | 28M | 4.5G | 755.2 | 72.0 | TBA | |
| MoBY | DeiT-S | 300 | 22M | 4.6G | 940.4 | 72.8 | GoogleDrive/GitHub/Baidu | GoogleDrive/GitHub/Baidu |
| MoBY | Swin-T | 300 | 28M | 4.5G | 755.2 | 75.3 | GoogleDrive/GitHub/Baidu | GoogleDrive/GitHub/Baidu |
-
1 denotes the result of MoBY which has adopted a trick from MoCo v3 that replace theLayerNorm layers before the MLP blocks by BatchNorm.
-
Access code for
baiduismoby.
Transferring to Downstream Tasks
COCO Object Detection (2017 val)
| Backbone | Method | Model | Schd. | box mAP | mask mAP | Params | FLOPs |
|---|---|---|---|---|---|---|---|
| Swin-T | Mask R-CNN | Sup. | 1x | 43.7 | 39.8 | 48M | 267G |
| Swin-T | Mask R-CNN | MoBY | 1x | 43.6 | 39.6 | 48M | 267G |
| Swin-T | Mask R-CNN | Sup. | 3x | 46.0 | 41.6 | 48M | 267G |
| Swin-T | Mask R-CNN | MoBY | 3x | 46.0 | 41.7 | 48M | 267G |
| Swin-T | Cascade Mask R-CNN | Sup. | 1x | 48.1 | 41.7 | 86M | 745G |
| Swin-T | Cascade Mask R-CNN | MoBY | 1x | 48.1 | 41.5 | 86M | 745G |
| Swin-T | Cascade Mask R-CNN | Sup. | 3x | 50.4 | 43.7 | 86M | 745G |
| Swin-T | Cascade Mask R-CNN | MoBY | 3x | 50.2 | 43.5 | 86M | 745G |
ADE20K Semantic Segmentation (val)
| Backbone | Method | Model | Crop Size | Schd. | mIoU | mIoU (ms+flip) | Params | FLOPs |
|---|---|---|---|---|---|---|---|---|
| Swin-T | UPerNet | Sup. | 512x512 | 160K | 44.51 | 45.81 | 60M | 945G |
| Swin-T | UPerNet | MoBY | 512x512 | 160K | 44.06 | 45.58 | 60M | 945G |
Citing MoBY and Swin
MoBY
@article{xie2021moby,
  title={Self-Supervised Learning with Swin Transformers},
  author={Zhenda Xie and Yutong Lin and Zhuliang Yao and Zheng Zhang and Qi Dai and Yue Cao and Han Hu},
  journal={arXiv preprint arXiv:2105.04553},
  year={2021}
}
Swin Transformer
@article{liu2021Swin,
  title={Swin Transformer: Hierarchical Vision Transformer using Shifted Windows},
  author={Liu, Ze and Lin, Yutong and Cao, Yue and Hu, Han and Wei, Yixuan and Zhang, Zheng and Lin, Stephen and Guo, Baining},
  journal={arXiv preprint arXiv:2103.14030},
  year={2021}
}
Getting Started
- For Self-Supervised Pre-training and Linear Evaluation with MoBY and Swin Transformer, please see get_started.md for detailed instructions.
- For Transferring Performance on Object Detection/Instance Segmentation, please see Swin Transformer for Object Detection.
- For Transferring Performance on Semantic Segmentation, please see Swin Transformer for Semantic Segmentation.