Deep Reinforcement Learning for mobile robot navigation in ROS Gazebo simulator. Using Twin Delayed Deep Deterministic Policy Gradient (TD3) neural network, a robot learns to navigate to a random goal point in a simulated environment while avoiding obstacles.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Language
Python
Category
Model Development
Subcategory
Fine-tuning
Stars
1,439
Forks
124
Contributors
1
Created date
2024-03-05
Updated date
2026-10-16
Stars in 1 day
-1
Stars in 7 days
-1
Rank
18,867
Previous rank
10,322
Rank change
-8,545
7-day stars rank
17,153
Previous 7-day stars rank
12,619
7-day stars rank change
-4,534
Total stars rank
8,361
Previous total stars rank
8,345
Total stars rank change
-16
Country
Japan
README summary
🐟 Evolutionary Optimization of Model Merging Recipes 🤗 Models | 👀 Demo | 📚 Paper | 📝 Blog | 🐦 Twitter This repository serves as a central hub for SakanaAI's Evolutionary Model Merge series, showcasing its releases and resources. It includes models and code for reproducing the evaluation presented in our paper. Look forward to more updates and additions coming soon. 1, GAIR/Abel-7B-002 | EvoLLM-JP-v1-10B | 10B | Microsoft Research License | EvoLLM-JP-v1-7B, shisa-gamma-7b-v1 | | EvoLLM-JP-A-v1-7B | 7B | Apache 2
. 0 | shisa-gamma-7b-v1, Arithmo2-Mistral-7B, GAIR/Abel-7B-002 | | EvoVLM-JP-v1-7B | 7B | Apache 2. 6-Mistral-7B, shisa-gamma-7b-v1 Comparing EvoLLM-JP w/ Source LLMs For details on the evaluation, please refer to Section 4. 2** | Comparing EvoVLM-JP w/ Existing VLMs For details on the evaluation, please see Section 4. 50 | | Heron BLIP Japanese StableLM Base 7B llava-620k | 14. 25** | \*1: Japanese Stable VLM cannot be evaluated using the JA-VG
-VQA-500 dataset because this model has used this dataset for training. Download fastext Model We use fastext to detect language for evaluation. Please download from this link and place it in your current directory. If you place the file in a directory other than the current directory, specify the path to the file using the environment variable. Install Libraries We conducted our tests in the following environment: Python Version 3. We cannot guarantee that it will work in other
environments. Run To launch evaluation, run the following script with a certain config. Acknowledgement We would like to thank the developers of the source models for their contributions and for making their work available. Our math evaluation code builds on the WizardMath repository, and we are grateful for their work.
Frequently asked questions
How many stars and forks are recorded?
SakanaAI/evolutionary-model-merge has 1,439 stars and 124 forks.
What is the repository rank?
SakanaAI/evolutionary-model-merge is ranked 18,867.
What language and category are recorded?
SakanaAI/evolutionary-model-merge has 1,439 stars, uses Python and belongs to Model Development.
Which repository is closest in rank?
SakanaAI/evolutionary-model-merge is compared with wenet-e2e/wespeaker, ranked 18,868 with 1,436 stars.
README
🐟 Evolutionary Optimization of Model Merging Recipes
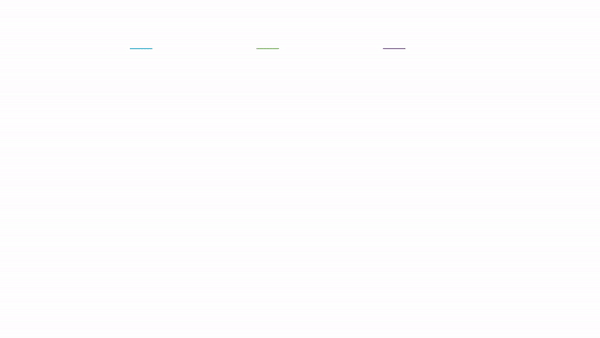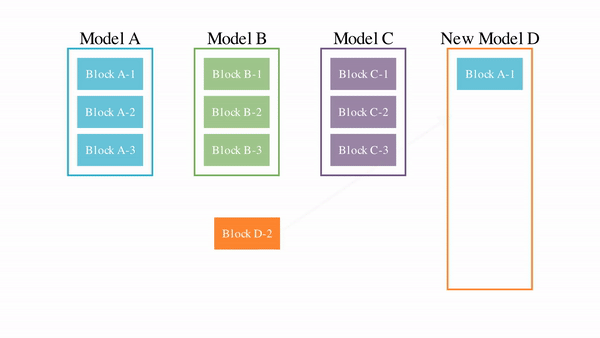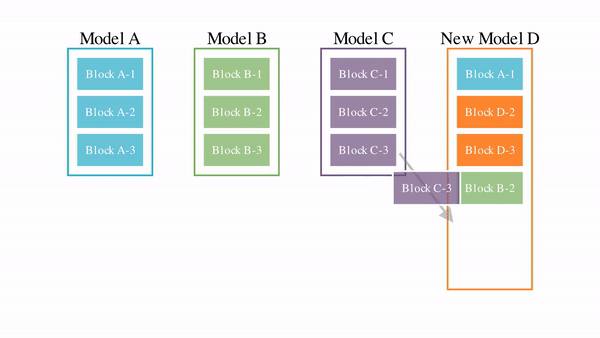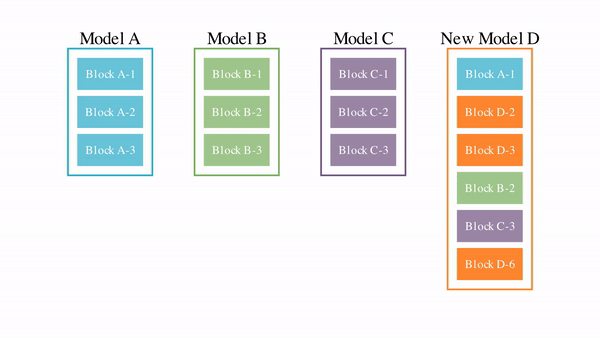
This repository serves as a central hub for SakanaAI's Evolutionary Model Merge series, showcasing its releases and resources. It includes models and code for reproducing the evaluation presented in our paper. Look forward to more updates and additions coming soon.
*1: Japanese Stable VLM cannot be evaluated using the JA-VG-VQA-500 dataset because this model has used this dataset for training.
Reproducing the Evaluation
1. Clone the Repo
git clone https://github.com/SakanaAI/evolutionary-model-merge.git
cd evolutionary-model-merge
2. Download fastext Model
We use fastext to detect language for evaluation. Please download lid.176.ftz from this link and place it in your current directory. If you place the file in a directory other than the current directory, specify the path to the file using the LID176FTZ_PATH environment variable.
3. Install Libraries
pip install -e .
We conducted our tests in the following environment: Python Version 3.10.12 and CUDA Version 12.3.
We cannot guarantee that it will work in other environments.
4. Run
To launch evaluation, run the following script with a certain config. All configs used for the paper are in configs.
python evaluate.py --config_path {path-to-config}
Acknowledgement
We would like to thank the developers of the source models for their contributions and for making their work available. Our math evaluation code builds on the WizardMath repository, and we are grateful for their work.