[!IMPORTANT] 🌟 Stay up to date at opendrivelab.com!
Table of Contents
-
⭐ GenAD: OpenDV Dataset (CVPR 2024 Hightlight)
-
Vista (NeurIPS 2024)
-
DriveLM (ECCV 2024 Oral)
-
DriveData Survey (SCIENTIA SINICA Informationis 2024)
NEWS
[ NEW❗️] 2024/09/08 We released a mini version of OpenDV-YouTube, containing 25 hours of driving videos. Feel free to try the mini subset by following instructions at OpenDV-mini!
2024/05/28 We released our latest research, Vista, a generalizable driving world model. It's capable of predicting high-fidelity and long-horizon futures, executing multi-modal actions, and serving as a generalizable reward function to assess driving behaviors.
2024/03/24 OpenDV-YouTube Update: Full suite of toolkits for OpenDV-YouTube is now available, including data downloading and processing scripts, as well as language annotations. Please refer to OpenDV-YouTube.
2024/03/15 We released the complete video list of OpenDV-YouTube, a large-scale driving video dataset, for GenAD project. Data downloading and processing script, as well as language annotations, will be released next week. Stay tuned.
2024/01/24
We are excited to announce some update to our survey and would like to thank John Lambert, Klemens Esterle from the public community for their advice to improve the manuscript.
GenAD: OpenDV Dataset
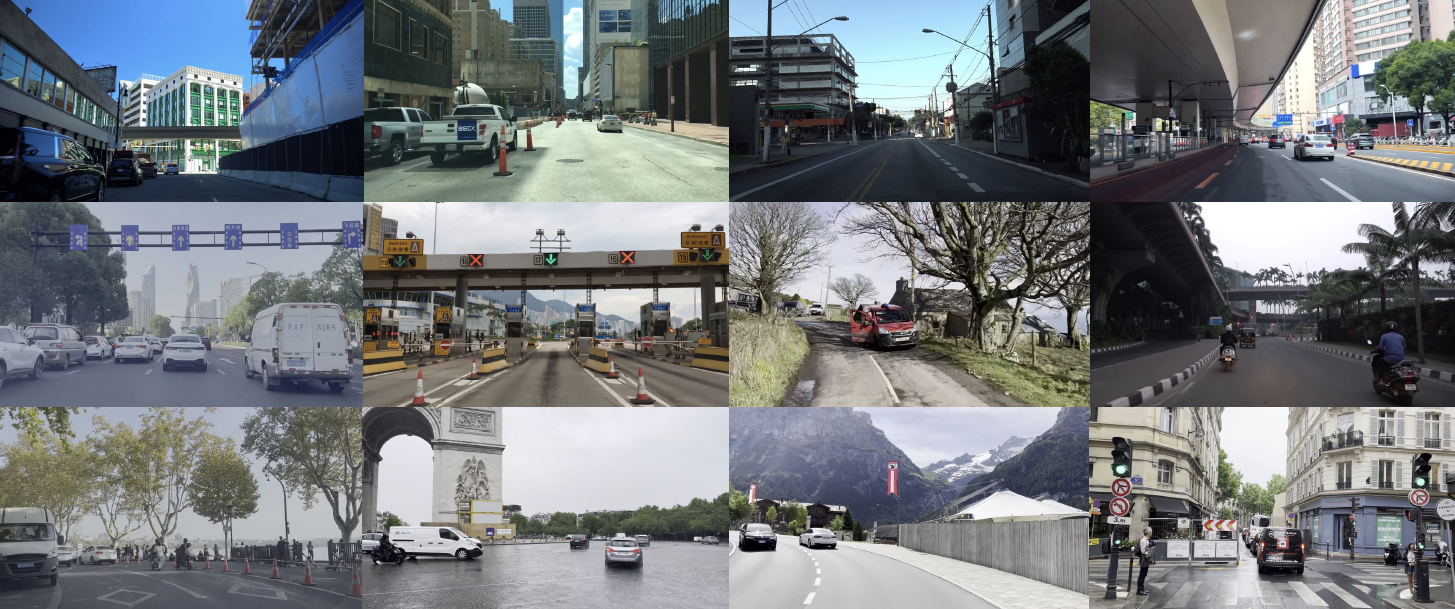
Examples of real-world driving scenarios in the OpenDV dataset, including urban, highway, rural scenes, etc.
⭐ Generalized Predictive Model for Autonomous Driving (CVPR 2024, Highlight)
Paper | Video | Poster | Slides
🎦 The Largest Driving Video dataset to date, containing more than 1700 hours of real-world driving videos and being 300 times larger than the widely used nuScenes dataset.
- Complete video list (under YouTube license): OpenDV Videos.
- The downloaded raw videos (
mostly 1080P) consume about3 TBstorage space. However, these hour-long videos cannot be directly applied for model training as they are extremely memory consuming. - Therefore, we preprocess them into conseductive images which are more flexible and efficient to load during training. Processed images consumes about
24 TBstorage space in total. - It's recommended to set up your experiments on a small subset, say 1/20 of the whole dataset. An official mini subset is also provided and you can refer to OpenDV-mini for details. After stablizing the training, you can then apply your method on the whole dataset and hope for the best 🤞.
- The downloaded raw videos (
- [ New❗️] Mini subset: OpenDV-mini.
- A mini version of
OpenDV-YouTube. The raw videos consume about44 GBof storage space and the processed images will consume about390 GBof storage space.
- A mini version of
- Step-by-step instruction for data preparation: OpenDV-YouTube.
- Language annotation for OpenDV-YouTube: OpenDV-YouTube-Language.
Quick facts:
- Task: large-scale video prediction for driving scenes.
- Data source:
YouTube, with careful collection and filtering process. - Diversity Highlights: 1700 hours of driving videos, covering more than 244 cities in 40 countries.
- Related work: GenAD
Accepted at CVPR 2024, Highlight Note: Annotations for other public datasets in OpenDV-2K will not be released since we randomly sampled a subset of them in training, which are incomplete and hard to trace back to their origins (i.e., file name). Nevertheless, it's easy to reproduce the collection and annotation process on your own following our paper.
@inproceedings{yang2024genad,
  title={Generalized Predictive Model for Autonomous Driving},
  author={Jiazhi Yang and Shenyuan Gao and Yihang Qiu and Li Chen and Tianyu Li and Bo Dai and Kashyap Chitta and Penghao Wu and Jia Zeng and Ping Luo and Jun Zhang and Andreas Geiger and Yu Qiao and Hongyang Li},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition},
  year={2024}
}
Vista
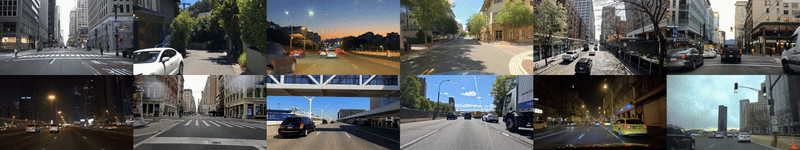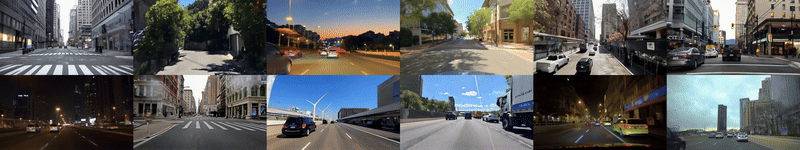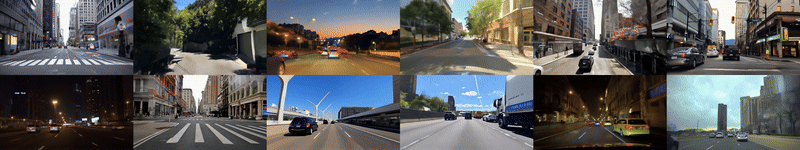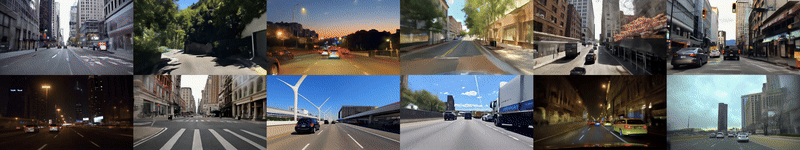
Simulated futures in a wide range of driving scenarios by Vista. Best viewed on demo page.
🌏 A Generalizable Driving World Model with High Fidelity and Versatile Controllability (NeurIPS 2024)
Quick facts:
- Introducing the world's first generalizable driving world model.
- Task: High-fidelity, action-conditioned, and long-horizon future prediction for driving scenes in the wild.
- Dataset:
OpenDV-YouTube,nuScenes - Code and model: https://github.com/OpenDriveLab/Vista
- Video Demo: https://vista-demo.github.io
- Related work: Vista, GenAD
@inproceedings{gao2024vista,
 title={Vista: A Generalizable Driving World Model with High Fidelity and Versatile Controllability},
 author={Shenyuan Gao and Jiazhi Yang and Li Chen and Kashyap Chitta and Yihang Qiu and Andreas Geiger and Jun Zhang and Hongyang Li},
 booktitle={Advances in Neural Information Processing Systems (NeurIPS)},
 year={2024}
}

@inproceedings{yang2024genad,
  title={{Generalized Predictive Model for Autonomous Driving}},
  author={Jiazhi Yang and Shenyuan Gao and Yihang Qiu and Li Chen and Tianyu Li and Bo Dai and Kashyap Chitta and Penghao Wu and Jia Zeng and Ping Luo and Jun Zhang and Andreas Geiger and Yu Qiao and Hongyang Li},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2024}
}
DriveLM
Introducing the First benchmark on Language Prompt for Driving.
Quick facts:
- Task: given the language prompts as input, predict the trajectory in the scene
- Origin dataset:
nuScenes,CARLA (To be released) - Repo: https://github.com/OpenDriveLab/DriveLM, https://github.com/OpenDriveLab/ELM
- Related work: DriveLM, ELM
- Related challenge: Driving with Language AGC Challenge 2024
DriveData Survey
Abstract
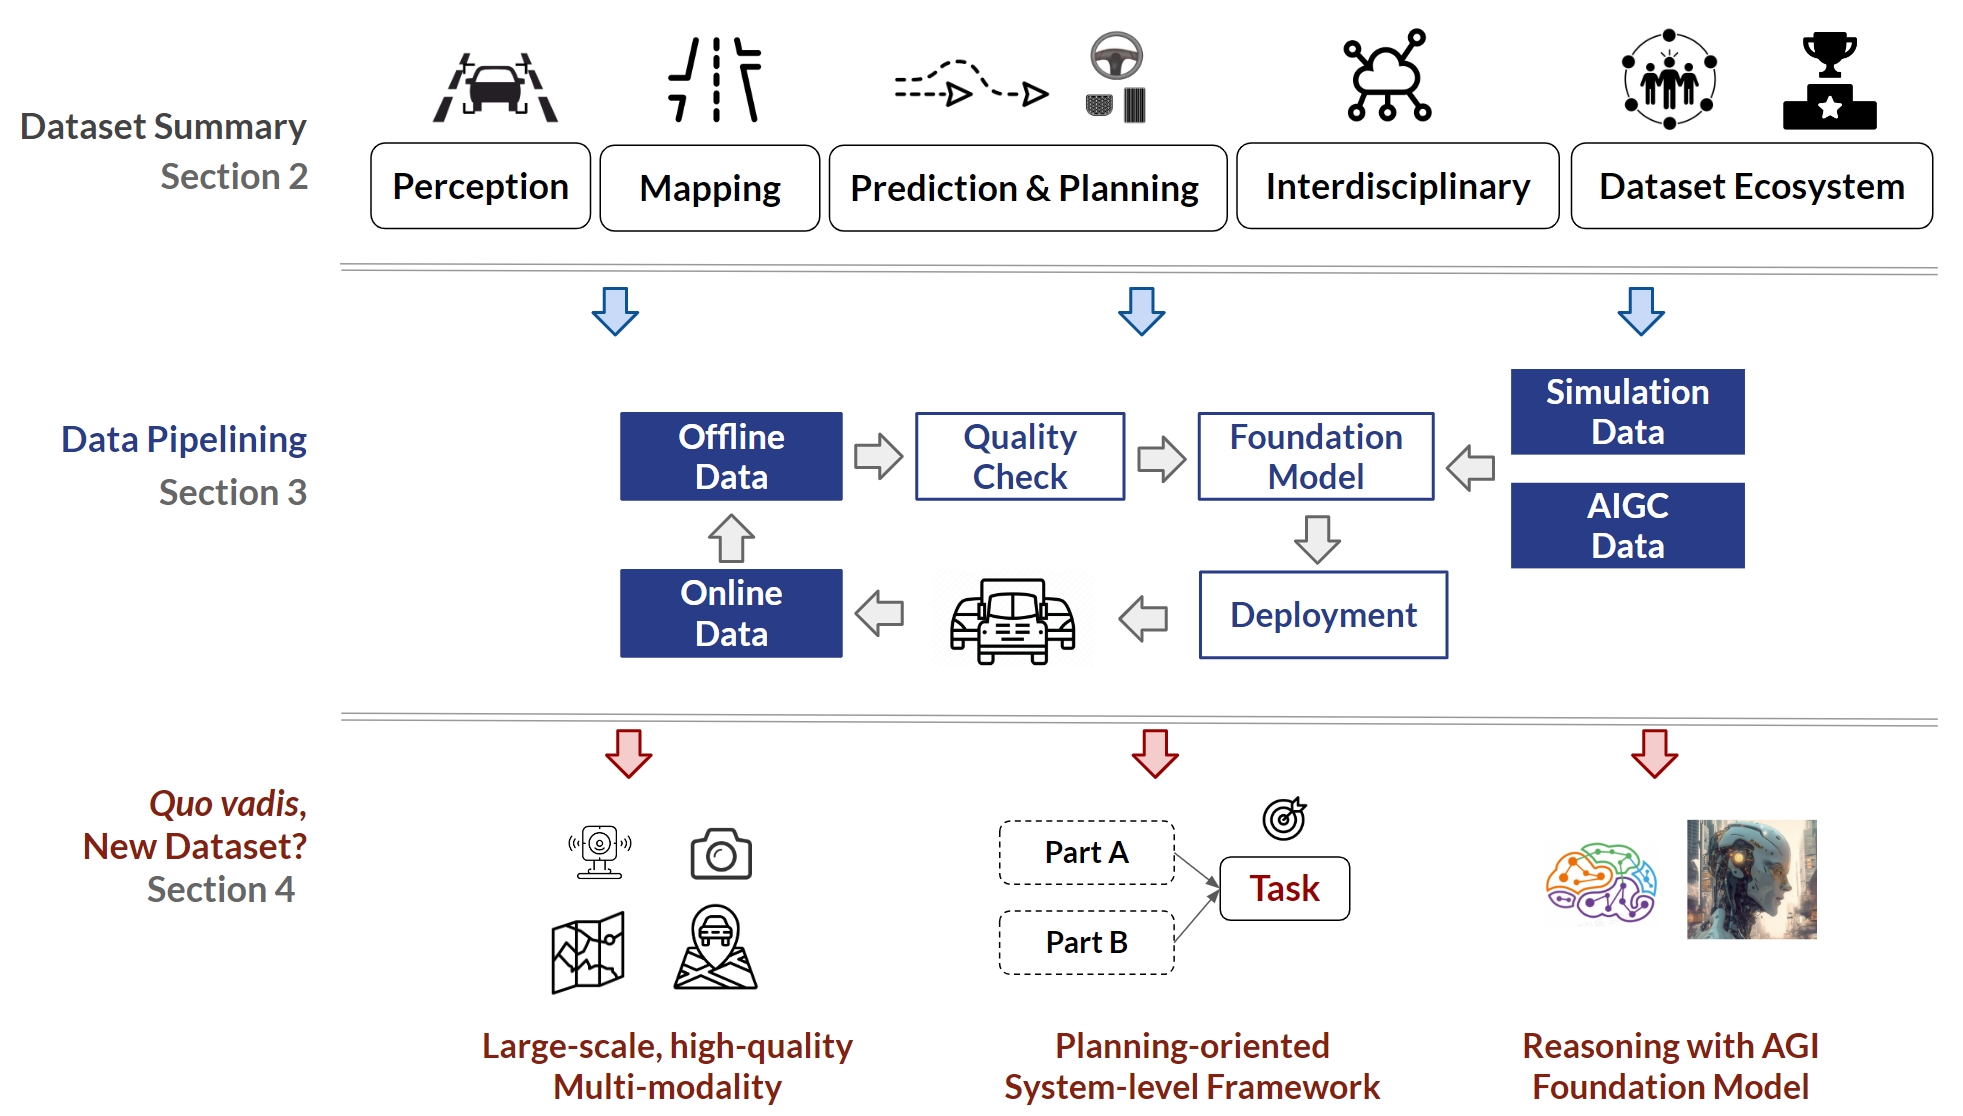
With the continuous maturation and application of autonomous driving technology, a systematic examination of open-source autonomous driving datasets becomes instrumental in fostering the robust evolution of the industry ecosystem. In this survey, we provide a comprehensive analysis of more than 70 papers on the timeline, impact, challenges, and future trends in autonomous driving dataset.
Open-sourced Data Ecosystem in Autonomous Driving: the Present and Future
- English Version
- Chinese Version
Accepted at SCIENTIA SINICA Informationis (中文版)
@article{li2024_driving_dataset_survey,
 title = {Open-sourced Data Ecosystem in Autonomous Driving: the Present and Future},
 author = {Hongyang Li and Yang Li and Huijie Wang and Jia Zeng and Huilin Xu and Pinlong Cai and Li Chen and Junchi Yan and Feng Xu and Lu Xiong and Jingdong Wang and Futang Zhu and Chunjing Xu and Tiancai Wang and Fei Xia and Beipeng Mu and Zhihui Peng and Dahua Lin and Yu Qiao},
 journal = {SCIENTIA SINICA Informationis},
 year = {2024},
 doi = {10.1360/SSI-2023-0313}
}
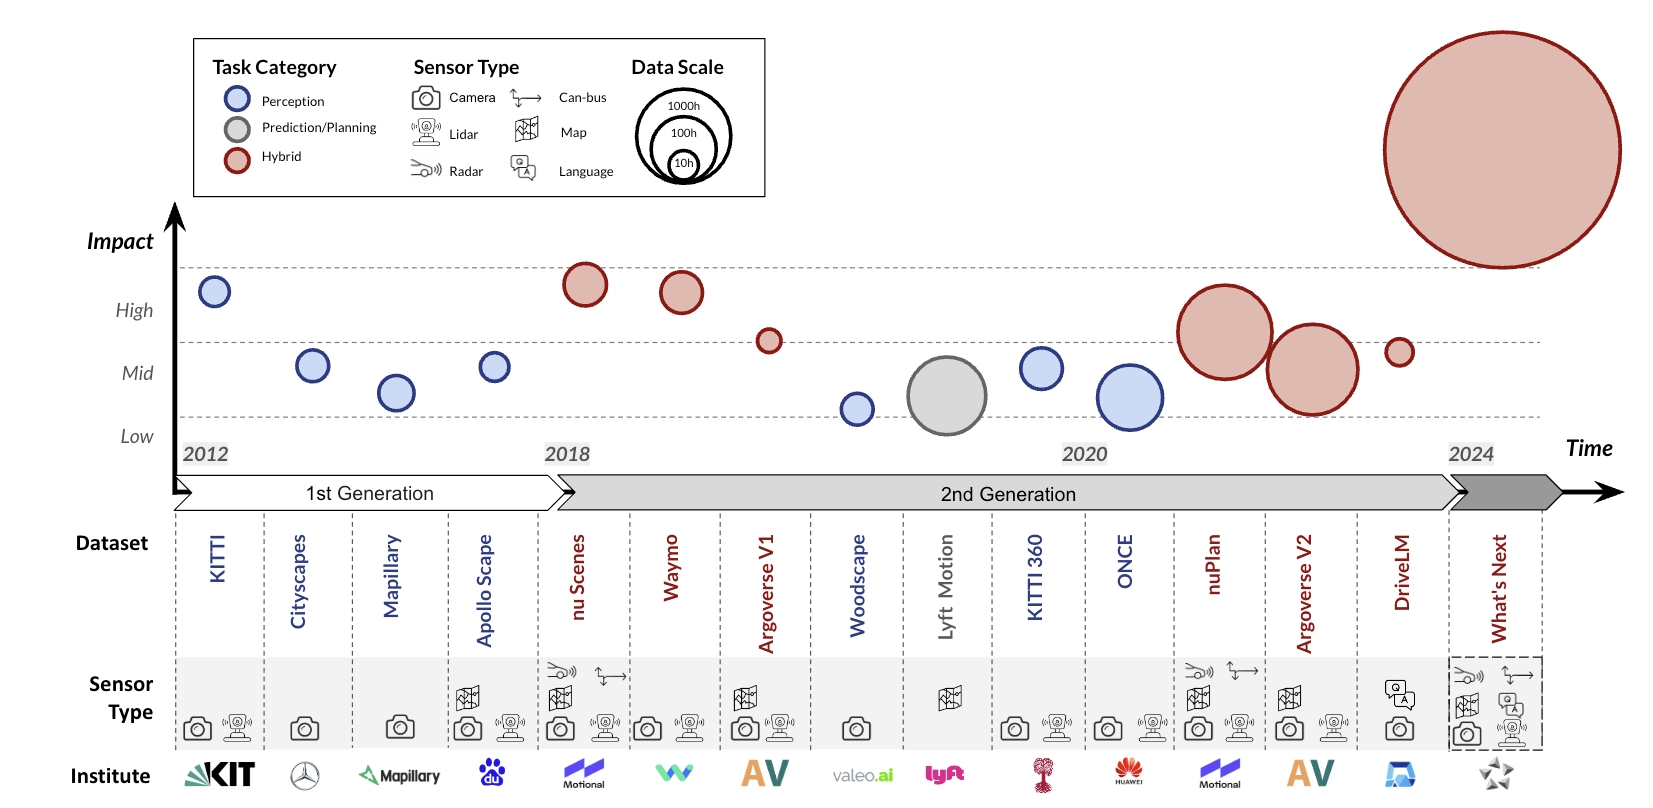
Current autonomous driving datasets can broadly be categorized into two generations since the 2010s. We define the Impact (y-axis) of a dataset based on sensor configuration, input modality, task category, data scale, ecosystem, etc.
Related Work Collection
We present comprehensive paper collections, leaderboards, and challenges.(Click to expand)
Challenges and Leaderboards
Title
Host
Year
Task
Entry
OpenDriveLab
CVPR2023
Perception / OpenLane Topology
111
Perception / Online HD Map Construction
Perception / 3D Occupancy Prediction
Prediction & Planning / nuPlan Planning
Waymo
CVPR2023
Perception / 2D Video Panoptic Segmentation
35
Perception / Pose Estimation
Prediction / Motion Prediction
Prediction / Sim Agents
CVPR2022
Prediction / Motion Prediction
128
Prediction / Occupancy and Flow Prediction
Perception / 3D Semantic Segmentation
Perception / 3D Camera-only Detection
CVPR2021
Prediction / Motion Prediction
115
Prediction / Interaction Prediction
Perception / Real-time 3D Detection
Perception / Real-time 2D Detection
Argoverse
CVPR2023
Prediction / Multi-agent Forecasting
81
Perception & Prediction / Unified Sensorbased Detection, Tracking, and Forecasting
Perception / LiDAR Scene Flow
Prediction / 3D Occupancy Forecasting
CVPR2022
Perception / 3D Object Detection
81
Prediction / Motion Forecasting
Perception / Stereo Depth Estimation
CVPR2021
Perception / Stereo Depth Estimation
368
Prediction / Motion Forecasting
Perception / Streaming 2D Detection
CARLA Autonomous Driving Challenge
CARLA Team, Intel
2023
Planning / CARLA AD Challenge 2.0
NeurIPS2022
Planning / CARLA AD Challenge 1.0
19
NeurIPS2021
Planning / CARLA AD Challenge 1.0
琶洲实验室
2023
感知 / 跨场景单目深度估计
感知 / 路侧毫米波雷达标定和目标跟踪
2022
感知 / 路侧三维感知算法
感知 / 街景图像店面招牌文字识别
ETH Zurich, University of Montreal,Motional
NeurIP2021
Perception / nuScenes Panoptic
11
ICRA2021
Perception / nuScenes Detection
456
Perception / nuScenes Tracking
Prediction / nuScenes Prediction
Perception / nuScenes LiDAR Segmentation
国家自然科学基金委信息科学部
2021
感知 / 交通标志检测
37
University of Tübingen
2012
Perception / Stereo, Flow, Scene Flow, Depth, Odometry, Object, Tracking, Road, Semantics
5,610
Perception Datasets
Dataset
Year
Diversity
Sensor
Annotation
Paper
Scenes
Hours
Region
Camera
Lidar
Other
2012
50
6
EU
Font-view
✗
GPS & IMU
2D BBox & 3D BBox
2016
EU
Font-view
✗
2D Seg
2016
112
Font-view
✗
2D Seg
2016
Global
Street-view
✗
2D Seg
2017
36
12
EU
Front-view
✗
GPS & CAN-bus & Event Camera
2016
103
2.5
AS
Front-view
✗
GPS & IMU
3D BBox & 2D Seg
2018
6984
77
NA
Front-view
✗
Language
2018
104
NA
Front-view
✓
GPS & IMU & CAN-bus
2D BBox
2018
182
AS
Front-view
✗
2D Seg
2019
50
6
EU
✗
✓
3D Seg
2019
Global
360°
✓
GPS & IMU & CAN-bus
3D BBox & 2D Seg
2019
42
AS
Front-view
✓
2019
67
10
EU
Front-view
✓
GPS & IMU & Infrared Camera
2019
55
AS
Front-view
✓
3D BBox
2019
850
283.3
NA
Front-view
✓
Language & 3D BBox
2019
10714
Sim
360°
✗
Language
2019
6
NA
Front-view
✗
2D BBox
2019
13
AS & NA
360°
✓
IMU
2019
700
AS
Front-view
✗
2D BBox
2019
160
0.77
NA
Front-view
✓
GPS & IMU
2020
5.6
EU
360°
✓
GPS & IMU & CAN-bus
3D BBox & 2D Seg
2020
30
0.3
NA
Front-view
✗
Radar
3D BBox
2019
Global
Front-view
✗
2D BBox
2019
Front-view
✗
GPS & IMU
2019
Front-view
✗
2D Seg
2020
AS
✗
✓
GPS & IMU
3D Seg
2020
4
NA
✗
✓
3D Seg
2021
22
EU
Front-view
✗
2D BBox & Topology
2021
Sim
Front-view
✗
Language
2021
1250
20.9
AS
Front-view
✗
GPS
Language
2021
179
NA
360°
✓
GPS & IMU
3D BBox
2022
Sim
360°
✓
2D Seg& 2D BBox
2022
Front-view
✗
Infrared Camera
2D Seg
2022
6
Sim
✗
✓
3D BBox
2022
Front-view
✗
2D Seg
2023
1000
5.5
AS & NA
360°
✗
3D Occ
2023
1473
8.2
EU
360°
✓
GPS & IMU & CAN-bus
3D BBox & 2D Seg
2019
1000
5.5
AS & NA
360°
✓
GPS & CAN-bus & Radar & HDMap
3D BBox & 3D Seg
2019
324k
320
NA
360°
✓
HDMap
3D BBox & 3D Seg
2019
1000
6.4
NA
360°
✓
2D BBox & 3D BBox
2020
366
2.5
EU
360°
✓
3D BBox & 3D Seg
2021
144
AS
360°
✓
3D BBox
2021
120
AS & NA
360°
✓
3D BBox
2022
1000
4
NA
360°
✓
HDMap
3D BBox
2023
1000
5.5
AS & NA
360°
✗
Language
Mapping Datasets
Dataset
Year
Diversity
Sensor
Annotation
Paper
Scenes
Frames
Camera
Lidar
Type
Space
Inst.
Track
2008
4
1224/1224
✗
PV
✓
✗
2017
20K/20K
✗
PV
✗
2017
6.4K
6.4K/128K
✗
PV
✓
✗
2018
133K/133K
✗
PV
✓
2018
235
115K/115K
✓
PV
✗
✗
2019
14
79K/100K
Front-view Image
✗
Laneline
PV
✓
✗
2020
10K/10K
✗
PV
✓
2020
150K/150K
✗
PV
✓
2021
100
10K/10K
✗
PV
✓
✗
2022
1K
200K/200K
✗
3D
✓
✓
2022
211K/211K
✗
3D
✓
2023
2K
72K/72K
Multi-view Image
✗
Lane Centerline, Lane Segment
3D
✓
✓
Prediction and Planning Datasets
Subtask
Input
Output
Evaluation
Dataset
Motion Prediction
Surrounding Traffic States
Spatiotemporal Trajectories of Single/Multiple Vehicle(s)
Displacement Error
Trajectory Planning
Motion States for Ego Vehicles, Scenario Cognition and Prediction
Trajectories for Ego Vehicles
Displacement Error, Safety, Compliance, Comfort
Path Planning
Maps for Road Network
Routes Connecting to Nodes and Links
Efficiency, Energy Conservation
OpenScene
The Largest up-to-date 3D Occupancy Forecasting dataset for visual pre-training.
Quick facts:
- Task: given the large amount of data, predict the 3D occupancy in the environment.
- Origin dataset:
nuPlan - Repo: https://github.com/OpenDriveLab/OpenScene
- Related work: OccNet
- Related challenge: 3D Occupancy Prediction Challenge 2023, Occupancy and Flow AGC Challenge 2024, Predictive World Model AGC Challenge 2024
OpenLane-V2 Update
Flourishing OpenLane-V2 with Standard Definition (SD) Map and Map Elements.
Quick facts:
- Task: given multi-view images and SD-map (also known as ADAS map) as input, build the driving scene on the fly without the aid of HD-map.
- Repo: https://github.com/OpenDriveLab/OpenLane-V2
- Related work: OpenLane-V2, TopoNet, LaneSegNet
- Related challenge: Lane Topology Challenge 2023, Mapless Driving AGC Challenge 2024