xLAM: A Family of Large Action Models to Empower AI Agent Systems.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Category
Models
Subcategory
Vision models
Keywords
3D, Computer vision, Image production
Stars
640
Forks
12
Contributors
1
Created date
2023-04-05
Updated date
2026-10-07
Stars in 1 day
0
Stars in 7 days
0
Rank
15,670
Previous rank
15,478
Rank change
-192
7-day stars rank
15,114
Previous 7-day stars rank
15,119
7-day stars rank change
5
Total stars rank
15,973
Previous total stars rank
15,949
Total stars rank change
-24
Country
USA
README summary
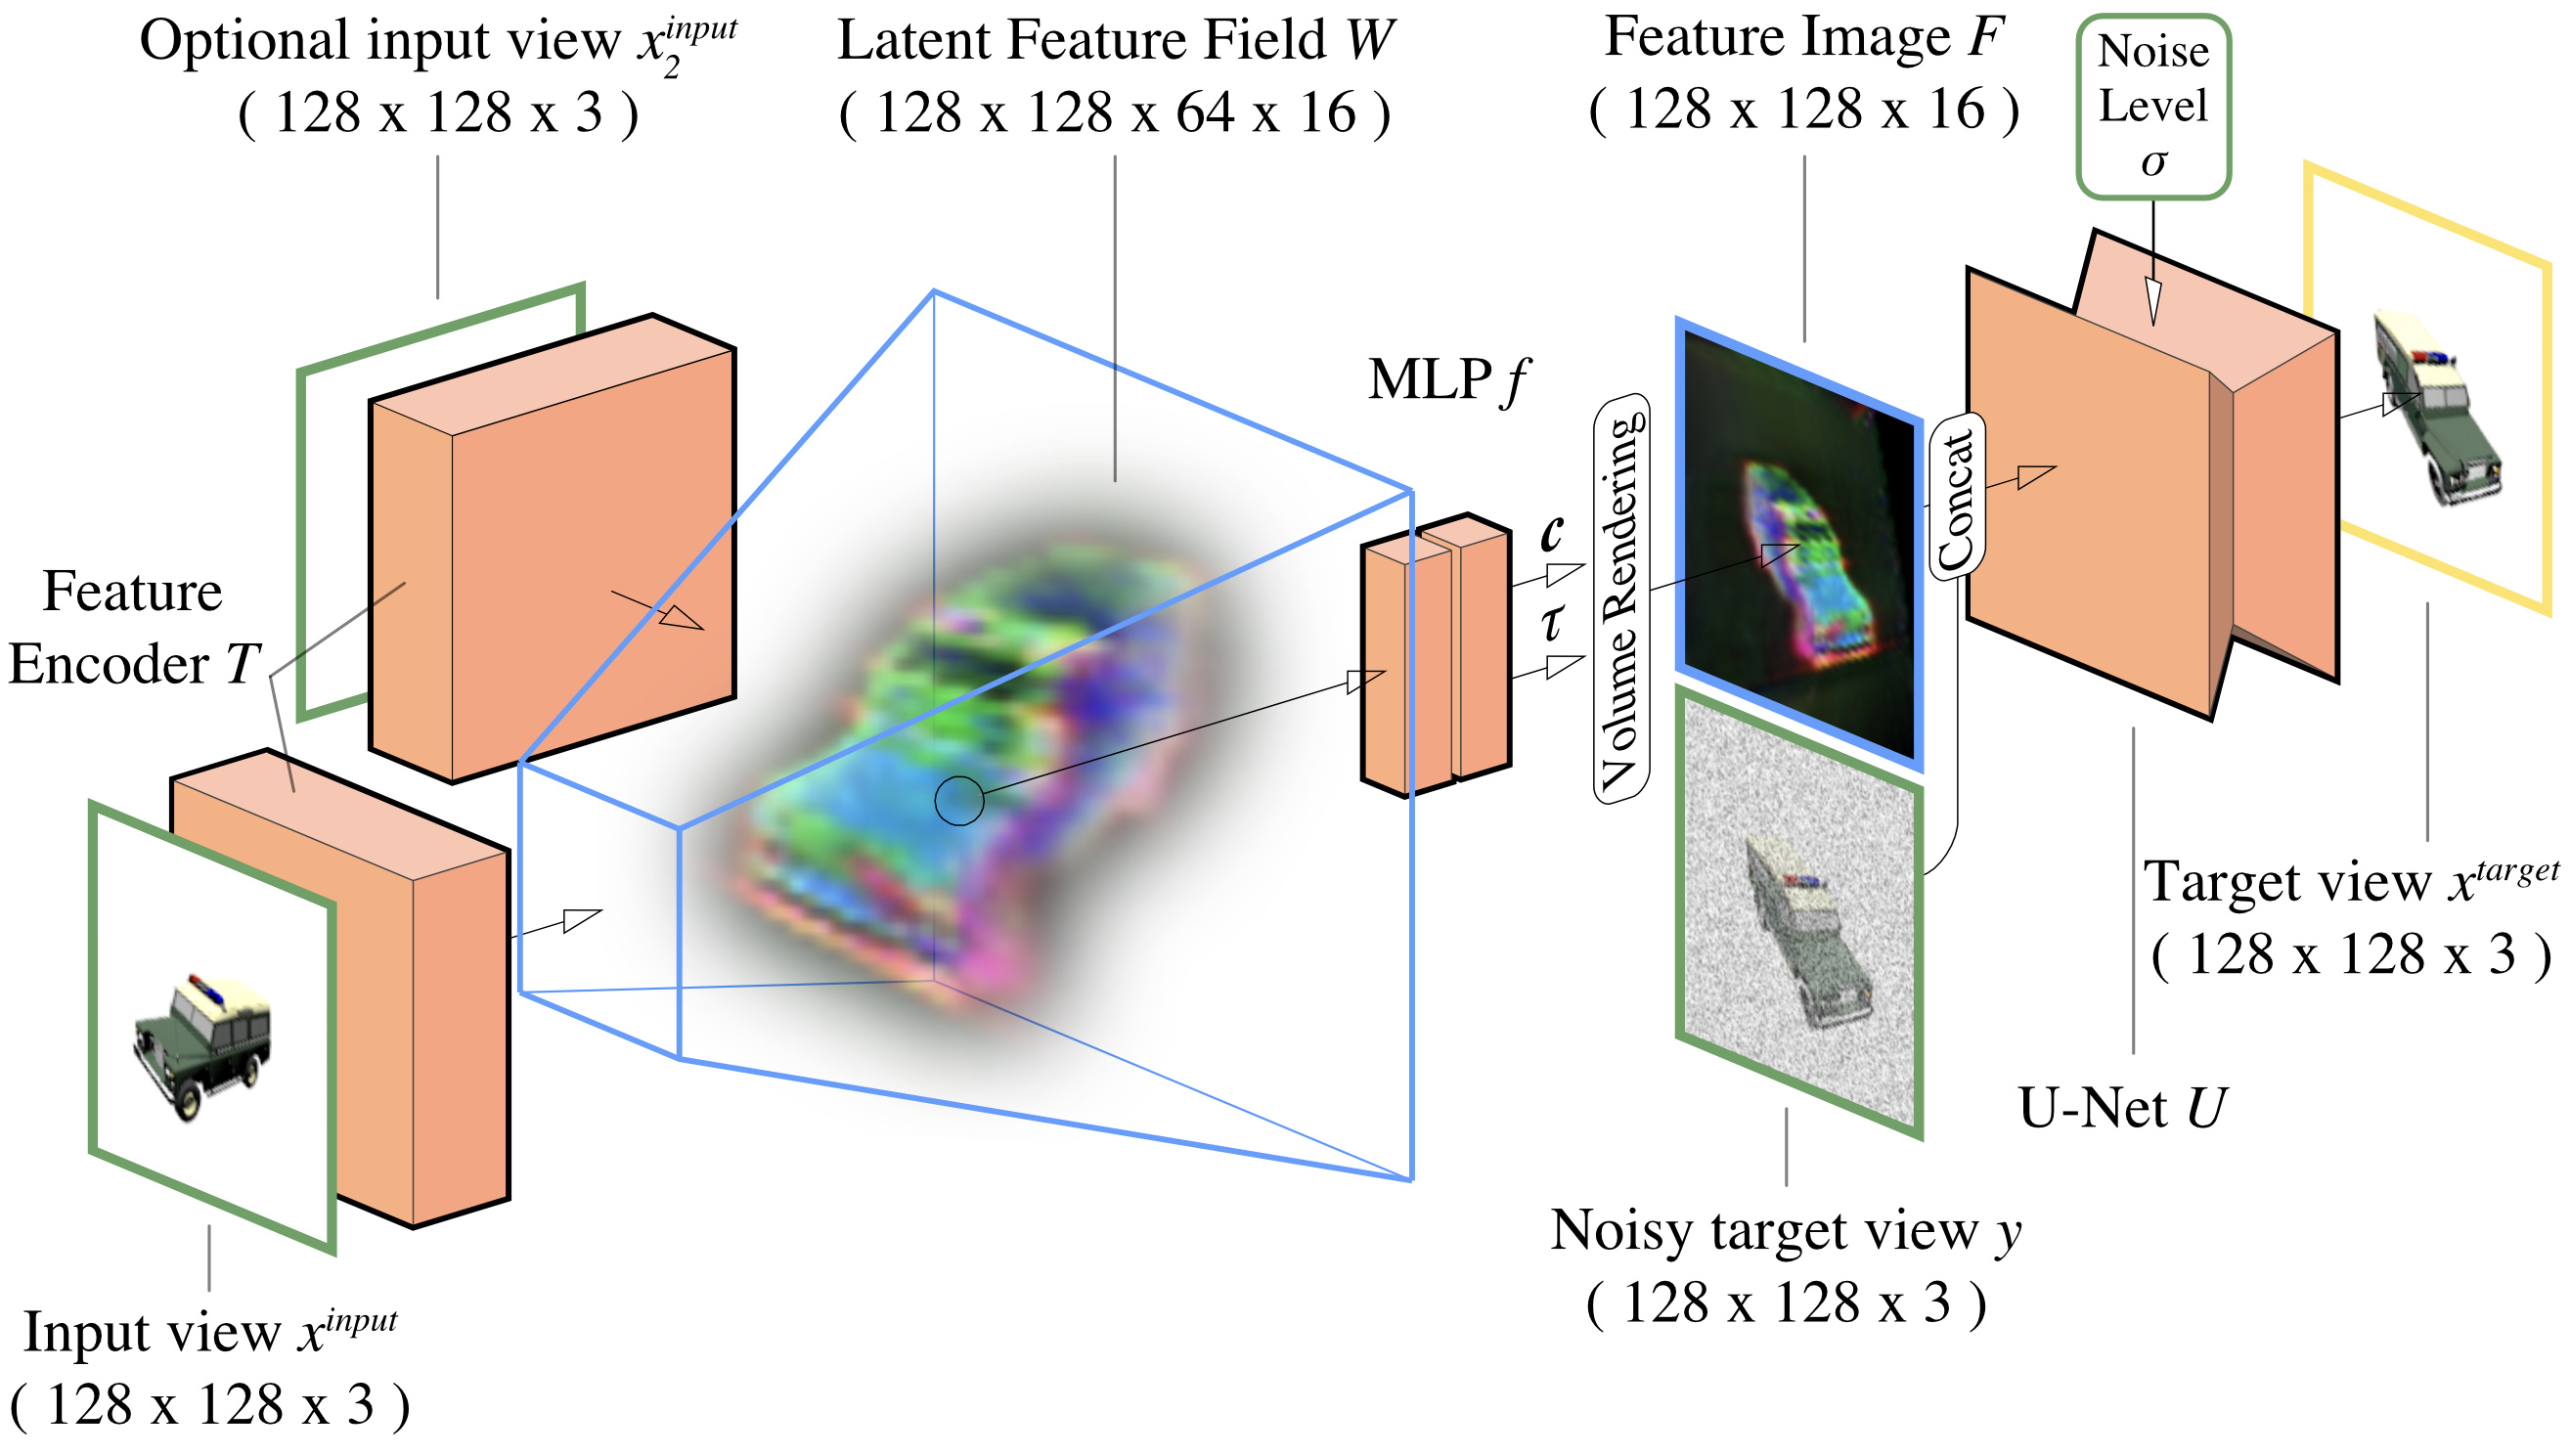
GeNVS: Generative Novel View Synthesis with 3D-Aware Diffusion Models Official PyTorch implementation coming soon **Generative Novel View Synthesis with 3D-Aware Diffusion Models** Eric R. Bergman*, Jeong Joon Park*, Axel Levy, Miika Aittala, Shalini De Mello, Tero Karras, Gordon Wetzstein Abstract: *We present a diffusion-based model for 3D-aware generative novel view synthesis from as few as a single input image. Our model samples from the distribution of possible renderings consistent with the input and, even in the
presence of ambiguity, is capable of rendering diverse and plausible novel views. To achieve this, our method makes use of existing 2D diffusion backbones but, crucially, incorporates geometry priors in the form of a 3D feature volume. This latent feature field captures the distribution over possible scene representations and improves our method's ability to generate view-consistent novel renderings. In addition to generating novel views, our method has the ability to autoregressively synthesize 3D-consistent sequences. We demonstrate state-of
-the-art results on synthetic renderings and room-scale scenes; we also show compelling results for challenging, real-world objects. * For business inquiries, please visit our website and submit the form: NVIDIA Research Licensing
Frequently asked questions
How many stars and forks are recorded?
NVlabs/genvs has 640 stars and 12 forks.
What is the repository rank?
NVlabs/genvs is ranked 15,670.
Which repository is closest in rank?
NVlabs/genvs is compared with Vision-CAIR/MiniGPT4-video, ranked 15,671 with 640 stars.
README
GeNVS: Generative Novel View Synthesis with 3D-Aware Diffusion Models
Official PyTorch implementation coming soon
Generative Novel View Synthesis with 3D-Aware Diffusion Models
Eric R. Chan*, Koki Nagano*, Matthew A. Chan*, Alexander W. Bergman*, Jeong Joon Park*, Axel Levy, Miika Aittala, Shalini De Mello, Tero Karras, Gordon Wetzstein
Abstract: We present a diffusion-based model for 3D-aware generative novel view synthesis from as few as a single input image. Our model samples from the distribution of possible renderings consistent with the input and, even in the presence of ambiguity, is capable of rendering diverse and plausible novel views. To achieve this, our method makes use of existing 2D diffusion backbones but, crucially, incorporates geometry priors in the form of a 3D feature volume. This latent feature field captures the distribution over possible scene representations and improves our method's ability to generate view-consistent novel renderings. In addition to generating novel views, our method has the ability to autoregressively synthesize 3D-consistent sequences. We demonstrate state-of-the-art results on synthetic renderings and room-scale scenes; we also show compelling results for challenging, real-world objects.