NeMo Gym


Requirements • Quick Start • Environment Tutorials • Available Environments • Documentation & Resources • Community & Support • Citations
NeMo Gym is a library for evaluating and improving models and agents using environments. NeMo Gym provides infrastructure to develop environments, scalably run evaluation and training, and a collection of popular benchmarks and training environments.
An environment is the complete system an agent interacts with to complete a task. It consists of a dataset (tasks to solve), an agent harness (how the model interacts with the world), a verifier (task completion scoring), and state (per-task execution context).
🎯 When to Use NeMo Gym
- You need to evaluate models or agents in stateful environments (e.g. code execution, tool calling, sandboxes)
- You want reproducible evaluation across teams using shared environments and verifiers
- You need to use environments at scale — multiple repeats per task, or thousands of concurrent requests for training
- You want to seamlessly transition between evaluation, agent optimization, and training
If you're scoring model outputs with a stateless check and don't need scale or training, a script is probably sufficient.
🏆 What NeMo Gym Provides
- Modular, extensible interfaces for agents, environments, tasks, and verifiers
- Environment hub of popular benchmarks and training environments
- Use your own agents or choose from built-in harnesses
- Scale to thousands of concurrent environments
- Train with the RL framework of your choice
- Optional OpenTelemetry tracing across the agent, model, and resources servers
- Battle-tested in production Nemotron training
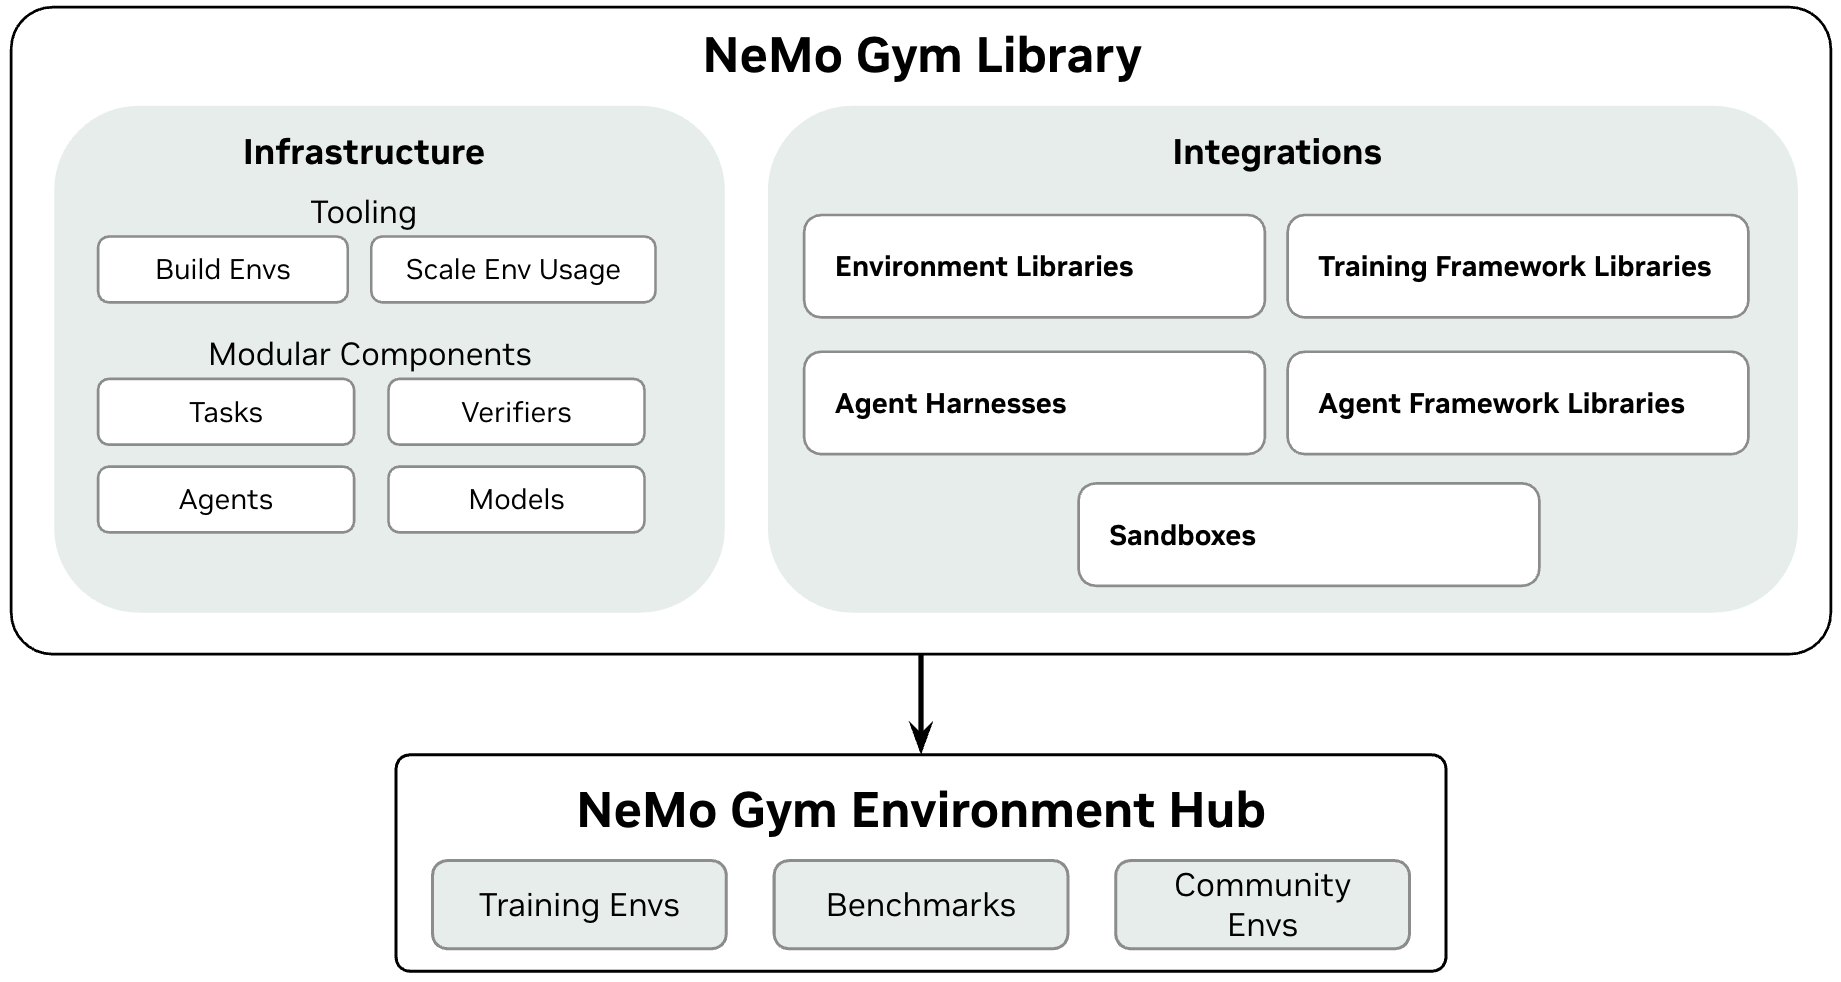
🌎 Ecosystem
NeMo Gym is a component of NVIDIA NeMo, a GPU-accelerated platform for training generative AI models and optimizing AI agents. NeMo Gym is integrated with the broader agentic ecosystem - see the Ecosystem page for more details.
Environment Libraries: Seamlessly combine environments and benchmarks from other libraries alongside NeMo Gym environments. Examples: Aviary • Harbor • OpenEnv • Reasoning Gym • Verifiers
Training Framework Libraries: Use environments for SFT and RL training. NeMo RL • Unsloth • VeRL
Agent Harnesses: Agent harnesses for evaluation and training available out of the box. Examples: OpenHands • Mini SWE Agent • LangGraph
📣 News
- [09/03/2026] Release v0.6.0:
Highlights:
- Use supported external agent harnesses during RL training while preserving exact token IDs across multi-step runs
- Compare fixed and routed model strategies on the same benchmark with Switchyard
- Validate and debug rollouts with automatic health checks, traces, and token, tool-call, turn, and latency diagnostics
- Evaluate multiple agents and datasets in one run with task-level harness routing
- Scale vLLM evaluation jobs across GPUs or Slurm nodes for higher rollout concurrency
Previous News
-
[08/06/2026] Release v0.5.0: Highlights:
- Seven sandbox providers: Docker, Daytona, ECS Fargate, Enroot, and OpenShell join OpenSandbox and Apptainer; large-scale OpenSandbox reliability significantly improved
- Four new agent harnesses: Codex CLI, KiloCode, RemoteAgent, and anyswe_agent
- Recompute rewards from stored rollouts without re-running inference with
gym eval reverify - Rollout observability joined end-to-end: model-call capture, agent observations, and a standardized
ng_trajectoryschema - 21 new environments across six domains: Agentic, Knowledge and instruction following, Long context, Science and coding, Translation and multilingual, and Reasoning
-
[07/01/2026] Release v0.4.0: Unified
gymCLI, BLADE diagnostics, agent skill evaluation, pluggable sandboxes, more agent harnesses (OpenCode, OpenClaw, Pi), hosted inference providers, and new benchmarks. -
[06/04/2026] Release v0.3.0: 70+ new environments, Nemotron 3 Ultra training datasets, VeRL integration, and out-of-the-box harnesses including Claude Code and Hermes.
📋 Requirements
NeMo Gym is designed to run on standard development machines:
| Hardware Requirements | Software Requirements |
|---|---|
| GPU: Not required for NeMo Gym library operation | |
| • GPU may be needed for specific resources servers or model inference (see individual server documentation) | Operating System: |
| • Linux (Ubuntu 20.04+, or equivalent) | |
| • macOS (11.0+ for x86_64, 12.0+ for Apple Silicon) | |
| • Windows (via WSL2) | |
| CPU: Any modern x86_64 or ARM64 processor (e.g., Intel, AMD, Apple Silicon) | Python: 3.13.14 or higher |
| RAM: Minimum 8 GB (16 GB+ recommended for larger environments) | Git: For cloning the repository |
| Storage: Minimum 5 GB free disk space for installation and basic usage | Internet Connection: Required for downloading dependencies and API access |
Additional Requirements
- API Keys: OpenAI API key with available credits (for the quickstart examples)
- Other model providers supported (Azure OpenAI, self-hosted models via vLLM)
- Ray: Automatically installed as a dependency (no separate setup required)
🚀 Quick Start
Requires Python 3.13.14+ on x86_64 or ARM64 (Linux, macOS, Windows via WSL2). No GPU required. See the Getting Started docs for a more comprehensive walkthrough.
Install NeMo Gym:
Requires uv and Python 3.13.14+.
git clone https://github.com/NVIDIA-NeMo/Gym.git
cd Gym
uv venv --python 3.13.14 && source .venv/bin/activate
uv sync
Configure your model:
This quickstart uses OpenAI. NeMo Gym supports local and hosted inference — see Configure Model for vLLM, Fireworks, OpenRouter, and others.
Create env.yaml in the project root:
policy_base_url: https://api.openai.com/v1
policy_api_key:
policy_model_name: gpt-4.1-2025-04-14
Run Evaluation
Run your agent on a set of tasks and score the results. This example uses a simple tool calling agent simple_agent with the mcqa (multiple-choice Q&A) environment and its included example data.
1. Start servers
NeMo Gym uses local servers to coordinate your model, agent, and task verification. Start them first:
gym env start \
    --resources-server mcqa \
    --model-type openai_model
You should see three server instances starting:
[1] mcqa (resources_servers/mcqa)
[2] mcqa_simple_agent (responses_api_agents/simple_agent)
[3] policy_model (responses_api_models/openai_model)
2. Evaluate your agent
In a new terminal, run your agent on a single task to verify everything works:
source .venv/bin/activate

gym eval run --no-serve \
    --agent mcqa_simple_agent \
    --input resources_servers/mcqa/data/example.jsonl \
    --output results/mcqa_rollouts.jsonl \
    --limit 5 \
    --num-repeats 1
You should see a progress bar followed by aggregate metrics:
Collecting rollouts: 100%|██████| 5/5 [01:22<00:00, 16.44s/it]

Key metrics for mcqa_simple_agent:
{
    "mean/reward": 0.8,
    "pass@1[avg-of-1]/accuracy": 80.0,
    "pass@1/accuracy": 80.0
}
Finished rollout collection! View results at:
Fully materialized inputs: results/mcqa_rollouts_materialized_inputs.jsonl
Rollouts: results/mcqa_rollouts.jsonl
Aggregate metrics: results/mcqa_rollouts_aggregate_metrics.json
For per-task pass rates, see the gym eval profile command.
Using the NeMo-Gym Container with VLM or Audio/Video Benchmarks
The NeMo-Gym container omits packages with bundled codec libraries
(opencv-python-headless, torchvision, torchaudio) to avoid shipping
royalty-bearing binaries. If you are running VLM or audio/video benchmarks
inside the container, restore them first:
bash docker/install_codec_deps.sh
This installs the packages at the same versions used during the container build. It is safe to run multiple times.
Next Steps
- Browse Environments — Browse available environments for evaluation and training.
- Agents — Explore available agent harnesses and learn how to integrate your own.
- Training — Improve your agent or model with RL or fine-tuning.
- Build Custom Environments — Create your own evaluation or training environments.
🧭 Environment Tutorials
Learn how to build custom environments through hands-on tutorials. Here are popular starting points:
| Name | Demonstrates |
|---|---|
| Single Step | Basic single-step tool calling |
| Multi Step | Multi-step tool calling |
| Session State | Session state management (in-memory) |
| Multi Reward | Multiple reward components for evaluation and multi-objective RL (e.g. GDPO) |
See all environment tutorials for additional patterns and advanced topics.
📦 Available Environments
Environments for training and evaluation.
Each resources server includes example data, configuration files, and tests. See each server's README for details.
The Dataset column links to publicly available datasets (e.g., on HuggingFace). A - means the train/validation data has not been publicly released yet, or that it is procedurally generated using a provided script. If no data is released yet, new data can be generated, or the environment can be used as a reference. Each server includes 5 example tasks in data/example.jsonl.
| Environment | Domain | Description | Value | Train | Validation | License | Config | Dataset |
|---|---|---|---|---|---|---|---|---|
| Aalcr | other | - | - | - | - | - | aalcr.yaml | - |
| Abstention | rlhf | Train models to abstain when unsure using three-tier reward on Nemotron-RL-QA-Abstention-v1 with LLM judge | Improve calibration by rewarding abstention over incorrect answers | ✓ | - | Creative Commons Attribution 4.0 International | abstention.yaml | Nemotron-RL-QA-Abstention-v1 |
| Aegis V4 Safety | safety | Multimodal response-safety evaluation with NVIDIA Nemotron 3 Content Safety (Aegis v4) | Classify target-model prompts and responses as safe or unsafe and report safety categories | - | - | - | aegis_v4_safety.yaml | - |
| Agentif | instruction_following | AgentIF instruction-following benchmark (707 agentic scenarios) scored with CSR/ISR using an LLM judge for llm/llm_conditional_check constraints and code exec for code constraints. | Improve instruction-following in agentic scenarios across unconditional, conditional, and example-driven constraint dimensions. | - | ✓ | - | agentif.yaml | - |
| Anyswe Agent | coding | SWE-bench run by a NeMo Fabric-selected harness inside each task environment. | Evaluate software-engineering agents with a harness-neutral Fabric lifecycle. | - | - | - | anyswe_nemo_fabric.yaml | - |
| Anyswe Agent | coding | SWE-bench run by Claude Code natively inside the task container. | Eval software engineering capabilities on SWE-bench with any Gym agent. | - | - | - | anyswe_claude_code.yaml | - |
| Anyswe Agent | coding | SWE-bench run by Hermes Agent natively inside the task container. | Eval software engineering capabilities on SWE-bench with any Gym agent. | - | - | - | anyswe_hermes.yaml | - |
| Anyswe Agent | coding | SWE-bench run by OpenClaw natively inside the task container. | Eval software engineering capabilities on SWE-bench with any Gym agent. | - | - | - | anyswe_openclaw.yaml | - |
| Anyswe Agent | coding | SWE-bench run by OpenCode inside the task container. | Eval software engineering capabilities on SWE-bench with any Gym agent. | - | - | - | anyswe_opencode.yaml | - |
| Anyswe Agent | coding | SWE-bench run by Pi inside the task container. | Eval software engineering capabilities on SWE-bench with any Gym agent. | - | - | - | anyswe_pi.yaml | - |
| Anyswe Agent | coding | SWE-bench run by the Cline CLI natively inside the task container. | Eval software engineering capabilities on SWE-bench with any Gym agent. | - | - | - | anyswe_cline.yaml | - |
| Anyterminal Agent | coding | Terminal Bench run by a NeMo Fabric harness inside the task sandbox. | Evaluate terminal-task agents through a harness-neutral Fabric lifecycle. | - | - | - | anyterminal_nemo_fabric.yaml | - |
| Anyterminal Agent | coding | Terminal Bench run by claude-code natively inside the task container. | Evaluate terminal-task capabilities on Terminal Bench with any Gym agent. | - | - | - | anyterminal_claude_code.yaml | - |
| Anyterminal Agent | coding | Terminal Bench run by OpenClaw natively inside the task container. | Evaluate terminal-task capabilities on Terminal Bench with any Gym agent. | - | - | - | anyterminal_openclaw.yaml | - |
| Anyterminal Agent | coding | Terminal Bench run by Terminus-2 natively inside the task container. | Evaluate terminal-task capabilities on Terminal Bench with any Gym agent. | - | - | - | anyterminal_terminus_2.yaml | - |
| Anyterminal Agent | coding | Terminal Bench run by the Hermes agent inside the task container. | Evaluate terminal-task capabilities on Terminal Bench with any Gym agent. | - | - | - | anyterminal_hermes.yaml | - |
| Arc Agi | knowledge | Solve puzzles designed to test intelligence. See https://arcprize.org/arc-agi. | Improve puzzle-solving capabilities. | - | ✓ | - | arc_agi.yaml | - |
| Arena | rlhf | LMArena proxy v2 chat evaluation benchmark | Measure general chat quality via win rate against baseline responses | - | ✓ | - | lmarena_v2.yaml | - |
| Arena | rlhf | LMArena proxy v3 chat evaluation benchmark | Measure general chat quality via win rate against baseline responses | - | ✓ | - | lmarena_v3.yaml | - |
| Arena Judge | - | - | - | - | - | arena_judge.yaml | - | |
| Asr With Pc | other | ASR with WER scoring (standard, case-sensitive, punctuation+capitalization) | Improve transcription quality with structural detail | - | - | - | asr_with_pc.yaml | - |
| Assaybench | knowledge | AssayBench -- rank the hit genes of a CRISPR screen from its plain-text description (arXiv:2605.10876) | Tests whether a model can link mechanistic biology to measured phenotypic outcomes, scored with the paper's adjusted nDCG | - | - | - | assaybench.yaml | - |
| Bbq | safety | BBQ comparative QA with Answer and Explanation Quality checks | Evidence-grounded and fairness-safe comparative reasoning | - | - | - | bbq.yaml | - |
| Bigcodebench | coding | Verifies model-generated Python solutions against the BigCodeBench unittest suite. | Improve practical, library-rich Python coding capabilities. | - | - | - | bigcodebench.yaml | - |
| Bird Sql | coding | Text-to-SQL with execution-based evaluation on BIRD dev (1534 SQLite tasks). Binary reward from unordered result-set equality. | Improve text-to-SQL capabilities on BIRD's realistic dev split using execution-based binary reward without an LLM judge. | - | - | - | bird_sql.yaml | - |
| Blackjack | games | Blackjack. Model hits or stands. Reward +1 win, 0 draw, -1 loss/bust. | Example gymnasium-style multi-step environment | - | - | - | blackjack.yaml | - |
| Browsecomp Advanced Harness | agent | Model uses search tools to satisfy a user query. | Measure agentic search capability | - | - | - | browsecomp_advanced_harness.yaml | - |
| Bunsenbench Chemistry Mcq | knowledge | Public BunsenBench chemistry multiple-choice benchmark verifier | Measure chemistry MCQ reasoning with source and taxonomy breakdowns | - | - | - | bunsenbench_chemistry_mcq.yaml | - |
| Calendar | agent | Multi-turn calendar scheduling dataset. User states events and constraints in natural language; model schedules events to satisfy all constraints. | Improve multi-turn instruction following capabilities | ✓ | ✓ | Apache 2.0 | calendar.yaml | Nemotron-RL-agent-calendar_scheduling |
| Calendar | agent | Multi-turn calendar scheduling dataset. User states events and constraints in natural language; model schedules events to satisfy all constraints. | Improve multi-turn instruction following capabilities | ✓ | ✓ | Creative Commons Attribution 4.0 International | calendar_v2.yaml | Nemotron-RL-Instruction-Following-Calendar-v2 |
| Circle Click | other | Click on circles in images | Improve visual grounding and spatial reasoning | - | - | - | circle_click.yaml | - |
| Circle Count | other | Count circles of a given color in images | Improve visual counting and color recognition | - | - | - | circle_count.yaml | - |
| Citation If | instruction_following | Citation instruction-following reward checker | Train models to follow citation format instructions in search-grounded synthesis tasks | - | - | - | citation_if.yaml | - |
| Code Fim | coding | Code Fill-in-the-Middle judged by HumanEval-Infilling test suite (single_line, multi_line, random_span, random_span_light) | Improve Python code-infilling capabilities (prefix + completion + suffix) | - | - | - | code_fim.yaml | - |
| Code Gen | coding | Model must submit the right code to solve a problem | Improve competitive coding capabilities | ✓ | ✓ | Apache 2.0 | code_gen.yaml | nemotron-RL-coding-competitive_coding |
| Competitive Coding Challenges | coding | Execution of competitive programming competition questions | Improve competitive coding capabilities on contest-style problems | - | - | - | competitive_coding_challenges.yaml | - |
| Conversational Tool Use Simulation | agent | Conversational tool-use simulation environment. | - | - | - | - | conversational_tool_use_simulation.yaml | - |
| Critpt | other | Research-level physics problems scored by the Artificial Analysis API | Evaluate model performance on research-level physics reasoning | - | - | - | critpt.yaml | - |
| Deepsearchqa | knowledge | Grade DeepSearchQA single-answer and set-answer responses | Evaluate multi-step web research answers | - | - | - | deepsearchqa.yaml | - |
| Denovo Swe | - | - | - | - | - | denovo_swe_example.yaml | - | |
| Denovo Swe | - | - | ✓ | - | Creative Commons Attribution 4.0 International | denovo_swe_opencode.yaml | - | |
| Equivalence Llm Judge | agent | Short bash command generation questions with LLM-as-a-judge | Improve foundational bash and IF capabilities | ✓ | ✓ | GNU General Public License v3.0 | nl2bash-equivalency.yaml | - |
| Equivalence Llm Judge | knowledge | Short answer questions with LLM-as-a-judge | Improve knowledge-related benchmarks like GPQA / HLE | - | - | - | equivalence_llm_judge.yaml | - |
| Equivalence Rule | knowledge | Question - Answering with rule-based reward | Improve retrieval and counting capabilities | - | - | - | lc.yaml | - |
| Ether0 | knowledge | ether0 chemistry benchmark verifiers | Evaluate chemistry knowledge and reasoning with ether0 benchmark | - | ✓ | - | ether0.yaml | - |
| Evalplus | coding | Function-completion code judged by EvalPlus base + plus tests (HumanEval+, MBPP+) | Improve Python function-completion capabilities | - | - | - | evalplus.yaml | - |
| False Statement Judge | math | Sycophancy grader for prove-the-false-statement benchmarks, using MathArena's 0-2 judge rubric | Measure how often a model claims to prove a statement that is false as written | - | - | - | false_statement_judge.yaml | - |
| Finance Agent V2 | agent | Vals finance-agent-v2 tools (web/EDGAR/price/calculator) for financial research questions | Run the official Vals FABv2 agent tools at scale in NeMo Gym | - | - | - | finance_agent_v2.yaml | - |
| Finance Sec Search | agent | SEC EDGAR filing search for financial analysis questions | Enable LLMs to search and analyze SEC filings | - | - | - | finance_sec_search.yaml | - |
| Format Verification | instruction_following | Verify citation/reference markers in model responses via string matching | Improve instruction following for citation format adherence | ✓ | - | Apache 2.0 | citation_format.yaml | - |
| Format Verification | instruction_following | Verify freeform text formatting (bullets, headings, tables, etc.) via regex patterns | Improve instruction following for text formatting constraints | ✓ | - | Apache 2.0 | freeform_formatting.yaml | - |
| Frontierscience Judge | other | FrontierScience answer grading via single-pass LLM judge | Evaluate FrontierScience Olympiad short answers or Research rubric-scored answers | - | - | - | frontierscience_judge.yaml | - |
| Fukuyamabench | knowledge | FukuyamaBench organic reaction-mechanism pathway verifier | Evaluate step-by-step organic reaction mechanism prediction with FukuyamaBench | - | ✓ | - | fukuyamabench.yaml | - |
| Gdp Pdf | other | GDP.pdf: professional multimodal reasoning over real-world PDFs (contracts, filings, records) across ten domains, graded per atomic rubric criterion by an LLM judge | Measure document reasoning on the dense professional documents the economy runs on | - | - | - | gdp_pdf.yaml | - |
| Generative Reward Model | rlhf | Train GenRM to score and rank response pairs per-rubric and overall | - | ✓ | - | Apache 2.0 | genrm_train.yaml | - |
| Genrm Compare | rlhf | GenRM pairwise comparison for RLHF training | Compare multiple candidate responses using GenRM model | - | - | - | genrm_compare.yaml | - |
| Google Search | agent | Multi-choice question answering problems with search tools integrated | Improve knowledge-related benchmarks with search tools | ✓ | - | Apache 2.0 | google_search.yaml | Nemotron-RL-knowledge-web_search-mcqa |
| Gpqa Diamond | knowledge | GPQA Diamond multiple-choice question answering problems | Evaluate graduate-level scientific reasoning via MCQ verification | ✓ | - | MIT | gpqa_diamond.yaml | - |
| Graphwalks | other | Long-context graph-walks (BFS / parents) with F1-over-node-sets grading from openai/graphwalks | Improve long-context multi-step graph reasoning and adjacency-list traversal | - | - | - | graphwalks.yaml | - |
| Grl Sokoban | games | Single-box Sokoban in Gymnasium API style. | Model emits one move per turn until the puzzle is solved. | - | - | - | grl_sokoban.yaml | - |
| Grl Tetris | games | Tetris in Gymnasium API style. Model emits one or more moves per turn. | Multi-step Tetris environment | - | - | - | grl_tetris.yaml | - |
| Gui Coordinate | other | GUI coordinate grounding verifier for visual pointing tasks | Verify GUI coordinate predictions using smooth quadratic reward based on Euclidean distance | - | - | - | gui_coordinate.yaml | - |
| Gymnasium | other | Base class for Gymnasium-style servers. Not a standalone server. | Reusable base class for step/reset style environments | - | - | - | gymnasium.yaml | - |
| Harbor Agent | agent | Fast local smoketest task (trivial 1-turn task, no LLM judge) for iterating on the Gym<->Harbor bridge. | - | ✓ | - | - | harbor_agent_smoketest_docker.yaml | - |
| Harbor Agent | agent | Harbor integration for agent harnesses and environments. | Improve models in popular agentic environments supported by Harbor such as Terminus2. | - | - | - | harbor_agent_opensandbox.yaml | - |
| Harbor Agent | agent | Harbor integration for agent harnesses and environments. | Improve models in popular agentic environments supported by Harbor such as Terminus2. | ✓ | - | - | harbor_agent.yaml | - |
| Harbor Agent | agent | Harbor integration for agent harnesses and environments. | Improve models in popular agentic environments supported by Harbor such as Terminus2. | ✓ | - | - | harbor_agent_daytona.yaml | - |
| Hotpotqa Qa | knowledge | Short-answer QA with deterministic SQuAD-style + alternative-aware substring verification (HotpotQA closed-book). | Improve closed-book multi-hop question-answering accuracy. | - | - | - | hotpotqa_qa.yaml | - |
| Ifbench | instruction_following | IFBench instruction following evaluation using AllenAI's IFBench library (57 instruction types) | Improve IFBench instruction following | - | - | - | ifbench.yaml | - |
| Iheval | instruction_following | IHEval instruction-hierarchy benchmark (8 single-turn tasks — task execution, safety, tool use, rule following) scored with the upstream rule-based checkers. | Improve instruction-hierarchy following across aligned/conflict/reference settings, including native tool-use trajectories. | - | ✓ | - | iheval.yaml | - |
| Image Tools | agent | PivotRL verifier for VLM image-tool trajectories; scores one tool call against the demonstrated SFT action. | Improve per-turn image-tool decisions (which tool, which image, which region). | ✓ | ✓ | NVIDIA Internal Use Only, Do Not Distribute | image_tools_pivot.yaml | - |
| Imo Gradingbench | math | Four-class grading of math proofs — the policy model reads a problem plus a candidate proof and emits one of correct / almost / partial / incorrect as the last word. | Improve the IMO-GradingBench benchmark and proof-grading skill. | - | - | - | imo_gradingbench.yaml | - |
| Imo Proofbench Judge | math | IMO ProofBench grader using a strong LLM judge with the IMO 0-7 rubric | Score IMO-style proof submissions with a problem-specific grading rubric | - | - | - | imo_proofbench_judge.yaml | - |
| Indian Banking | agent | Indian retail-banking customer-support environment: a multi-turn dialog with an LLM-simulated customer over 33 deterministic banking tools (accounts, deposits, loans, cards, mandates, service requests), scored with partial credit against gold tool calls, final DB state, required disclosures and an NL-assertion judge. | Improve stateful multi-turn tool use, policy compliance and customer communication in a regulated domain. | ✓ | ✓ | Apache 2.0 | indian_banking.yaml | nemo-gym-indian-banking |
| Indirect Prompt Injection | safety | Indirect prompt injection resistance for multi-domain tool-use agents | Improve agentic security by teaching robustness against tool outputs containing malicious instructions | ✓ | ✓ | Apache 2.0 | indirect_prompt_injection.yaml | - |
| Instruction Following | instruction_following | Instruction following datasets targeting IFEval and IFBench style instruction following capabilities | Improve IFEval and IFBench | ✓ | - | Apache 2.0 | instruction_following.yaml | Nemotron-RL-instruction_following |
| Interactive Browser | agent | Interactive browser environment — navigate/click/type/observe a live page; pluggable local (Playwright) or remote (CDP) browser backend. | - | - | - | - | interactive_browser.yaml | - |
| Inverse If | knowledge | Inverse IF instruction-following benchmark with per-task LLM judge | - | ✓ | - | TBD | inverse_if.yaml | - |
| Jailbreak Detection | safety | Jailbreak detection with Nemotron judge + combined reward | Improve Jailbreak Robustness and Safety/Security Behavior Guide Enforcement | - | - | - | jailbreak_detection_nemotron_combined_reward_tp8.yaml | - |
| Labbench2 Vlm | knowledge | labbench2 VLM benchmarks: scientific figure/table QA (figqa2, tableqa2), protocol troubleshooting (protocolqa2), LLM-as-judge | Measure scientific reasoning on figures, tables, and lab protocols | - | ✓ | - | labbench2_vlm.yaml | - |
| Lc Niah | knowledge | Answer-correctness reward gated by low reasoning/input overlap | Reward correct answers while discouraging copying the prompt into reasoning | - | - | - | lc_niah.yaml | - |
| Legal Agent Bench | agent | Harbor-native integration of Legal Agent Benchmark (LAB) | Improve legal-agent document review, drafting, and analysis capability | - | ✓ | - | legal_agent_bench.yaml | - |
| Litmus Agent | knowledge | Domain-agnostic answer verifier: extracts a model's final answer with an answer_format regex and scores it against expected_answer per an answer_type taxonomy (float, bool, string). For tool-using rows it can also host a sandbox-backed stateful Python code-execution tool. | Reusable scoring for any benchmark whose tasks reduce to "match the expected answer". | ✓ | - | Creative Commons Attribution 4.0 International | litmus_agent.yaml | Nemotron-RL-litmus-bench-v0.1 |
| Litmus Agent | knowledge | Domain-agnostic answer verifier: extracts a model's final answer with an answer_format regex and scores it against expected_answer per an answer_type taxonomy (float, bool, string). For tool-using rows it can also host a sandbox-backed stateful Python code-execution tool. This variant backs the tool with the local Apptainer provider (no service or API key); swap to litmus_agent.yaml for the OpenSandbox provider. | Reusable scoring for any benchmark whose tasks reduce to "match the expected answer". | ✓ | - | Creative Commons Attribution 4.0 International | litmus_agent_apptainer.yaml | Nemotron-RL-litmus-bench-v0.1 |
| Longmemeval | long_context | LongMemEval long-term-memory QA (orig-session / JSON history / no-CoT) scored by an LLM judge with the upstream per-question-type rubrics. | Improve long-horizon memory recall, temporal reasoning, knowledge updating and abstention over multi-session chat history. | - | ✓ | - | longmemeval.yaml | - |
| Longmt Eval | other | Document-level MT verifier for pg19 books using the SEGALE pipeline (ersatz segment → LASER2 embed → vecalign align → COMETKiwi score) | Rewards long-form book translation at the document level using reference-free COMETKiwi scores as the RL reward signal. | - | - | - | longmt_pg19.yaml | - |
| Longmt Eval | other | Document-level MT verifier for wmt24pp short docs using the SEGALE pipeline (ersatz segment → LASER2 embed → vecalign align → COMETKiwi score). | Rewards document-level translation quality across 55 language pairs using reference-free COMETKiwi scores as the RL reward signal. | - | - | - | longmt_wmt24pp.yaml | - |
| Longmt Eval | other | Document-level MT verifier using the SEGALE pipeline (ersatz segment → LASER2 embed → vecalign align → COMETKiwi score) | Rewards long-form translation quality at the document level using reference-free COMETKiwi scores as the RL reward signal. | - | - | - | longmt_eval.yaml | - |
| Math Advanced Calculations | agent | An instruction following math environment with counter-intuitive calculators | Improve instruction following capabilities in specific math environments | ✓ | - | Apache 2.0 | math_advanced_calculations.yaml | Nemotron-RL-math-advanced_calculations |
| Math Formal Lean | math | Lean4 formal proof verification environment | Improve formal theorem proving capabilities | ✓ | - | Apache 2.0 | nemotron_clean_easy.yaml | - |
| Math Formal Lean | math | Lean4 formal proof verification environment | Improve formal theorem proving capabilities | ✓ | - | Apache 2.0 | nemotron_first_try_hard.yaml | - |
| Math Formal Lean | math | Lean4 formal proof verification environment | Improve formal theorem proving capabilities | ✓ | - | Apache 2.0 | nemotron_medium_500.yaml | - |
| Math Formal Lean | math | Lean4 formal proof verification environment | Improve formal theorem proving capabilities | ✓ | - | Apache 2.0 | nemotron_very_easy.yaml | - |
| Math Formal Lean | math | Lean4 formal proof verification environment | Improve formal theorem proving capabilities | ✓ | - | MIT | math_formal_lean.yaml | - |
| Math Formal Lean | math | Lean4 formal proof verification environment with multi-turn self-correction | Improve formal theorem proving capabilities | ✓ | - | MIT | math_formal_lean_multi_turn.yaml | - |
| Math Proof Judgement | math | Binary judgement of math proofs — the policy model reads a problem plus a candidate proof and outputs Judgement: Yes/No. | Improve the NVIDIA ProofBench judge benchmark and math-proof verification skill. | - | - | - | math_proof_judgement.yaml |