← Open Source
NJU-PCALab

STAR

[ICCV 2025] STAR: Spatial-Temporal Augmentation with Text-to-Video Models for Real-World Video Super-Resolution.

ModelsVision modelsPython
Open on GitHub
Momentum
+1stars in 24 hours+0.1%
1.50k
Stars
87
Forks
+2
This week
2
Contributors
Created 2024-11-21 · Updated 2026-10-16 · #5509 today
Top developers
CSRuiXieyhliu04

NJU-PCALab/STAR is ranked 5,509 with 1,497 stars.

Same-category comparison

NJU-PCALab/STAR is ranked 5,509 among these 8 peers; SkyworkAI/Skywork is ranked 5,507.

Same-category comparison
NameRankMetrics
NVlabs/Fast-FoundationStereo5,483
Language:
Python
Stars:
1,535
Forks:
161
Description:
[CVPR 2026] Fast-FoundationStereo: Real-Time Zero-Shot Stereo Matching.
WenmuZhou/PytorchOCR5,489
Language:
Python
Stars:
1,528
Forks:
317
piddnad/DDColor5,501
Language:
Python
Stars:
1,507
Forks:
169
Description:
[ICCV 2023] DDColor: Towards Photo-Realistic Image Colorization via Dual Decoders.
SkyworkAI/Skywork5,507
Language:
Python
Stars:
1,498
Forks:
148
Description:
Skywork series models are pre-trained on 3.2TB of high-quality multilingual (mainly Chinese and English) and code data. We have open-sourced the model, training data, evaluation data, evaluation methods, etc.
nyrahealth/CrisperWhisper5,539
Language:
Python
Stars:
1,450
Forks:
94
Description:
Controllable Transcription. Verbatim ( every, filler, pause, stutter, vocal sound) , or intended ( what the speaker meant to say, optimized for readability) with word-level timestamps.
MiuLab/Taiwan-LLM5,550
Language:
Python
Stars:
1,427
Forks:
121
Description:
Traditional Mandarin LLMs for Taiwan.
marl/crepe5,554
Language:
Python
Stars:
1,420
Forks:
188
dailenson/SDT5,559
Language:
Python
Stars:
1,412
Forks:
114
Description:
This repository is the official implementation of Disentangling Writer and Character Styles for Handwriting Generation (CVPR 2023).
Key parameters and specifications
ParameterValue
LanguagePython
CategoryModels
SubcategoryVision models
KeywordsData synthesis, Multimodal, Text-to-video, Video production
Stars1,497
Forks87
Contributors2
Created date2024-11-21
Updated date2026-10-16
Stars in 1 day1
Stars in 7 days2
Rank5,509
Previous rank10,180
Rank change4,671
7-day stars rank8,035
Previous 7-day stars rank9,862
7-day stars rank change1,827
Total stars rank8,110
Previous total stars rank8,104
Total stars rank change-6
README summary

01** 🔥 Training codes of I2VGen-XL version have been released. 19** 📖 The STAR demo is now available on Google Colab. 09** 📖 The online demo of STAR on Hugging Face is now live! Please note that due to the duration limitation of ZeroGPU, the running time may exceed the allocated GPU duration. If you'd like to try it, you can duplicate the demo and assign a paid GPU. 07** 🔥 The pretrained STAR model (I2VGen-XL and CogVideoX-5B versions) and inference

code have been released. ⚙️ Dependencies and Installation **VRAM requirement**: Upscaling the provided toy example by 4x, with 72 frames, a width of 426, and a height of 240, requires around 39GB of VRAM using the default settings. If you encounter an OOM problem, you can set a smaller frame_length in inference_sr. We recommend using a GPU with at least 24GB of VRAM to run this project. I2VGen-XL-based Step 1: Download the pretrained model STAR from HuggingFace

. We provide two versions for I2VGen-XL-based model, for heavy degraded videos and for light degraded videos (e. , the low-resolution video downloaded from video websites). Step 2: Prepare testing data You can put the testing videos in the . As for the prompt, there are three options: 1. Step 3: Change the path You need to change the paths in to your local corresponding paths, including , , , and . CogVideoX-based Refer to these instructions for inference with the CogVideX-5B

-based model. Please note that the CogVideX-5B-based model supports only 720x480 input. 🌈 Training Step 1: Download the pretrained VEnhancer. Step 2: Prepare training data, structured as follows: Follow this instruction to generate training data. Step 3: Training for STAR (I2VGen-XL-based) : path to the pretrained VEnhancer. : save a model checkpoint every N training steps. ❤️ Acknowledgments This project is based on I2VGen-XL, VEnhancer, CogVideoX and OpenVid-1M. 🎓Citations If our project helps your research or work, please

consider citing our paper: 📧 Contact If you have any inquiries, please don't hesitate to reach out via email at 📄 License I2VGen-XL-based models are distributed under the terms of the MIT License. CogVideoX-5B-based model is distributed under the terms of the CogVideoX License.

Frequently asked questions

How many stars and forks are recorded?

NJU-PCALab/STAR has 1,497 stars and 87 forks.

What is the repository rank?

NJU-PCALab/STAR is ranked 5,509.

What language and category are recorded?

NJU-PCALab/STAR has 1,497 stars, uses Python and belongs to Models.

Which repository is closest in rank?

NJU-PCALab/STAR is compared with SkyworkAI/Skywork, ranked 5,507 with 1,498 stars.

README
STAR: Spatial-Temporal Augmentation with Text-to-Video Models for Real-World Video Super-Resolution


    [Rui Xie1*](https://github.com/CSRuiXie), 
    [Yinhong Liu1*](https://github.com/yhliu04), 
    [Penghao Zhou2](https://scholar.google.com/citations?hl=zh-CN&user=yWq1Fd4AAAAJ), 
    [Chen Zhao1](https://scholar.google.com/citations?user=Uhp3JKgAAAAJ&hl=zh-CN&oi=sra), 
    [Jun Zhou3](https://scholar.google.com/citations?hl=zh-CN&user=w03CHFwAAAAJ)  

    [Kai Zhang1](https://cszn.github.io/), 
    [Zhenyu Zhang1](https://jessezhang92.github.io/), 
    [Jian Yang1](https://scholar.google.com.hk/citations?user=6CIDtZQAAAAJ&hl=zh-CN), 
    [Zhenheng Yang2](https://scholar.google.com/citations?hl=zh-CN&user=Ds5wwRoAAAAJ), 
    [Ying Tai1&#8224](https://tyshiwo.github.io/index.html)


    1Nanjing University, 2ByteDance,  3Southwest University


        [![](https://img.shields.io/badge/🌟-Project%20Page-blue)](https://nju-pcalab.github.io/projects/STAR)
        [![](https://img.shields.io/badge/arXiv-2501.02976-b31b1b.svg)](https://arxiv.org/abs/2501.02976)
        [![](https://img.shields.io/badge/Demo%20Video-%23FF0000.svg?logo=YouTube&logoColor=white)](https://youtu.be/hx0zrql-SrU)
          

        [![](https://img.shields.io/static/v1?label=Demo STAR&message=HuggingFace&color=yellow)](https://huggingface.co/spaces/SherryX/STAR)
        [![](https://img.shields.io/static/v1?label=Demo STAR&message=Google Colab&color=orange)](https://colab.research.google.com/drive/1K8A1U_BNpAteRhhW9A8pAYs6LWjItQs_?usp=sharing)
🔆 Updates

  • 2025.07.01 🔥 Training codes of I2VGen-XL version have been released.

  • 2025.06.26 🌟 STAR is accepted by ICCV 2025!

  • 2025.01.19 📖 The STAR demo is now available on Google Colab. Feel free to give it a try!

  • 2025.01.09 📖 The online demo of STAR on Hugging Face is now live! Please note that due to the duration limitation of ZeroGPU, the running time may exceed the allocated GPU duration. If you'd like to try it, you can duplicate the demo and assign a paid GPU.

  • 2025.01.07 🔥 The pretrained STAR model (I2VGen-XL and CogVideoX-5B versions) and inference code have been released.

📑 TODO

  • [x] Training codes
  • [x] Inference codes
  • [x] Online demo

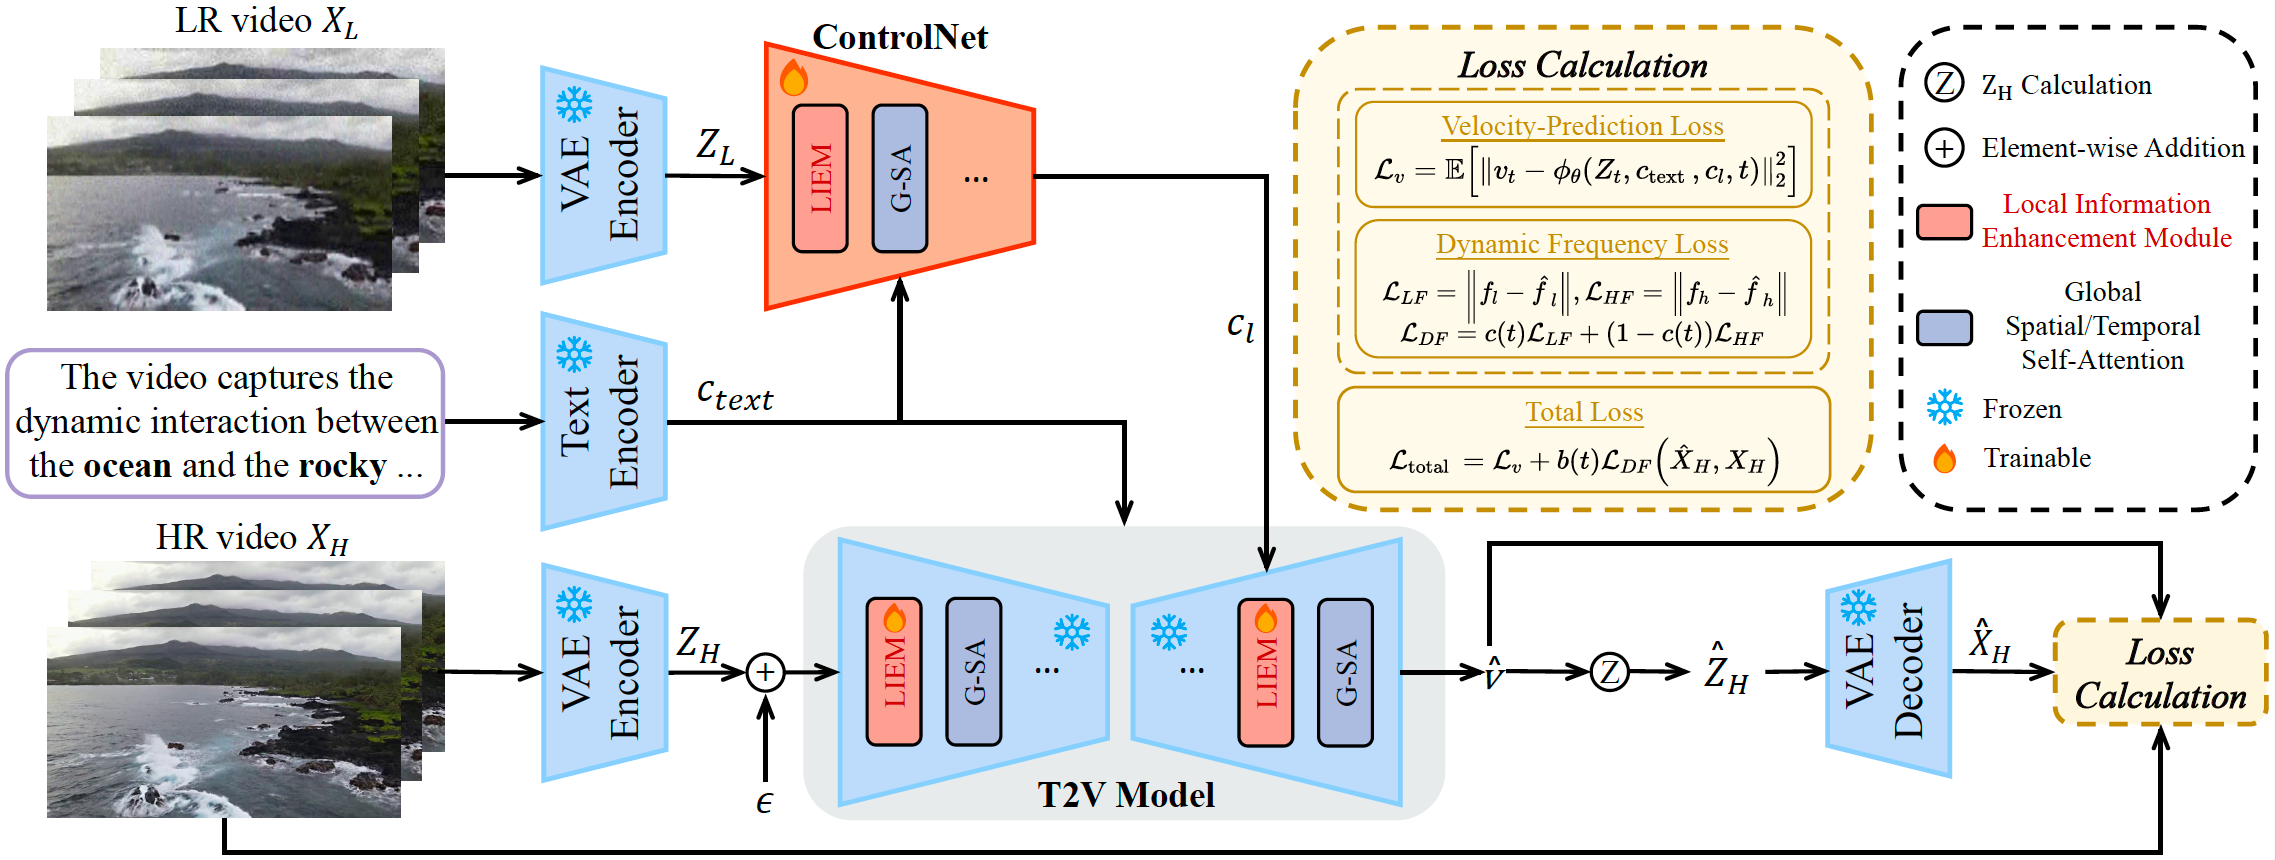
🔎 Method Overview

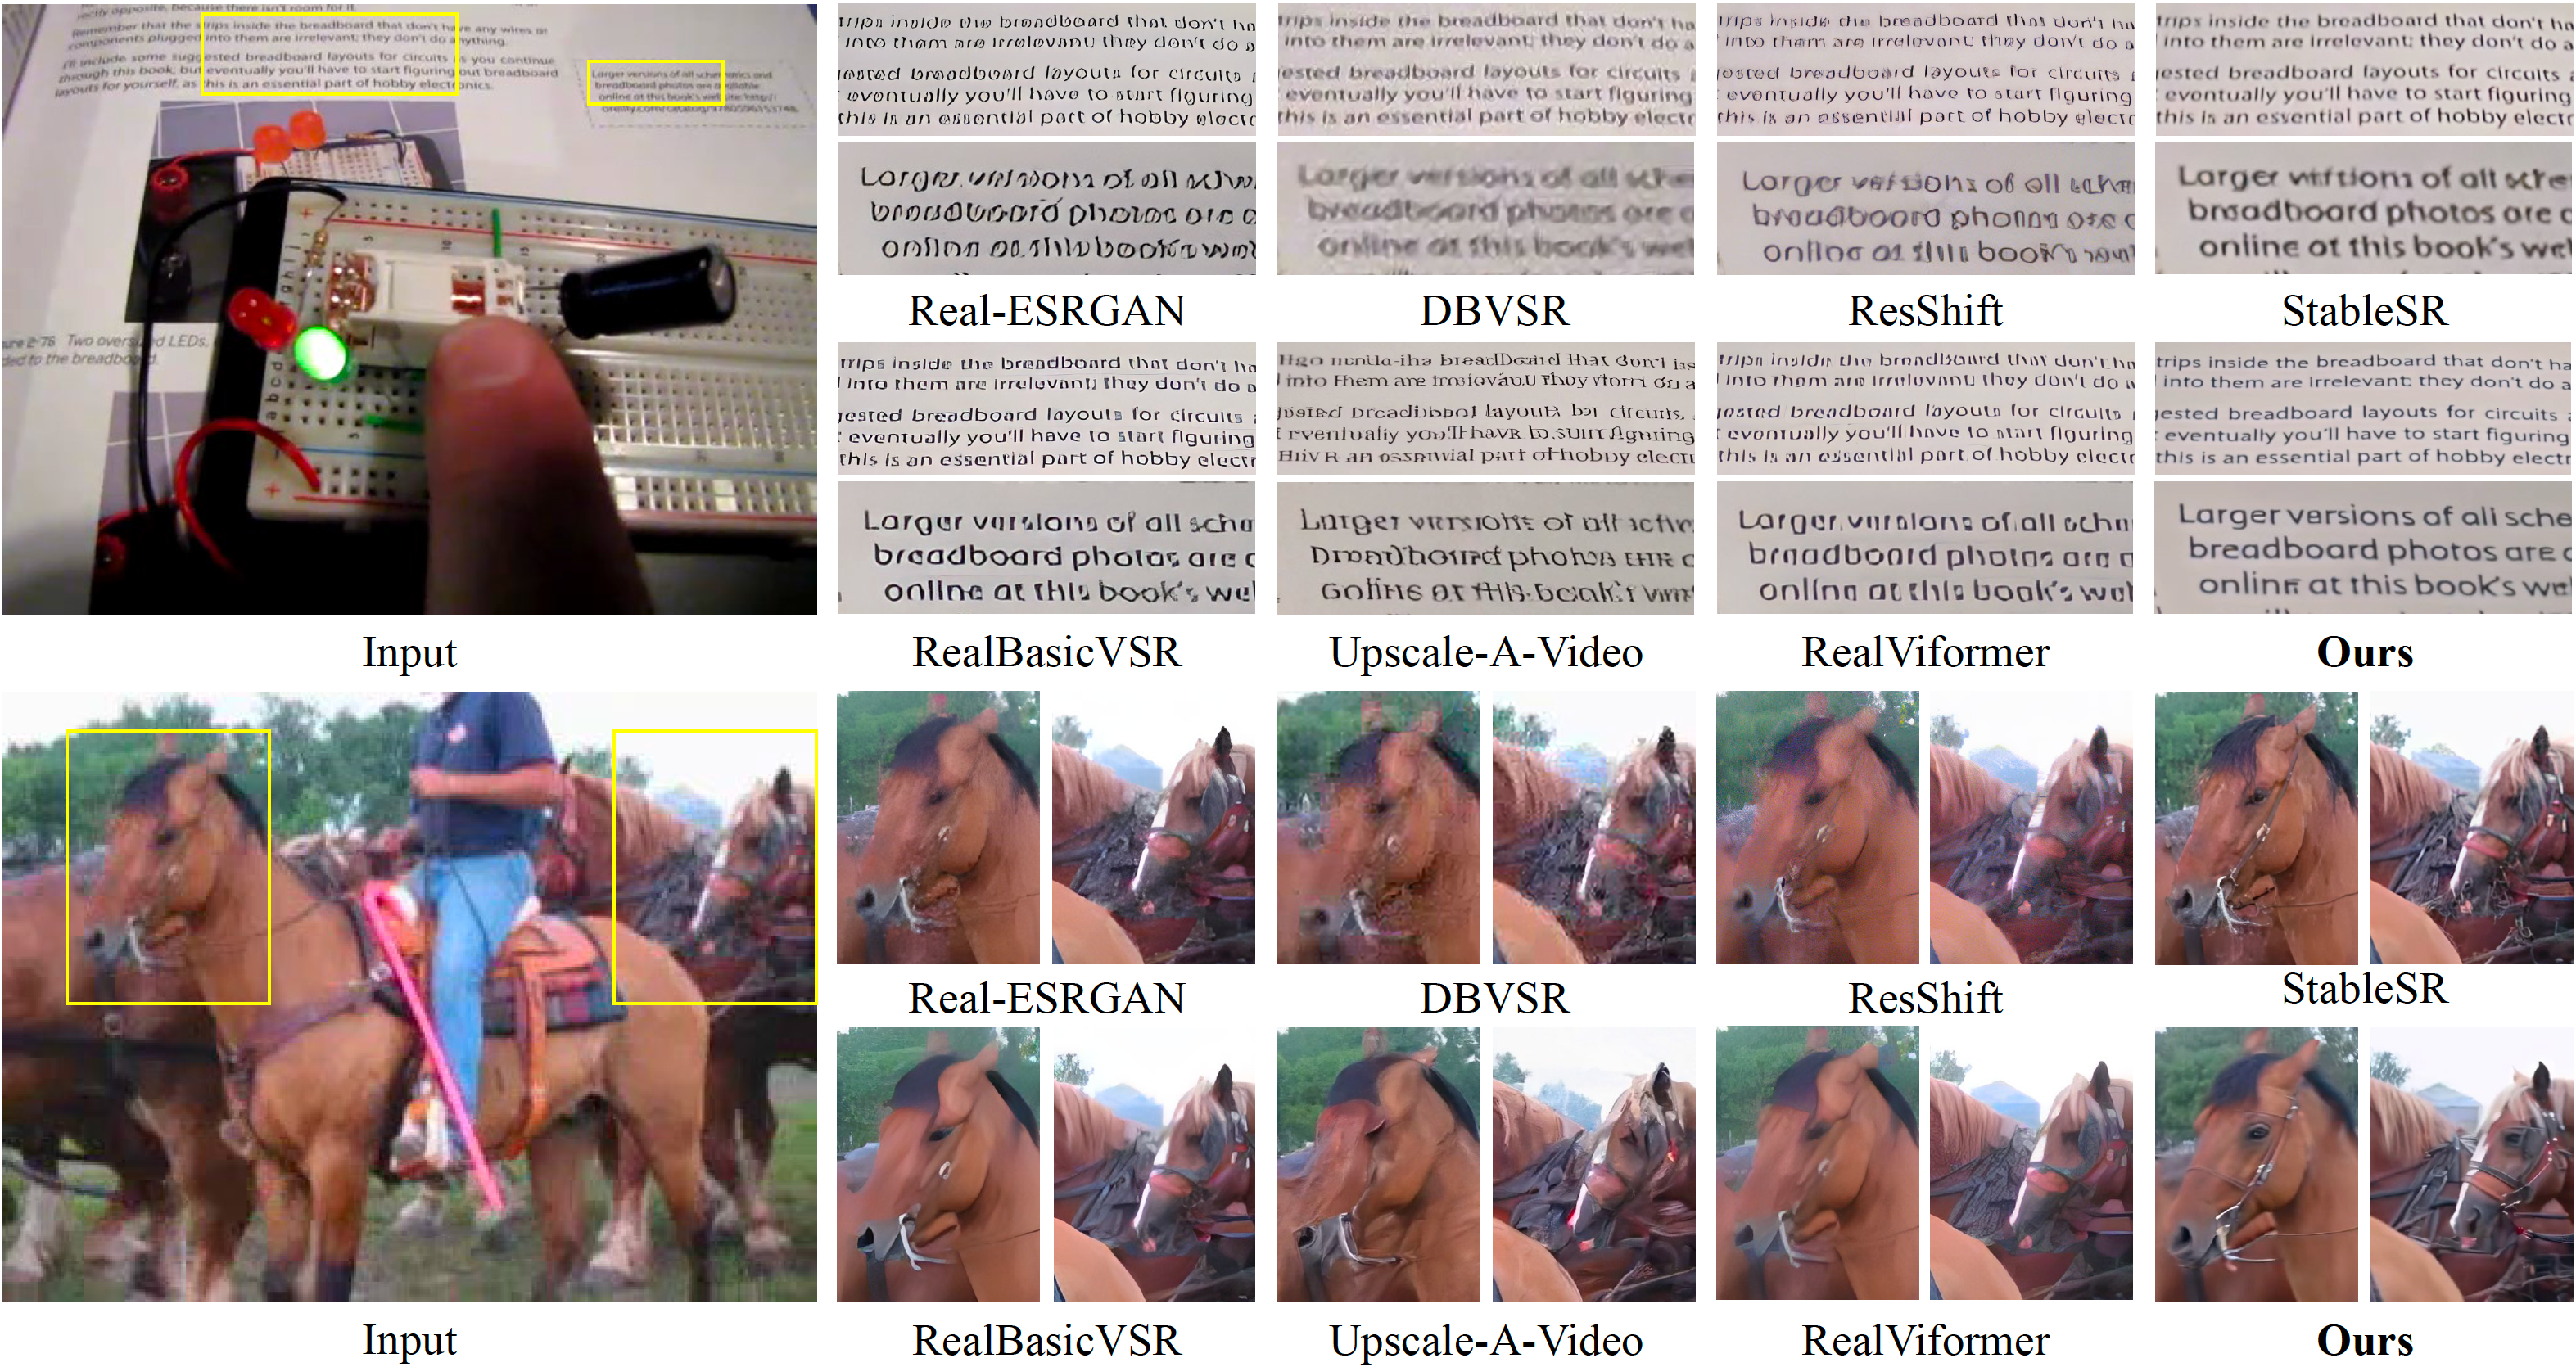
📷 Results Display
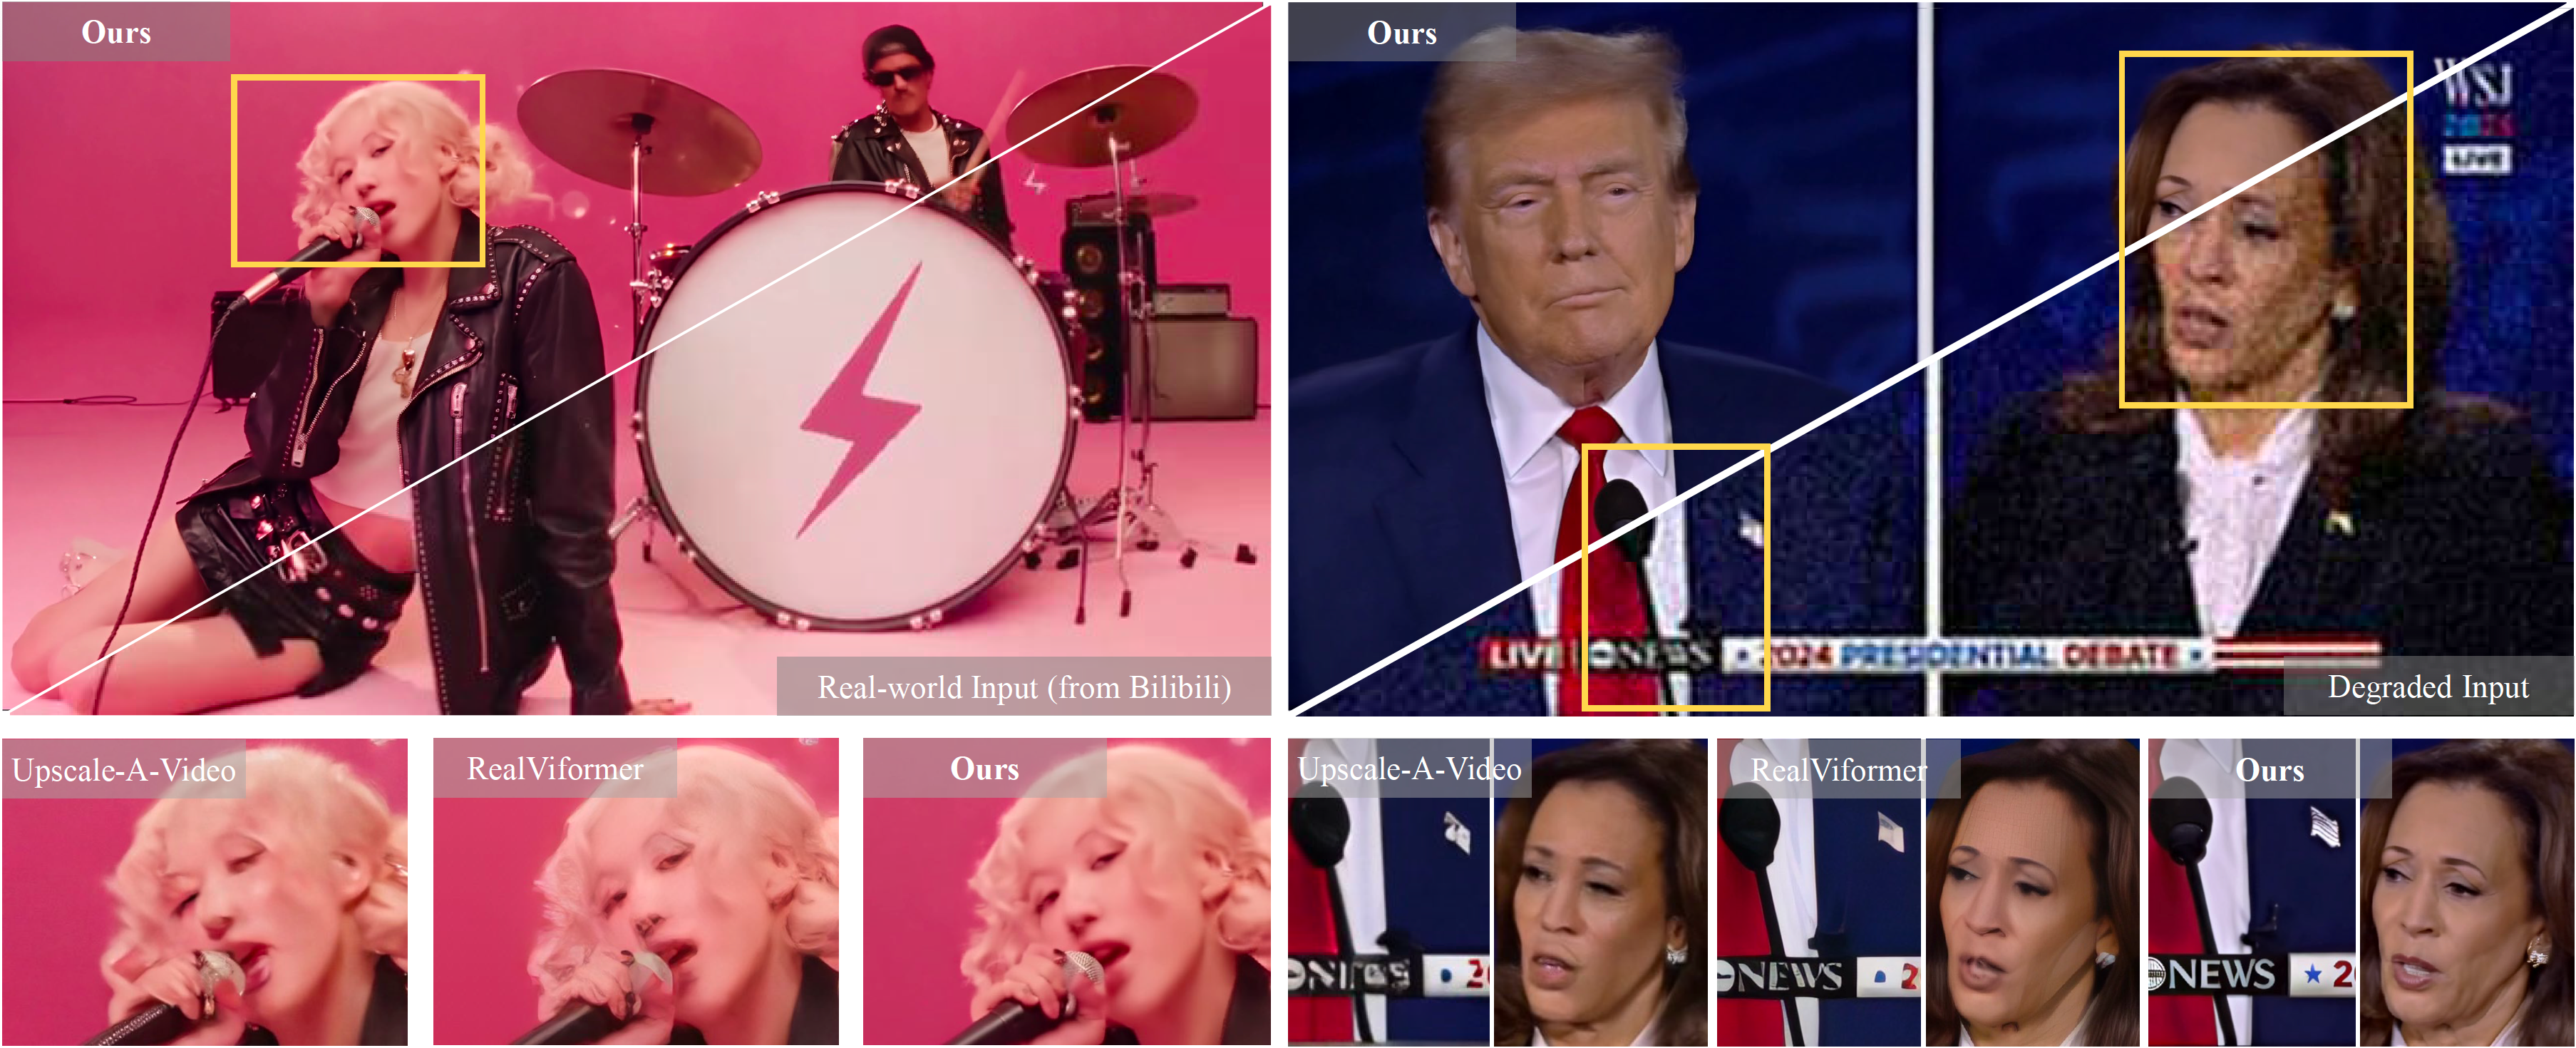
👀 More visual results can be found in our Project Page and Video Demo.

⚙️ Dependencies and Installation

VRAM requirement: Upscaling the provided toy example by 4x, with 72 frames, a width of 426, and a height of 240, requires around 39GB of VRAM using the default settings. If you encounter an OOM problem, you can set a smaller frame_length in inference_sr.sh. We recommend using a GPU with at least 24GB of VRAM to run this project.

## git clone this repository
git clone https://github.com/NJU-PCALab/STAR.git
cd STAR

## create an environment
conda create -n star python=3.10
conda activate star
pip install -r requirements.txt
sudo apt-get update && sudo apt-get install ffmpeg libsm6 libxext6  -y

🚀 Inference

Model Weight

Base Model Type URL
I2VGen-XL Light Degradation :link:
I2VGen-XL Heavy Degradation :link:
CogVideoX-5B Heavy Degradation :link:

1. I2VGen-XL-based

Step 1: Download the pretrained model STAR from HuggingFace.

We provide two versions for I2VGen-XL-based model, heavy_deg.pt for heavy degraded videos and light_deg.pt for light degraded videos (e.g., the low-resolution video downloaded from video websites).

You can put the weight into pretrained_weight/.

Step 2: Prepare testing data

You can put the testing videos in the input/video/.

As for the prompt, there are three options: 1. No prompt. 2. Automatically generate a prompt (e.g., using Pllava). 3. Manually write the prompt. You can put the txt file in the input/text/.

Step 3: Change the path

You need to change the paths in video_super_resolution/scripts/inference_sr.sh to your local corresponding paths, including video_folder_path, txt_file_path, model_path, and save_dir.

Step 4: Running inference command

bash video_super_resolution/scripts/inference_sr.sh

2. CogVideoX-based

Refer to these instructions for inference with the CogVideX-5B-based model.

Please note that the CogVideX-5B-based model supports only 720x480 input.

🌈 Training

Step 1: Download the pretrained VEnhancer.

Step 2: Prepare training data, structured as follows:

/dataset/
    ├── gt/        # Ground-truth high-quality videos
    │   ├── video1.mp4
    │   ├── video2.mp4
    │   └── ...
    ├── lq/        # Low-quality input videos
    │   ├── video1.mp4
    │   ├── video2.mp4
    │   └── ...
    └── text/      # Text prompts corresponding to each video
        ├── video1.txt
        ├── video2.txt
        └── ...

Follow this instruction to generate training data.

Step 3: Training for STAR (I2VGen-XL-based)

bash video_super_resolution/scripts/train_sr.sh

--pretrained_model_path: path to the pretrained VEnhancer.

--checkpointing_steps: save a model checkpoint every N training steps.

--num_frames: length of each training video.

❤️ Acknowledgments

This project is based on I2VGen-XL, VEnhancer, CogVideoX and OpenVid-1M. Thanks for their awesome works.

🎓Citations

If our project helps your research or work, please consider citing our paper:

@misc{xie2025starspatialtemporalaugmentationtexttovideo,
      title={STAR: Spatial-Temporal Augmentation with Text-to-Video Models for Real-World Video Super-Resolution}, 
      author={Rui Xie and Yinhong Liu and Penghao Zhou and Chen Zhao and Jun Zhou and Kai Zhang and Zhenyu Zhang and Jian Yang and Zhenheng Yang and Ying Tai},
      year={2025},
      eprint={2501.02976},
      archivePrefix={arXiv},
      primaryClass={cs.CV},
      url={https://arxiv.org/abs/2501.02976}, 
}

📧 Contact

If you have any inquiries, please don't hesitate to reach out via email at ruixie0097@gmail.com

📄 License

I2VGen-XL-based models are distributed under the terms of the MIT License.

CogVideoX-5B-based model is distributed under the terms of the CogVideoX License.

Nearby in the ranking
Similar items