SMPLer-X: Scaling Up Expressive Human Pose and Shape Estimation
Check out SMPLest-X, an extension of SMPLer-X with stronger foundation models!
Useful links
[[Homepage]](https://caizhongang.github.io/projects/SMPLer-X/)
[[HuggingFace]](https://huggingface.co/spaces/caizhongang/SMPLer-X)
[[arXiv]](https://arxiv.org/abs/2309.17448)
[[Video]](https://youtu.be/DepTqbPpVzY)
[[SMPLest-X]](https://github.com/wqyin/SMPLest-X)
[[MMHuman3D]](https://github.com/open-mmlab/mmhuman3d)
News
- [2025-10-21] SMPLest-X accepted to TPAMI.
- [2025-02-17] Pretrained models of SMPLest-X available for download.
- [2025-02-14] Brand new codebase of SMPLest-X released for trainig, testing and inference.
- [2025-01-20] SMPLest-X released on arXiv.
- [2025-01-08] Project page of SMPLest-X created.
- [2024-03-29] An updated version of SMPLer-X-H32 is released to fix camera estimation on 3DPW-like data.
- [2024-02-29] HuggingFace demo is online!
- [2023-10-23] Support visualization through SMPL-X mesh overlay and add inference docker.
- [2023-10-02] arXiv preprint is online!
- [2023-09-28] Homepage and Video are online!
- [2023-07-19] Pretrained models are released.
- [2023-06-15] Training and testing code is released.
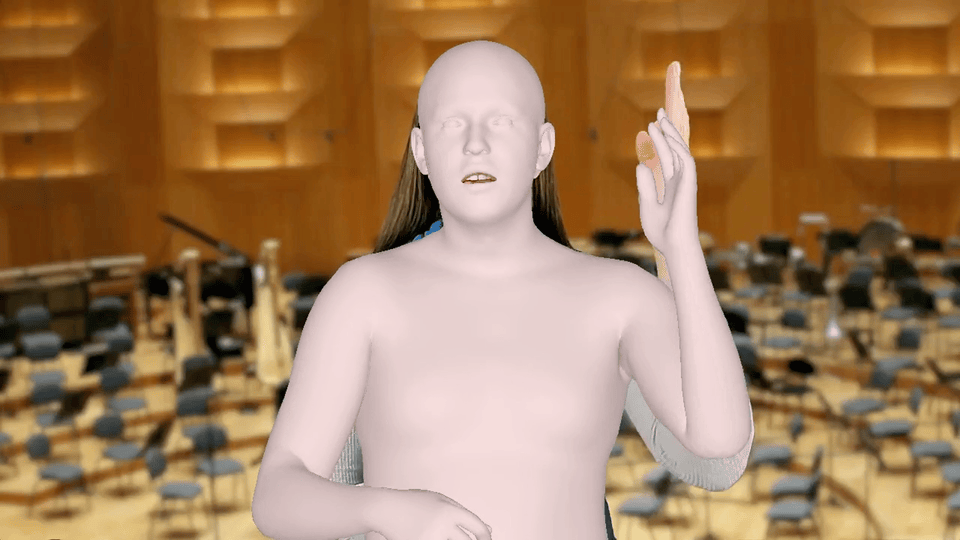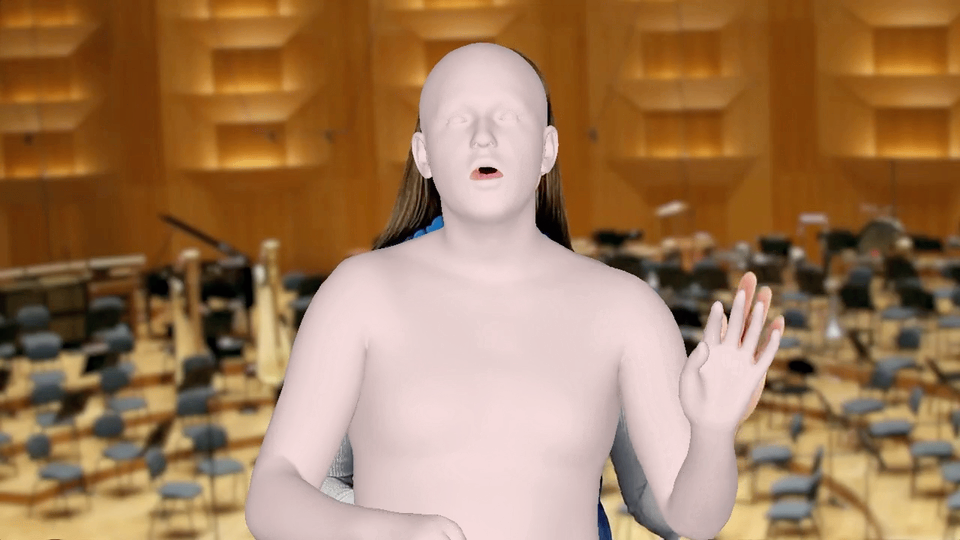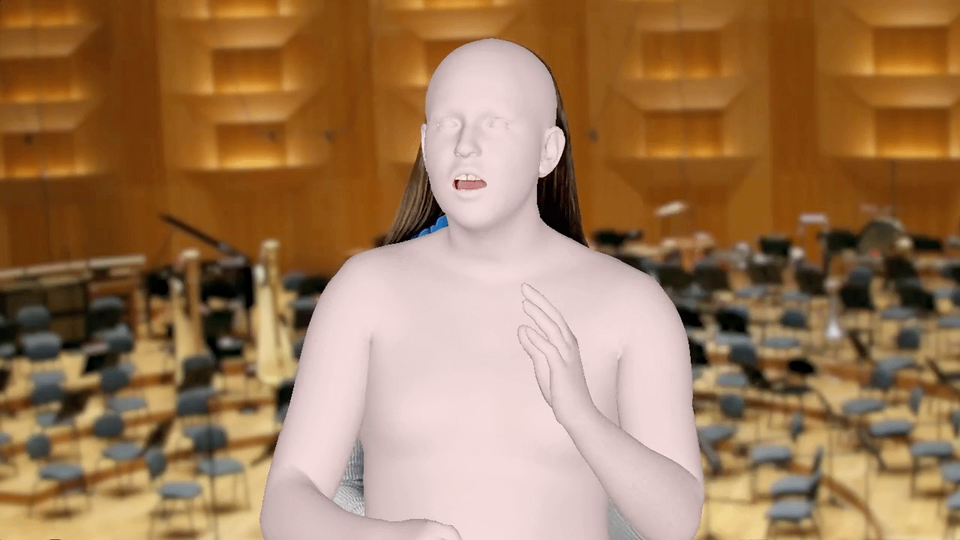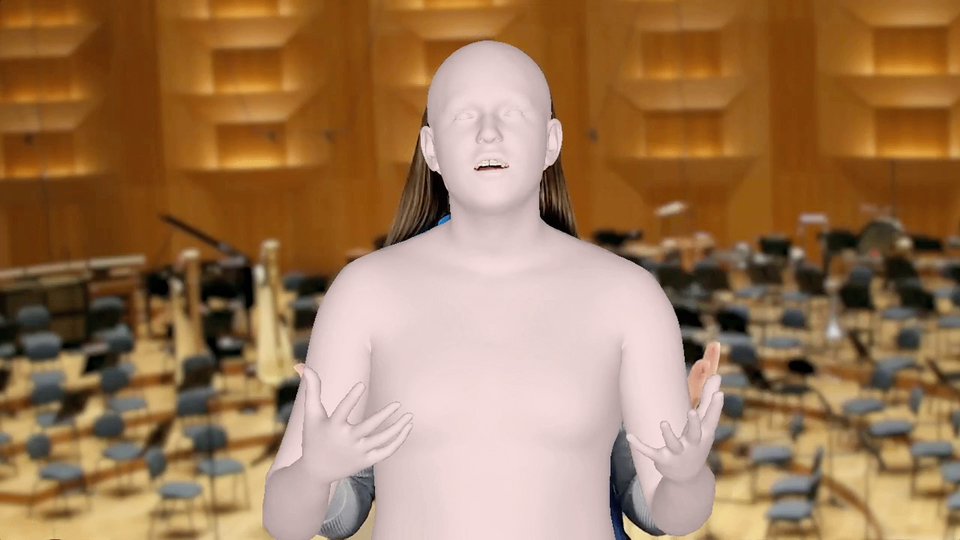
Gallery
 |
 |
 |
|---|---|---|
 |
 |
 |
Install
conda create -n smplerx python=3.8 -y
conda activate smplerx
conda install pytorch==1.12.0 torchvision==0.13.0 torchaudio==0.12.0 cudatoolkit=11.3 -c pytorch -y
pip install mmcv-full==1.7.1 -f https://download.openmmlab.com/mmcv/dist/cu113/torch1.12.0/index.html
pip install -r requirements.txt

# install mmpose
cd main/transformer_utils
pip install -v -e .
cd ../..
Docker Support (Early Stage)
docker pull wcwcw/smplerx_inference:v0.2
docker run  --gpus all -v :/smplerx_inference/vid_input \
        -v :/smplerx_inference/vid_output \
        wcwcw/smplerx_inference:v0.2 --vid .mp4
# Currently any customization need to be applied to /smplerx_inference/smplerx/inference_docker.py
- We recently developed a docker for inference at docker hub.
- This docker image uses SMPLer-X-H32 as inference baseline and was tested at RTX3090 & WSL2 (Ubuntu 20.04).
Pretrained Models
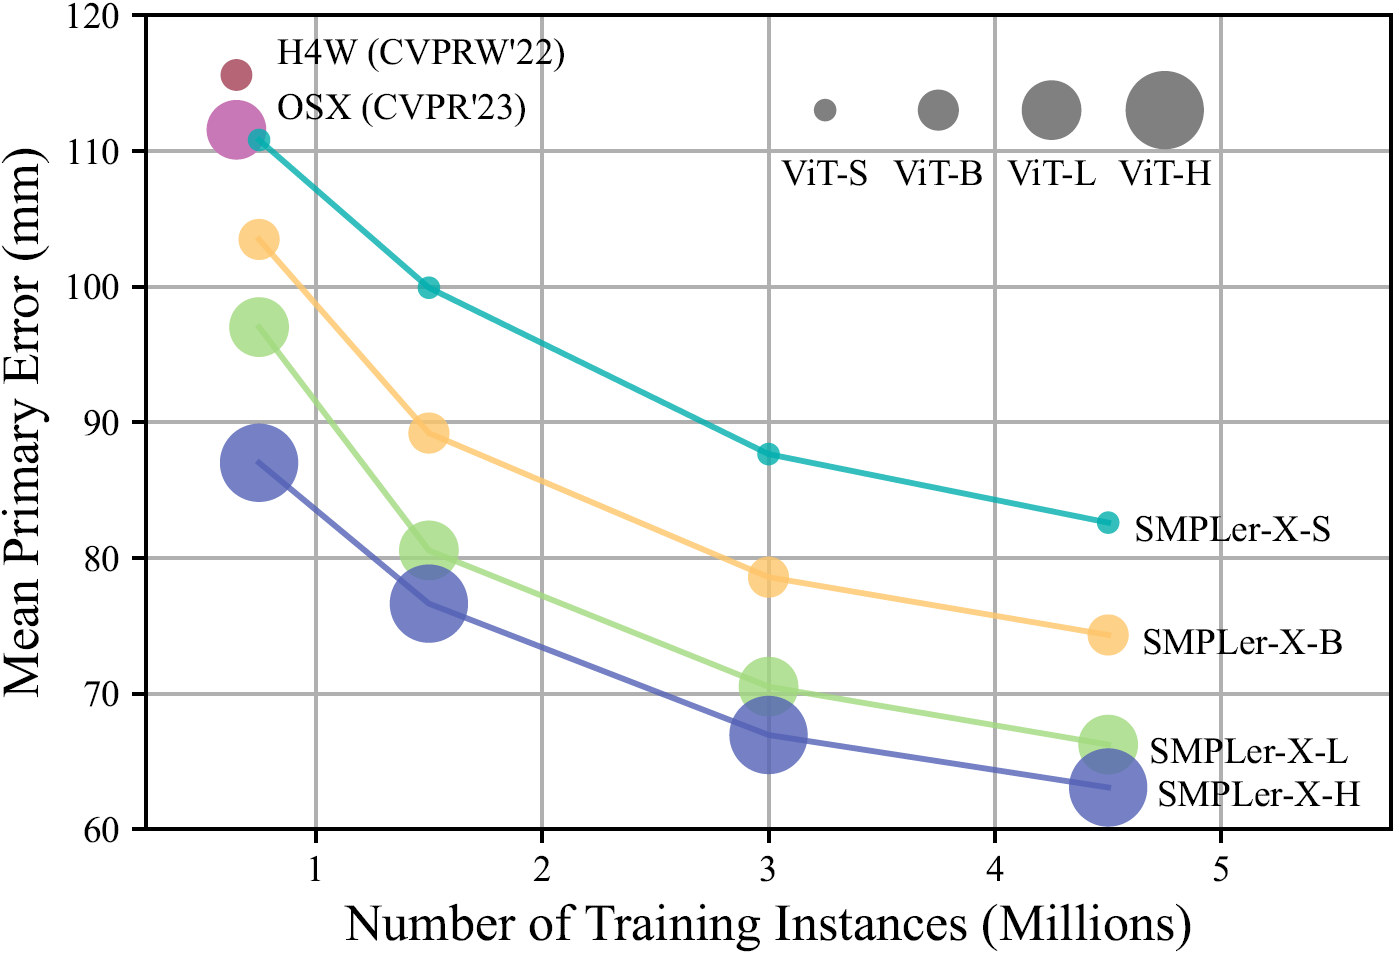
| Model | Backbone | #Datasets | #Inst. | #Params | MPE | Download | FPS |
|---|---|---|---|---|---|---|---|
| SMPLer-X-S32 | ViT-S | 32 | 4.5M | 32M | 82.6 | model | 36.17 |
| SMPLer-X-B32 | ViT-B | 32 | 4.5M | 103M | 74.3 | model | 33.09 |
| SMPLer-X-L32 | ViT-L | 32 | 4.5M | 327M | 66.2 | model | 24.44 |
| SMPLer-X-H32 | ViT-H | 32 | 4.5M | 662M | 63.0 | model | 17.47 |
| SMPLer-X-H32* | ViT-H | 32 | 4.5M | 662M | 59.7 | model | 17.47 |
- MPE (Mean Primary Error): the average of the primary errors on five benchmarks (AGORA, EgoBody, UBody, 3DPW, and EHF)
- FPS (Frames Per Second): the average inference speed on a single Tesla V100 GPU, batch size = 1
- SMPLer-X-H32* is the updated version of SMPLer-X-H32, which fixes the camera estimation issue on 3DPW-like data.
Preparation
- download all datasets
- process all datasets into HumanData format, except the following:
- AGORA, MSCOCO, MPII, Human3.6M, UBody.
- follow OSX in preparing these 5 datasets.
- follow OSX in preparing pretrained ViTPose models. Download the ViTPose pretrained weights for ViT-small and ViT-huge from here.
- download SMPL-X and SMPL body models.
- download mmdet pretrained model and config for inference.
The file structure should be like:
SMPLer-X/
├── common/
│   └── utils/
│       └── human_model_files/  # body model
│           ├── smpl/
│           │   ├──SMPL_NEUTRAL.pkl
│           │   ├──SMPL_MALE.pkl
│           │   └──SMPL_FEMALE.pkl
│           └── smplx/
│               ├──MANO_SMPLX_vertex_ids.pkl
│               ├──SMPL-X__FLAME_vertex_ids.npy
│               ├──SMPLX_NEUTRAL.pkl
│               ├──SMPLX_to_J14.pkl
│               ├──SMPLX_NEUTRAL.npz
│               ├──SMPLX_MALE.npz
│               └──SMPLX_FEMALE.npz
├── data/
├── main/
├── demo/
│   ├── videos/
│   ├── images/
│   └── results/
├── pretrained_models/  # pretrained ViT-Pose, SMPLer_X and mmdet models
│   ├── mmdet/
│   │   ├──faster_rcnn_r50_fpn_1x_coco_20200130-047c8118.pth
│   │   └──mmdet_faster_rcnn_r50_fpn_coco.py
│   ├── smpler_x_s32.pth.tar
│   ├── smpler_x_b32.pth.tar
│   ├── smpler_x_l32.pth.tar
│   ├── smpler_x_h32.pth.tar
│   ├── vitpose_small.pth
│   ├── vitpose_base.pth
│   ├── vitpose_large.pth
│   └── vitpose_huge.pth
└── dataset/
    ├── AGORA/
    ├── ARCTIC/
    ├── BEDLAM/
    ├── Behave/
    ├── CHI3D/
    ├── CrowdPose/
    ├── EgoBody/
    ├── EHF/
    ├── FIT3D/
    ├── GTA_Human2/
    ├── Human36M/
    ├── HumanSC3D/
    ├── InstaVariety/
    ├── LSPET/
    ├── MPII/
    ├── MPI_INF_3DHP/
    ├── MSCOCO/
    ├── MTP/
    ├── MuCo/
    ├── OCHuman/
    ├── PoseTrack/
    ├── PROX/
    ├── PW3D/
    ├── RenBody/
    ├── RICH/
    ├── SPEC/
    ├── SSP3D/
    ├── SynBody/
    ├── Talkshow/
    ├── UBody/
    ├── UP3D/
    └── preprocessed_datasets/  # HumanData files
Inference
- Place the video for inference under
SMPLer-X/demo/videos - Prepare the pretrained models to be used for inference under
SMPLer-X/pretrained_models - Prepare the mmdet pretrained model and config under
SMPLer-X/pretrained_models - Inference output will be saved in
SMPLer-X/demo/results
cd main
sh slurm_inference.sh {VIDEO_FILE} {FORMAT} {FPS} {PRETRAINED_CKPT}

# For inferencing test_video.mp4 (24FPS) with smpler_x_h32
sh slurm_inference.sh test_video mp4 24 smpler_x_h32
2D Smplx Overlay
We provide a lightweight visualization script for mesh overlay based on pyrender.
- Use ffmpeg to split video into images
- The visualization script takes inference results (see above) as the input.
ffmpeg -i {VIDEO_FILE} -f image2 -vf fps=30 \
        {SMPLERX INFERENCE DIR}/{VIDEO NAME (no extension)}/orig_img/%06d.jpg \
        -hide_banner  -loglevel error

cd main && python render.py \
            --data_path {SMPLERX INFERENCE DIR} --seq {VIDEO NAME} \
            --image_path {SMPLERX INFERENCE DIR}/{VIDEO NAME} \
            --render_biggest_person False
Training
cd main
sh slurm_train.sh {JOB_NAME} {NUM_GPU} {CONFIG_FILE}

# For training SMPLer-X-H32 with 16 GPUS
sh slurm_train.sh smpler_x_h32 16 config_smpler_x_h32.py
- CONFIG_FILE is the file name under
SMPLer-X/main/config - Logs and checkpoints will be saved to
SMPLer-X/output/train_{JOB_NAME}_{DATE_TIME}
Testing
# To eval the model ../output/{TRAIN_OUTPUT_DIR}/model_dump/snapshot_{CKPT_ID}.pth.tar
# with confing ../output/{TRAIN_OUTPUT_DIR}/code/config_base.py
cd main
sh slurm_test.sh {JOB_NAME} {NUM_GPU} {TRAIN_OUTPUT_DIR} {CKPT_ID}
- NUM_GPU = 1 is recommended for testing
- Logs and results will be saved to
SMPLer-X/output/test_{JOB_NAME}_ep{CKPT_ID}_{TEST_DATSET}
FAQ
-
RuntimeError: Subtraction, the '-' operator, with a bool tensor is not supported. If you are trying to invert a mask, use the '~' or 'logical_not()' operator instead.Follow this post and modify
torchgeometry -
KeyError: 'SinePositionalEncoding is already registered in position encoding'or any other similar KeyErrors due to duplicate module registration.Manually add
force=Trueto respective module registration undermain/transformer_utils/mmpose/models/utils, e.g.@POSITIONAL_ENCODING.register_module(force=True)in this file -
How do I animate my virtual characters with SMPLer-X output (like that in the demo video)?
- We are working on that, please stay tuned! Currently, this repo supports SMPL-X estimation and a simple visualization (overlay of SMPL-X vertices).
References
Citation
# SMPLest-X
@article{yin2025smplest,
    title={SMPLest-X: Ultimate Scaling for Expressive Human Pose and Shape Estimation},
    author={Yin, Wanqi and Cai, Zhongang and Wang, Ruisi and Zeng, Ailing and Wei, Chen and Sun, Qingping and Mei, Haiyi and Wang, Yanjun and Pang, Hui En and Zhang, Mingyuan and Zhang, Lei and Loy, Chen Change and Yamashita, Atsushi and Yang, Lei and Liu, Ziwei},
    journal={IEEE Transactions on Pattern Analysis and Machine Intelligence},
    year={2026},
    volume={48},
    number={2},
    pages={1778-1794},
    doi={10.1109/TPAMI.2025.3618174}
}

# SMPLer-X
@inproceedings{cai2023smplerx,
    title={{SMPLer-X}: Scaling up expressive human pose and shape estimation},
    author={Cai, Zhongang and Yin, Wanqi and Zeng, Ailing and Wei, Chen and Sun, Qingping and Yanjun, Wang and Pang, Hui En and Mei, Haiyi and Zhang, Mingyuan and Zhang, Lei and Loy, Chen Change and Yang, Lei and Liu, Ziwei},
    booktitle={Advances in Neural Information Processing Systems},
    year={2023}
}
Explore More Motrix Projects
Motion Capture
- [SMPL-X] [TPAMI'25] SMPLest-X: An extended version of SMPLer-X with stronger foundation models.
- [SMPL-X] [NeurIPS'23] SMPLer-X: Scaling up EHPS towards a family of generalist foundation models.
- [SMPL-X] [ECCV'24] WHAC: World-grounded human pose and camera estimation from monocular videos.
- [SMPL-X] [CVPR'24] AiOS: An all-in-one-stage pipeline combining detection and 3D human reconstruction.
- [SMPL-X] [NeurIPS'23] RoboSMPLX: A framework to enhance the robustness of whole-body pose and shape estimation.
- [SMPL-X] [ICML'25] ADHMR: A framework to align diffusion-based human mesh recovery methods via direct preference optimization.
- [SMPL-X] MKA: Full-body 3D mesh reconstruction from single- or multi-view RGB videos.
- [SMPL] [ICCV'23] Zolly: 3D human mesh reconstruction from perspective-distorted images.
- [SMPL] [IJCV'26] PointHPS: 3D HPS from point clouds captured in real-world settings.
- [SMPL] [NeurIPS'22] HMR-Benchmarks: A comprehensive benchmark of HPS datasets, backbones, and training strategies.
Motion Generation
- [SMPL-X] [ICLR'26] ViMoGen: A comprehensive framework that transfers knowledge from ViGen to MoGen across data, modeling, and evaluation.
- [SMPL-X] [ECCV'24] LMM: Large Motion Model for Unified Multi-Modal Motion Generation.
- [SMPL-X] [NeurIPS'23] FineMoGen: Fine-Grained Spatio-Temporal Motion Generation and Editing.
- [SMPL] InfiniteDance: A large-scale 3D dance dataset and an MLLM-based music-to-dance model designed for robust in-the-wild generalization.
- [SMPL] [NeurIPS'23] InsActor: Generating physics-based human motions from language and waypoint conditions via diffusion policies.
- [SMPL] [ICCV'23] ReMoDiffuse: Retrieval-Augmented Motion Diffusion Model.
- [SMPL] [TPAMI'24] MotionDiffuse: Text-Driven Human Motion Generation with Diffusion Model.