(CVPR 2023) T2M-GPT
Pytorch implementation of paper "T2M-GPT: Generating Human Motion from Textual Descriptions with Discrete Representations"
[Project Page] [Paper] [Notebook Demo] [HuggingFace] [Space Demo] [T2M-GPT+]
If our project is helpful for your research, please consider citing :
@inproceedings{zhang2023generating,
  title={T2M-GPT: Generating Human Motion from Textual Descriptions with Discrete Representations},
  author={Zhang, Jianrong and Zhang, Yangsong and Cun, Xiaodong and Huang, Shaoli and Zhang, Yong and Zhao, Hongwei and Lu, Hongtao and Shen, Xi},
  booktitle={Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)},
  year={2023},
}
Table of Content
- 1. Visual Results
- 2. Installation
- 3. Quick Start
- 4. Train
- 5. Evaluation
- 6. SMPL Mesh Rendering
- 7. Acknowledgement
- 8. ChangLog
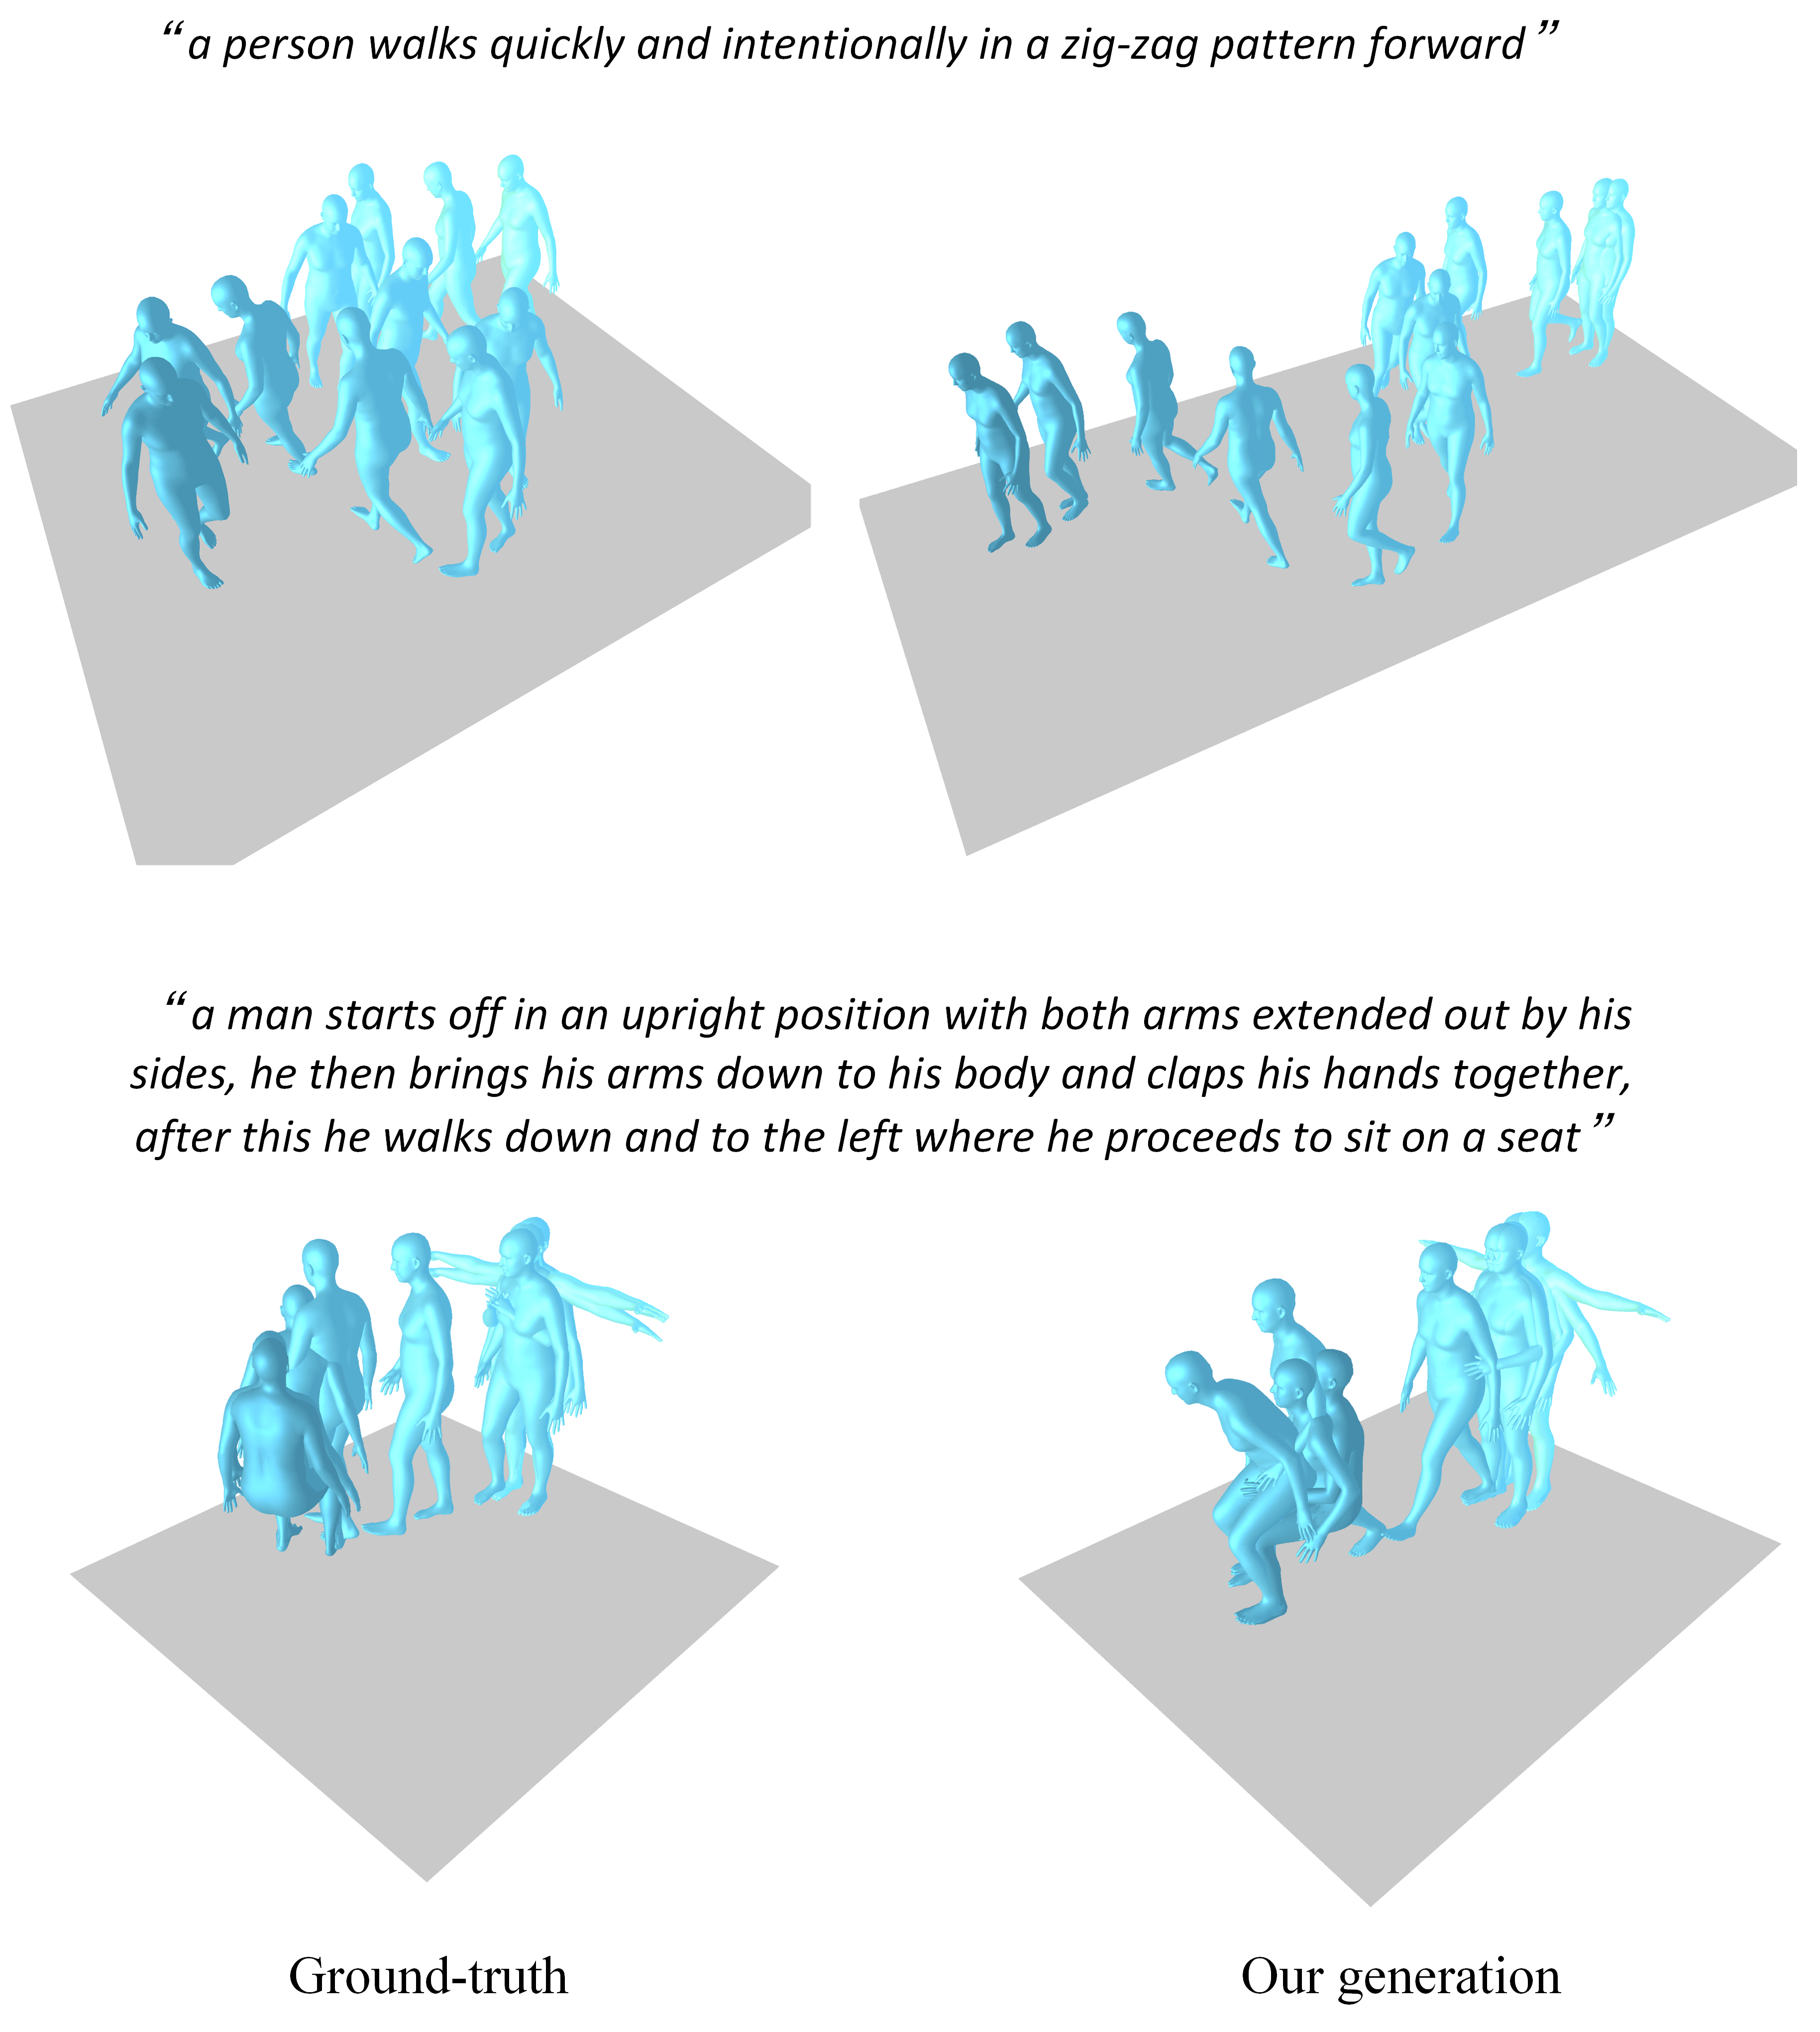
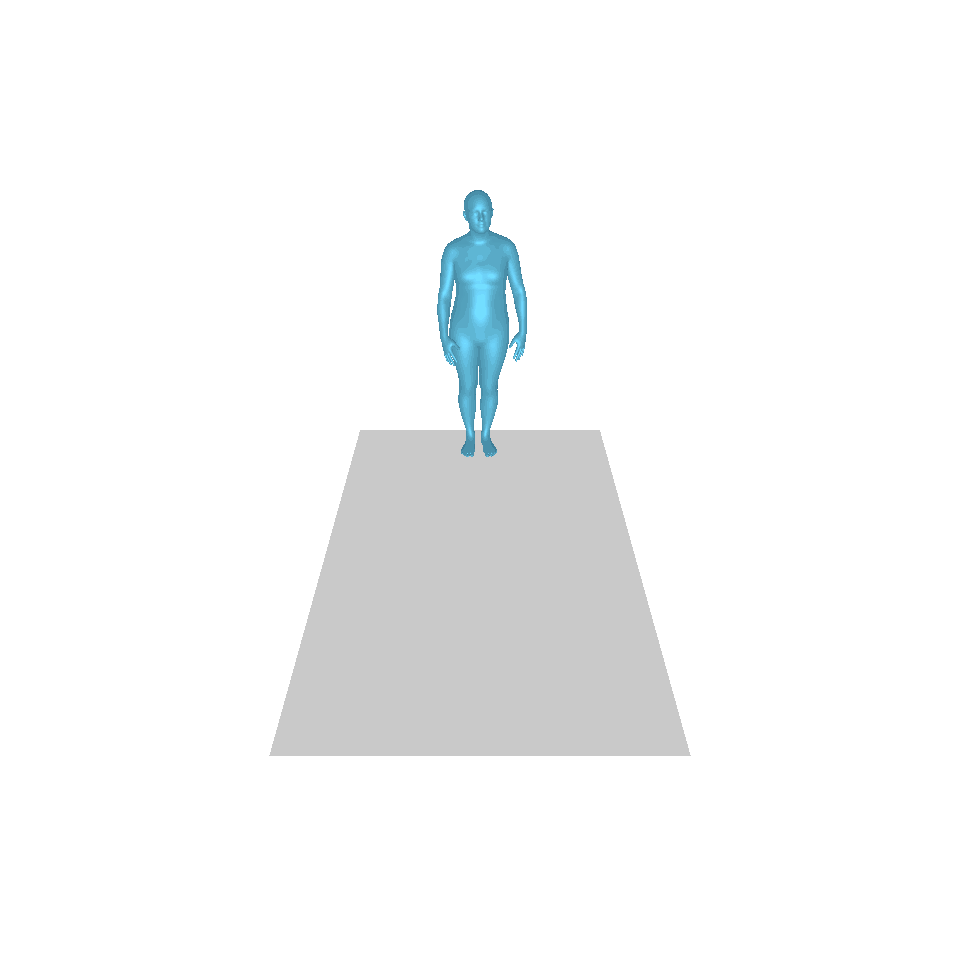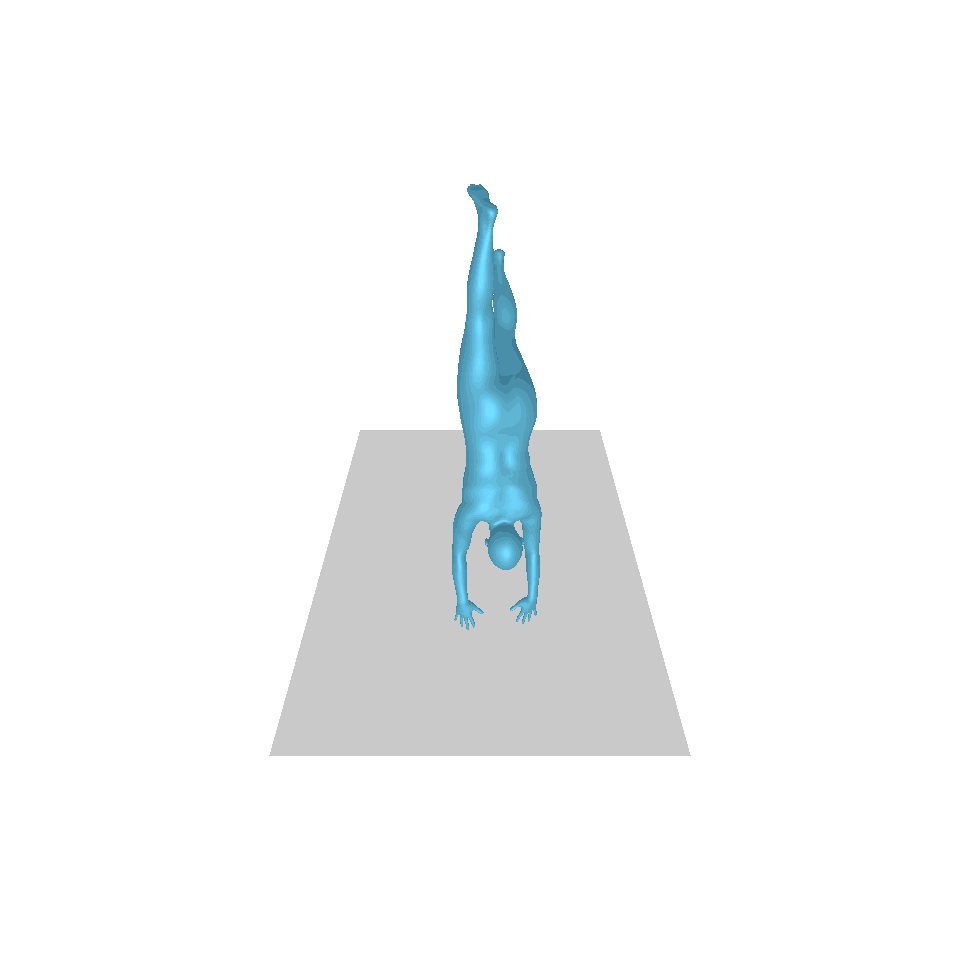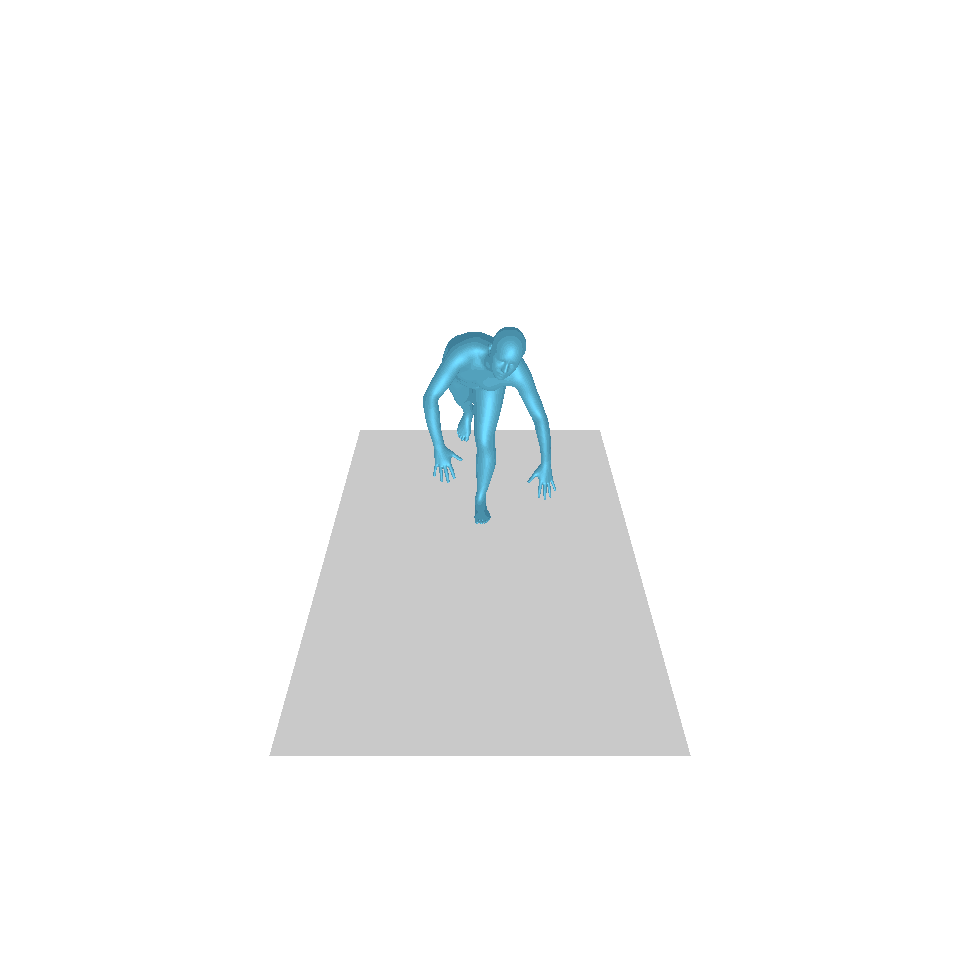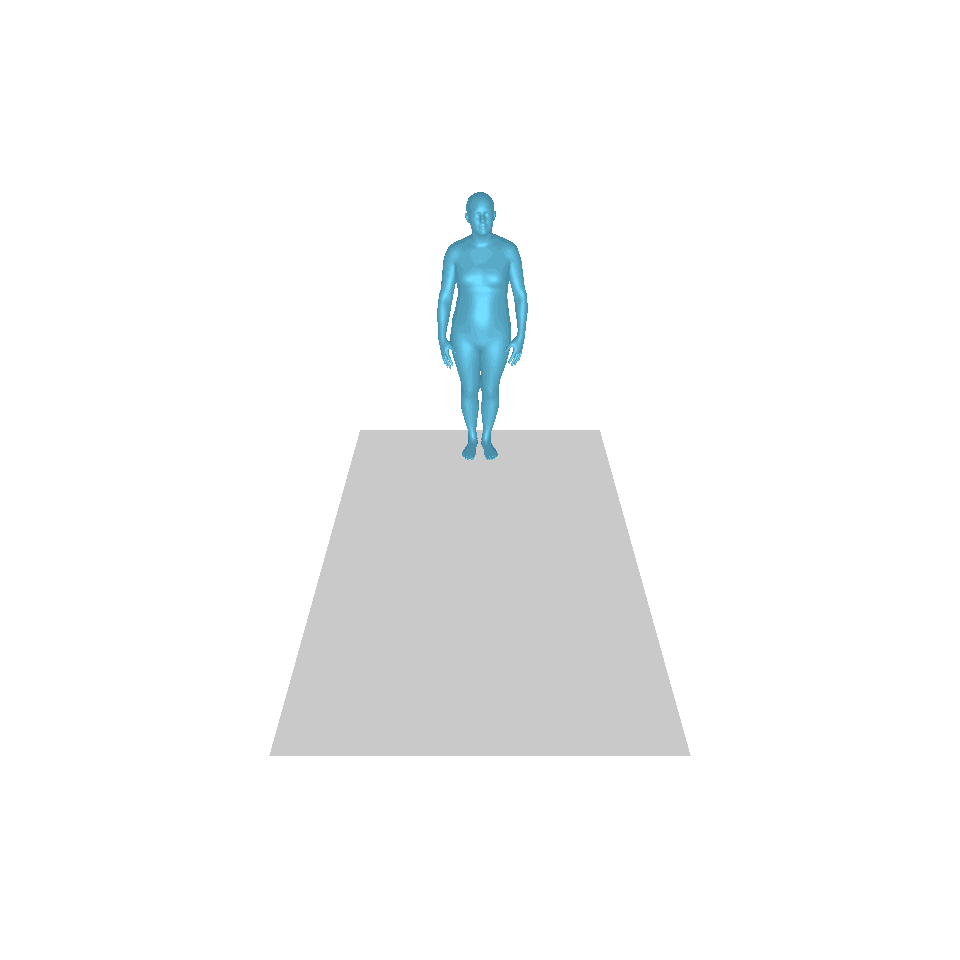
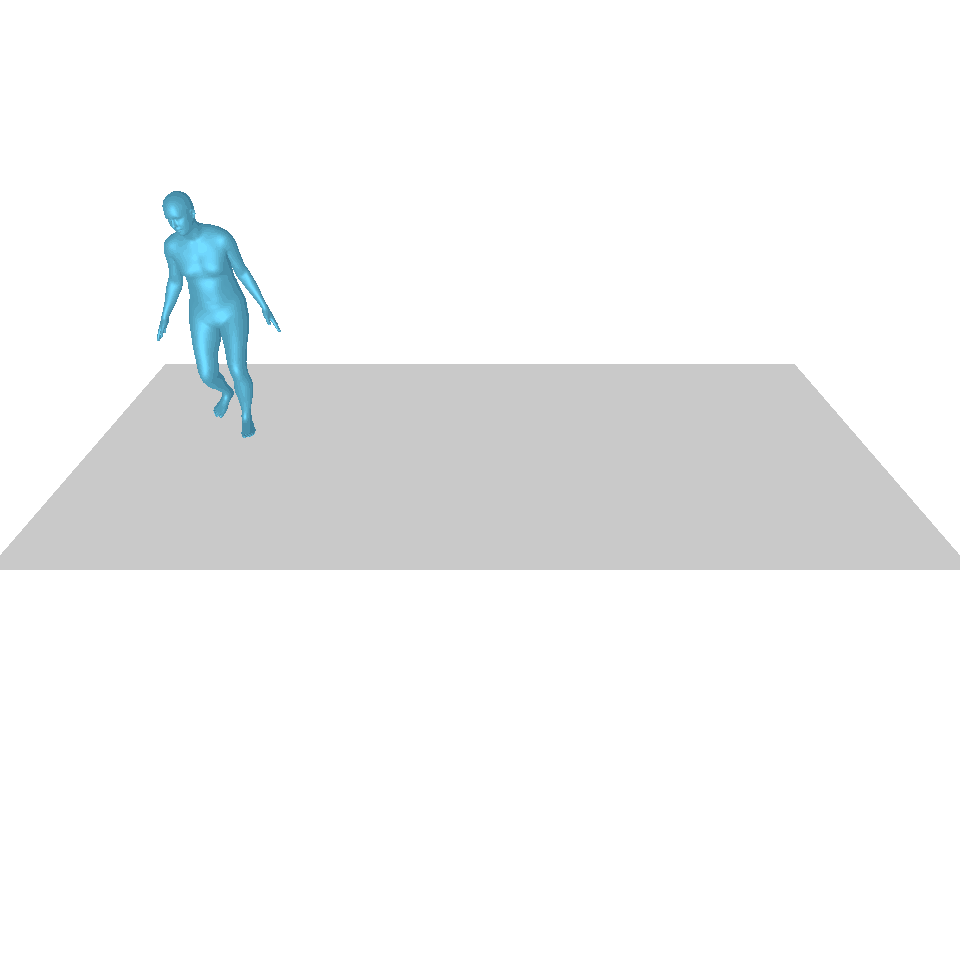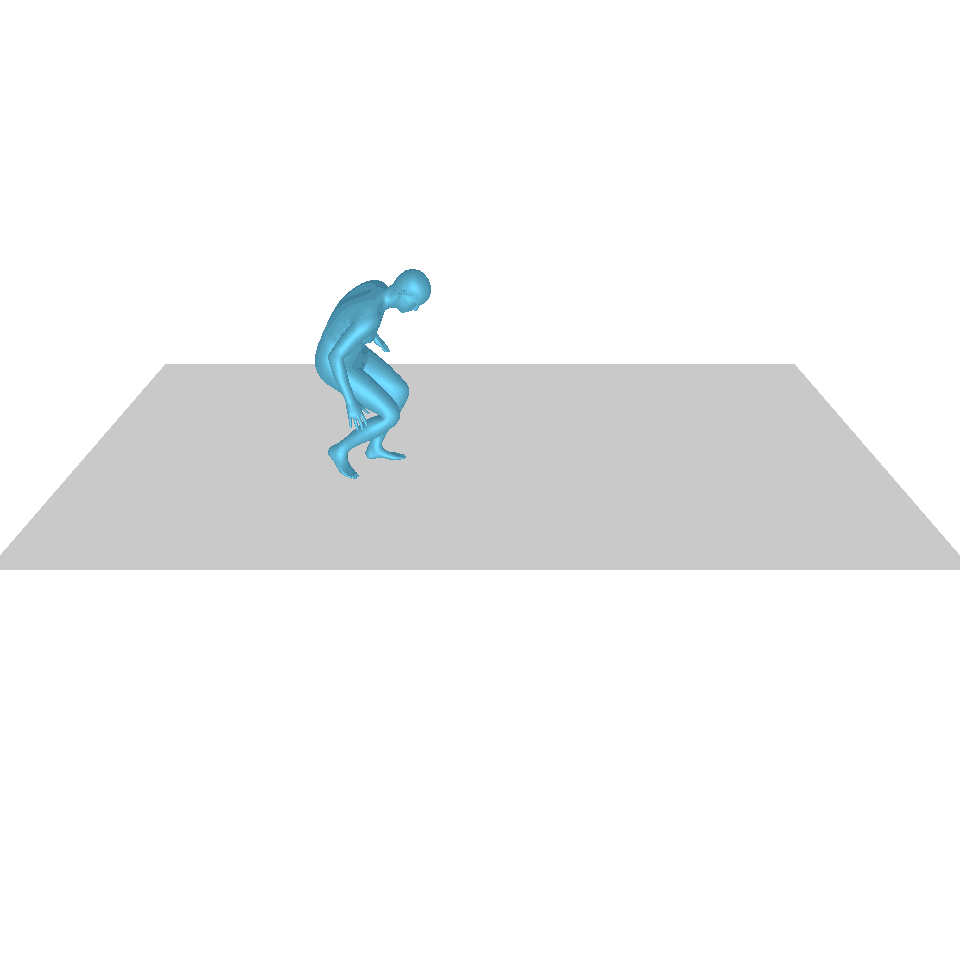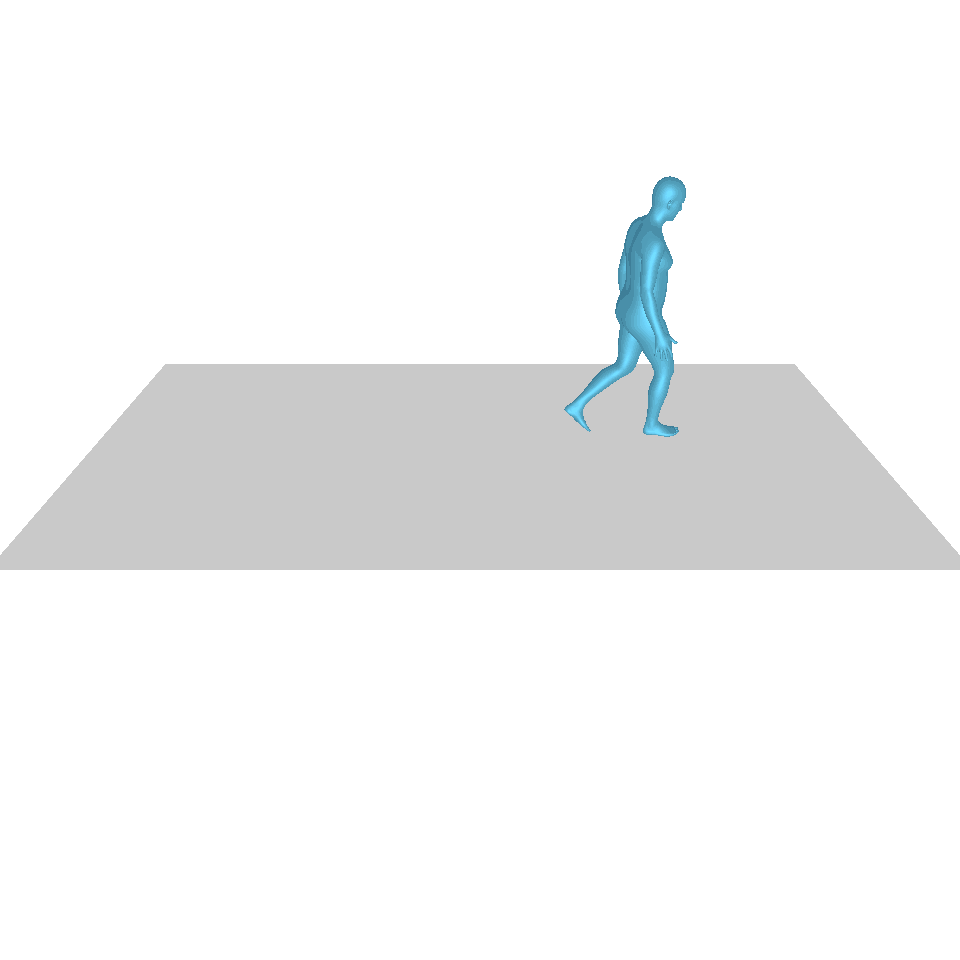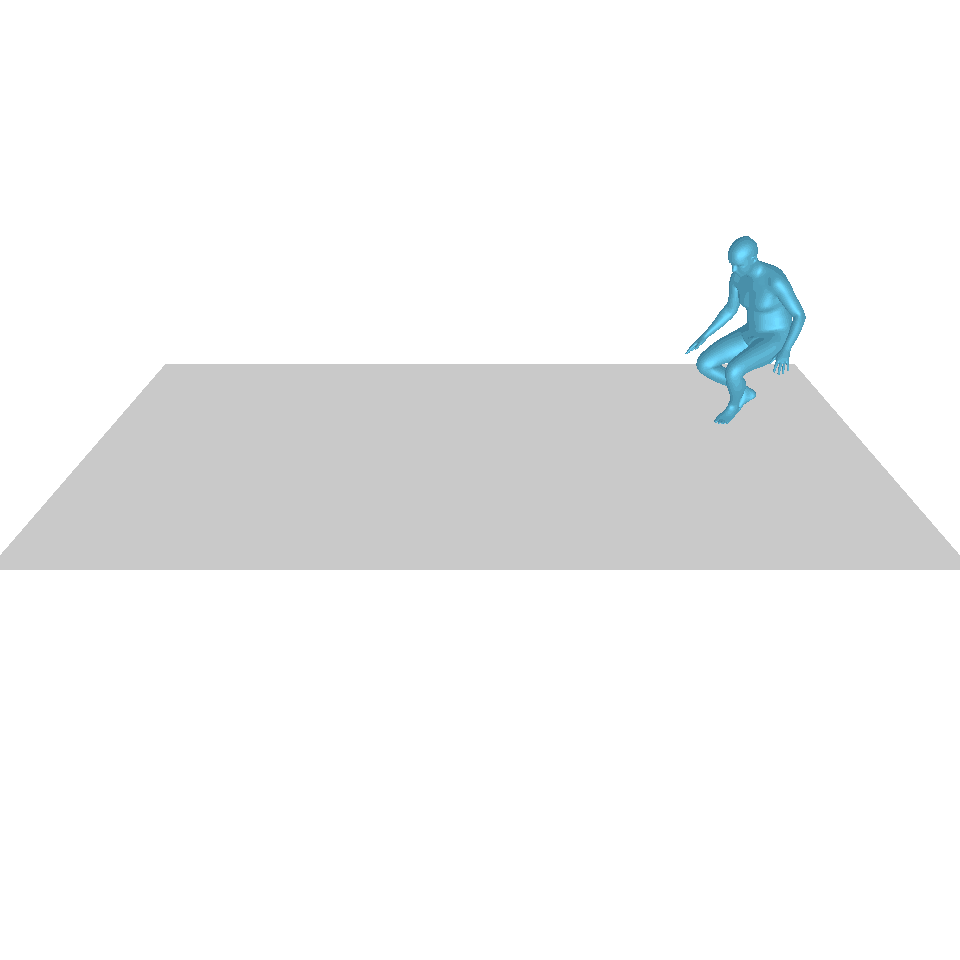
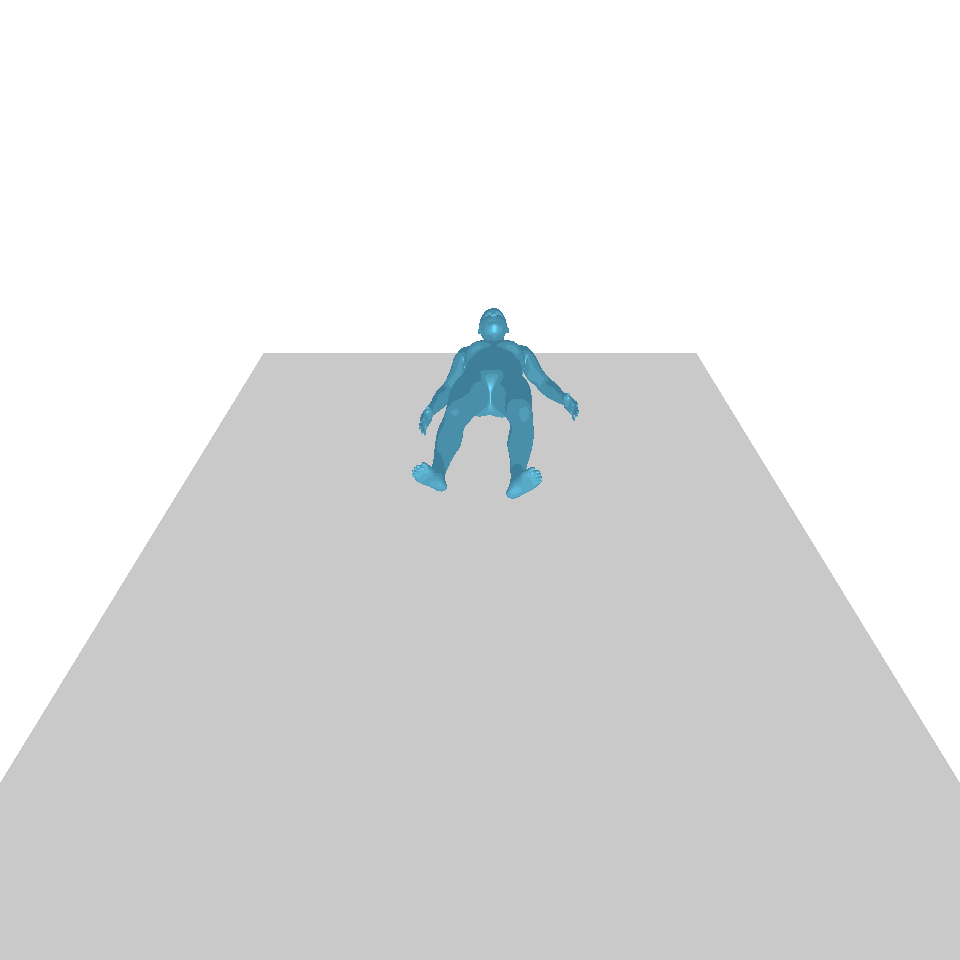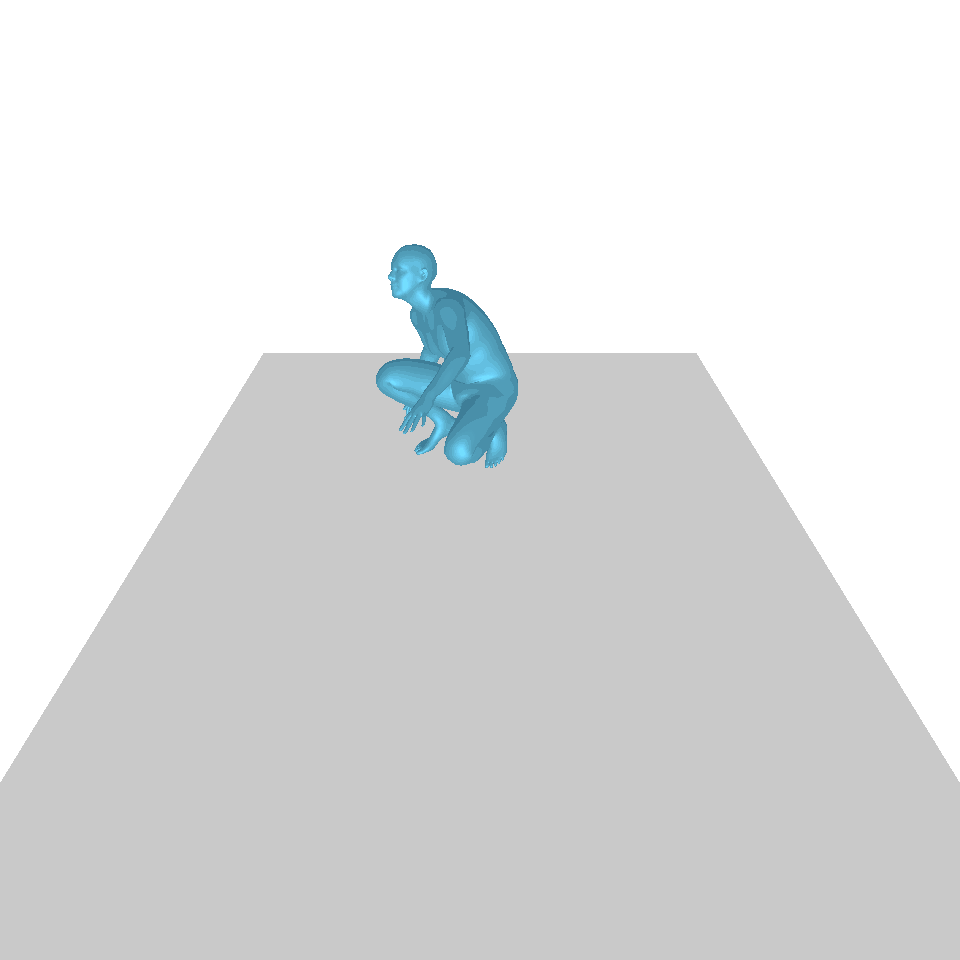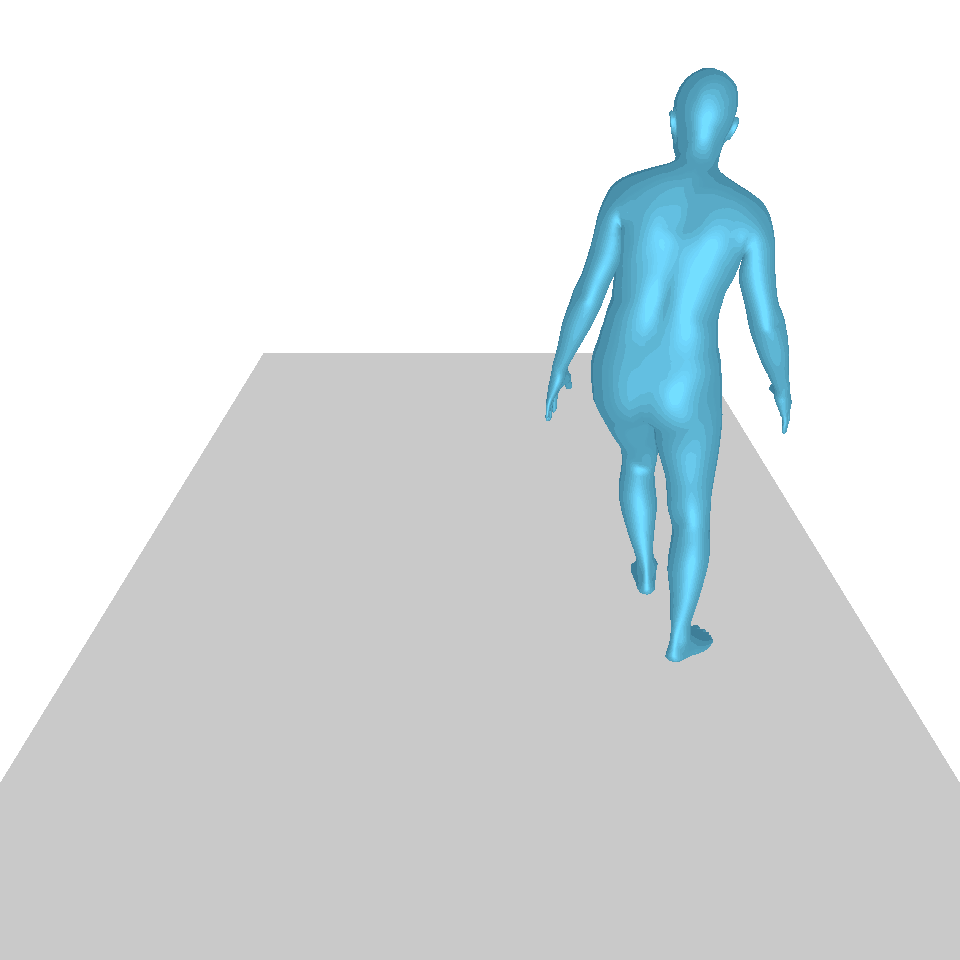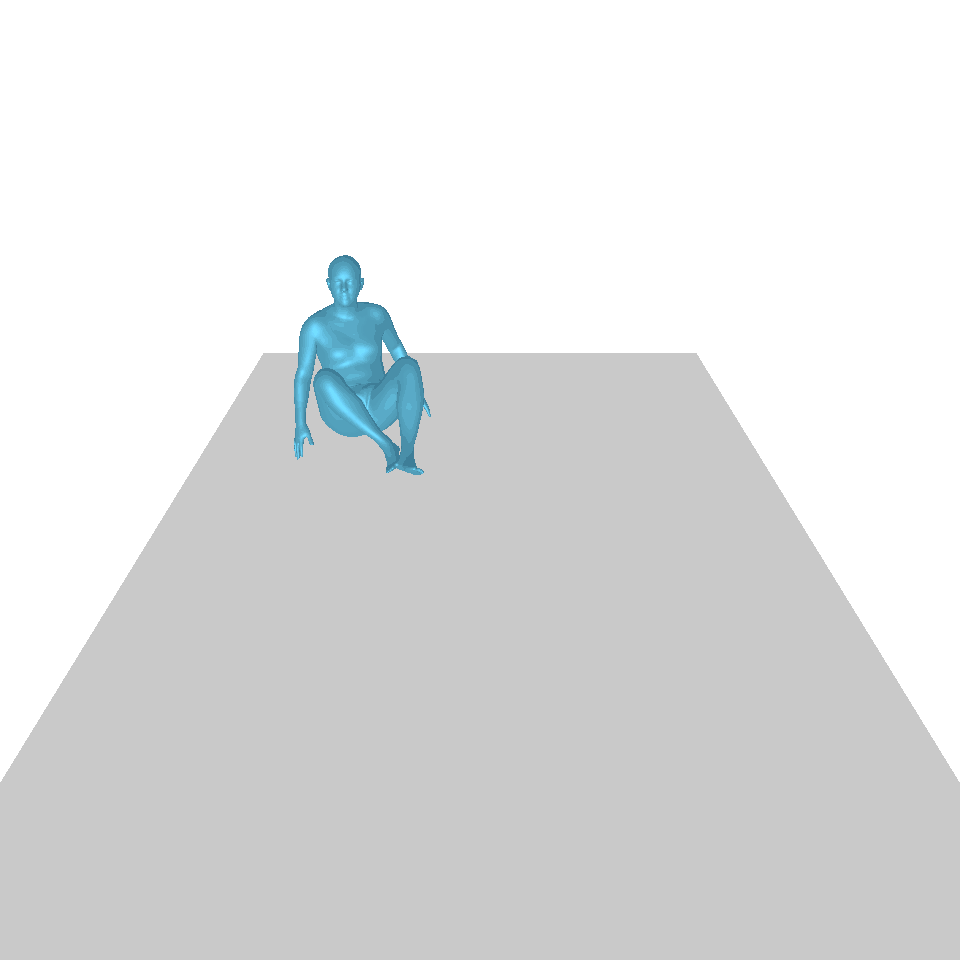
1. Visual Results (More results can be found in our project page)
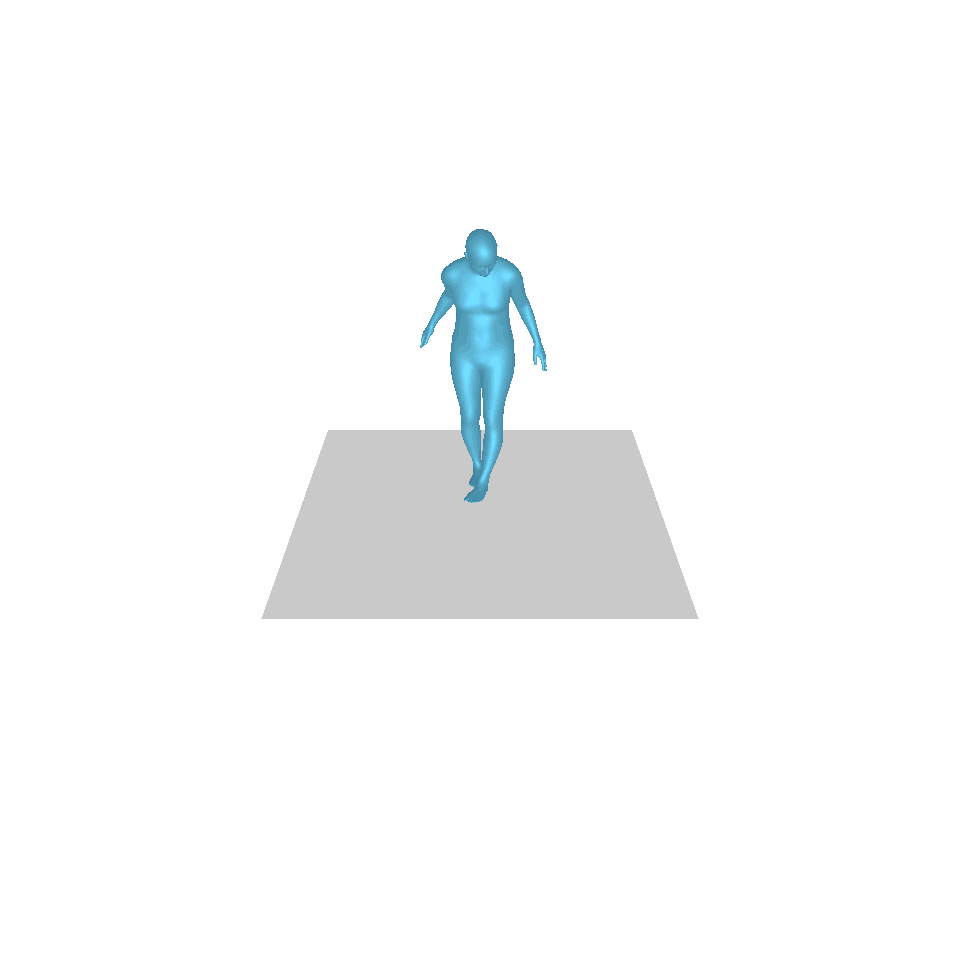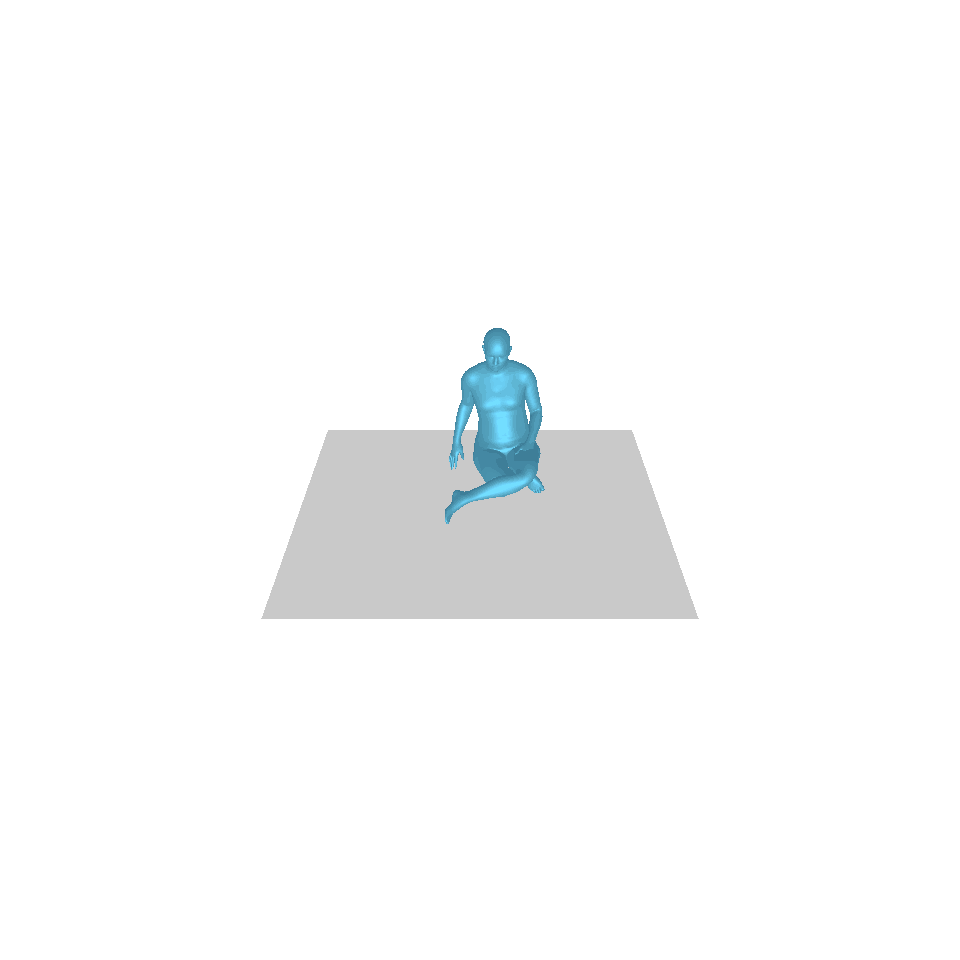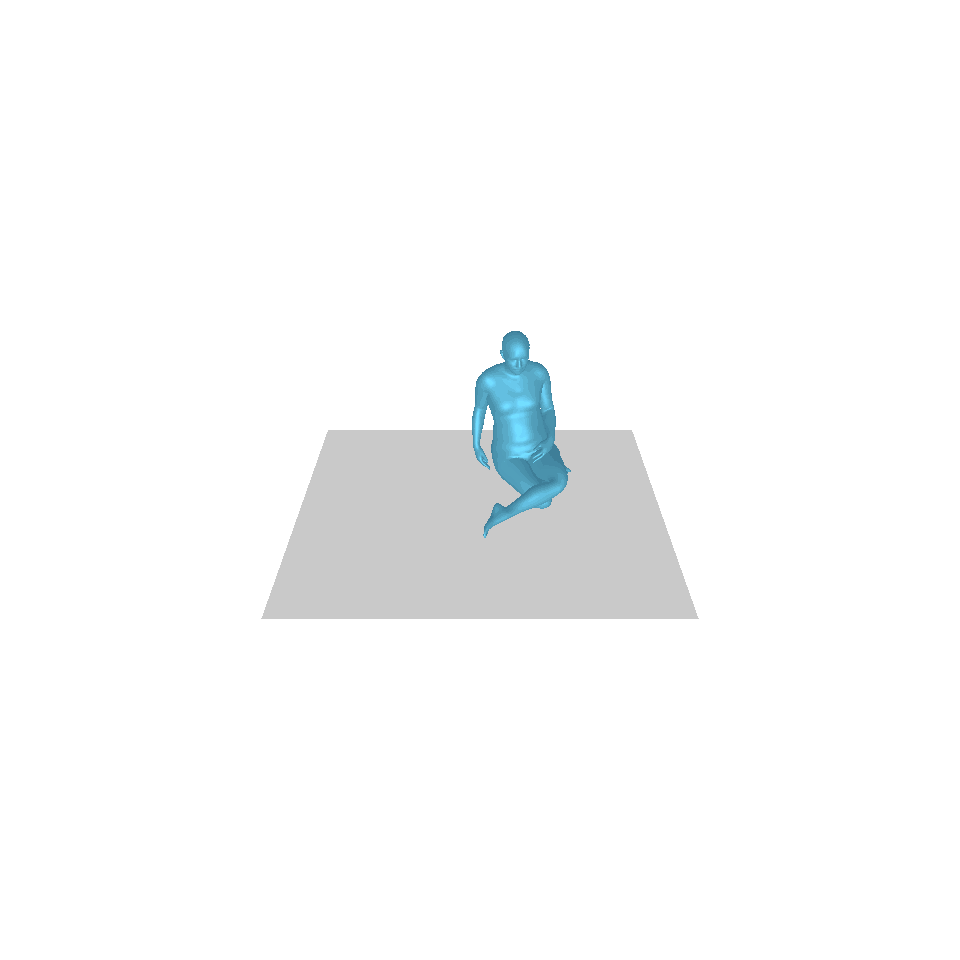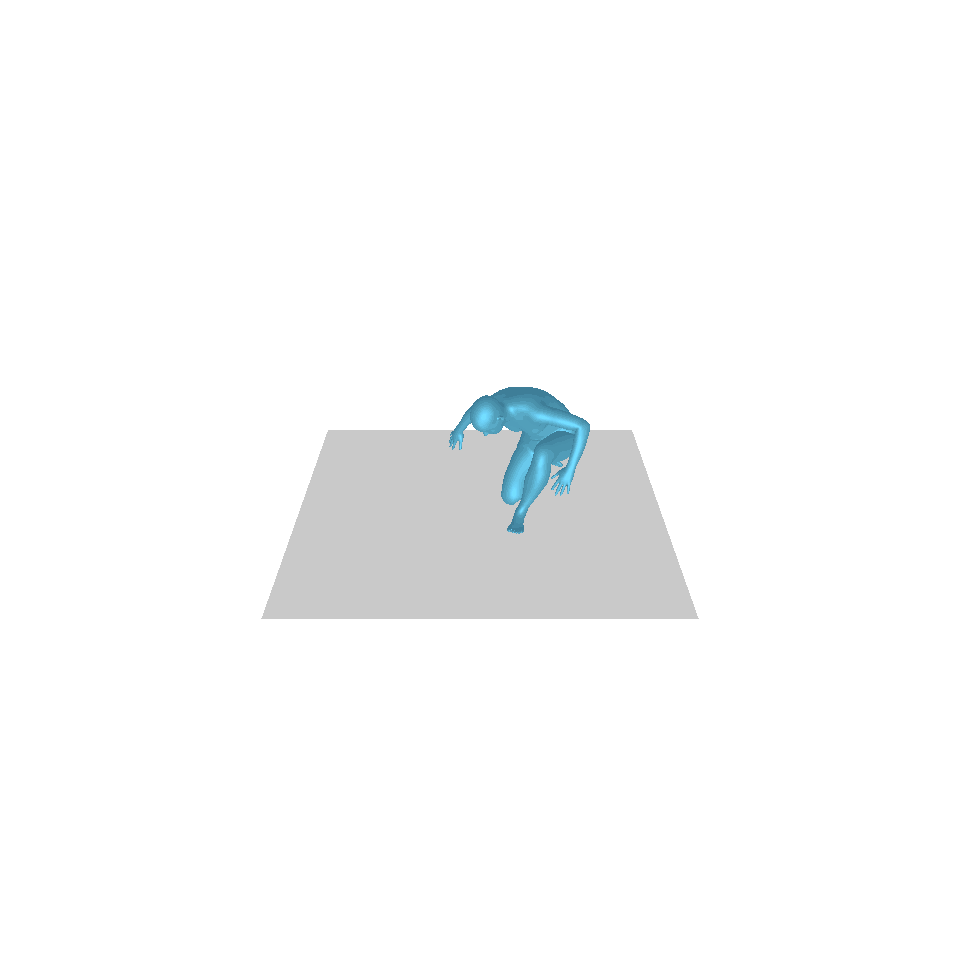
Text: a man steps forward and does a handstand.
GT
Ours
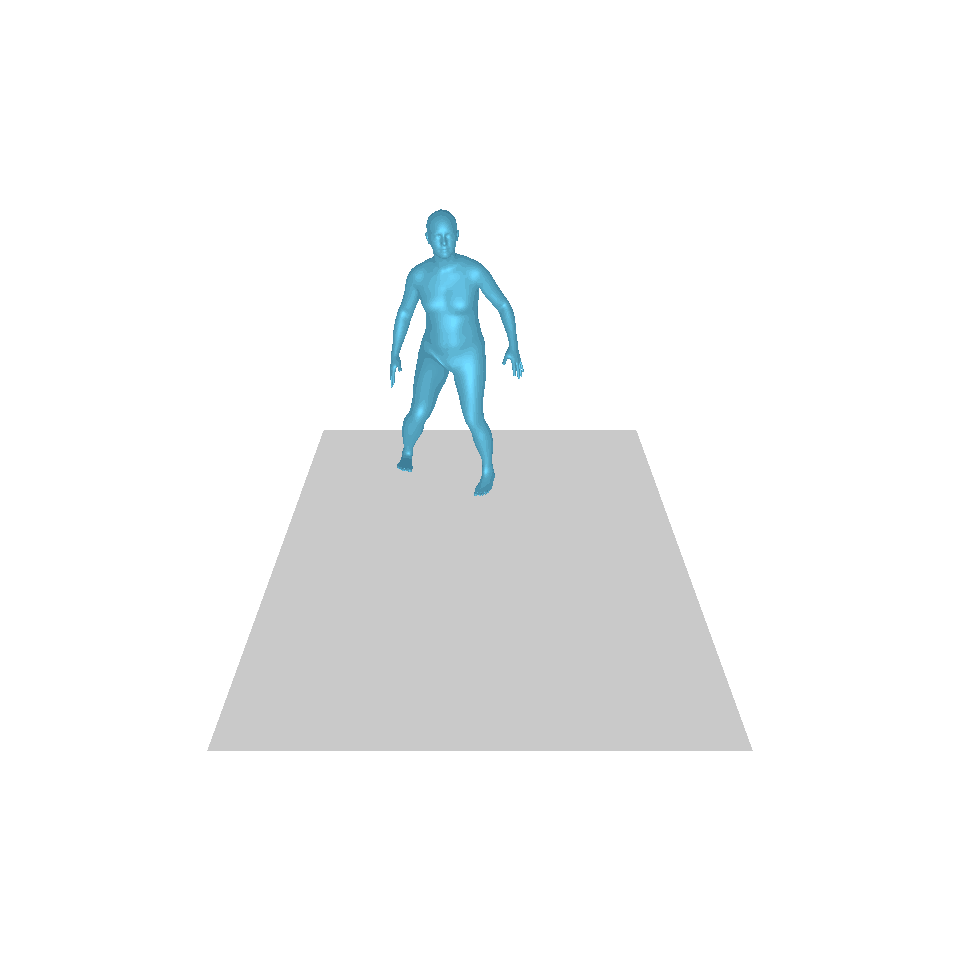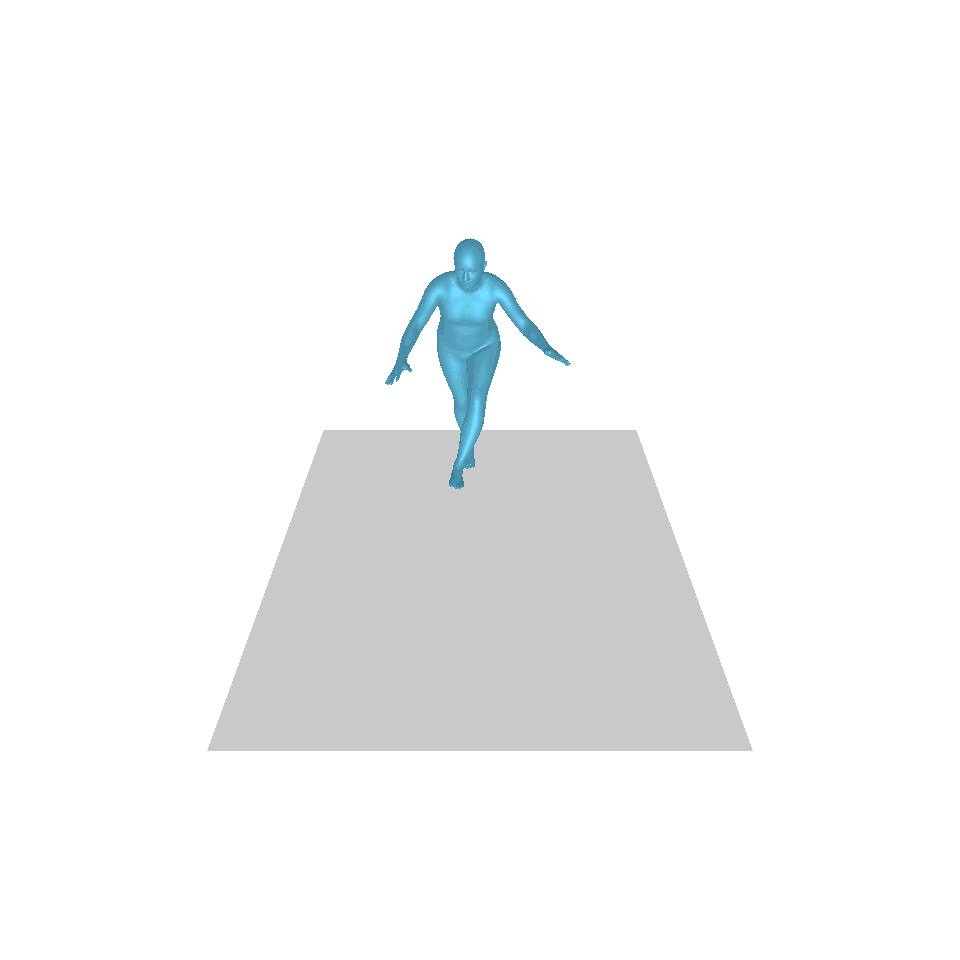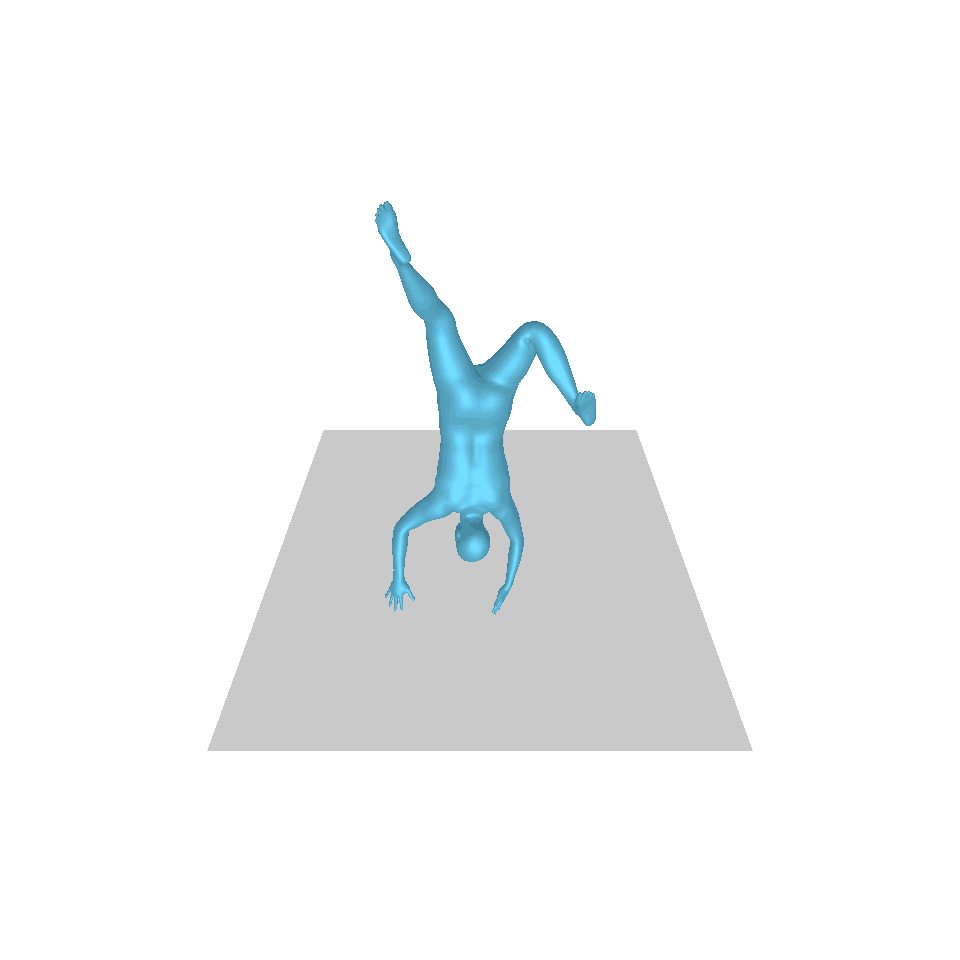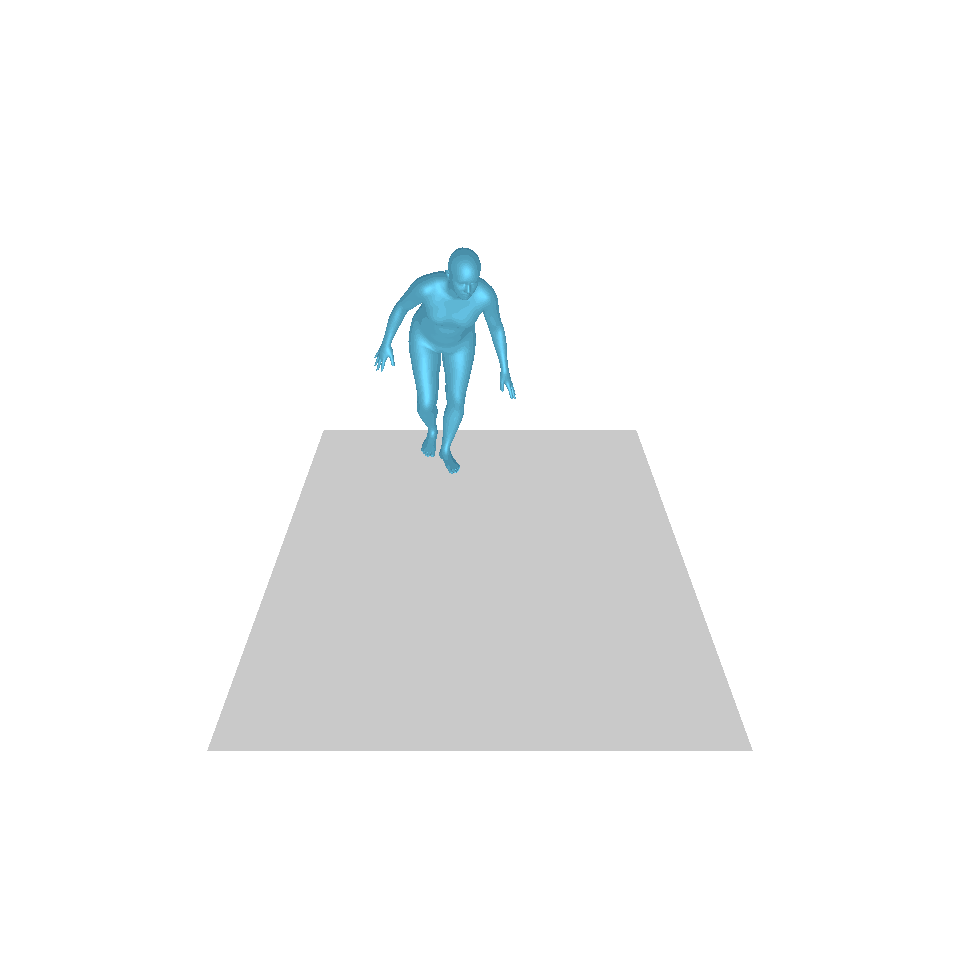
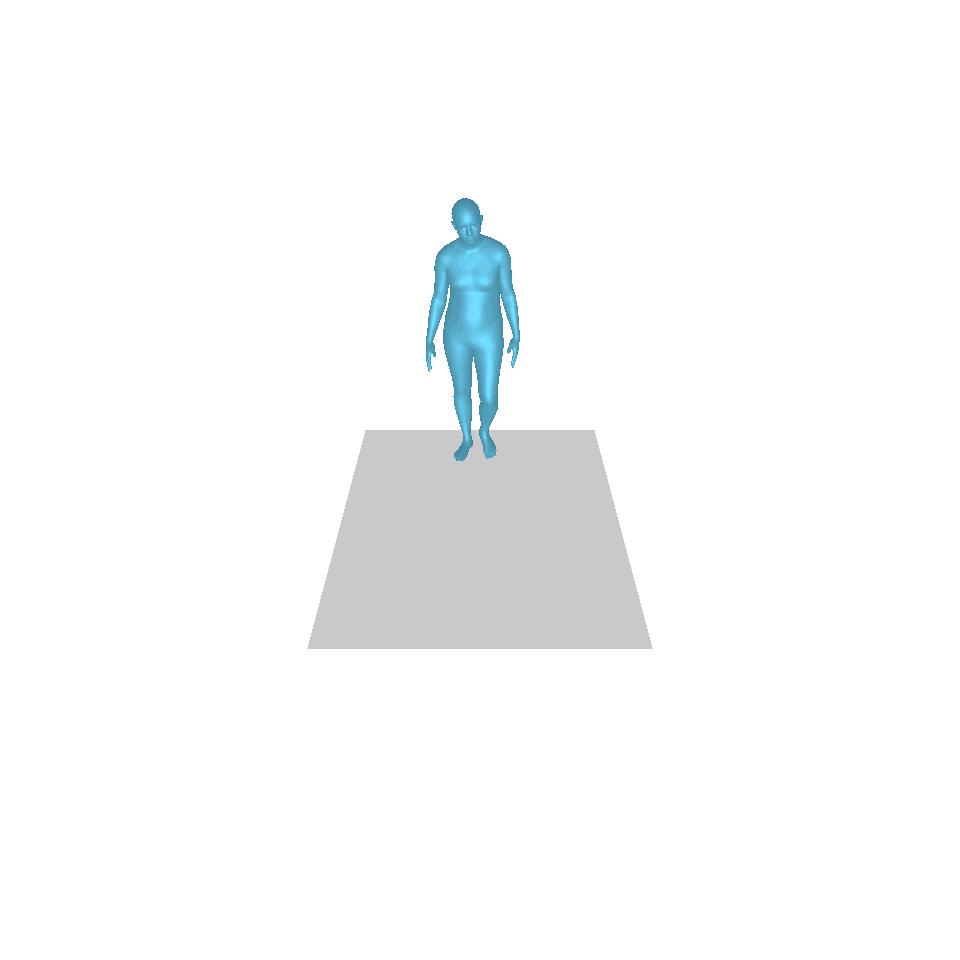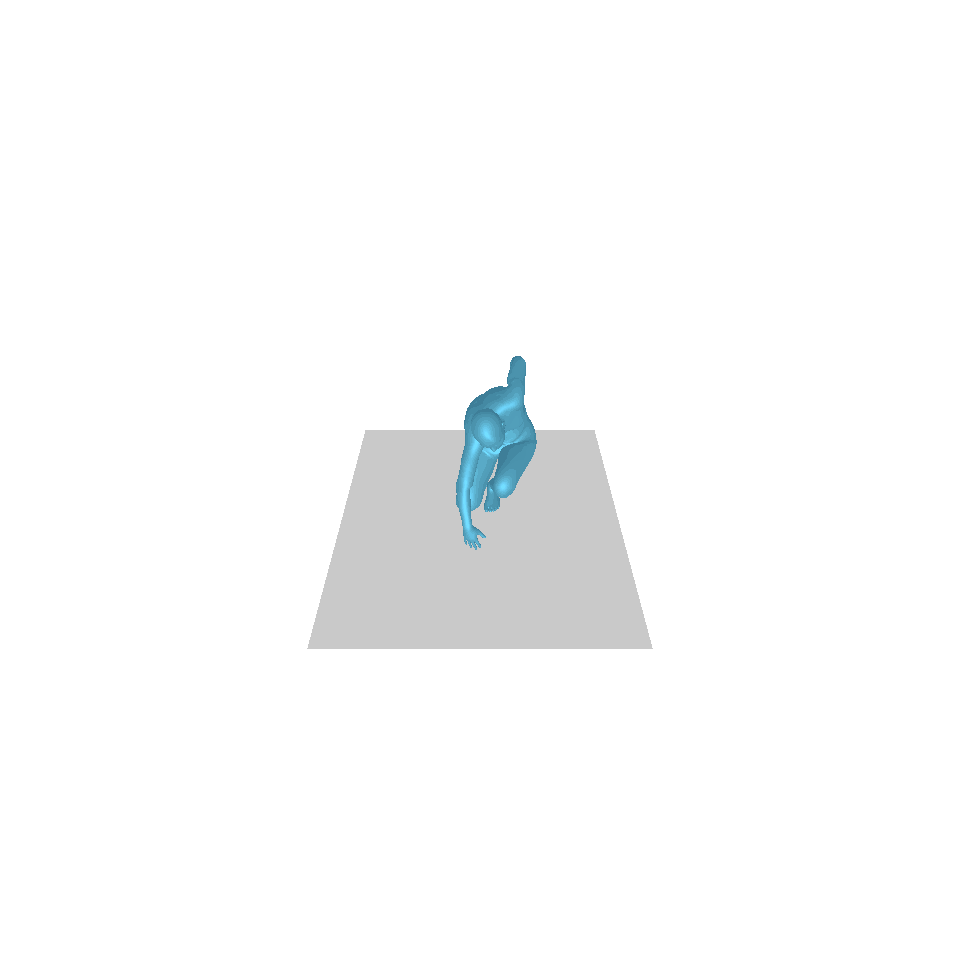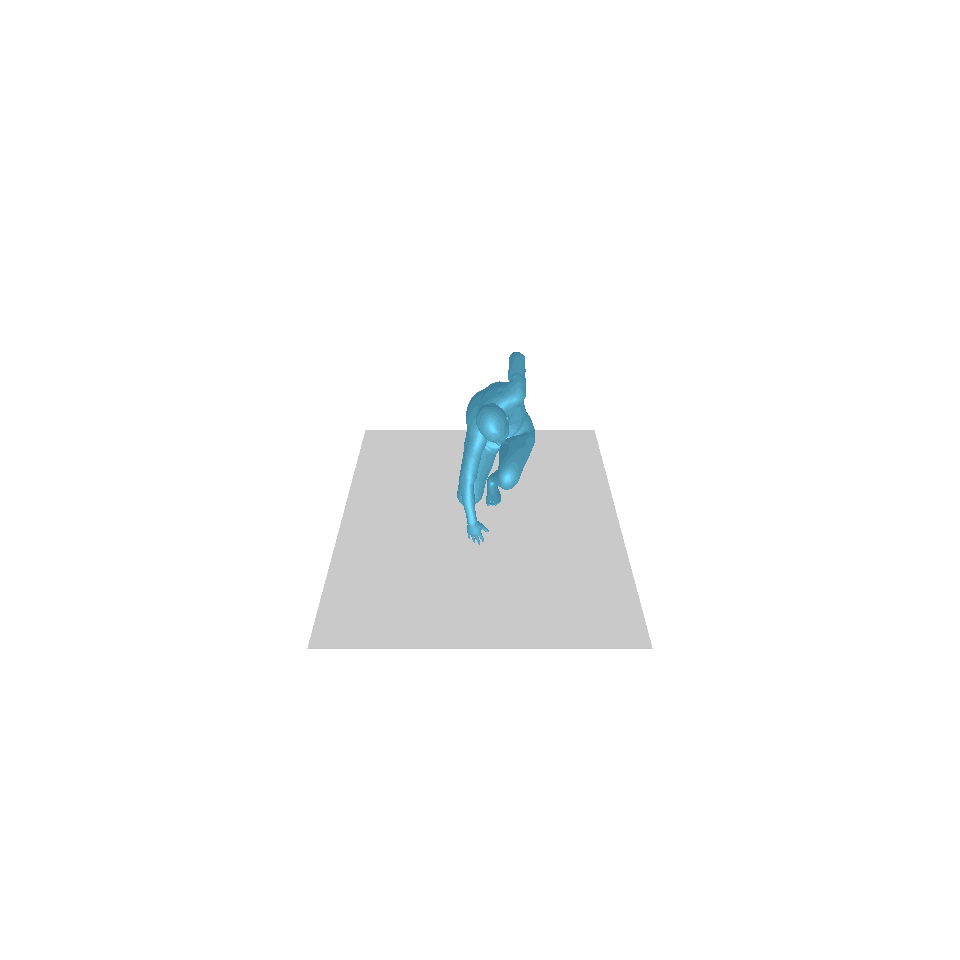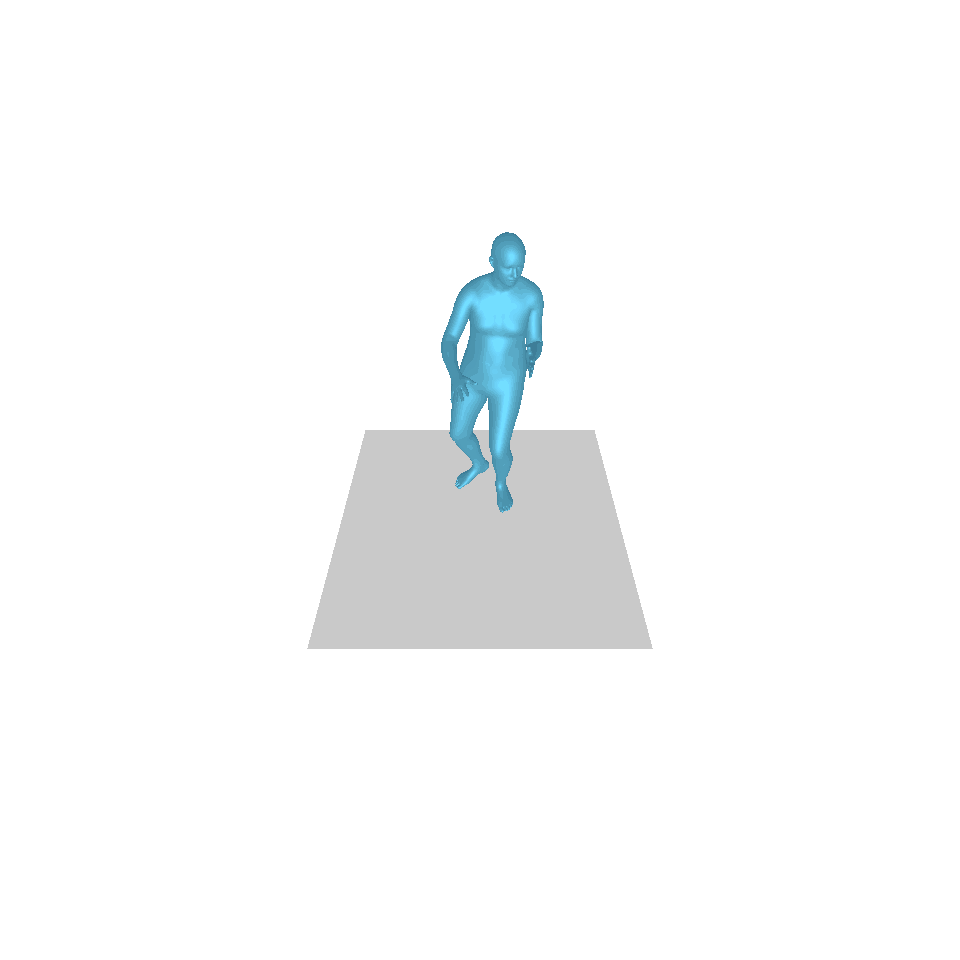
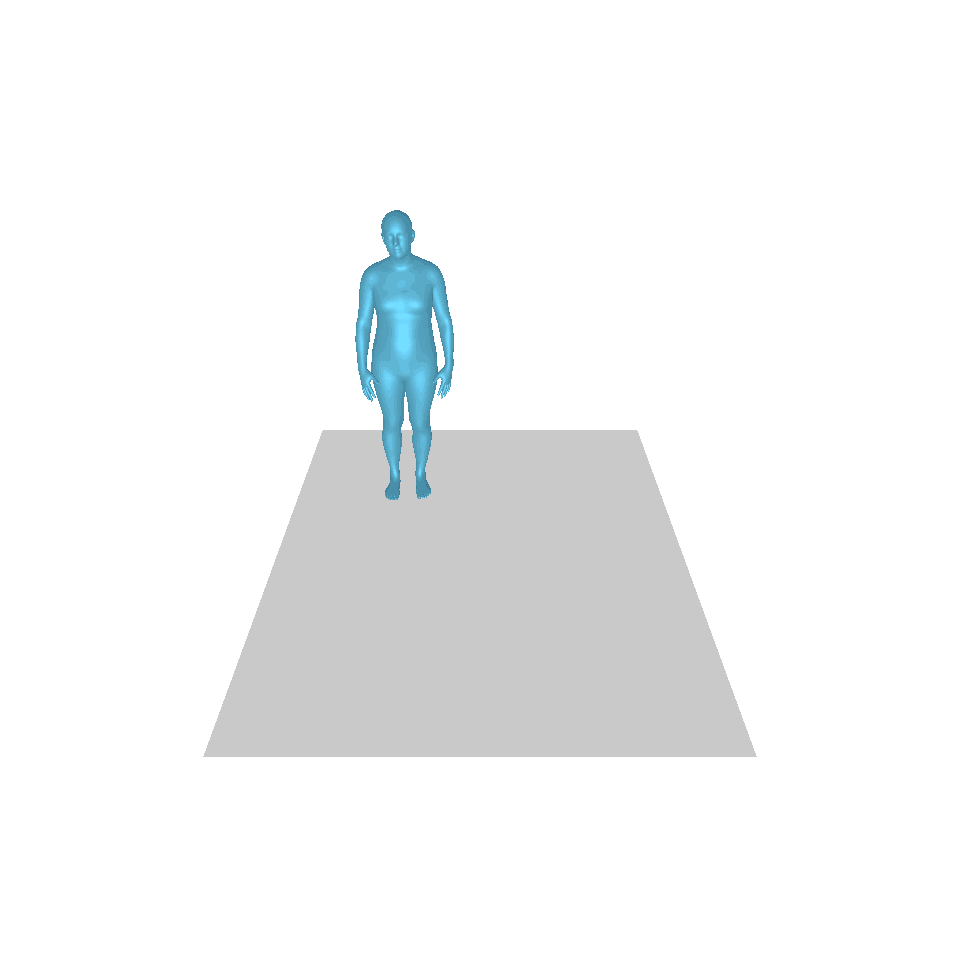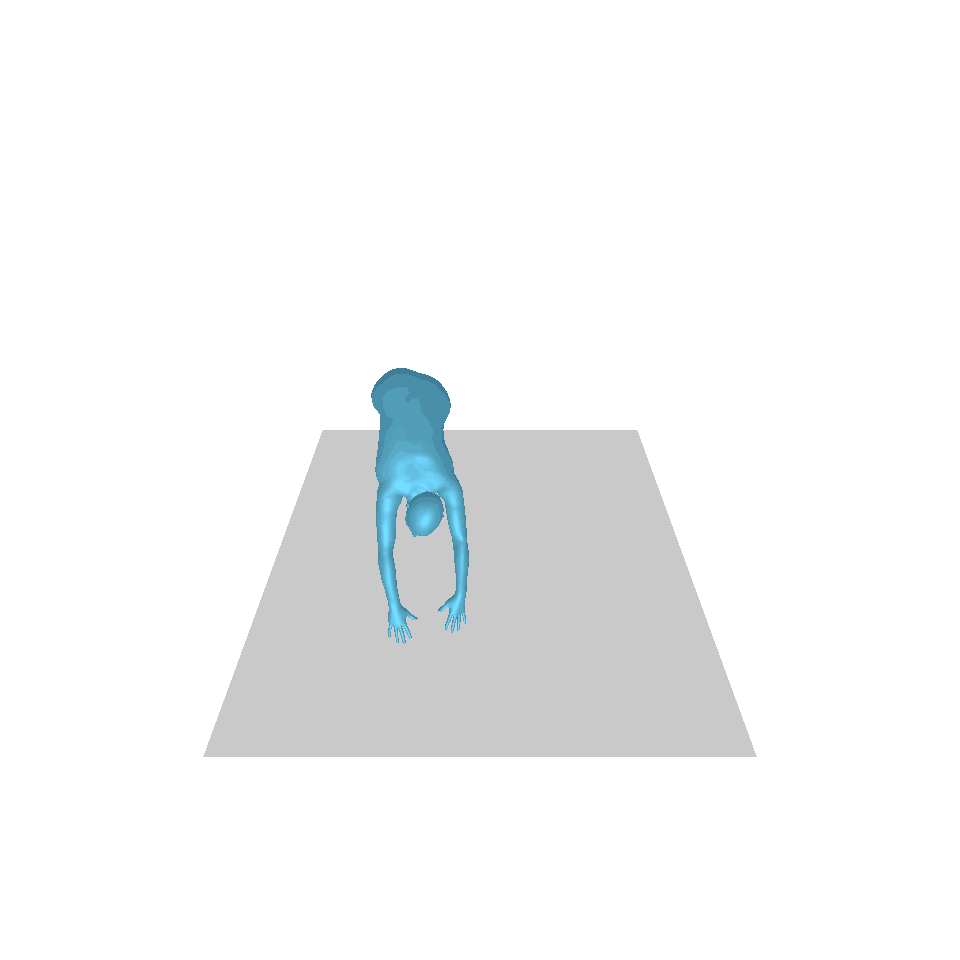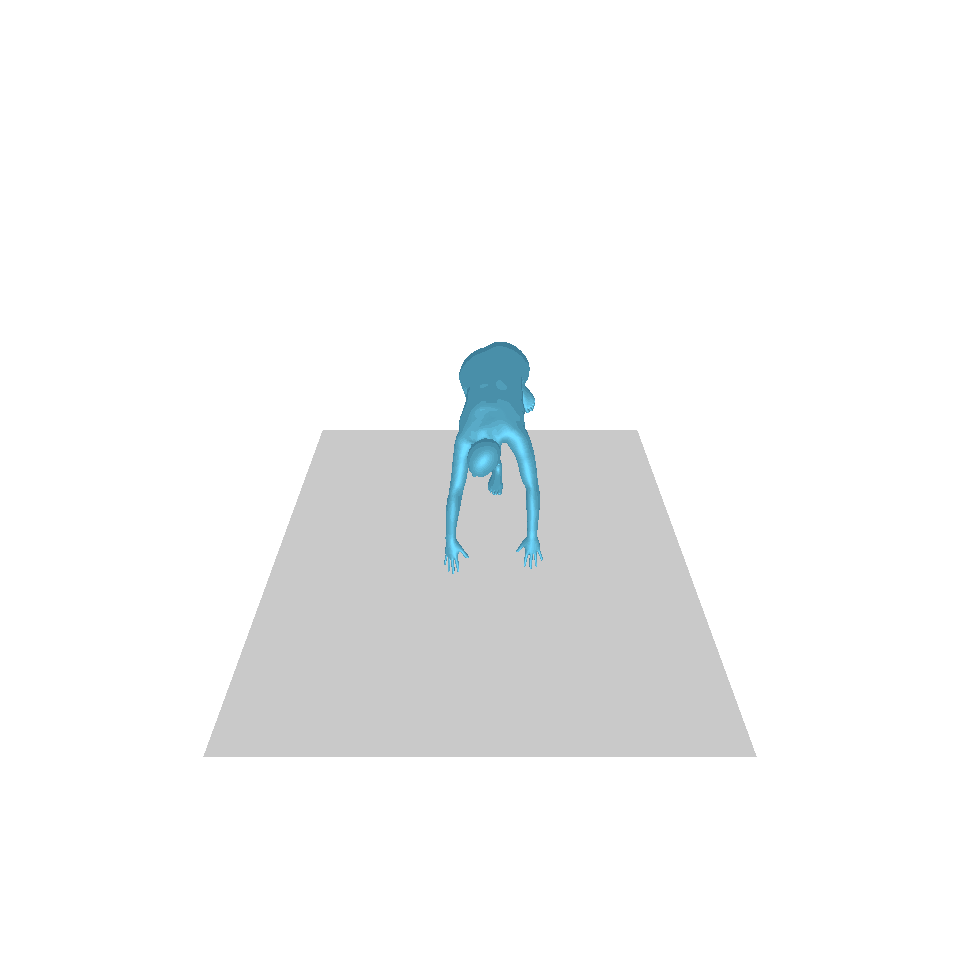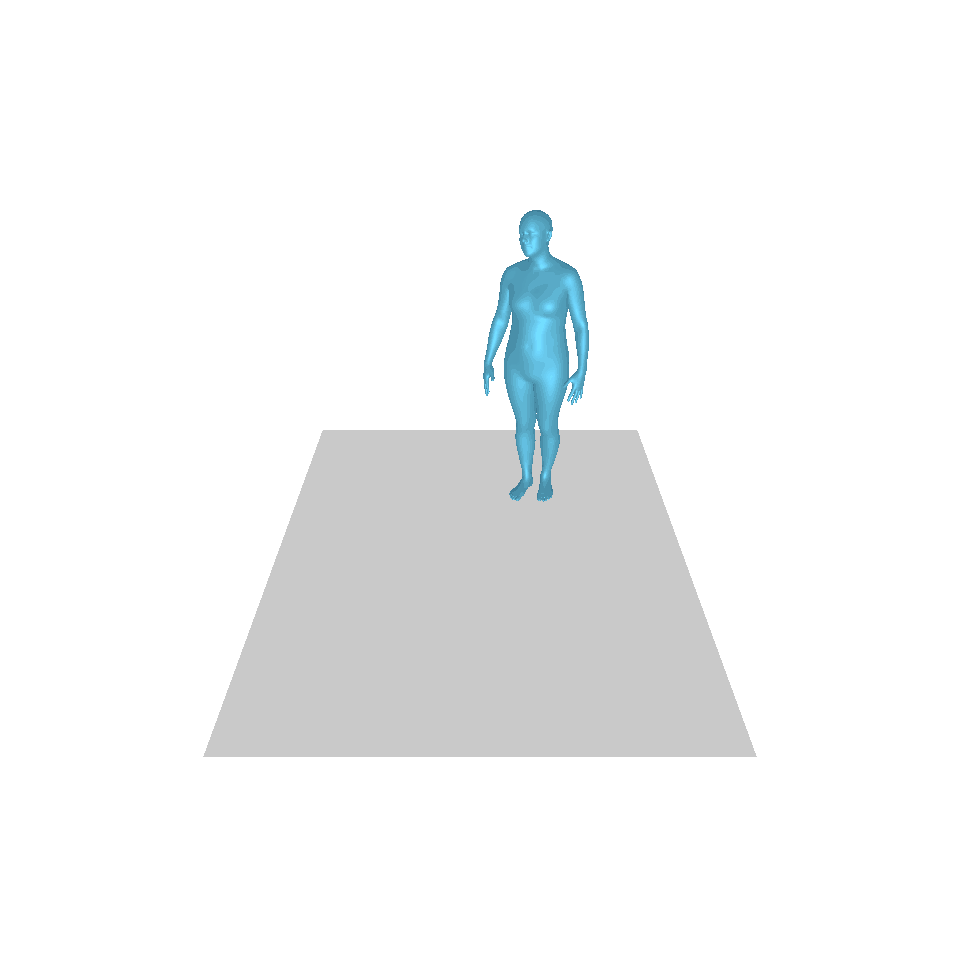
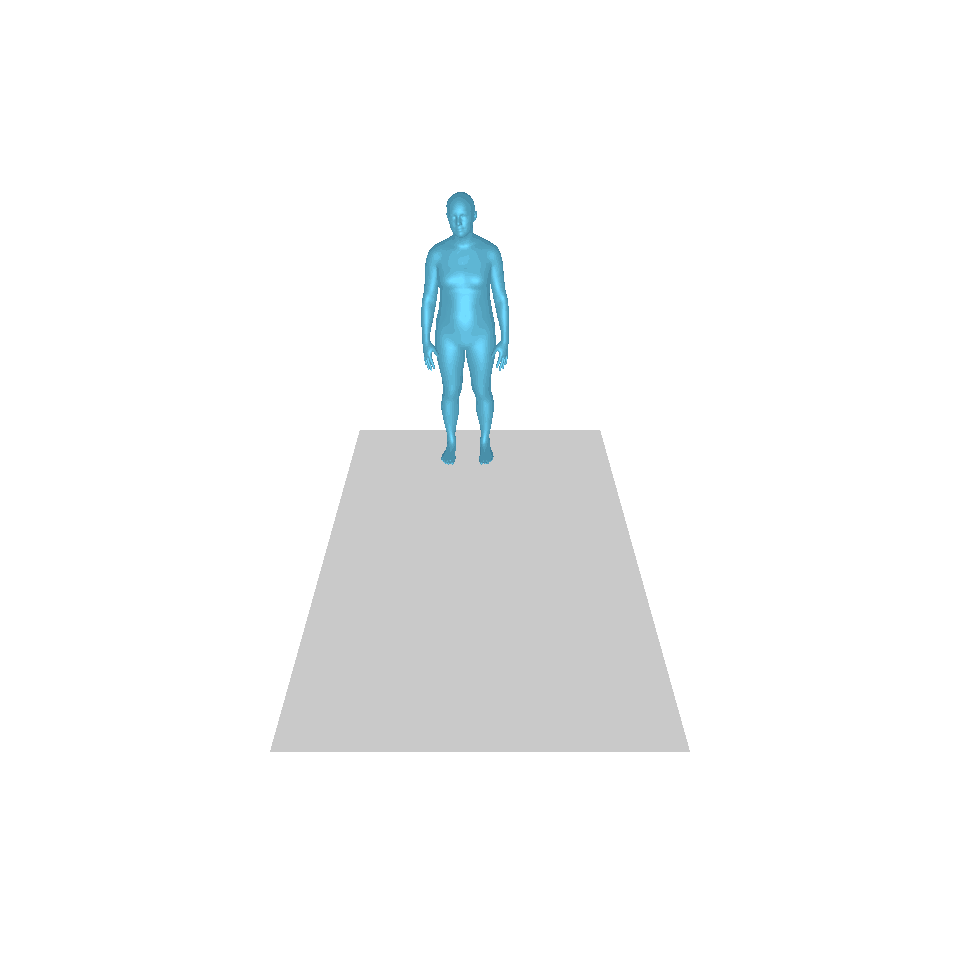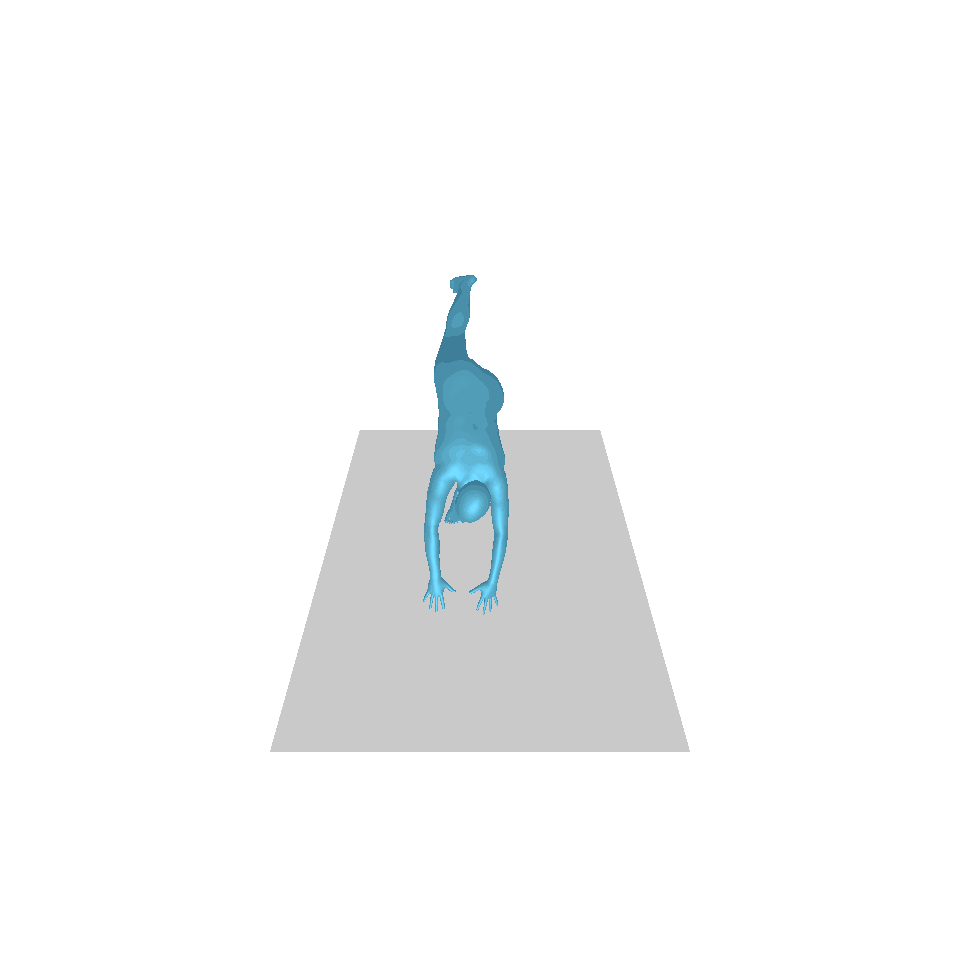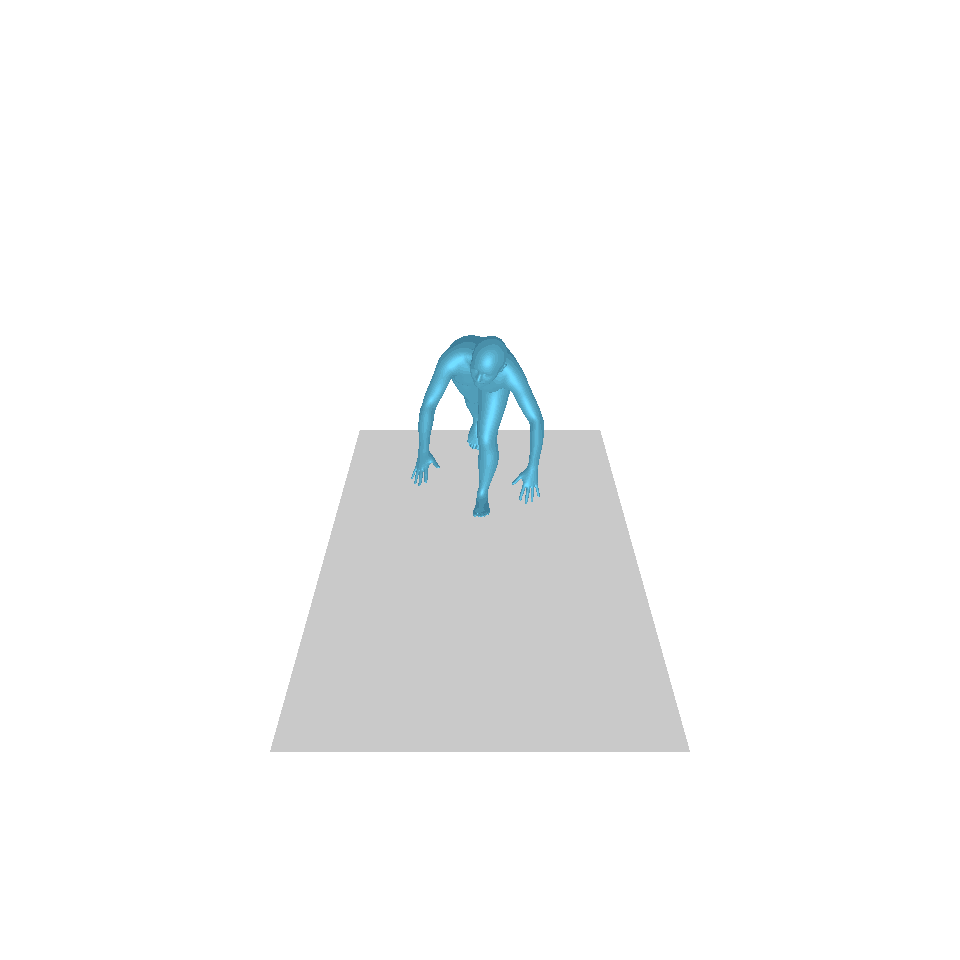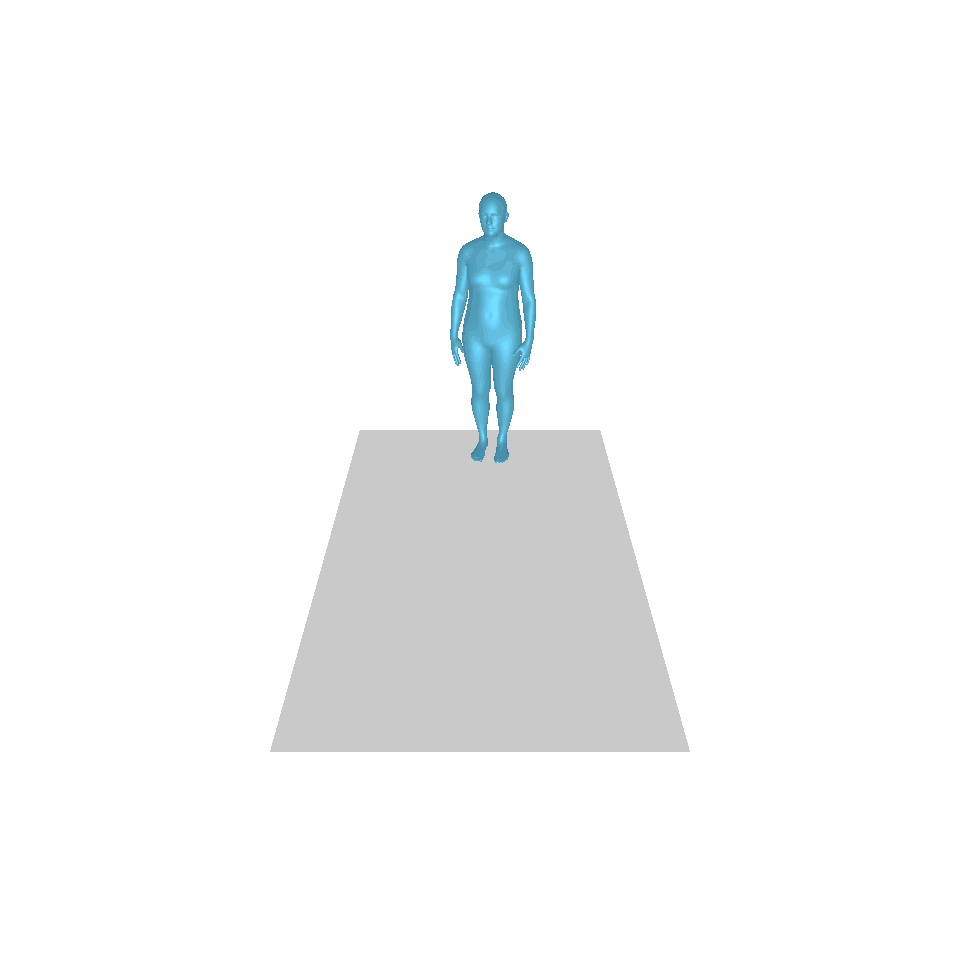
Text: A man rises from the ground, walks in a circle and sits back down on the ground.
GT
Ours
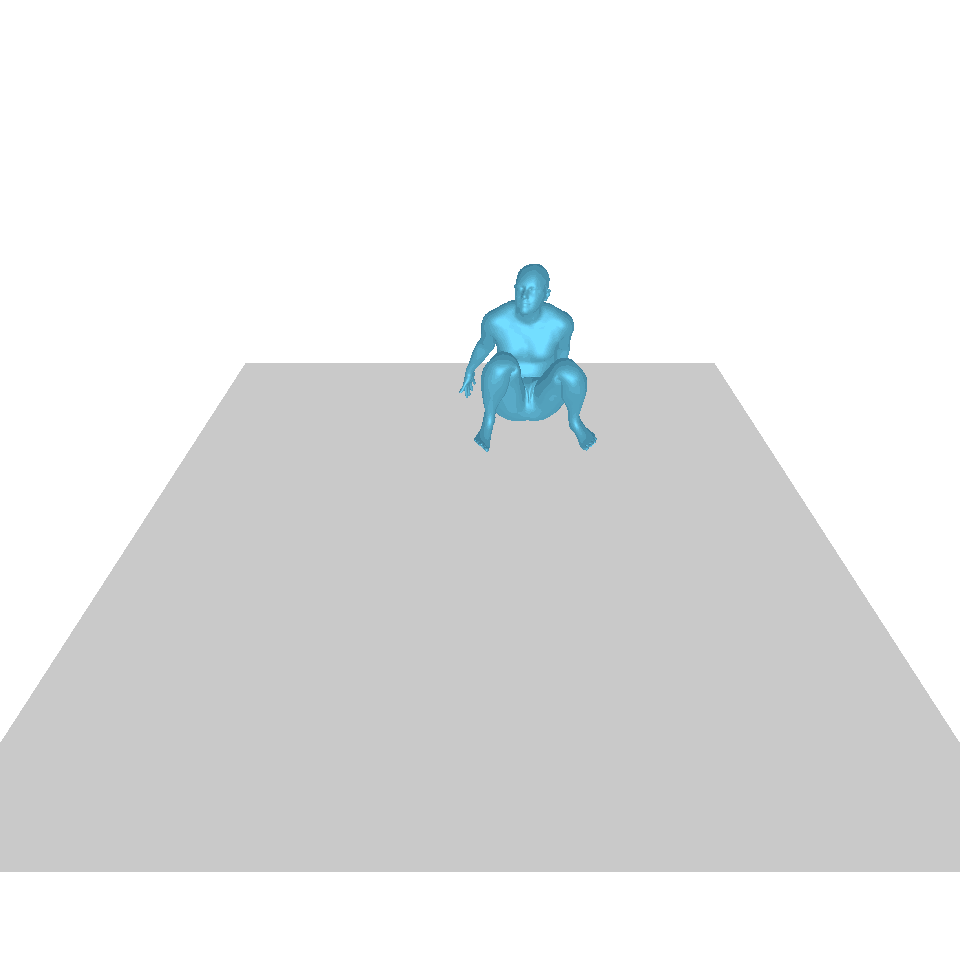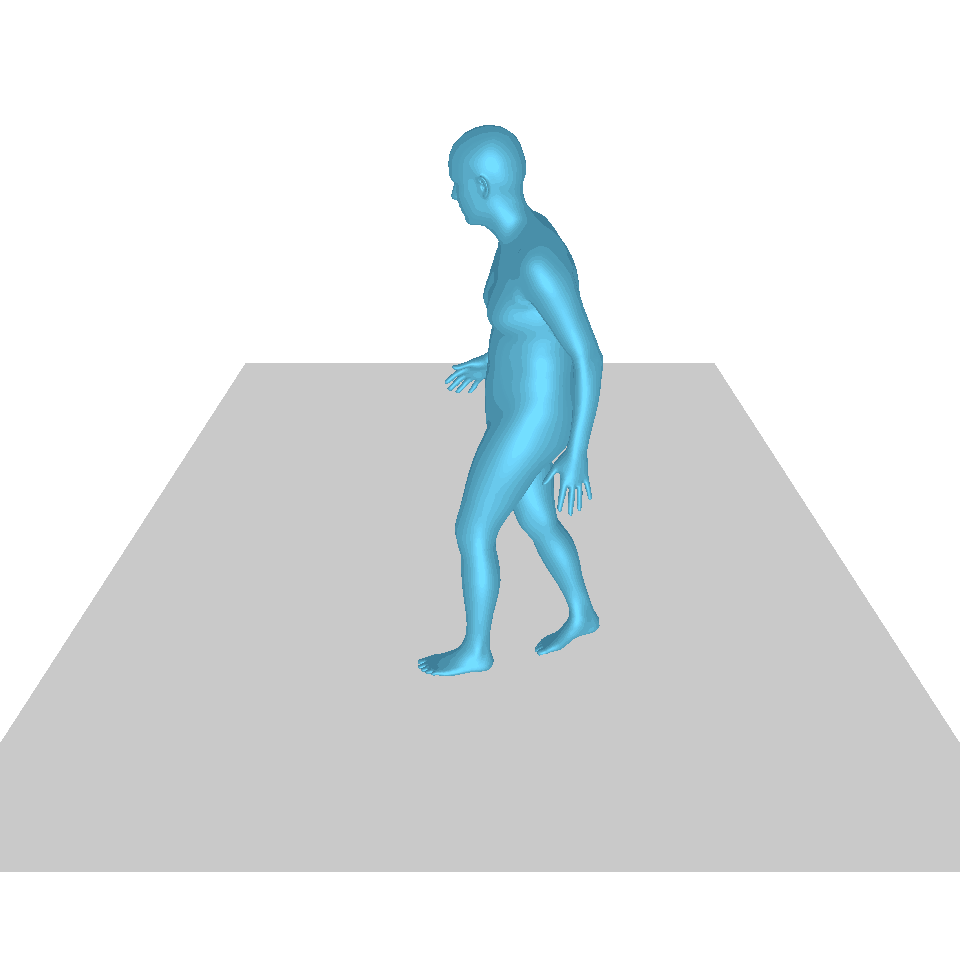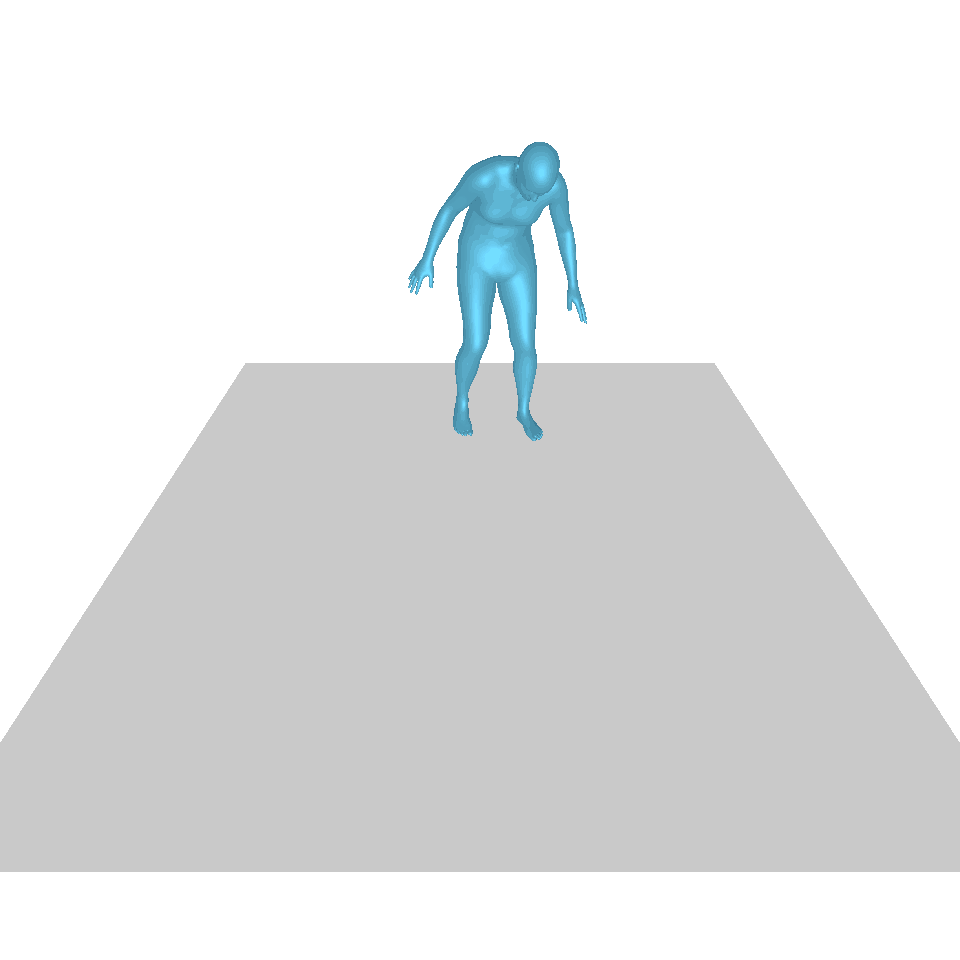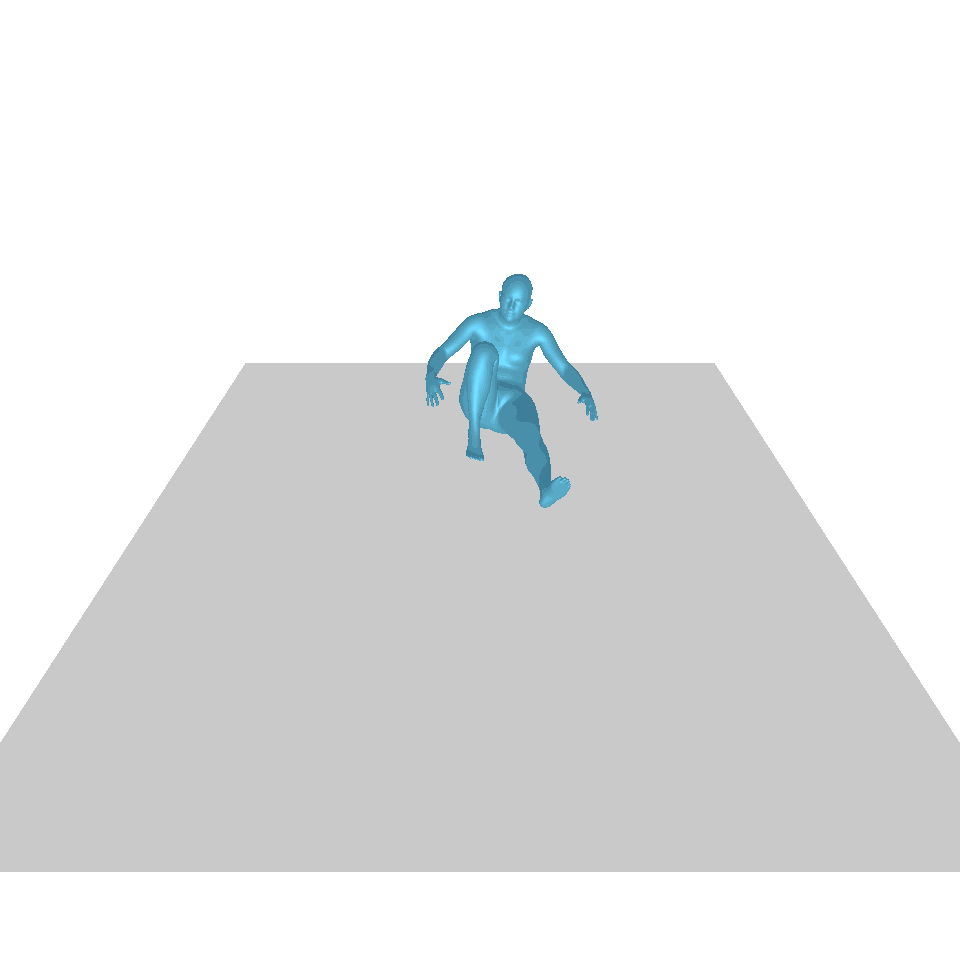
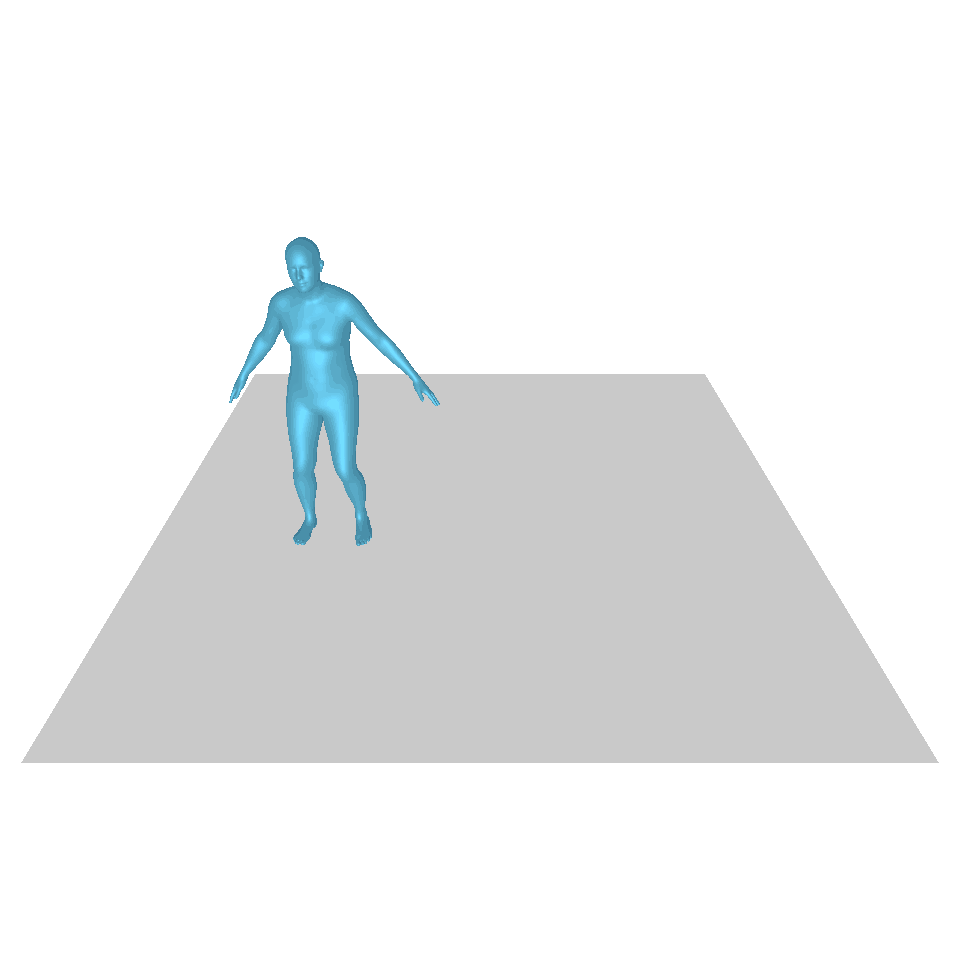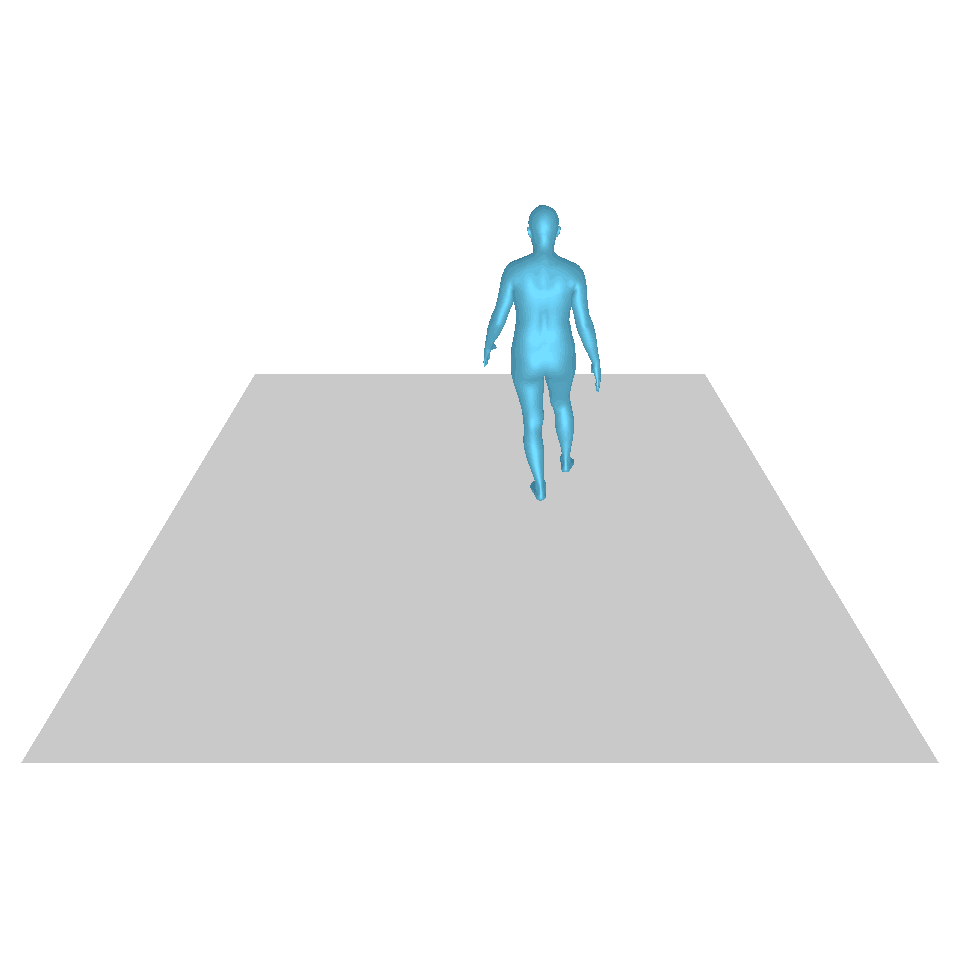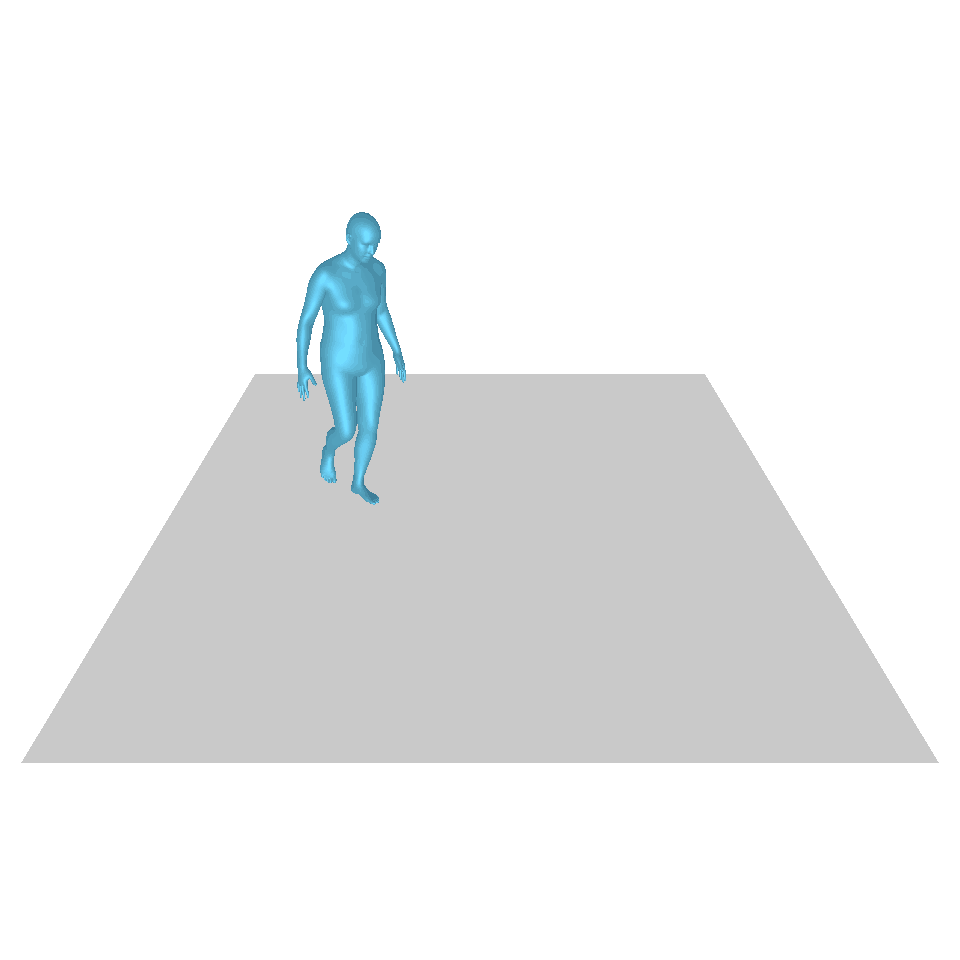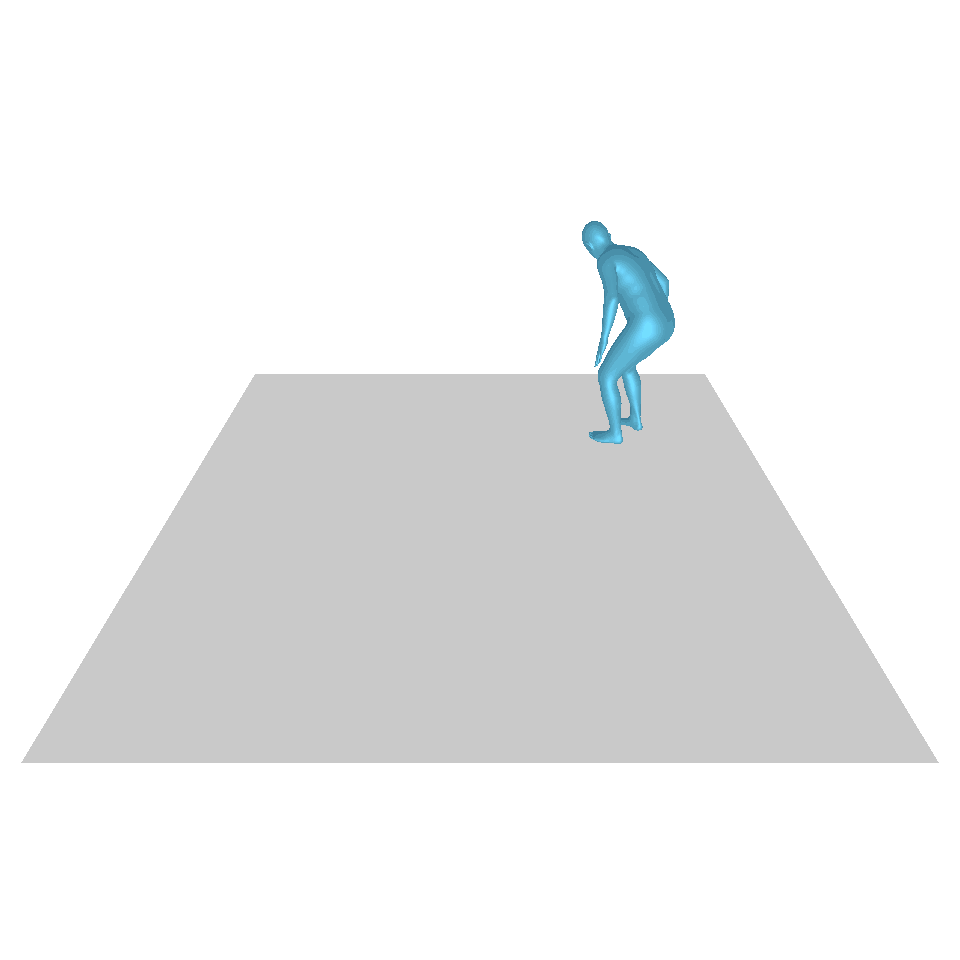
2. Installation
2.1. Environment
Our model can be learnt in a single GPU V100-32G
conda env create -f environment.yml
conda activate T2M-GPT
The code was tested on Python 3.8 and PyTorch 1.8.1.
2.2. Dependencies
bash dataset/prepare/download_glove.sh
2.3. Datasets
We are using two 3D human motion-language dataset: HumanML3D and KIT-ML. For both datasets, you could find the details as well as download link [here].
Take HumanML3D for an example, the file directory should look like this:
./dataset/HumanML3D/
├── new_joint_vecs/
├── texts/
├── Mean.npy # same as in [HumanML3D](https://github.com/EricGuo5513/HumanML3D)
├── Std.npy # same as in [HumanML3D](https://github.com/EricGuo5513/HumanML3D)
├── train.txt
├── val.txt
├── test.txt
├── train_val.txt
└── all.txt
2.4. Motion & text feature extractors:
We use the same extractors provided by t2m to evaluate our generated motions. Please download the extractors.
bash dataset/prepare/download_extractor.sh
2.5. Pre-trained models
The pretrained model files will be stored in the 'pretrained' folder:
bash dataset/prepare/download_model.sh
2.6. Render SMPL mesh (optional)
If you want to render the generated motion, you need to install:
sudo sh dataset/prepare/download_smpl.sh
conda install -c menpo osmesa
conda install h5py
conda install -c conda-forge shapely pyrender trimesh mapbox_earcut
3. Quick Start
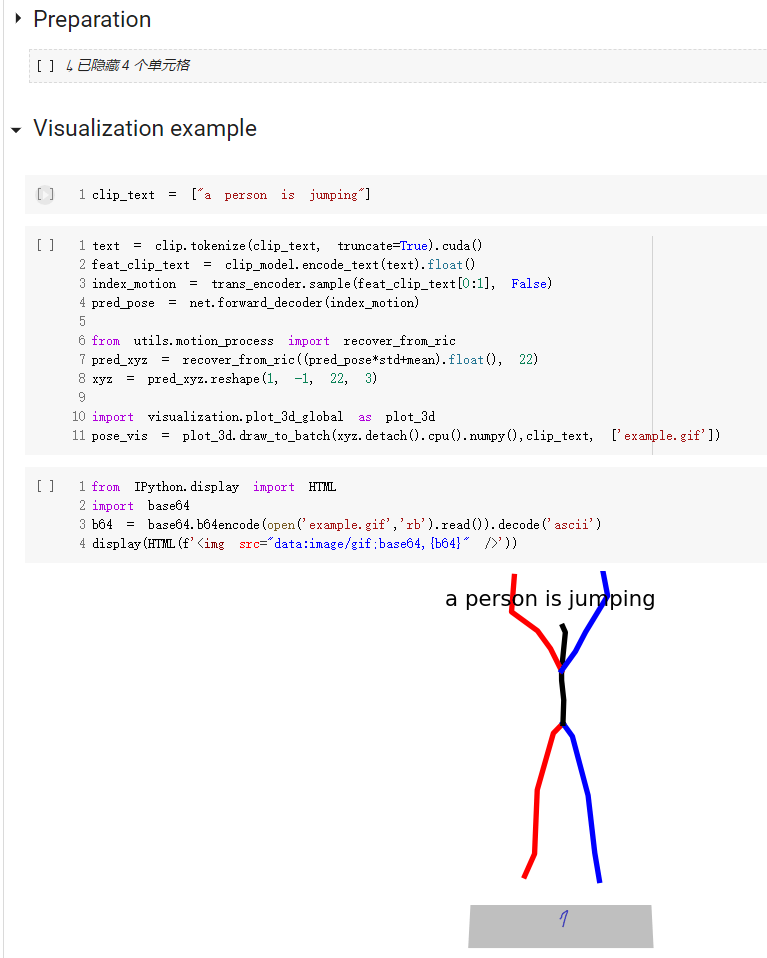
A quick start guide of how to use our code is available in demo.ipynb
4. Train
Note that, for kit dataset, just need to set '--dataname kit'.
4.1. VQ-VAE
The results are saved in the folder output.
VQ training
python3 train_vq.py \
--batch-size 256 \
--lr 2e-4 \
--total-iter 300000 \
--lr-scheduler 200000 \
--nb-code 512 \
--down-t 2 \
--depth 3 \
--dilation-growth-rate 3 \
--out-dir output \
--dataname t2m \
--vq-act relu \
--quantizer ema_reset \
--loss-vel 0.5 \
--recons-loss l1_smooth \
--exp-name VQVAE
4.2. GPT
The results are saved in the folder output.
GPT training
python3 train_t2m_trans.py  \
--exp-name GPT \
--batch-size 128 \
--num-layers 9 \
--embed-dim-gpt 1024 \
--nb-code 512 \
--n-head-gpt 16 \
--block-size 51 \
--ff-rate 4 \
--drop-out-rate 0.1 \
--resume-pth output/VQVAE/net_last.pth \
--vq-name VQVAE \
--out-dir output \
--total-iter 300000 \
--lr-scheduler 150000 \
--lr 0.0001 \
--dataname t2m \
--down-t 2 \
--depth 3 \
--quantizer ema_reset \
--eval-iter 10000 \
--pkeep 0.5 \
--dilation-growth-rate 3 \
--vq-act relu
5. Evaluation
5.1. VQ-VAE
VQ eval
python3 VQ_eval.py \
--batch-size 256 \
--lr 2e-4 \
--total-iter 300000 \
--lr-scheduler 200000 \
--nb-code 512 \
--down-t 2 \
--depth 3 \
--dilation-growth-rate 3 \
--out-dir output \
--dataname t2m \
--vq-act relu \
--quantizer ema_reset \
--loss-vel 0.5 \
--recons-loss l1_smooth \
--exp-name TEST_VQVAE \
--resume-pth output/VQVAE/net_last.pth
5.2. GPT
GPT eval
Follow the evaluation setting of text-to-motion, we evaluate our model 20 times and report the average result. Due to the multimodality part where we should generate 30 motions from the same text, the evaluation takes a long time.
python3 GPT_eval_multi.py  \
--exp-name TEST_GPT \
--batch-size 128 \
--num-layers 9 \
--embed-dim-gpt 1024 \
--nb-code 512 \
--n-head-gpt 16 \
--block-size 51 \
--ff-rate 4 \
--drop-out-rate 0.1 \
--resume-pth output/VQVAE/net_last.pth \
--vq-name VQVAE \
--out-dir output \
--total-iter 300000 \
--lr-scheduler 150000 \
--lr 0.0001 \
--dataname t2m \
--down-t 2 \
--depth 3 \
--quantizer ema_reset \
--eval-iter 10000 \
--pkeep 0.5 \
--dilation-growth-rate 3 \
--vq-act relu \
--resume-trans output/GPT/net_best_fid.pth
6. SMPL Mesh Rendering
SMPL Mesh Rendering
You should input the npy folder address and the motion names. Here is an example:
python3 render_final.py --filedir output/TEST_GPT/ --motion-list 000019 005485
7. Acknowledgement
We appreciate helps from :
- public code like text-to-motion, TM2T, MDM, MotionDiffuse etc.
- Mathis Petrovich, Yuming Du, Yingyi Chen, Dexiong Chen and Xuelin Chen for inspiring discussions and valuable feedback.
- Minh Chien Vu for the hugging face space demo.
8. ChangLog
- 2023/02/19 add the hugging face space demo for both skelton and SMPL mesh visualization.