Motion-X: A Large-scale 3D Expressive Whole-body Human Motion Dataset

This repository contains the implementation of the following papers:
Motion-X++: A Large-Scale Multimodal 3D Whole-body Human Motion Dataset
Yuhong Zhang😎12, Jing Lin😎12, Ailing Zeng😎2, Guanlin Wu😎23, Shunlin Lu😎24, Yurong Fu2, Yuanhao Cai3, Ruimao Zhang4, Haoqian Wang🤗1, Lei Zhang🤗2
😎Equal contribution. 🤗Corresponing author.
1Tsinghua University 2International Digital Economy Academy 3Johns Hopkins University 4The Chinese University of Hong Kong, Shenzhen
Motion-X: A Large-scale 3D Expressive Whole-body Human Motion Dataset
Jing Lin😎12, Ailing Zeng😎🤗1, Shunlin Lu😎13, Yuanhao Cai2, Ruimao Zhang3, Haoqian Wang2, Lei Zhang1
😎Equal contribution. 🤗Corresponing author.
1International Digital Economy Academy 2Tsinghua University 3The Chinese University of Hong Kong, Shenzhen
🥳 News
- [2025.03.01] We have reorganized and fixed some issues of data for Motion-X++ and published the new data on Huggingface, including the consistency of different modalities, adding generation motion TOMATO format directly.
- [2024.09.01] We have identified some issues with the new annotations of Motion-X++ and are working on resolving them. We have added the original Motion-X version using the same link we sent.
- [2024.4.25] We are working on a new version of Motion-X, named Motion-X++. It has the following updates: i) more paired modalities, including video, whole-body 2d keypoints, local and global whole-body SMPL-X, text, and audio (if the video has); ii) better quality, such as manual scene detection for temporally consistent video clips, more stable motion annotation, and improved semantic video caption via GPT4V and whole-body pose descriptions via Vicuna. We have released the IDEA400 subset and will release other subsets in the same directory. For detailed instructions on data preprocessing and loading, please refer to this document.
- [2024.2.6] We release the self-recorded IDEA400 videos and the corresponding SMPL-X to support (a) whole-body local or global pose estimation and (2) motion-condition video generation. Please check the email.
- [2024.1.9] We update the frame-level textual descriptions for each whole-body pose. Please download it here and refer to this usage guidance here.
- [2023.12.22] We update the sequential motion text descriptions (text_v1.1) augmented by Vicuna 1.5 to enhance the standardization and diversity of text. Please download via this link and replace it with the original file motionx_seq_text.zip. Many thanks to Linghao Chen for polishing the text labels!
- [2023.11.15] We release the rendered SMPL-X visualization of all subsets on DDS platform for quick content viewing.
- [2023.11.15] We release the HumanTOMATO motion representation (
tomatorepresentation) and split files. - [2023.10.26] We release the Motion-X-V1, which provides semantic text labels corresponding to SMPL-X sequences, facial expression motions, and the corresponding texts for augmenting some motions without facial expressions. Please kindly check your email!
- [2023.10.26] We release a high-quality monocular dataset named IDEA400 as a subset of Motion-X, which contains rich expressions and gestures. See this video for more details.
📜 TODO
- [x] Release whole-body pose descriptions.
- [ ] Gathering more motion datasets (e.g., music-to-dance, audio-to-gesture motions).
- [ ] Release Videos after the agreement of video owners.
- [ ] Release audio and music if motions are needed.
Stay tuned!
🥳 Highlight Motion Samples
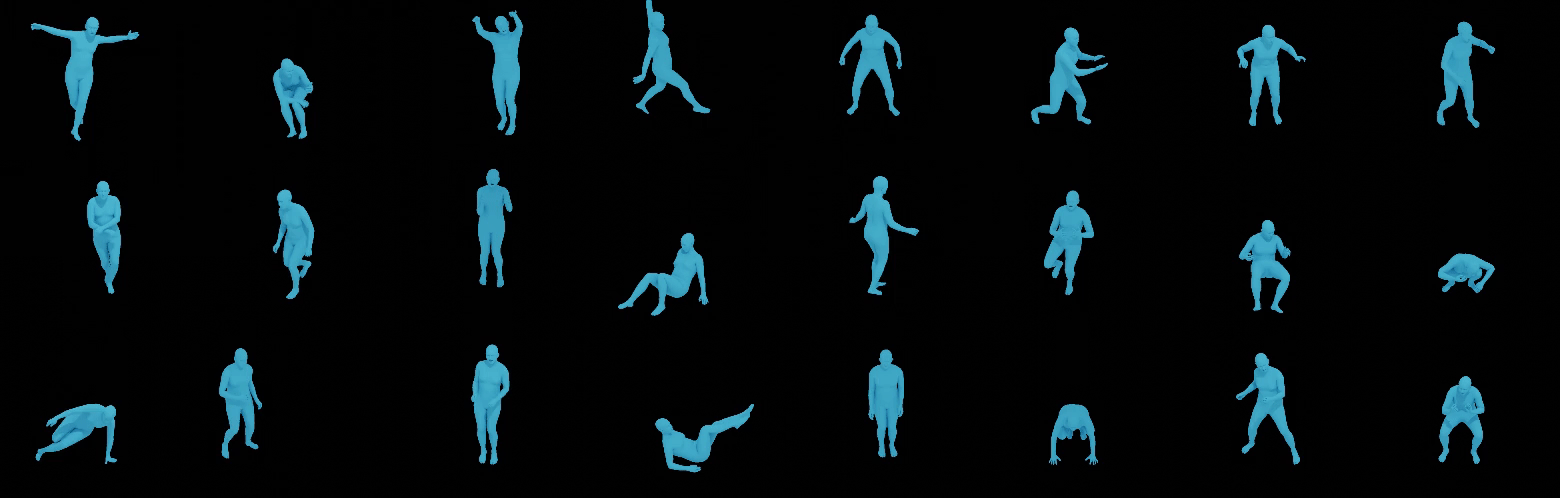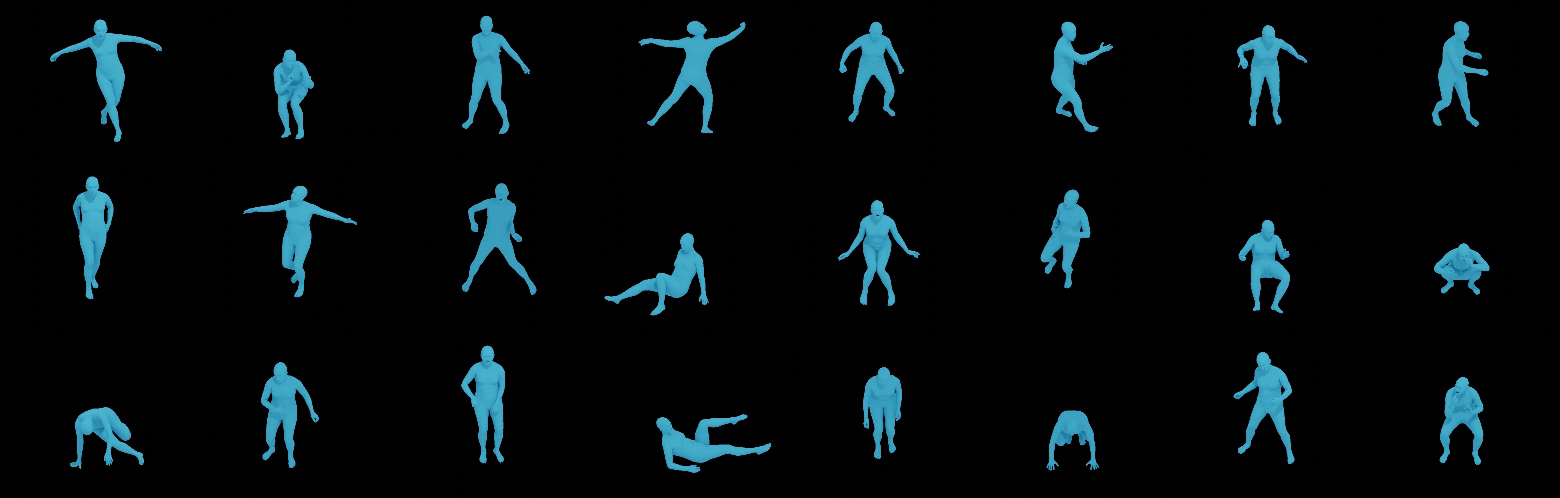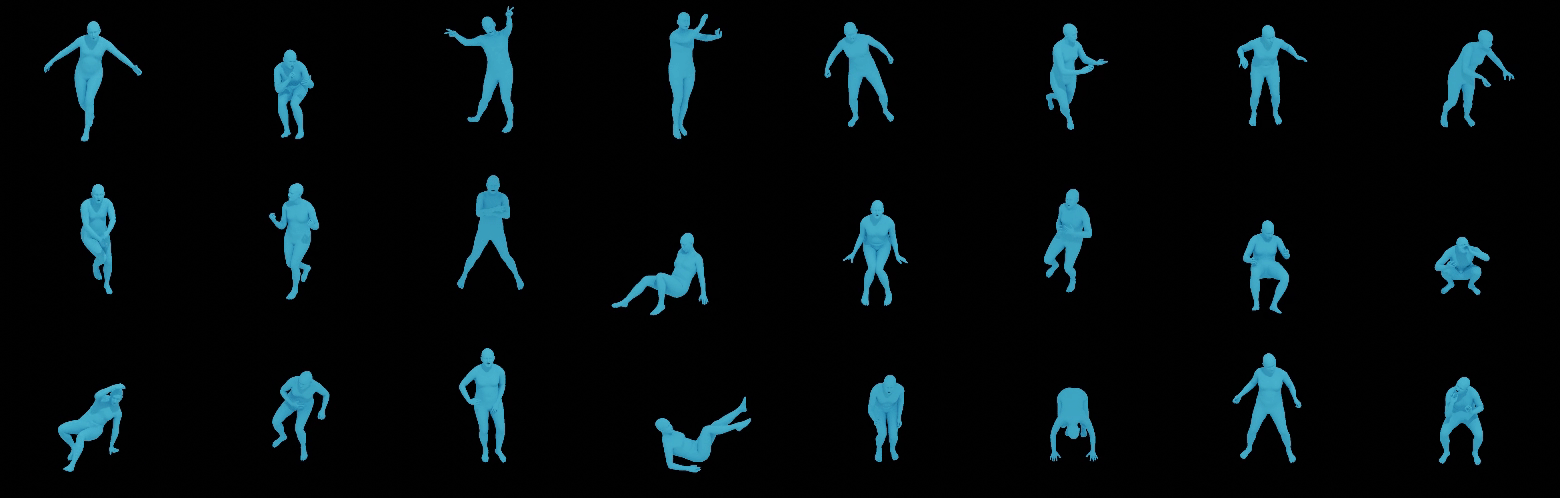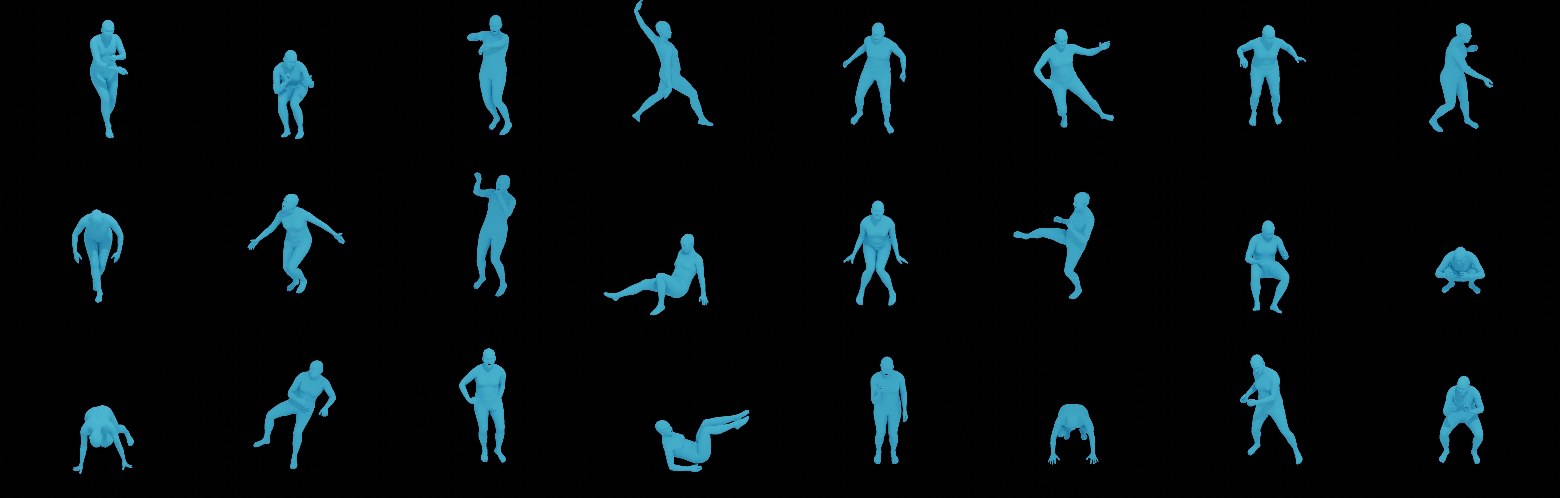
📊 Table of Contents
📜 General Description
We propose a high-accuracy and efficient annotation pipeline for whole-body motions and the corresponding text labels. Based on it, we build a large-scale 3D expressive whole-body human motion dataset from massive online videos and eight existing motion datasets. We unify them into the same formats, providing whole-body motion (i.e., SMPL-X) and corresponding text labels.
Labels from Motion-X:
- Motion label: including
15.6Mwhole-body poses and81.1Kmotion clips annotation, represented as SMPL-X parameters. All motions have been unified in 30 fps. - Text label: (1)
15.6Mframe-level whole-body pose description and (2)81.1Ksequence-level semantic labels. - Other modalities: RGB videos, audio, and music information.
Supported Tasks:
- Text-driven 3d whole-body human motion generation
- 3D whole-body human mesh recovery
- Others: Motion pretraining, multi-modality pre-trained models for motion understanding and generation, etc.
Dataset
Clip Number
Frame Number
Website
License
Downloading Link
AMASS
26K
5.4M
EgoBody
1.0K
0.4M
GRAB
1.3K
0.4M
IDEA400
12.5K
2.6M
AIST++
1.4K
0.3M
HAA500
5.2K
0.3M
HuMMan
0.7K
0.1M
BAUM
1.4K
0.2M
Online Videos
32.5K
6.0M
Motion-X (Ours)
81.1K
15.6M
📥 Dataset Download
We disseminate Motion-X in a manner that aligns with the original data sources. Here are the instructions:
1. Request Authorization
Please fill out this form to request authorization to use Motion-X for non-commercial purposes. Then you will receive an email and please download the motion and text labels from the provided downloading links. The pose texts can be downloaded from here. Please extract the body_texts folder and hand_texts folder from the downloaded motionx_pose_text.zip.(Note: We updated the Baidu Disk link of motionx_seq_face_text.zip and motionx_face_motion.zip on October 29, 2023. Thus, if you download these zips via Baidu Disk before October 29, please fill out the form and download again.)
Please collect them as the following directory structure:
../datasets

├──  motion_data
  ├── smplx_322
    ├── idea400
    ├── ...
├──  face_motion_data
  ├── smplx_322
    ├── humanml
    ├── EgoBody
    ├── GRAB
├── texts
  ├──  semantic_labels
    ├── idea400
    ├── ...
  ├──  face_texts
    ├── humanml
    ├── EgoBody
    ├── GRAB
    ├── idea400
    ├── ...
  ├──  body_texts
    ├── humanml
    ├── EgoBody
    ├── GRAB
    ├── idea400
    ├── ...
  ├──  hand_texts
    ├── humanml
    ├── EgoBody
    ├── GRAB
    ├── idea400
    ├── ...
2. Non-Mocap Subsets
For the non-mocap subsets, please refer to this link for a detailed instruction, notably:
- We do not distribute the original RGB videos. We provide the motion and text labels annotated by our team.
- Due to license and quality consideration, we do not provide NTU-RGBD120. Instead, we build IDEA400, which includes 400 daily actions (covering NTU-RGBD120). Please refer to this video for a detailed introduction.
3. Mocap Subsets
For the mocap datasets (i.e., AMASS, GRAB, EgoBody), please refer to this link for a detailed instruction, notably:
- We do not distribute the original motion data.
- We only provide the text labels and facial expressions annotated by our team.
The AMASS and GRAB datasets are released for academic research under custom licenses by Max Planck Institute for Intelligent Systems. To download AMASS and GRAB, you must register as a user on the dataset websites and agree to the terms and conditions of each license:
https://amass.is.tue.mpg.de/license.html
https://grab.is.tuebingen.mpg.de/license.html
Finally, the datasets folder is collected as the following directory structure:
../datasets

├──  motion_data
  ├── smplx_322
    ├── humanml
    ├── EgoBody
    ├── GRAB
    ├── idea400
    ├── ...
├── texts
  ├──  semantic_labels
    ├── idea400
    ├── ...
  ├──  face_texts
    ├── humanml
    ├── EgoBody
    ├── GRAB
    ├── idea400
    ├── ...
  ├──  body_texts
    ├── humanml
    ├── EgoBody
    ├── GRAB
    ├── idea400
    ├── ...
  ├──  hand_texts
    ├── humanml
    ├── EgoBody
    ├── GRAB
    ├── idea400
    ├── ...
🚀 Data Loading
-
To load the motion and text labels you can simply do:
import numpy as np
import torch

# read motion and save as smplx representation
motion = np.load('motion_data/smplx_322/000001.npy')
motion = torch.tensor(motion).float()
motion_parms = {
            'root_orient': motion[:, :3],  # controls the global root orientation
            'pose_body': motion[:, 3:3+63],  # controls the body
            'pose_hand': motion[:, 66:66+90],  # controls the finger articulation
            'pose_jaw': motion[:, 66+90:66+93],  # controls the yaw pose
            'face_expr': motion[:, 159:159+50],  # controls the face expression
            'face_shape': motion[:, 209:209+100],  # controls the face shape
            'trans': motion[:, 309:309+3],  # controls the global body position
            'betas': motion[:, 312:],  # controls the body shape. Body shape is static
        }

# read text labels
semantic_text = np.loadtxt('semantic_labels/000001.npy')     # semantic labels
💻 Visualization
We support the visualization from the camera space and world space, please refer to this guidance.
💻 Experiments
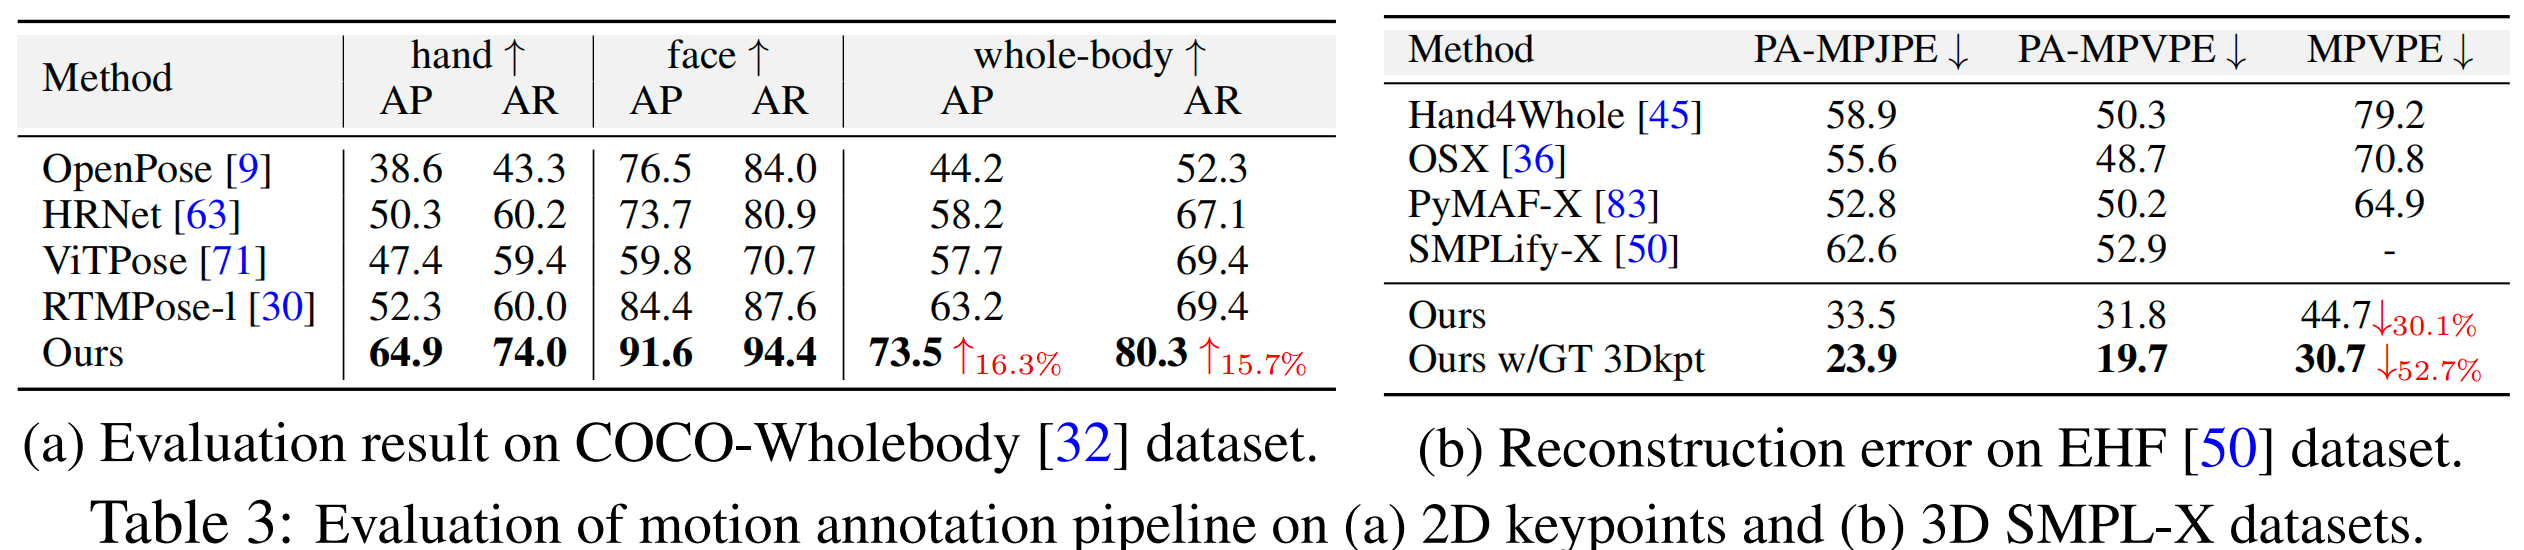
Validation of the motion annotation pipeline
Our annotation pipeline significantly surpasses existing SOTA 2D whole-body models and mesh recovery methods.
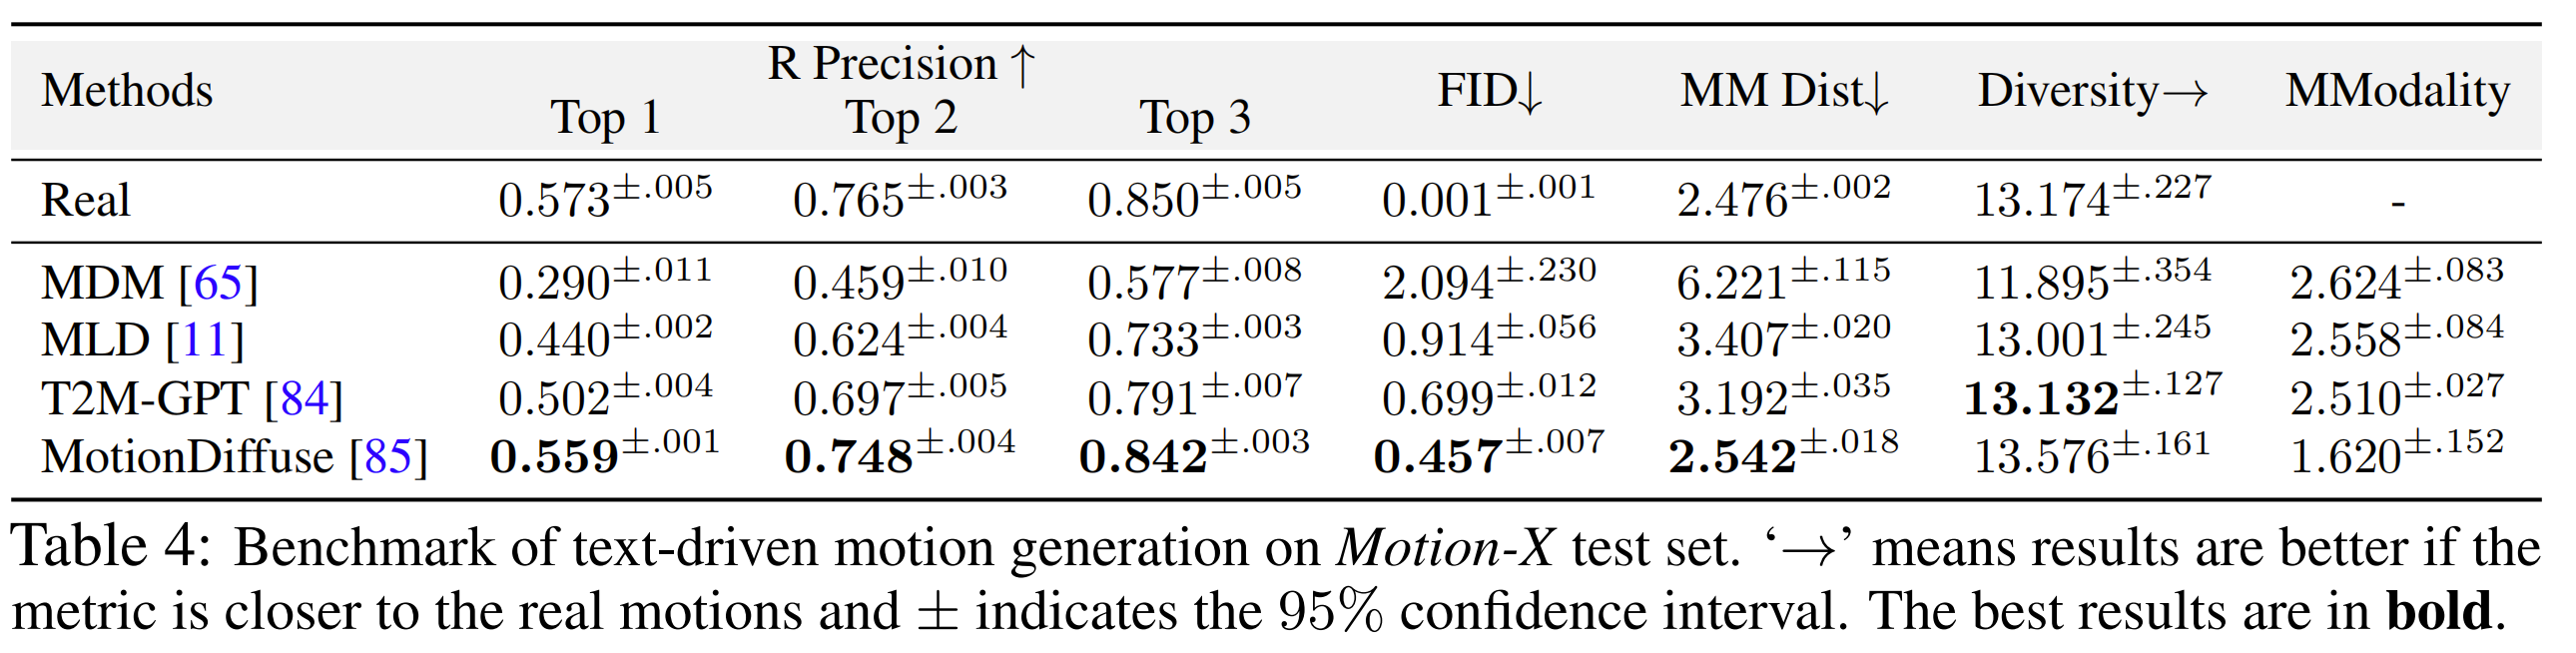
Benchmarking Text-driven Whole-body Human Motion Generation
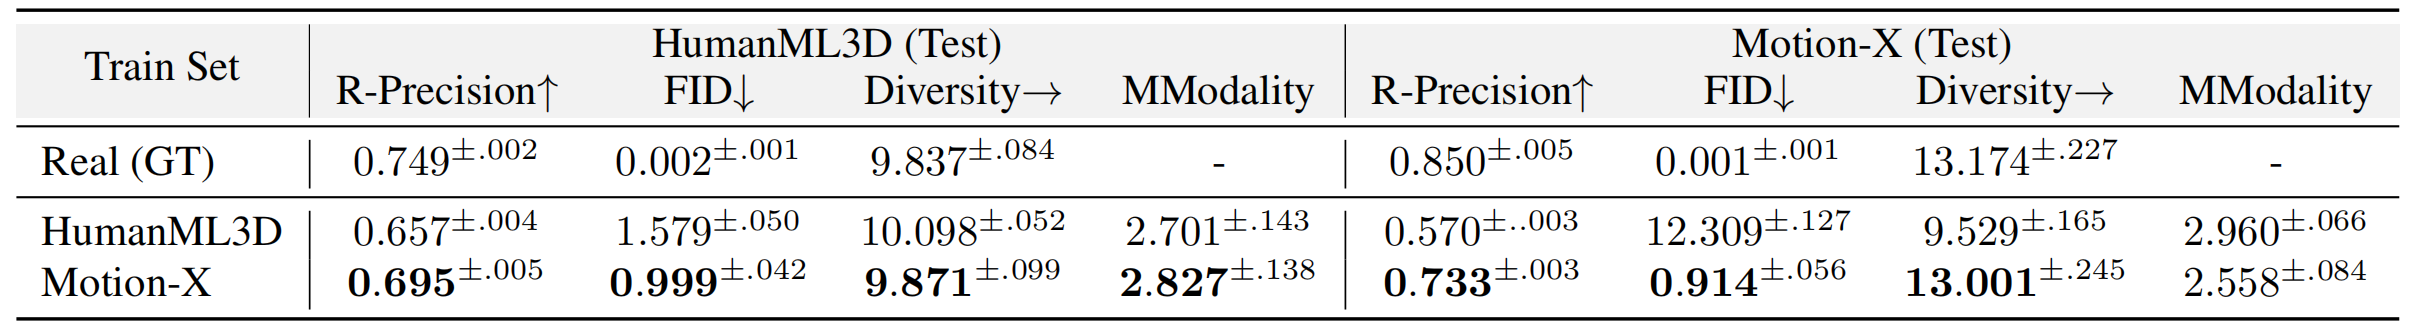
Comparison with HumanML3D on Whole-body Human Motion Generation Task
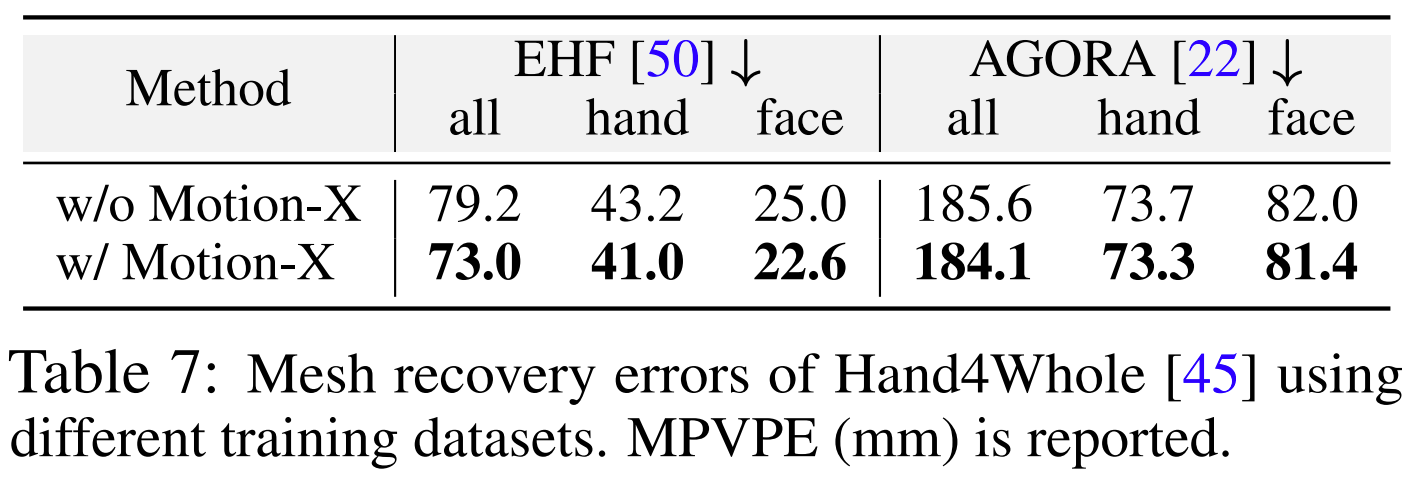
Impact on 3D Whole-Body Human Mesh Recovery
🤝 Citation
If you find this repository useful for your work, please consider citing it as follows:
@article{zhang2025motion,
  title={Motion-X++: A Large-Scale Multimodal 3D Whole-body Human Motion Dataset},
  author={Zhang, Yuhong and Lin, Jing and Zeng, Ailing and Wu, Guanlin and Lu, Shunlin and Fu, Yurong and Cai, Yuanhao and Zhang, Ruimao and Wang, Haoqian and Zhang, Lei},
  journal={arXiv preprint arXiv:2501.05098},
  year={2025}
}
@article{lin2023motionx,
  title={Motion-X: A Large-scale 3D Expressive Whole-body Human Motion Dataset},
  author={Lin, Jing and Zeng, Ailing and Lu, Shunlin and Cai, Yuanhao and Zhang, Ruimao and Wang, Haoqian and Zhang, Lei},
  journal={Advances in Neural Information Processing Systems},
  year={2023}
}