[ECCV 2024 - Oral] ACE0 is a learning-based structure-from-motion approach that estimates camera parameters of sets of images by learning a multi-view consistent, implicit scene representation.
The goal of this library is to generate more helpful exception messages for matrix algebra expressions for numpy, pytorch, jax, tensorflow, keras, fastai.
A powerful baseline for image classification, face recognition and image retrieval with Pytorch.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Language
Python
Category
Model Development
Subcategory
Fine-tuning
Keywords
Deep Research, RL
Stars
806
Forks
54
Contributors
4
Created date
2025-04-02
Updated date
2026-10-15
Stars in 1 day
0
Stars in 7 days
3
Rank
13,621
Previous rank
6,383
Rank change
-7,238
7-day stars rank
7,221
Previous 7-day stars rank
7,247
7-day stars rank change
26
Total stars rank
13,263
Previous total stars rank
13,237
Total stars rank change
-26
README summary
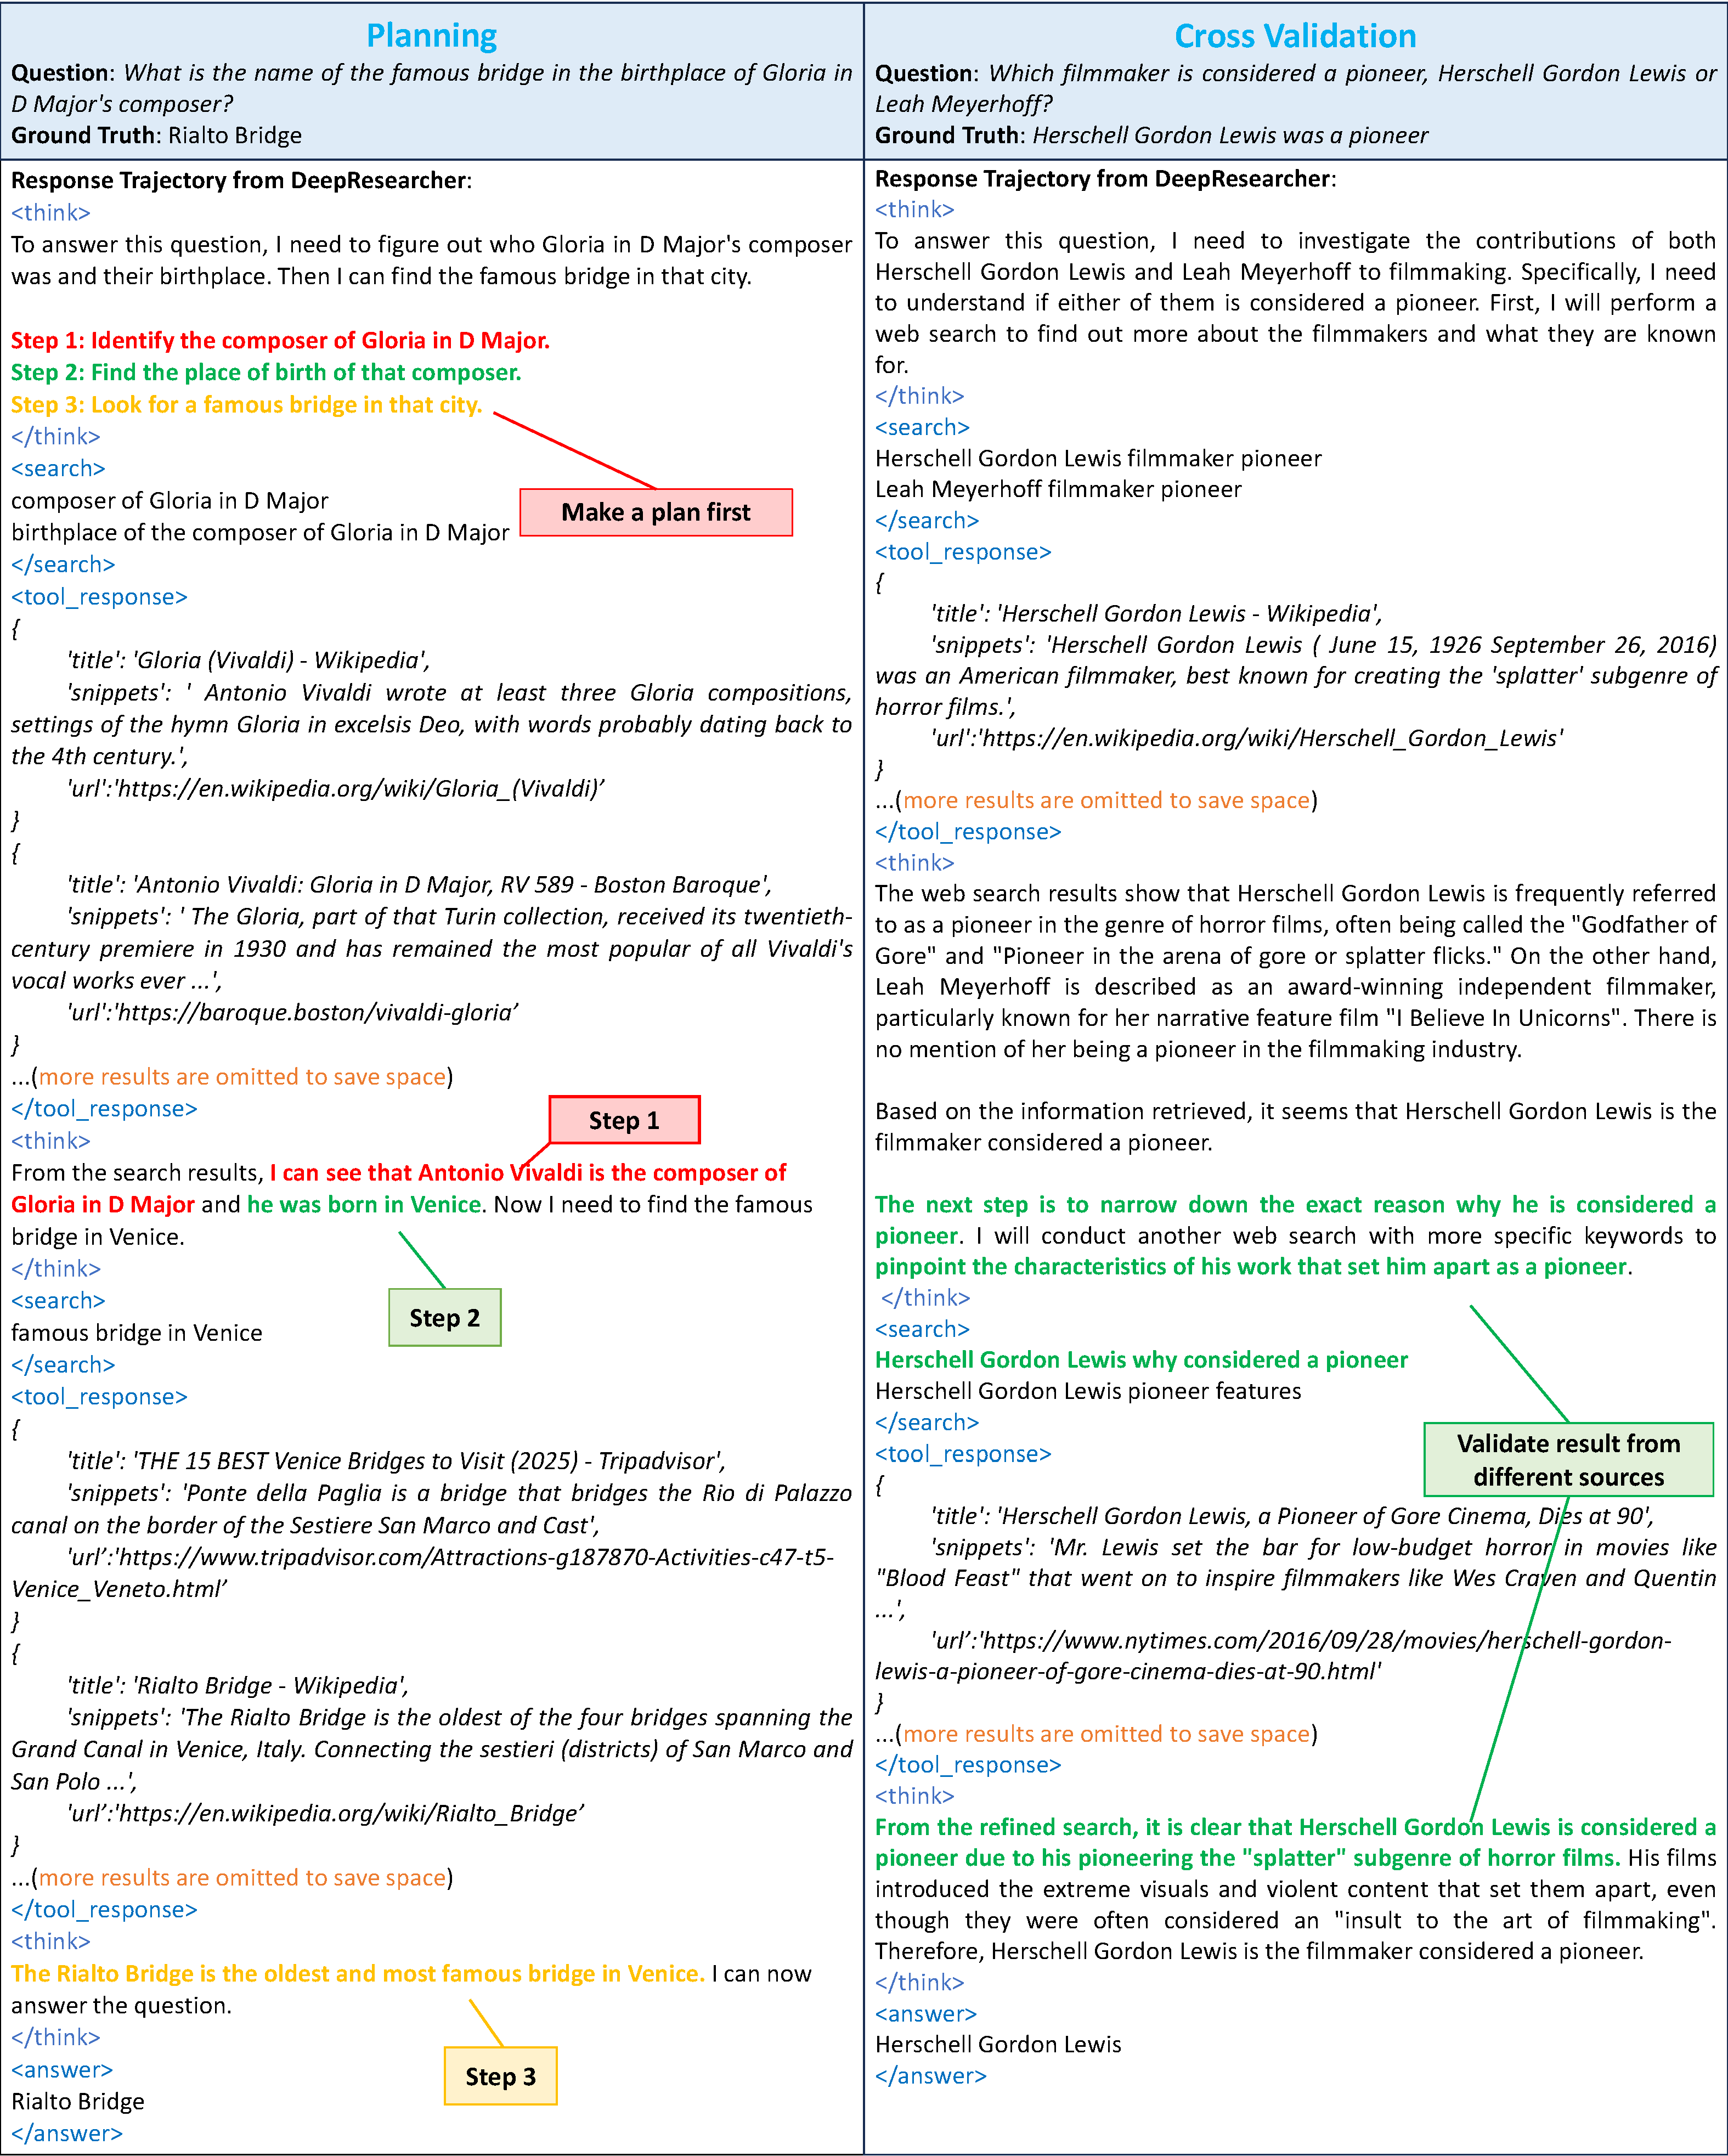
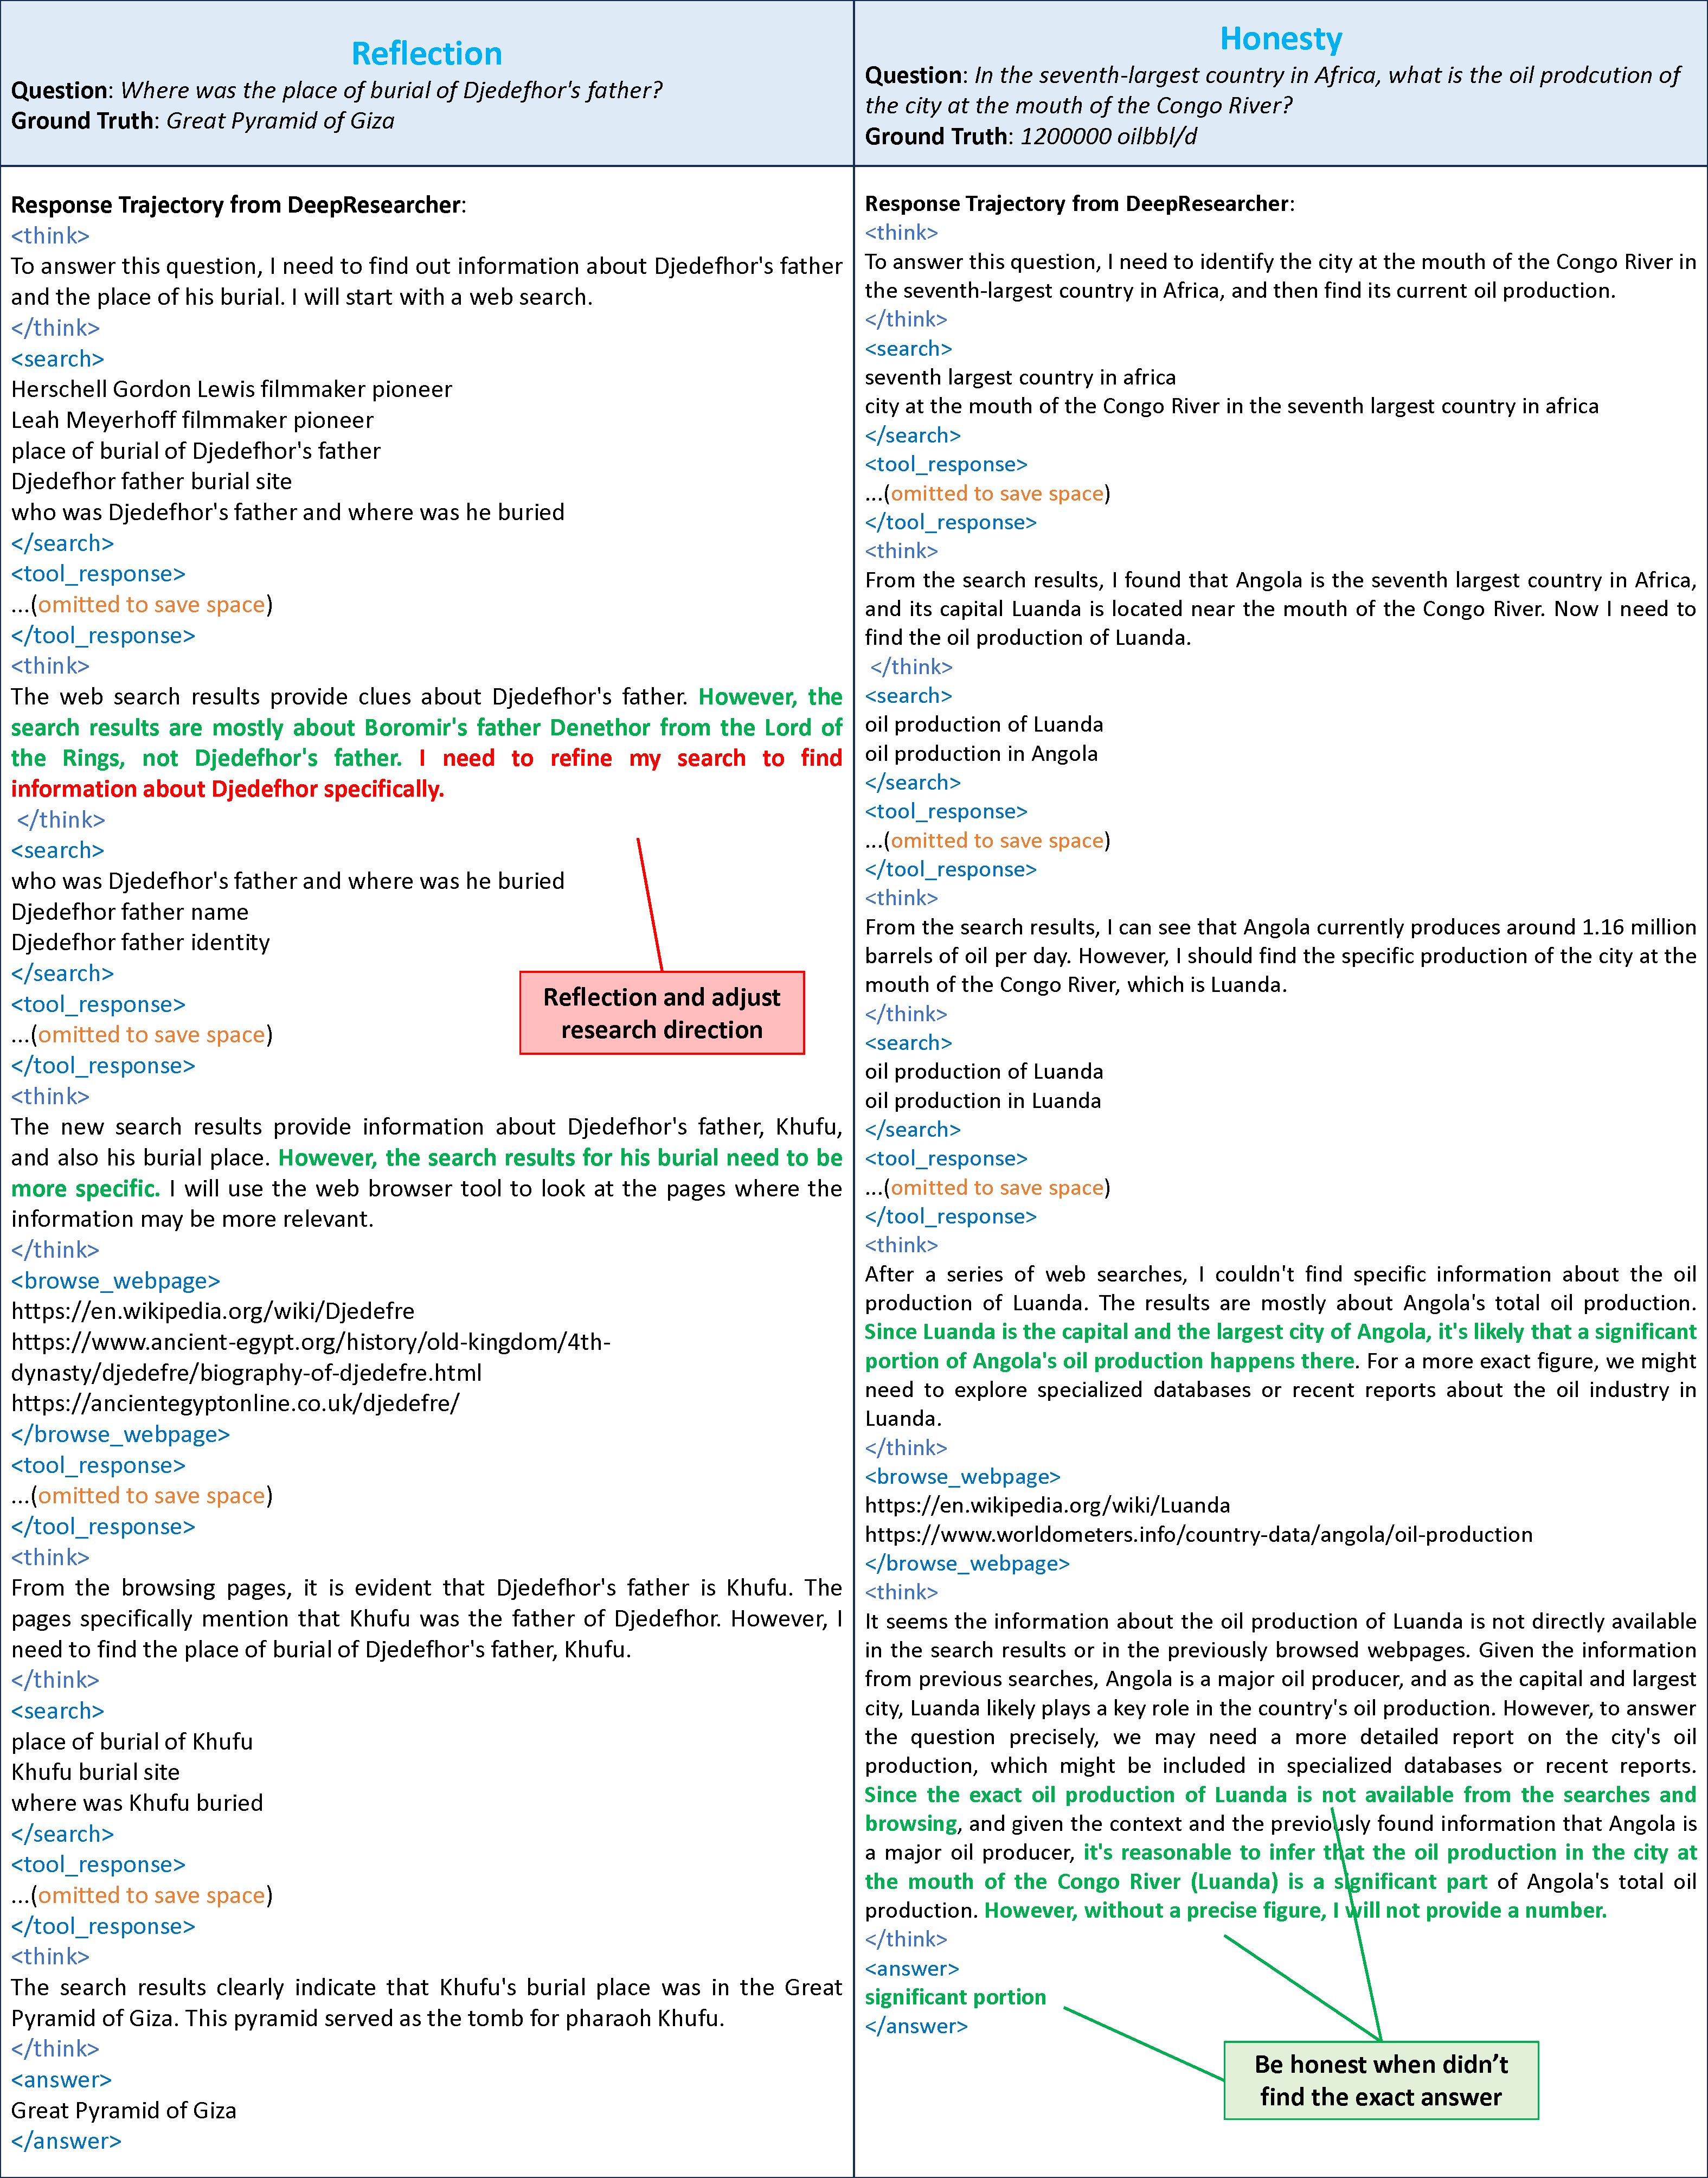
DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments This is the official repository for DeepResearcher. 📝 Introduction DeepResearcher is the first comprehensive framework for end-to-end training of LLM-based deep research agents through scaling reinforcement learning (RL) in real-world environments with authentic web search interactions. Our qualitative analysis reveals emergent **cognitive behaviors** from end-to-end RL training, including the ability to formulate plans, cross-validate information from multiple sources, engage in self-reflection to
redirect research, and maintain honesty when unable to find definitive answers. 9 points over prompt engineering-based baselines and up to 7. Our qualitative analysis reveals emergent cognitive behaviors from end-to-end RL training, including the ability to formulate plans, cross-validate information from multiple sources, engage in self-reflection to redirect research, and maintain honesty when unable to find definitive answers. Our results highlight that end-to-end training in real-world web environments is not merely an
implementation detail but a fundamental requirement for developing robust research capabilities aligned with real-world applications. 🚀 Get Started Package Installation To begin using this repo, you need to install the required dependencies. You can do this by running the following command: Start ray before training and inference We use ray to train model, befor start ray you should set first. (**This is compulsory even if you only have 1 node**). Here is the code of the head node: Run backend
handler Running the following command to launch the server handler: 1. Start server handler: After launching all server handlers, you can replace in in your training host node and then run: Training model Using the following command to train the model: Evaluate Using the following command to generate rollout: You can find the rollout file in: You can rename and copy it into Then, run the following command: You can check the score in 🙏 Acknowledgement DeepResearcher is inspired by Deepseek
-R1 with its implementation based on veRL and Search-r1. We deeply appreciate the contributions of these teams to open-source research and development. ✍️ Citation Please cite the repo if the model/code/conclusion in this repo are helpful to you.
Frequently asked questions
How many stars and forks are recorded?
GAIR-NLP/DeepResearcher has 806 stars and 54 forks.
What is the repository rank?
GAIR-NLP/DeepResearcher is ranked 13,621.
What language and category are recorded?
GAIR-NLP/DeepResearcher has 806 stars, uses Python and belongs to Model Development.
Which repository is closest in rank?
GAIR-NLP/DeepResearcher is compared with kuan-wang/pytorch-mobilenet-v3, ranked 13,624 with 806 stars.
README
DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments
DeepResearcher is the first comprehensive framework for end-to-end training of LLM-based deep research agents through scaling reinforcement learning (RL) in real-world environments with authentic web search interactions. Our qualitative analysis reveals emergent cognitive behaviors from end-to-end RL training, including the ability to formulate plans, cross-validate information from multiple sources, engage in self-reflection to redirect research, and maintain honesty when unable to find definitive answers.
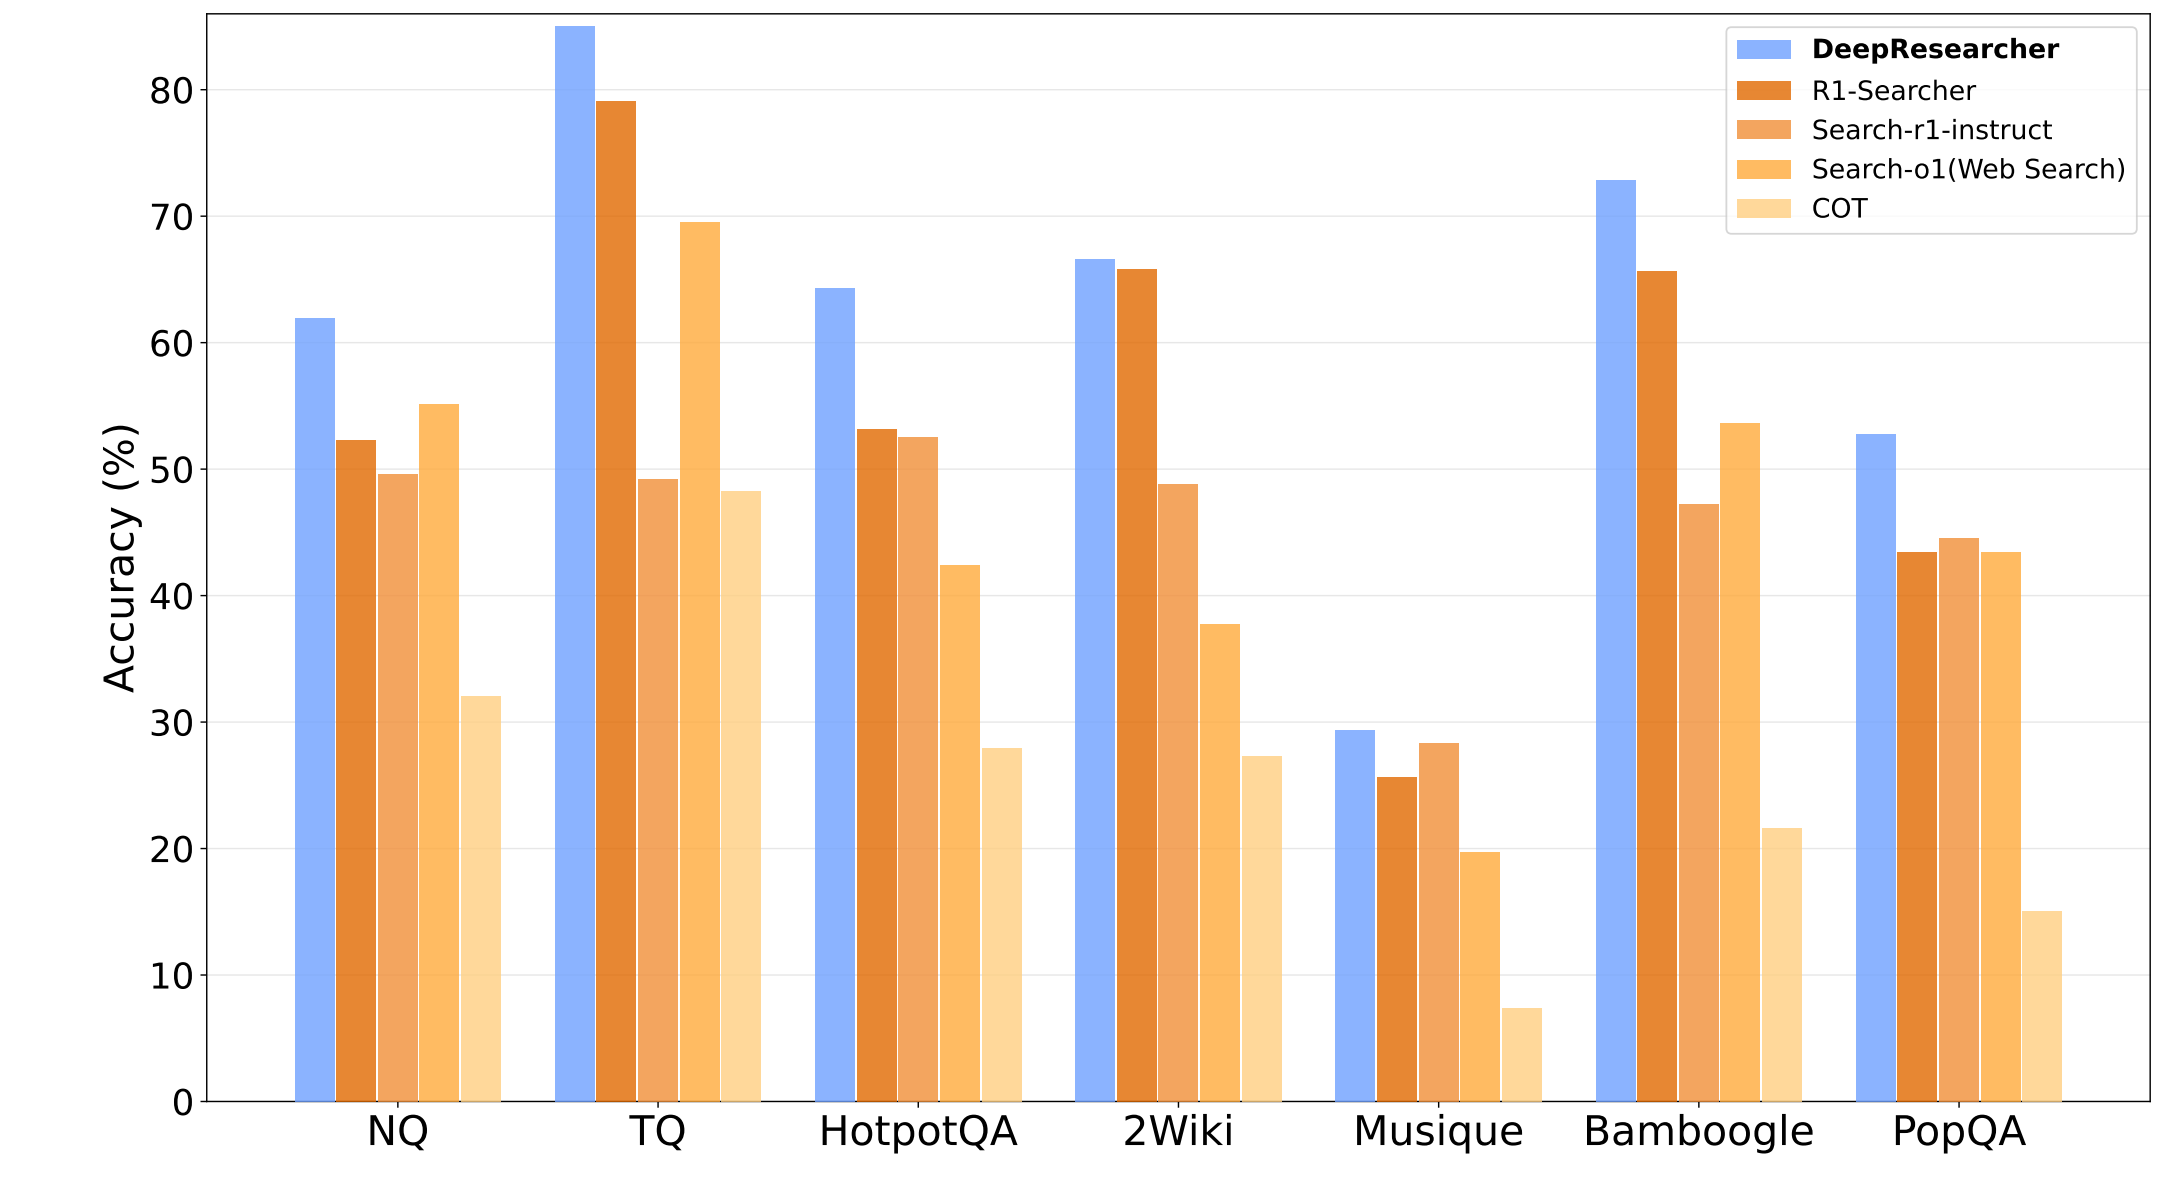
Extensive experiments on open-domain research tasks demonstrate that DeepResearcher achieves substantial improvements of up to 28.9 points over prompt engineering-based baselines and up to 7.2 points over RAG-based RL agents. Our qualitative analysis reveals emergent cognitive behaviors from end-to-end RL training, including the ability to formulate plans, cross-validate information from multiple sources, engage in self-reflection to redirect research, and maintain honesty when unable to find definitive answers. Our results highlight that end-to-end training in real-world web environments is not merely an implementation detail but a fundamental requirement for developing robust research capabilities aligned with real-world applications.
🚀 Get Started
Package Installation
To begin using this repo, you need to install the required dependencies. You can do this by running the following command:
We use ray to train model, befor start ray you should set PET_NODE_RANK first. (This is compulsory even if you only have 1 node).
Here is the code of the head node:
export PET_NODE_RANK=0
ray start --head
Run backend handler
Running the following command to launch the server handler:
Modify serper_api_key or azure_bing_search_subscription_key & search_engine in ./scrl/handler/config.yaml
Add qwen-plus api key in ./scrl/handler/server_handler.py
After launching all server handlers, you can replace server_url_list in ./scrl/handler/config.yaml in your training host node and then run:
python ./scrl/handler/handler.py
Training model
Using the following command to train the model:
bash train_grpo.sh
Evaluate
Using the following command to generate rollout:
bash evaluate.sh
You can find the rollout file in: ./outputs/{project_name}/{experiment_name}/rollout/rollout_step_0.json
You can rename and copy it into ./evaluate/{experiment_name}_result.json
You can check the score in ./evaluate/{experiment_name}_score.json
🙏 Acknowledgement
DeepResearcher is inspired by Deepseek-R1 with its implementation based on veRL and Search-r1. We deeply appreciate the contributions of these teams to open-source research and development.
✍️ Citation
Please cite the repo if the model/code/conclusion in this repo are helpful to you.
@misc{zheng2025deepresearcherscalingdeepresearch,
      title={DeepResearcher: Scaling Deep Research via Reinforcement Learning in Real-world Environments},
      author={Yuxiang Zheng and Dayuan Fu and Xiangkun Hu and Xiaojie Cai and Lyumanshan Ye and Pengrui Lu and Pengfei Liu},
      year={2025},
      eprint={2504.03160},
      archivePrefix={arXiv},
      primaryClass={cs.AI},
      url={https://arxiv.org/abs/2504.03160},
}