This is an unofficial implementation of the Point Transformer paper.
Key parameters and specifications
Key parameters and specifications
Parameter
Value
Language
Python
Category
Models
Subcategory
Vision models
Keywords
Image production, Multimodal
Stars
640
Forks
36
Contributors
2
Created date
2024-12-12
Updated date
2026-10-14
Stars in 1 day
0
Stars in 7 days
-1
Rank
15,668
Previous rank
15,477
Rank change
-191
7-day stars rank
17,803
Previous 7-day stars rank
17,757
7-day stars rank change
-46
Total stars rank
15,971
Previous total stars rank
15,948
Total stars rank change
-23
README summary
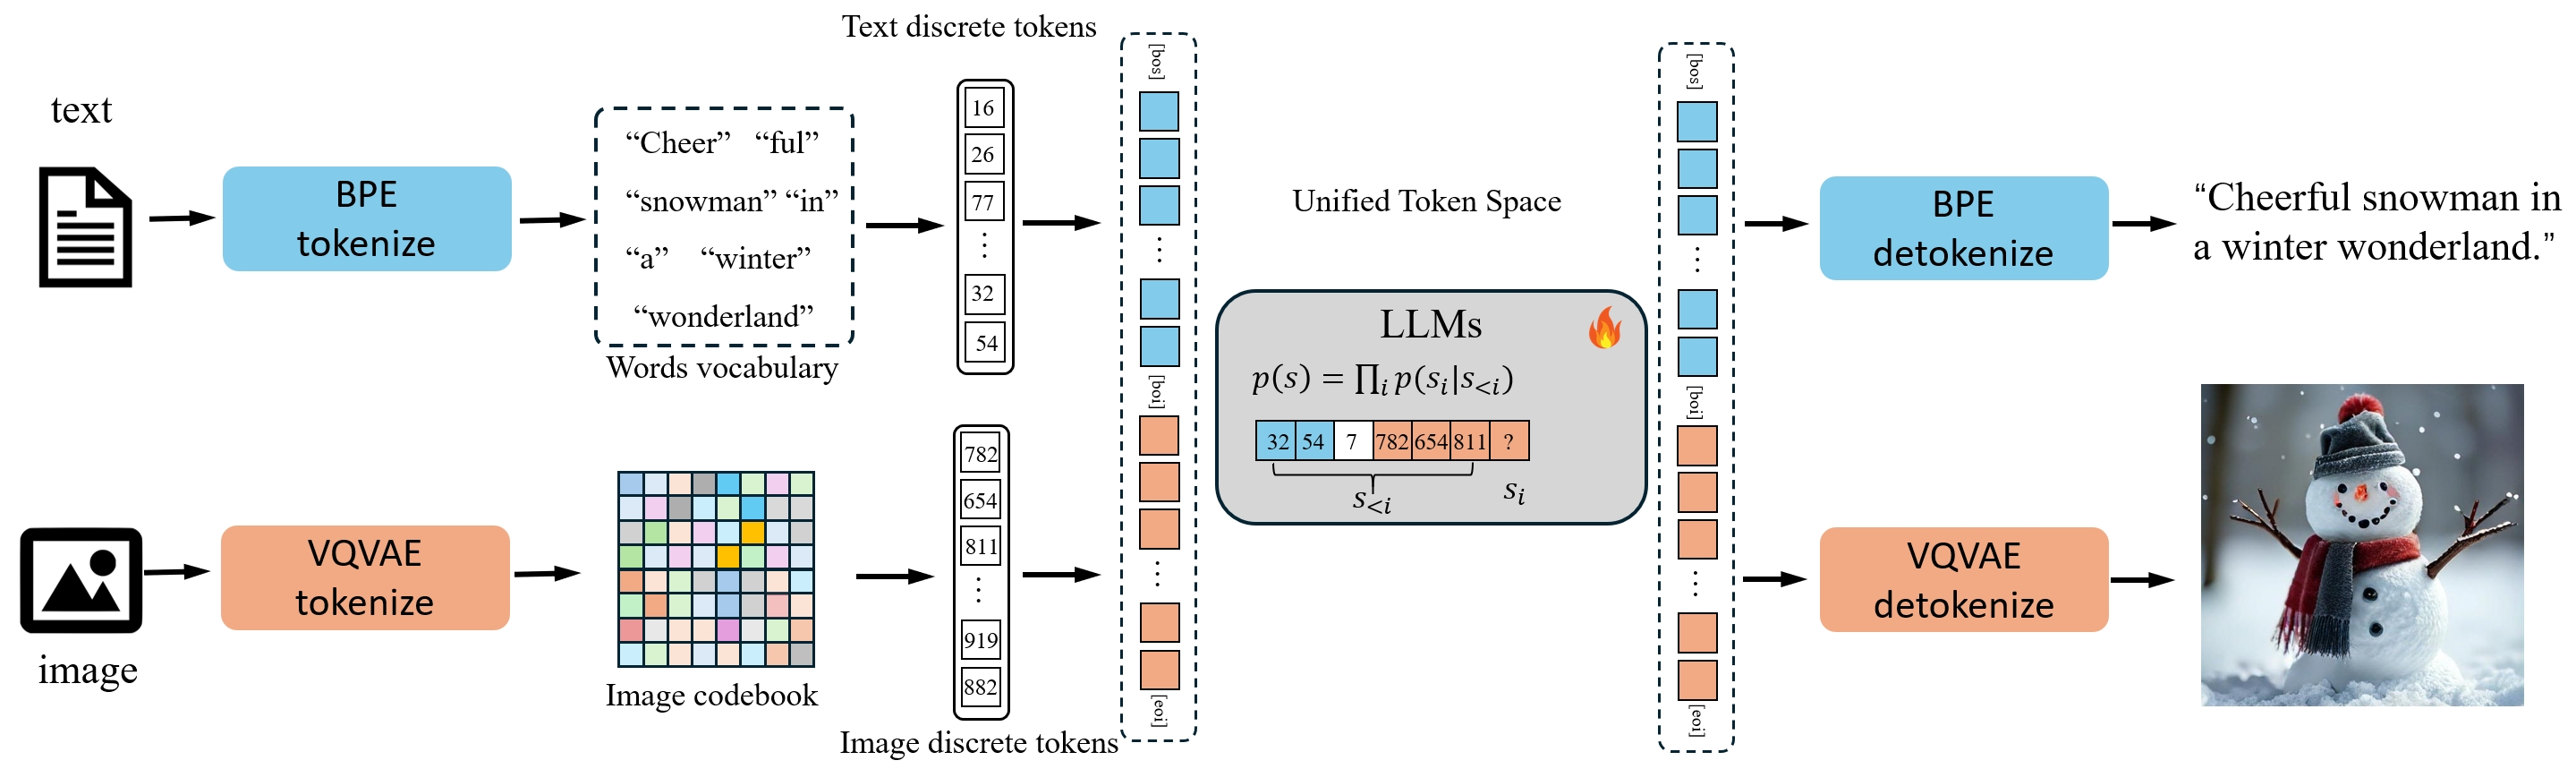
Liquid: Language Models are Scalable and Unified Multi-modal Generators **Junfeng Wu** 1,2 · **Yi Jiang** 2† · **Chuofan Ma** 2,3 **Yuliang Liu** 1 · **Hengshuang Zhao** 3 **Zehuan Yuan** 2 · **Song Bai** 2* · **Xiang Bai** 1* 1 HUST    2 ByteDance    3 HKU †project lead   *corresponding author This repo implements Liquid, a scalable and unified autoregressive generation paradigm that seamlessly integrates multimodal comprehension and generation. 📰 News **2025-03-25:** Data
processing and model pretraining scripts have been updated in Data. **2025-03-04:** Text-to-image and visual understanding evaluation scripts for Liquid are released in EVAL. **2025-02-28:** Paper, demo, model, and project page for Liquid are all released. 📑 Open-Source Plan Liquid-7B-IT (Instruction Tuned Multimodal Model with Instruction Following Ability) [✅] Web Demo [✅] Evaluation [✅] Checkpoints [✅] Training Codes Liquid-0. 5B~32B-Pretrain (Multimodal extension models of six different scales ranging from 0. ) [ ] Checkpoints 📽️Inference Using Liquid
for inference or evaluation doesn't require complex environment dependencies. Since it's essentially a HuggingFace format language model, you only need the library and some basic components to run it. Run the Gradio Demo locally If deploying on a GPU with less than 30GB VRAM, you may need to enable in in for image generation to avoid out-of-memory errors. Single inference ⚙️ Installation and Training See Data. 📖 Introduction We present Liquid, an auto-regressive generation paradigm that **seamlessly integrates visual
comprehension and generation. ** Unlike previous multimodal large language model (MLLM), Liquid achieves this integration using a single large language model (LLM), eliminating the need for external pretrained visual embeddings such as CLIP. For the first time, Liquid uncovers a **scaling law** that performance drop unavoidably brought by the unified training of visual and language tasks diminishes as the model size increases. Furthermore, the unified token space enables visual generation and comprehension tasks to **mutually enhance each other** 🔥 Multimodal Generation Liquid
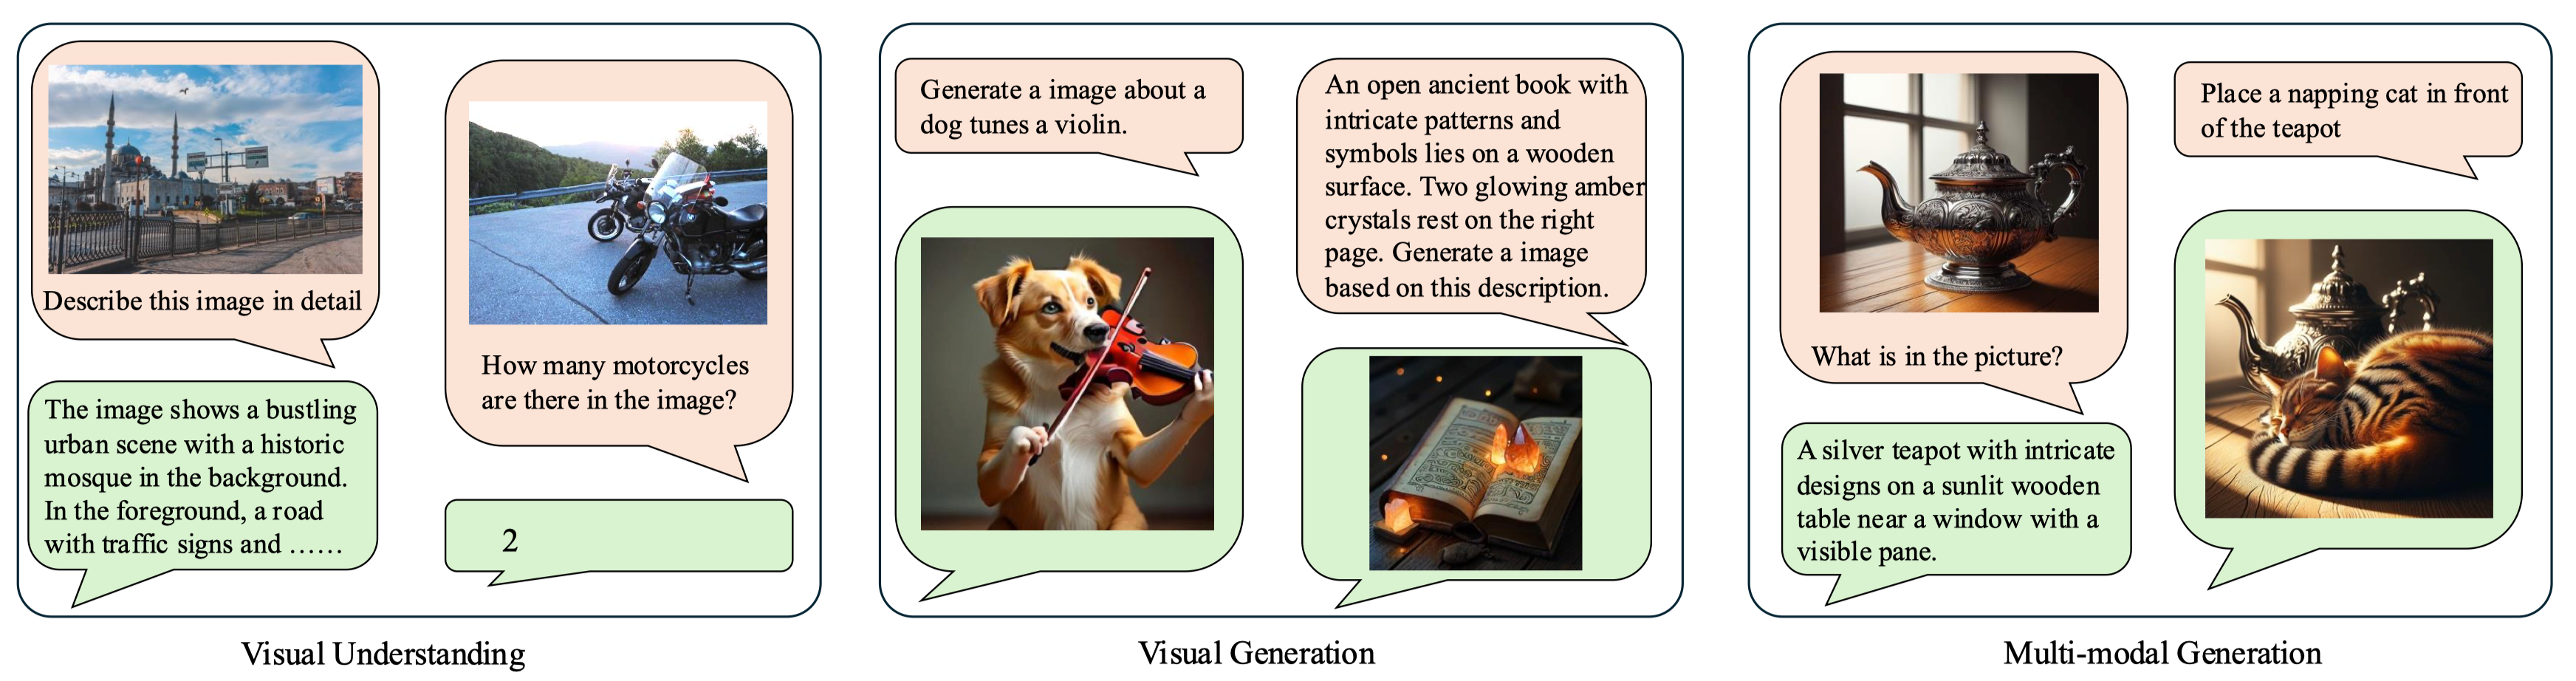
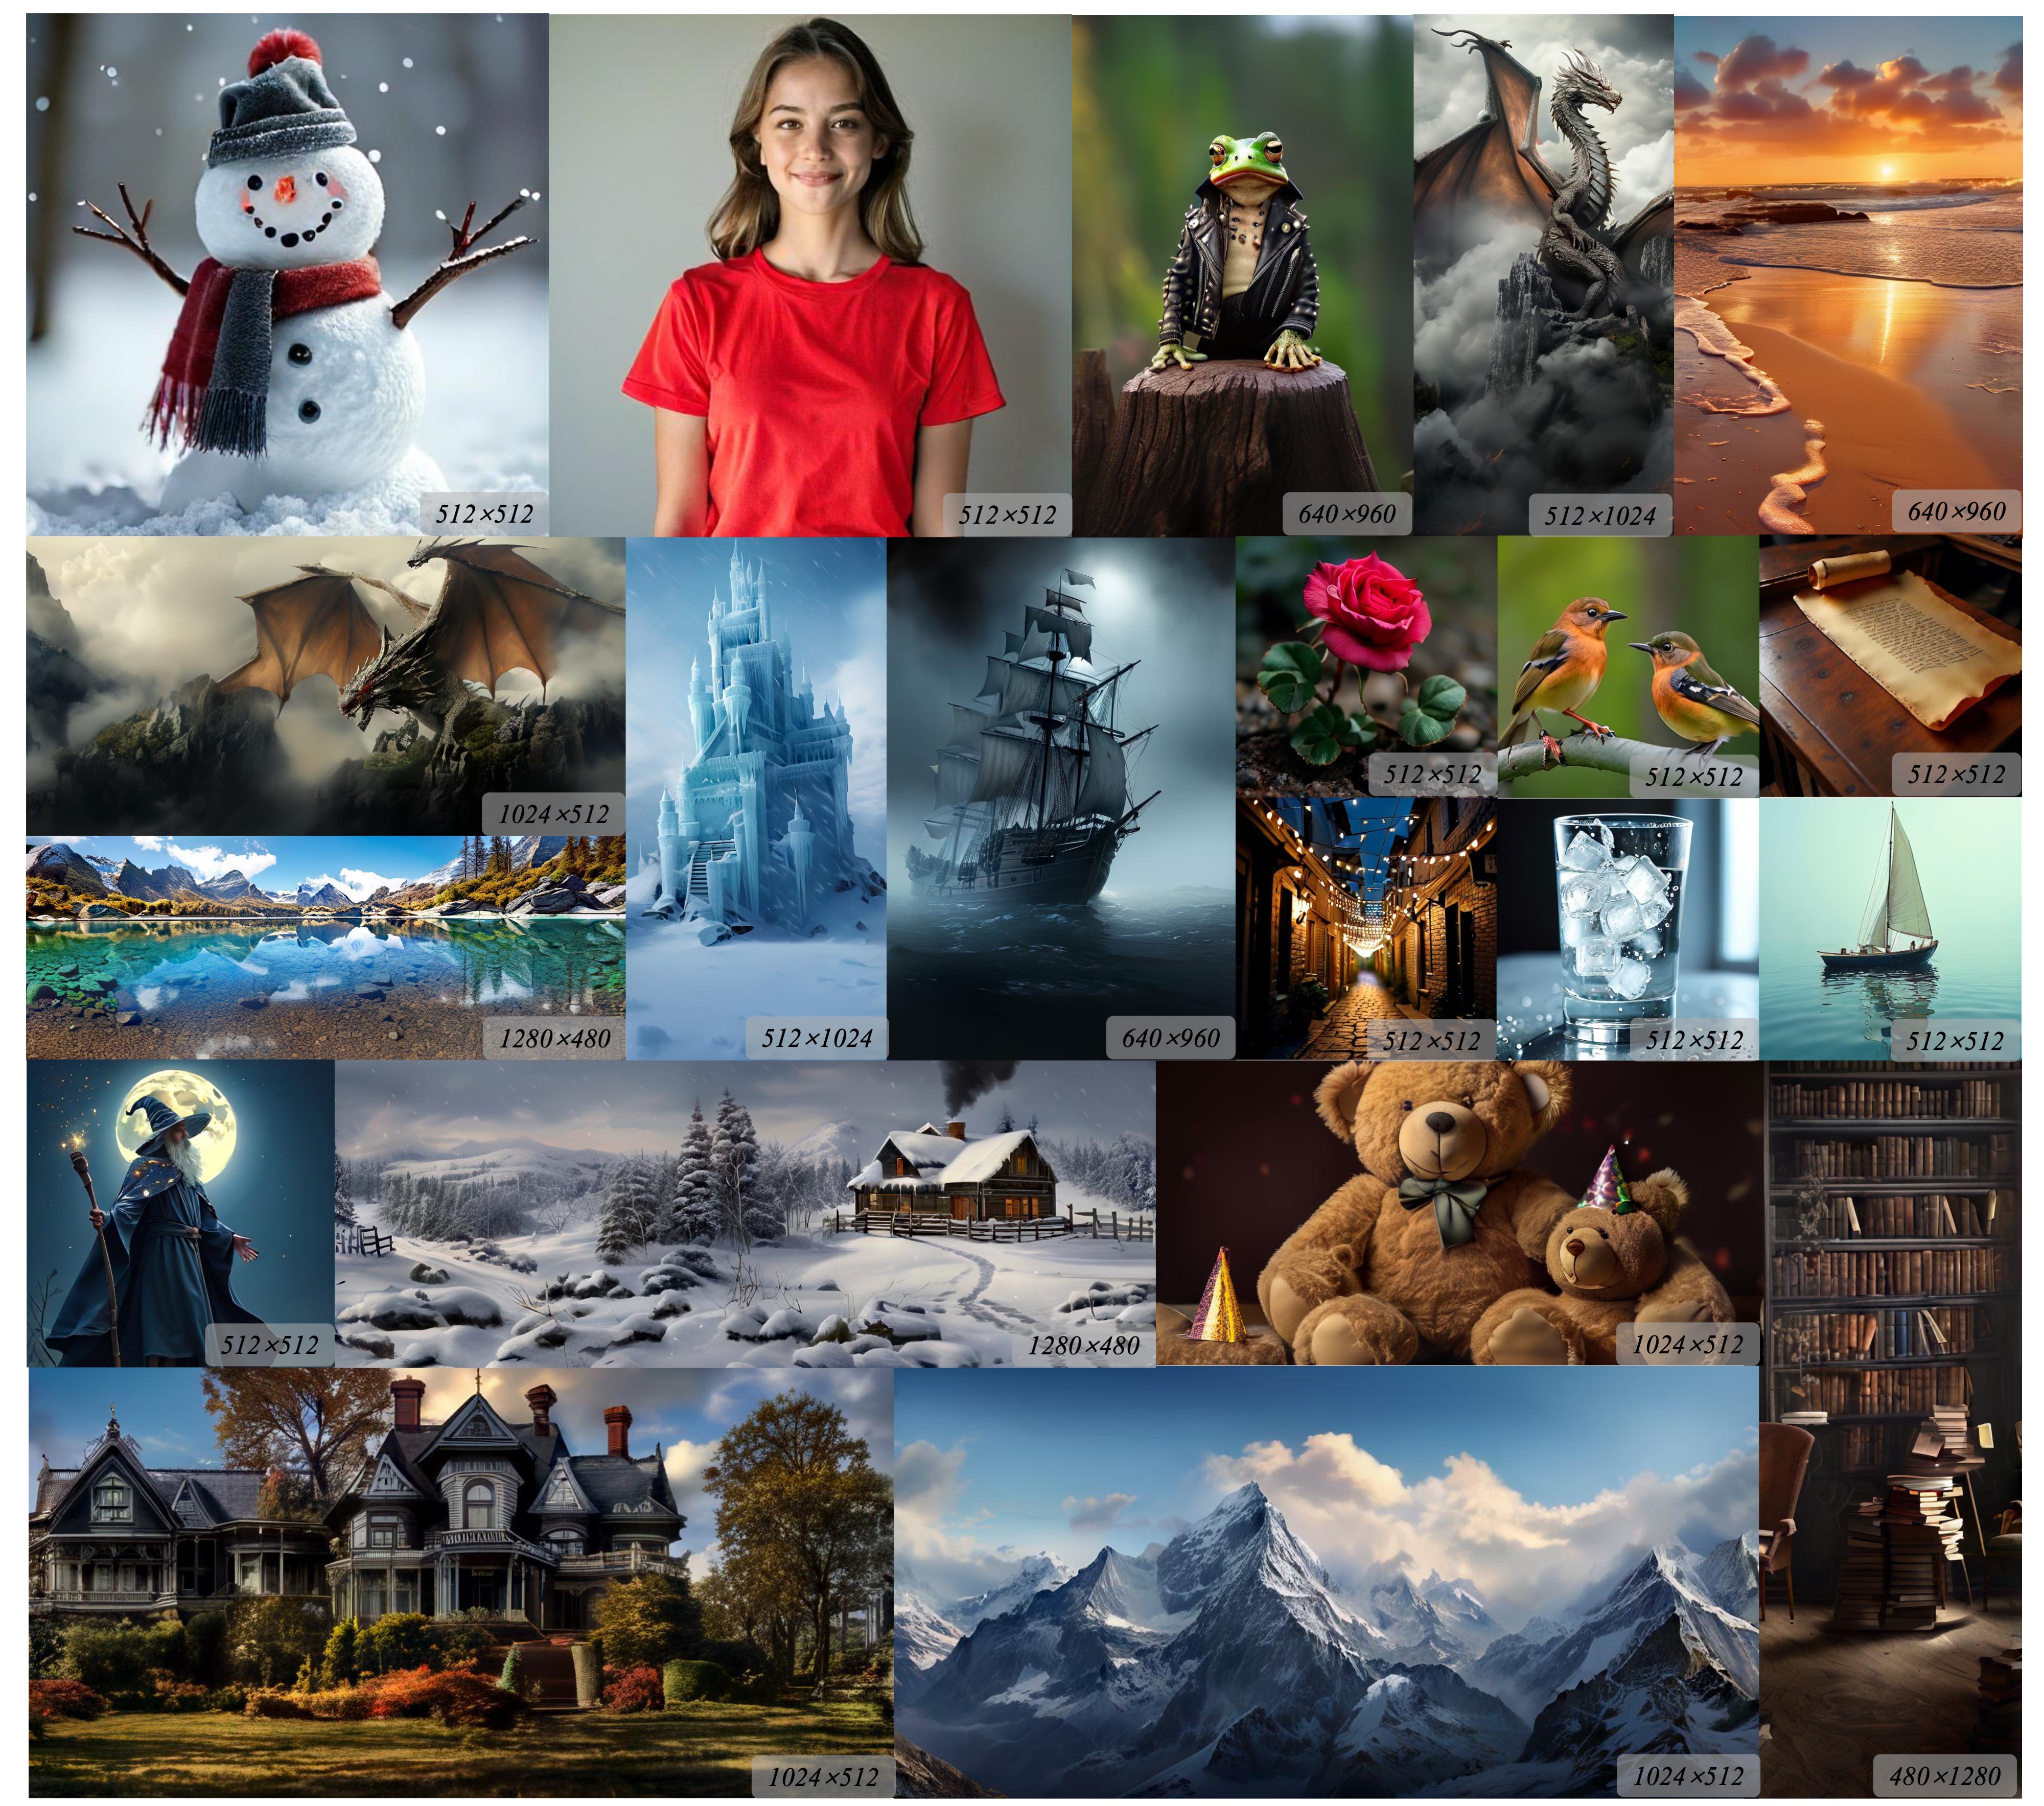
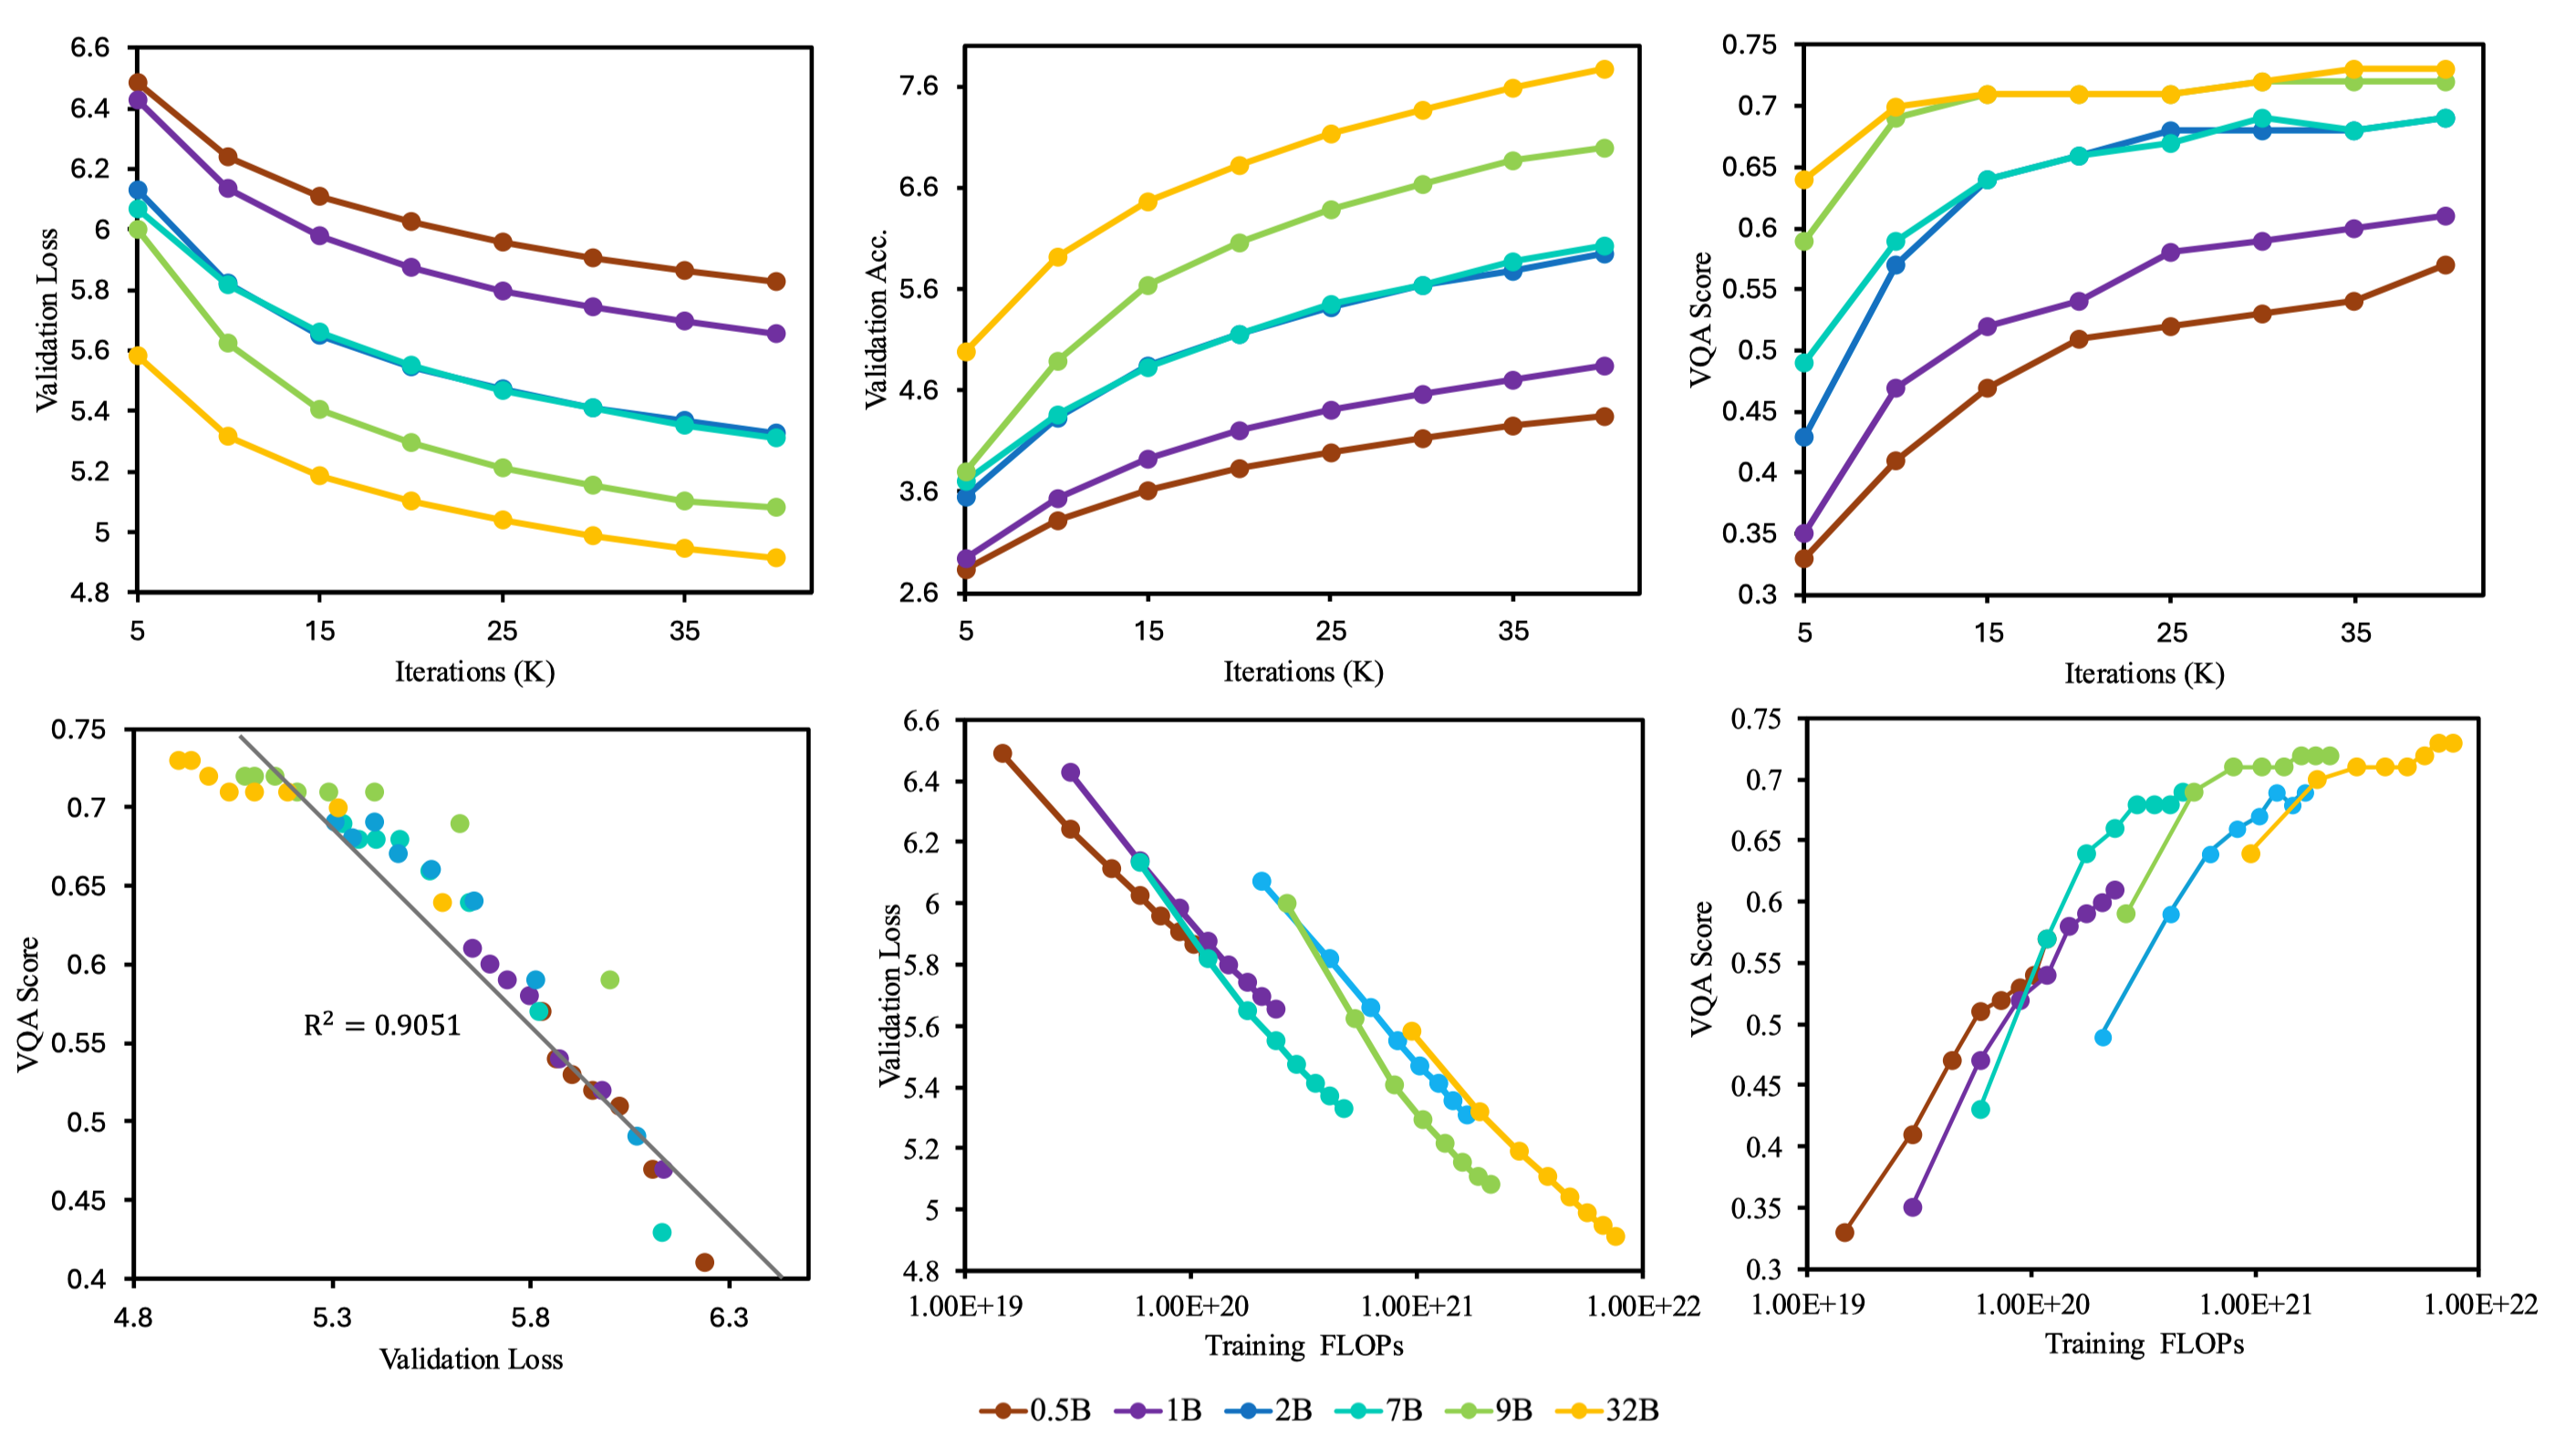
: Scalable and Versatile Unified Multimodal Generator which supports Visual Understanding, Visual Generation and Multi-modal Generation Liquid can generate high-quality, photorealistic images of any aspect ratio by language in an autoregressive paradigm. 🔥 Scaling Law for multimodal generation Liquid shows clear Scaling Law in multimodal generation across different sizes(0. License This project is licensed under the MIT License - see the LICENSE file for details. Citation If you find this project useful, please consider citing:
Frequently asked questions
How many stars and forks are recorded?
FoundationVision/Liquid has 640 stars and 36 forks.
What is the repository rank?
FoundationVision/Liquid is ranked 15,668.
What language and category are recorded?
FoundationVision/Liquid has 640 stars, uses Python and belongs to Models.
Which repository is closest in rank?
FoundationVision/Liquid is compared with NVlabs/genvs, ranked 15,670 with 640 stars.
README
Liquid: Language Models are Scalable and Unified
Multi-modal Generators
This repo implements Liquid, a scalable and unified autoregressive generation paradigm that seamlessly integrates multimodal comprehension and generation.
📰 News
2025-03-25: Data processing and model pretraining scripts have been updated in Data.md and TRAIN.md.
2025-03-04: Text-to-image and visual understanding evaluation scripts for Liquid are released in EVAL.md.
2025-02-28: Paper, demo, model, and project page for Liquid are all released.
📑 Open-Source Plan
Liquid-7B-IT (Instruction Tuned Multimodal Model with Instruction Following Ability)
[✅] Web Demo
[✅] Evaluation
[✅] Checkpoints
[✅] Training Codes
Liquid-0.5B~32B-Pretrain (Multimodal extension models of six different scales ranging from 0.5B to 32B across three model families. )
[ ] Checkpoints
📽️Inference
Using Liquid for inference or evaluation doesn't require complex environment dependencies. Since it's essentially a HuggingFace format language model, you only need the transformers library and some basic components to run it. Refer to EVAL.md for recommended versions.
Run the Gradio Demo locally
If deploying on a GPU with less than 30GB VRAM, you may need to enable load_in_8bit in AutoModelForCausalLM.from_pretrained in app.py for image generation to avoid out-of-memory errors.
pip install gradio==4.44.1
pip install gradio_client==1.3.0

cd evaluation
python app.py
Single inference
# Engage in pure language dialogue.

python inference_t2t.py  --model_path Junfeng5/Liquid_V1_7B  --prompt  "Write me a poem about Machine Learning."


# image understanding
python inference_i2t.py --model_path Junfeng5/Liquid_V1_7B  --image_path samples/baklava.png   --prompt 'How to make this pastry?'


# image generation, add --load_8bit for GPU with less than 30GB VRAM
python inference_t2i.py   --model_path Junfeng5/Liquid_V1_7B --prompt "young blue dragon with horn lightning in the style of dd fantasy full body"
We present Liquid, an auto-regressive generation paradigm that seamlessly integrates visual comprehension and generation.
Unlike previous multimodal large language model (MLLM), Liquid achieves this integration using a single large language model (LLM), eliminating the need for external pretrained visual embeddings such as CLIP.
For the first time, Liquid uncovers a scaling law that performance drop unavoidably brought by the unified training of visual and language tasks diminishes as the model size increases.
Furthermore, the unified token space enables visual generation and comprehension tasks to mutually enhance each other
🔥 Multimodal Generation
Liquid : Scalable and Versatile Unified Multimodal Generator which supports Visual Understanding, Visual Generation and Multi-modal Generation
Liquid can generate high-quality, photorealistic images of any aspect ratio by language in an autoregressive paradigm.
🔥 Scaling Law for multimodal generation
Liquid shows clear Scaling Law in multimodal generation across different sizes(0.5B to 32B).
License
This project is licensed under the MIT License - see the LICENSE file for details.
Citation
If you find this project useful, please consider citing:
@article{wu2026liquid,
  title={Liquid: Language Models are Scalable and Unified Multi-Modal Generators},
  author={Wu, Junfeng and Jiang, Yi and Ma, Chuofan and Liu, Yuliang and Zhao, Hengshuang and Yuan, Zehuan and Bai, Song and Bai, Xiang},
  journal={International Journal of Computer Vision},
  volume={134},
  number={1},
  year={2026},
  publisher={Springer US New York}
}