🔎 coding-agent-search (cass)




Unified, high-performance TUI to index and search your local coding agent history. Aggregates sessions from Codex, Claude Code, Gemini CLI, Cline, OpenCode, Amp, Cursor, ChatGPT, Aider, Pi-Agent, Prime Agent, Oh My Pi, GitHub Copilot Chat, Copilot CLI, OpenClaw, Clawdbot, Vibe, Crush, Goose, Hermes, Kimi Code, Muse Code, Qwen Code, Factory (Droid), Antigravity, OpenHands, Grok Build, Grok Bot, Codebuff/Freebuff, Devin CLI, Shelley, and Kiro CLI into a single, searchable timeline.
curl -fsSL "https://raw.githubusercontent.com/Dicklesworthstone/coding_agent_session_search/main/install.sh?$(date +%s)" \
  | bash -s -- --easy-mode --verify
# Windows (PowerShell)
& ([scriptblock]::Create((irm "https://raw.githubusercontent.com/Dicklesworthstone/coding_agent_session_search/main/install.ps1"))) -EasyMode -Verify
Installs the latest release by default. Pass --version / -Version to pin a specific version.
Or via package managers:
# Homebrew (Apple Silicon macOS + Linux)
brew install dicklesworthstone/tap/cass

# Windows (Scoop)
scoop bucket add dicklesworthstone https://github.com/Dicklesworthstone/scoop-bucket
scoop install dicklesworthstone/cass
The Homebrew tap installs prebuilt release tarballs (not bottles) for Linux and Apple Silicon macOS. On Intel macOS, use the install script with --from-source.
🤖 Agent Quickstart (Robot Mode)
⚠️ Never run bare cass in an agent context — it launches the interactive TUI. Always use --robot or --json.
# 1) Check the installed interface once per version (recipe verified on 0.8.0).
cass --version
cass search --help

# Verify a newly installed executable without opening the configured archive.
cass selftest --json
# `health --binary-only` still reports (and therefore probes) archive readiness.

# 2) For a quick history question, start with scoped read-only lexical retrieval.
#    Hybrid remains the product default; lexical is explicit for this workflow.
cass search "performance regression" --workspace /path/to/project --days 7 \
  --mode lexical --no-maintenance --robot --robot-meta --fields minimal \
  --limit 5 --max-tokens 2000 --timeout 2000

# 3) Find the current or recent session for this workspace
cass sessions --current --json
cass sessions --workspace "$(pwd)" --json --limit 5

# 4) View + expand a hit (use source_path/line_number from search output)
cass view /path/to/session.jsonl -n 42 -C 3 --json --timeout 2000

# 5) Discover the full machine API
cass capabilities --json
cass robot-docs guide
cass robot-docs schemas

# 6) Exclude a noisy agent harness from future indexing
cass sources agents list --json
cass sources agents exclude openclaw
cass sources agents include openclaw
The retrieval flags above are available in 0.8.0. On older builds, check help;
if --no-maintenance is absent, report the mismatch instead of dropping the
read-only constraint. --timeout is in milliseconds, while --max-tokens limits
approximate output size. Also set a caller-side deadline (for example, GNU
timeout 10s); an externally interrupted command may leave incomplete JSON.
Inspect budget.timed_out even after exit 0: timed-out empty hits are not proof
that no history exists. A maintenance-required response ends the retrieval
attempt; indexing or repair is a separate mutating task. Use triage/health/status
for readiness diagnosis, not as repeated prerequisites to a short summary.
Broaden scope deliberately, expand useful hits, and preserve source/line citations.
view -C bounds context lines, not bytes; check excerpt size before including
a long JSONL record in an agent prompt.
Output conventions
- stdout = data only
- stderr = diagnostics
- exit 0 = success
Search asset contract
- SQLite is the source of truth for indexed conversations and messages. All derived assets (lexical index, semantic vectors, analytics rollups, retention backups) can be rebuilt from SQLite; no derived asset is authoritative.
- Lexical search is the required fast path. Missing, stale, or incompatible lexical assets are treated as derived-state problems that cass should rebuild from SQLite instead of asking operators to perform routine manual repair.
- Hybrid is the default search intent. Robot metadata (
--robot --robot-meta) reports the requested mode, realized mode, semantic refinement status, and any lexical fallback reason when semantic assets are not ready. - Semantic assets are opportunistic background enrichment. Lexical-only results are expected during first indexing, semantic catch-up, disabled semantic policy, or unavailable local model/vector files.
- Semantic model acquisition is opt-in:
cass models installdownloads the defaultall-minilm-l6-v2(aliasminilm, ~90 MB) only on explicit request;--model multilingual-minilmselects the larger multilingual MiniLM L12 model (~480 MB) for CJK/mixed-language archives. Cass never auto-downloads or auto-selects the multilingual space. Air-gapped installs use--from-file. While the selected model is absent, hybrid search uses lexical-only and reportsfallback_mode="lexical"in health/status. cass triage --jsoncombines readiness,next_command,recommended_commands[], docs/schema pointers, starter workflows, and accepted recoveries for diagnosis. Review recommended mutations before executing them.cass health --jsonandcass status --jsonremain the narrower truth surfaces for readiness, active rebuilds, and recovery.
Lexical publish durability (atomic-swap)
- Every lexical publish is an atomic renameat2(RENAME_EXCHANGE) on Linux, or a parked-rename + restore-on-failure dance elsewhere. Readers never see a half-torn index — they see either the old or the new generation, never a mix. See
src/indexer/mod.rs::publish_staged_lexical_index. - The prior-live generation is retained under
/index/.lexical-publish-backups//for a bounded retention window. Default cap is1(keep just the most-recent prior generation for one-step rollback); override via theCASS_LEXICAL_PUBLISH_BACKUP_RETENTIONenv var (0disables retention entirely, higher N keeps deeper history). Pruning runs after every successful publish and emits structuredtracing::info!events withfreed_bytes+retention_limitfor observability. - Crash recovery is automatic: a crash between the atomic swap and the retain-rename is handled by
recover_or_finalize_interrupted_lexical_publish_backupat the start of the next lexical publish or rebuild (not at process startup), which moves any orphaned canonical sidecar (..publish-in-progress.bak) into.lexical-publish-backups/before the next publish lands.
Quarantine, GC, and the doctor/diag surface
- Corrupt or failed-validation assets are quarantined rather than auto-deleted.
cass diag --json --quarantineenumerates every quarantined derived artifact (failed seed bundles, retained publish backups, quarantined lexical generations; conversations excluded at ingest are listed bycass quarantine list --json) withsize_bytes,age_seconds,safe_to_gc, and a human-readablegc_reason. Thesafe_to_gcflag is advisory — it reflects retention policy + cleanup dry-run eligibility and is not wired to any automatic deletion path. cass doctor --jsonsurfaces the same quarantine summary pluschecks[]status for every diagnostic the tool runs. Without--fix, doctor is read-only (auto_fix_applied=false,auto_fix_actions=[],issues_fixed=0); with--fixit applies only the repairs whose dry-run plans are proven safe (currently: Track A analytics rebuild, Track B rollup rebuild viarebuild_token_daily_statswhen thetoken_usageledger is intact).- Lexical generation cleanup uses a dispositions + inspection-required-first policy. Operators running
cass doctor --fixnever have a generation reclaimed silently — every quarantine stays on disk until an explicit derived-asset rebuild (cass models backfillor an index refresh recommended bycass health --json) supersedes it. - A derived (SQLite fallback) FTS repair that fails identically on 5 consecutive
cass indexruns escalates from a warning to a non-zero exit (#434): the counter persists in/index/.fts-repair-failure-streak.json, watch daemons log the escalation instead of exiting, and any run whose repair succeeds — or fails differently — resets it. Canonical rows and the Tantivy index are unaffected; runcass doctor --rebuild-canonical-fts --yes --jsonfor the explicit repair.
Schema stability guarantees
- JSON contract surfaces are pinned by golden-file regression tests under
tests/golden/robot/:capabilities,selftest,health,status,diag,models status/verify/check-update,introspect,doctor,api-version,stats,search,export-html,onboarding, thequarantineanddedupcommands andanalytics incidents, plussessionsandpackon their missing-database and error paths only.swarm statusscenarios are pinned undertests/golden/swarm_status/.triage,swarm work-packetandswarm linthave no golden files; their shape is covered only by assertion tests. A change to any field name, type, or nullability fails the golden test suite and requires a deliberate regeneration pass (UPDATE_GOLDENS=1 rch exec -- env CARGO_TARGET_DIR=/data/tmp/cass-golden-target cargo test --test golden_robot_json --test golden_robot_docs). cass introspect --json'sresponse_schemasblock enumerates every schema in a stable alphabetical order (BTreeMap-backed — see bead coding_agent_session_search-8sl73).- Error envelopes (
{error: {code, kind, message, hint, retryable}}) have a fixed shape.kindvalues are kebab-case; branch onerr.kind, not on the numeric code, for codes ≥ 10 (see the Error Handling section below).
📬 Agent Mail Fallback (When MCP Tools Are Not Exposed)
If your runtime does not expose built-in mcp-agent-mail tools (for example, list_mcp_resources is empty), you can still coordinate via direct MCP HTTP calls.
1) Start the local Agent Mail server
~/.local/pipx/venvs/mcp-agent-mail/bin/python -m mcp_agent_mail.cli serve-http --host 127.0.0.1 --port 8765
2) Use the Streamable HTTP MCP endpoint (/mcp)
curl -sS -X POST http://127.0.0.1:8765/mcp \
  -H 'Content-Type: application/json' \
  -d '{"jsonrpc":"2.0","id":"health","method":"tools/call","params":{"name":"health_check","arguments":{}}}'
3) Minimal coordination flow (project -> agent -> message -> inbox -> ack)
# Ensure project
curl -sS -X POST http://127.0.0.1:8765/mcp -H 'Content-Type: application/json' -d \
'{"jsonrpc":"2.0","id":"ensure","method":"tools/call","params":{"name":"ensure_project","arguments":{"human_key":"/data/projects/coding_agent_session_search"}}}'

# Register agent
curl -sS -X POST http://127.0.0.1:8765/mcp -H 'Content-Type: application/json' -d \
'{"jsonrpc":"2.0","id":"register","method":"tools/call","params":{"name":"register_agent","arguments":{"project_key":"/data/projects/coding_agent_session_search","program":"codex","model":"gpt-5","name":"YourAgentName"}}}'

# Send message
curl -sS -X POST http://127.0.0.1:8765/mcp -H 'Content-Type: application/json' -d \
'{"jsonrpc":"2.0","id":"send","method":"tools/call","params":{"name":"send_message","arguments":{"project_key":"/data/projects/coding_agent_session_search","sender_name":"YourAgentName","to":["PeerAgent"],"subject":"[coord] hello","thread_id":"coord-2026-02-13","ack_required":true,"body_md":"Online and starting work."}}}'

# Fetch inbox
curl -sS -X POST http://127.0.0.1:8765/mcp -H 'Content-Type: application/json' -d \
'{"jsonrpc":"2.0","id":"inbox","method":"tools/call","params":{"name":"fetch_inbox","arguments":{"project_key":"/data/projects/coding_agent_session_search","agent_name":"YourAgentName","limit":50,"include_bodies":true}}}'

# Acknowledge message id 42
curl -sS -X POST http://127.0.0.1:8765/mcp -H 'Content-Type: application/json' -d \
'{"jsonrpc":"2.0","id":"ack","method":"tools/call","params":{"name":"call_extended_tool","arguments":{"tool_name":"acknowledge_message","arguments":{"project_key":"/data/projects/coding_agent_session_search","agent_name":"YourAgentName","message_id":42}}}}'
Important caveat
mcp_agent_mail defaults to sqlite+aiosqlite:///./storage.sqlite3. That means the server working directory determines which mailbox database you are using. To avoid "project not found" confusion, start the server from the same directory your team expects for mailbox state.
📸 Screenshots
Search Results Across All Your Agents
Three-pane layout with semantic styling: filter bar with pills, results list with color-coded agents and score tiers, and syntax-highlighted detail preview with tab navigation

Rich Conversation Detail View
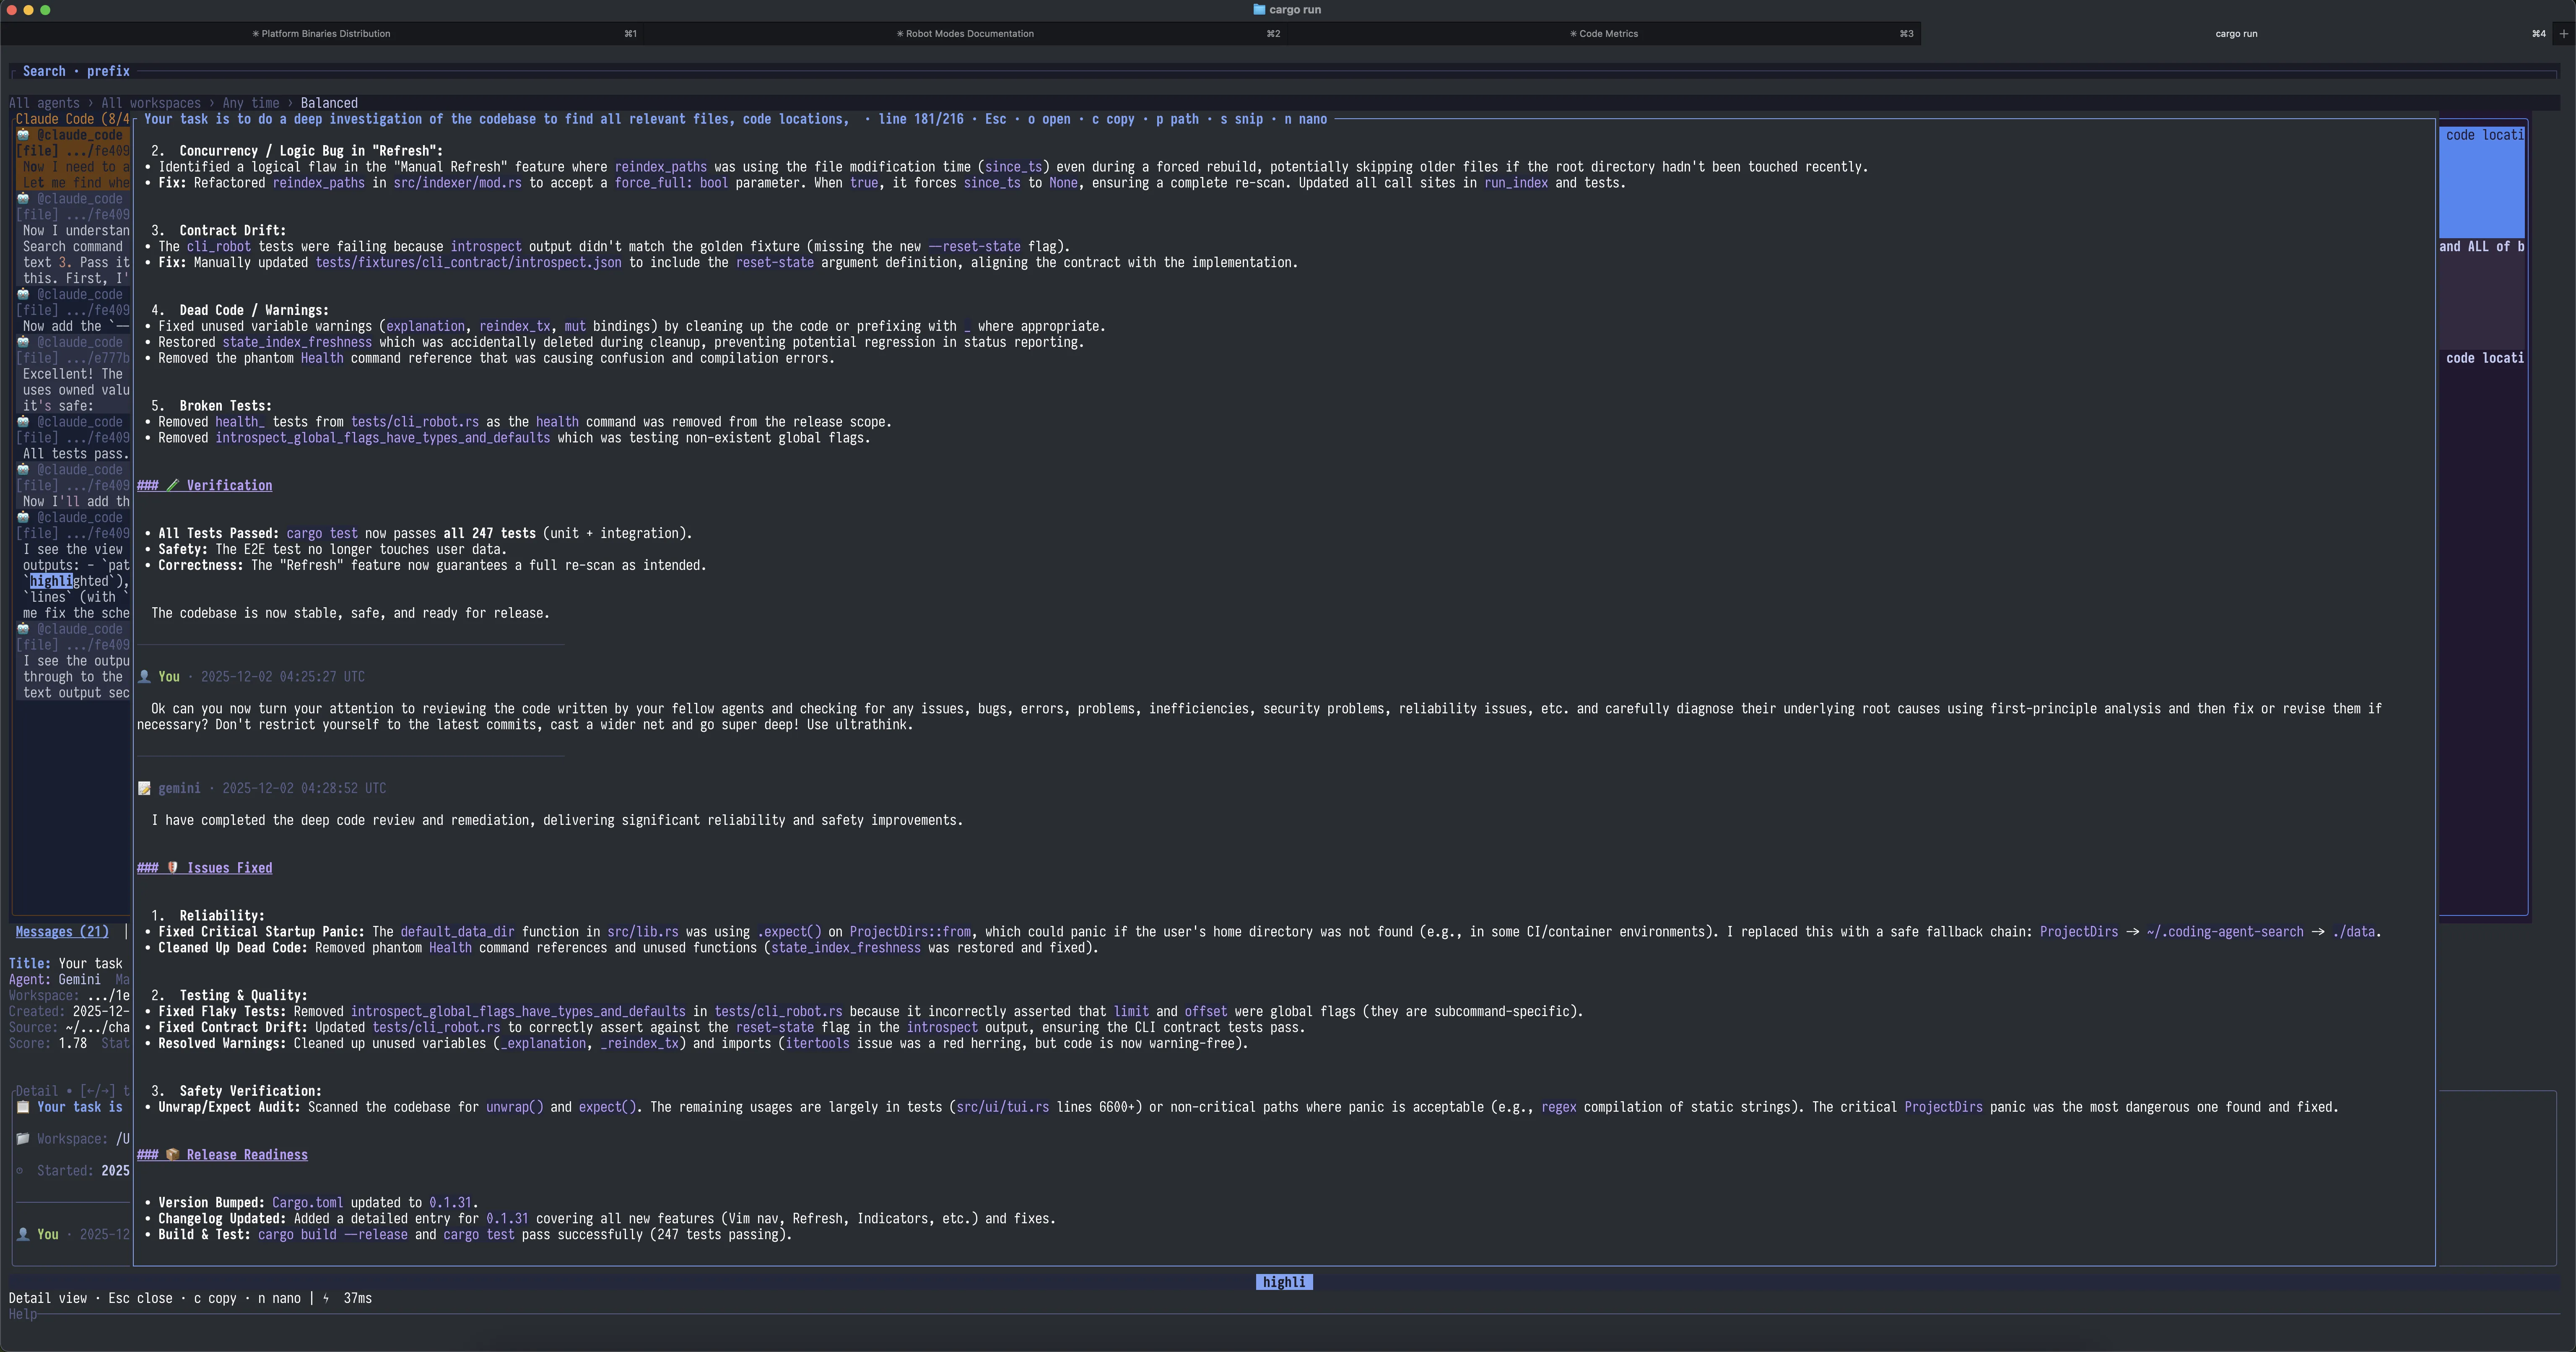
Full conversation rendering with markdown formatting, code blocks, headers, and structured content
Quick Start & Keyboard Reference
Built-in help screen (press F1 or ?) with all shortcuts, filters, modes, and navigation tips

💡 Why This Exists
The Problem
AI coding agents are transforming how we write software. Claude Code, Codex, Cursor, Copilot, Aider, Pi-Agent; each creates a trail of conversations, debugging sessions, and problem-solving attempts. But this wealth of knowledge is scattered and unsearchable:
- Fragmented storage: Each agent stores data differently—JSONL files, SQLite databases, markdown logs, proprietary JSON formats
- No cross-agent visibility: Solutions discovered in Cursor are invisible when you're using Claude Code
- Lost context: That brilliant debugging session from two weeks ago? Good luck finding it by scrolling through files
- No semantic search by default: File-based grep doesn't understand natural language queries; cass can add optional local ML search when model files are installed
The Solution
cass treats your coding agent history as a unified knowledge base. It:
- Normalizes disparate formats into a common schema
- Indexes everything with a purpose-built full-text search engine
- Surfaces relevant past conversations in milliseconds
- Respects your privacy—everything stays local, nothing phones home
Who Benefits
- Individual developers: Find that solution you know you've seen before
- Teams: Share institutional knowledge across different tool preferences
- AI agents themselves: Let your current agent learn from all your past agents (via robot mode)
- Power users: Build workflows that leverage your complete coding history
✨ Key Features
⚡ Instant Search (Sub-60ms Latency)
- "Search-as-you-type": Results update instantly with every keystroke.
- Edge N-Gram Indexing: We frontload the work by pre-computing prefix matches (e.g., "cal" -> "calculate") during indexing: 2–20 character prefixes of every word in titles and in the first 4 KiB of each message, trading disk space for fast lookup at query time.
- Smart Tokenization: Handles
snake_case("my_var" matches "my" and "var"), hyphenated terms, and code symbols (c++,foo.bar) correctly. - Zero-Stall Updates: The background indexer commits changes atomically;
reader.reload()ensures new messages appear in the search bar immediately without restarting. - One-shot CLI overhead: the sub-60ms figure is the engine query. A one-shot
cass search --robotcurrently spends roughly a second in archive open and integrity preflight on a ~10 GB archive;--robot-metareports that separately as_meta.timing.other_ms, whilesearch_msstays in the tens of milliseconds.
🧠 Optional Semantic Search (Local Inference, No Network at Query Time)
-
Local inference: Uses frankensearch's pure-Rust native MiniLM implementation with local safetensors weights. Once MiniLM is installed, no network traffic is required to answer queries.
-
Warm-daemon reuse: Semantic and hybrid CLI searches automatically use an already-running local embedding daemon (including a socket selected with
CASS_DAEMON_SOCKET) and only initialize the installed in-process model if daemon inference fails. Pass--daemonto permit auto-spawning a missing daemon in human-mode searches (robot/JSON searches never spawn one, even with--daemon, because their bounded budget cannot wait for a daemon to start; startcass daemonyourself first;_meta.effective.daemonshows the request and what applied), or--no-daemonto force direct inference.--fast-onlystays in the deterministic hash-vector space. Each data directory gets a distinct default socket and owner-private pinned key; fresh handshake, health, embedding, batch, and rerank challenges authenticate the exact response and immutable Frankensearch embedding identity before any daemon output is used.--two-tierprogressive refinement (fast results refined in place by the quality tier) is experimental and currently inactive: the one-shot CLI collapses it to a single-tier quality search and the TUI's progressive lanes are disabled at HEAD, so hybrid search today is lexical plus one MiniLM refinement pass when the model is installed. -
Opt-in acquisition:
cass models installdownloadsall-minilm-l6-v2from Hugging Face on explicit request and verifies SHA256 checksums.cass models install --model multilingual-minilmexplicitly selectsparaphrase-multilingual-MiniLM-L12-v2for CJK and mixed-language retrieval. Nothing is fetched until an install command runs, and merely installing the multilingual model never changes the active space. -
Air-gapped install:
cass models install --model --from-fileaccepts a pre-downloaded model directory so you can bring the assets in yourself. -
Switching spaces: both models output 384 values, but their identities and vectors are incompatible. Set
CASS_SEMANTIC_EMBEDDER=multilingual-minilm, then runcass models backfill --tier quality --embedder multilingual-minilm; cass keeps lexical fail-open active until the complete new generation is atomically published. -
Required files (all must be present after install;
cass models verify --modelchecks the selected model):model.safetensorstokenizer.jsonconfig.jsonspecial_tokens_map.jsontokenizer_config.json
-
Vector index: Stored as
vector_index/index-.fsviin the data directory. -
Lexical fail-open: While the model is absent,
cassreturns lexical-only results and reportsfallback_mode="lexical"in health/status; search never blocks on semantic assets.
Explicit Hash Vector Tier
The deterministic hash embedder is available only when explicitly selected, such as with --fast-only, --embedder hash, or CASS_SEMANTIC_EMBEDDER=hash. It is a separate lexical-feature vector space, not a silent substitute for missing MiniLM vectors:
| Feature | ML Model (MiniLM) | Hash Embedder (FNV-1a) |
|---|---|---|
| Meaning Understanding | ✅ "car" ≈ "automobile" | ❌ Exact tokens only |
| Initialization Time | ~500ms (model loading) | <1ms (instant) |
| Network Dependency | None (after install) | None |
| Disk Footprint | ~90MB model files | 0 bytes |
| Deterministic | ✅ Same input = same output | ✅ Same input = same output |
Algorithm:
- Tokenize: Lowercase, split on non-alphanumeric, filter tokens <2 characters
- Hash: Apply FNV-1a to each token
- Project: Use hash to determine dimension index and sign (+1 or -1) in a 384-dimensional vector
- Normalize: L2 normalize to unit length for cosine similarity
When to Use:
- Quick setup without downloading model files
- Environments where ML inference overhead is unwanted
- Fast-tier testing or an explicitly chosen degraded mode
Override: Set CASS_SEMANTIC_EMBEDDER=hash to force hash mode even when ML model is available.
FSVI Vector Index Format
cass uses the frankensearch FSVI vector index format (.fsvi) for storing semantic embeddings.
Features:
- Memory-mappable: large indexes open without copying into RAM
- Quantization: supports
f32andf16storage for smaller on-disk size - Fast search: exact brute-force vector search by default; HNSW approximate search runs only when
--approximateis passed and the HNSW sidecar file exists.hnsw_readyinstatus --jsonmeans only that the sidecar file is present, not that ANN is in use
Index Location: ~/.local/share/coding-agent-search/vector_index/index-.fsvi
Search Modes
cass supports three search modes, selectable via --mode flag or Alt+S in the TUI:
| Mode | Algorithm | Best For |
|---|---|---|
| Lexical | BM25 full-text | Exact term matching, code searches |
| Semantic | Vector similarity | Conceptual queries, "find similar" |
| Hybrid (default) | Lexical + single-tier semantic refinement fused with RRF; lexical fail-open | Balanced precision and recall |
Lexical Search: Uses Quill's BM25 implementation with prefix matching. Best when you know the exact terms you're looking for. The lexical index is derived from SQLite; if it is missing, stale, or incompatible, cass reports the state and rebuilds through the normal indexing path from the canonical database.
Semantic Search: Computes vector similarity between query and indexed MiniLM embeddings. Finds conceptually related content even without exact term overlap. Explicit semantic mode requires the MiniLM model and a compatible MiniLM vector index; it never substitutes same-dimensional hash vectors.
Hybrid Search: The default. It combines lexical and semantic results using Reciprocal Rank Fusion (RRF) when semantic assets are ready, and it fails open to lexical when semantic enrichment is still catching up or disabled:
RRF_score = Σ 1 / (K + rank_i)
Where K=60 (tuning constant) and rank_i is the position in each result list. This balances the precision of lexical search with the recall of semantic search. Semantic refinement is a single pass over the installed MiniLM index; progressive two-tier refinement (--two-tier) is experimental and currently inactive.
# CLI examples
cass search "authentication" --mode lexical --robot
cass search "how to handle user login" --mode semantic --robot
cass search "auth error handling" --mode hybrid --robot
🎯 Advanced Search Features
- Wildcard Patterns: Full glob-style pattern support:
foo*- Prefix match (finds "foobar", "foo123")*foo- Suffix match (finds "barfoo", "configfoo")*foo*- Substring match (finds "afoob", "configuration")
- Auto-Fuzzy Fallback: On small indexes (up to 10,000 documents by default), an exact search with sparse results is retried with
*term*wildcards to broaden matches. A visual indicator shows when the fallback is active. - Query History Deduplication: Recent searches deduplicated to show unique queries; navigate with
Up/Downarrows. - Match Quality Ranking: New ranking mode (cycle with
F12) that prioritizes exact matches over wildcard/fuzzy results. - Match Highlighting: Snippets mark the terms the engine matched with
**bold**, in human-readable and robot/JSON output alike;--highlightalso marks the query terms' other occurrences, never marking a term twice.
🖥️ Rich Terminal UI (TUI)
Powered by FrankenTUI (ftui) — a high-performance Elm-architecture TUI framework with adaptive frame budgets, Bayesian diff selection, and spring-based animations.
- Three-Pane Layout: Filter bar (top), scrollable results (left), and syntax-highlighted details (right).
- Multi-Line Result Display: Each result shows location and up to 3 lines of context; alternating stripes improve scanability.
- Live Status: Footer shows real-time indexing progress—agent discovery count during scanning, then item progress as a progress bar labelled
Indexing 150/2000 (7%)—plus active filters. - Multi-Open Queue: Queue multiple results with
Ctrl+Enter, then open all in your editor withCtrl+O. Confirmation prompt for large batches (≥12 items). - Find-in-Detail: Press
/to search within the detail pane; matches highlighted withn/Nnavigation. - Mouse Support: Click to select results, scroll panes, or clear filters.
- Theming: Adaptive Dark/Light modes with role-colored messages (User/Assistant/System). Presets include dark, light, high-contrast, and accessible variants.
- Ranking Modes: Cycle through
recent/balanced/relevance/qualitywithF12; quality mode penalizes fuzzy matches. - Analytics Dashboard: 7 views (Dashboard, Explorer, Heatmap, Breakdowns, Tools, Plans, Coverage) with interactive charts, KPI tiles, and drill-down filtering. Open with
Alt+A;Escreturns to search. - Inline Mode: Run
cass tui --inlineto keep terminal scrollback intact. The UI anchors to a region of the terminal while logs scroll normally. Configure with--ui-heightand--anchor top|bottom. - Macro Recording: Capture input sessions with
cass tui --record-macro session.macrofor reproducible bug reports and workflow automation. Events are saved as human-readable JSONL with full timing data. - Asciicast Recording: Capture reproducible TUI demos and bug repro artifacts with
cass tui --asciicast demo.cast.- Security default: recording captures terminal output only (input keystrokes are not serialized by default).
📄 HTML Session Export
Export conversations as styled, portable HTML files with optional encryption:
- Mostly Self-Contained: All layout CSS and the export payload are inlined directly; the file opens without a local web server and references no Tailwind CDN (Tailwind is not used at runtime). Only the Prism.js syntax-highlighting assets are loaded from
cdn.jsdelivr.net, pinned with SRI hashes. - Progressive Enhancement / Graceful Degradation: Prism.js resources fall back via
onerror="...no-prism"— code blocks remain readable offline in plain monospace, and the page layout never depends on a network resource. - Password Protection: AES-256-GCM encryption with PBKDF2 key derivation (600,000 iterations)—opens directly in any browser
- Rich Styling: Dark/light themes, syntax-highlighted code blocks, collapsible tool calls
- Print-Friendly: Optimized print styles with page breaks and footers
- Searchable: Built-in search functionality within the exported document
TUI Usage: Press Ctrl+E in the detail view to open the export modal, or Ctrl+Shift+E to export Markdown immediately with defaults. On the detail pane's Export tab, e/h open the HTML export modal and m runs the Markdown export.
CLI Usage:
# Basic export
cass export-html /path/to/session.jsonl

# With encryption
printf '%s\n' "secret" | cass export-html /path/to/session.jsonl --encrypt --password-stdin

# Custom output location
cass export-html session.jsonl --output-dir ~/exports --filename "my-session"

# Open in browser after export
cass export-html session.jsonl --open

# Robot mode (JSON output)
cass export-html session.jsonl --json
🔗 Universal Connectors
Ingests history from 32 local agent connectors, normalizing them into a unified Conversation -> Message -> Snippet model. cass capabilities --json | jq .connectors is the canonical machine-readable inventory (kept in lockstep with the runtime registry):
- Codex:
~/.codex/sessions(Rollout JSONL) - Cline: VS Code global storage (Task directories)
- Gemini CLI:
~/.gemini/tmp(Chat JSON) - Claude Code:
~/.claude/projects(Session JSONL), plus macOS Desktop metadata sidecars under~/Library/Application Support/Claude/claude-code-sessionsand~/Library/Application Support/Claude/local-agent-mode-sessions - Clawdbot:
~/.clawdbot/sessions(Session JSONL) - Vibe (Mistral):
~/.vibe/logs/session/*/messages.jsonl(Session JSONL) - OpenCode:
.opencodedirectories (SQLite) - Amp:
~/.local/share/amp& VS Code storage - Cursor:
~/Library/Application Support/Cursor/User/global + workspace storage (SQLitestate.vscdb) - ChatGPT:
~/Library/Application Support/com.openai.chat(v1 unencrypted JSON; v2/v3 encrypted—see Environment) - Aider:
~/.aider.chat.history.mdand per-project.aider.chat.history.mdfiles (Markdown) - Pi-Agent:
~/.pi/agent/sessions(Session JSONL with thinking content) - Prime Agent (
prime_agent):~/.prime/agent/sessions/.jsonl(versions 1–3). Indexes the active branch with omission counts for abandoned siblings; preserves thinking, tool results and context summaries. Overrides, in precedence order:PRIME_AGENT_SESSION_DIR, legacyPRIME_AGENT_CODING_AGENT_SESSION_DIR, thenPRIME_AGENT_CODING_AGENT_DIR(with/sessionsappended). Prime retains its own agent identity. - Oh My Pi (
omp): OMP v18's default~/.omp/agent/sessions, named profiles under~/.omp/profiles//agent/sessions, XDG stores under$XDG_DATA_HOME/omp, and explicit OMP-only archive roots viaCASS_OMP_DATA_ROOT(pi-family JSONL, including per-session sub-agent transcripts) - GitHub Copilot Chat: VS Code global storage under
github.copilot-chat(JSON) - Copilot CLI:
~/.copilot/session-state, legacy~/.copilot/history-session-state, andgh copilotconfig paths (JSONL/JSON) - OpenClaw:
~/.openclaw/agents/*/sessions(Session JSONL) - Goose:
~/.local/share/goose/sessions/sessions.db(SQLite, v1.20+), plus the earlier per-session*.jsonllayout under~/.goose/sessions - Crush:
~/.crush/crush.dband per-project.crush/crush.db(SQLite) - Hermes:
~/.hermes/state.dband project-local.hermes/state.db(SQLite) - Devin CLI:
~/.local/share/devin/cli/sessions.db(SQLite; override withCASS_DEVIN_DATA_ROOT). Indexes visible local sessions along their active parent chain, preserving tool messages and excluding abandoned branches and inline image payloads. Cloud-only sessions are outside this connector's scope. - Shelley: reads the local SQLite conversation database directly. Set
CASS_SHELLEY_DB=/absolute/path/to/shelley.db, or add that file to thepathsof atype = "local"source insources.toml. Any filename is accepted after schema validation. Defaults include~/.config/shelley/shelley.dbandshelley.dbin the current directory. Live indexing watches the database and its WAL/SHM sidecars; metadata changes refresh existing sessions.CASS_SKIP_SUBAGENTS=1excludes conversations with a Shelley parent ID. The database can also contain credentials and application settings, so raw mirroring and remote database ingestion are disabled; keep the database on its original machine. - Grok Bot: indexes the desktop application's local rolling chat replica. Set
CASS_GROK_BOT_DATA_ROOTto its persistence directory. Native message IDs preserve already indexed history as older messages leave the application's window; repeat scans do not duplicate retained messages. CASS reads only chat content. Raw mirroring and automatic fleet copying are disabled because the replica also holds secret and approval fields. This connector is separate from the Grok CLI connector and does not fetch cloud history. - Kimi Code:
$KIMI_CODE_HOME/sessions/*/*/agents/*/wire.jsonl(default~/.kimi-code; sub-agents index as:), plus the legacy~/.kimi/sessions/*/*/wire.jsonllayout (Session JSONL) - Muse Code:
~/.local/share/muse/sessions/////session.jsonl, including nestedsubagent/*/session.jsonltranscripts (override withCASS_MUSE_DATA_ROOT) - Qwen Code:
~/.qwen/tmp/*/chats/session-*.json(Chat JSON) - Factory (Droid):
~/.factory/sessions(JSONL files organized by workspace slug) - Antigravity (IDE + agy CLI): both stores are probed by default — the IDE's
~/.gemini/antigravity/and the CLI's~/.gemini/antigravity-cli/— each holdingbrain//.system_generated/logs/transcript.jsonl(clean JSONL transcript) with the durable per-conversationconversations/.db(SQLite) mirrored alongside. IDE conversations are keyedide/so the two stores never collide;CASS_ANTIGRAVITY_DATA_ROOTreplaces both with one explicit base. Resume withcass resume --agent agy(agy --conversation). - OpenHands (OpenDevin):
~/.openhands/conversations//—base_state.jsonmetadata plus anevents/event-NNNNN-.jsonevent stream (JSON) - Grok Build (xAI
grok):~/.grok/sessions///—updates.jsonl(authoritative ACP session-update stream) withsummary.jsonmetadata andchat_history.jsonlfallback (override the base dir withGROK_HOME). Resume withgrok --resume. - Codebuff / Freebuff (
codebuff):~/.config/manicode/projects//chats//chat-messages.jsonwith itsrun-state.json(override withCASS_CODEBUFF_DATA_ROOT). Both products write the same Manicode store and no chat records which binary wrote it, so their sessions share one lineage identity,codebuff(filter with--agent codebuff). Messages are reconciled by their native IDs, so an edited message updates in place instead of duplicating. - Kiro CLI (
kiro):~/.kiro/sessions/cli/.jsonl(append-only event log: prompts, assistant messages, tool results) with the matching.jsonsnapshot read for session ID, working directory, title, timestamps and model.
Claude Code Desktop sidecars preserve title, workspace, model, and session IDs, but not necessarily the full conversation body. If Claude Code has culled an old CLI JSONL body, cass can still index searchable sidecar metadata while reporting that the conversation body is unavailable.
Connector Details
Pi-Agent parses JSONL session files with rich event structure:
- Location:
~/.pi/agent/sessions/(override the agent home withPI_CODING_AGENT_DIR, or the sessions directory directly withPI_SESSIONS_DIR) - Format: Typed events—
session_start,message,model_change,thinking_level_change - Features: Extracts extended thinking content, flattens tool calls with arguments, tracks model changes
- Detection: Scans for
*_*.jsonlpattern in sessions directory
Oh My Pi (omp) uses the same pi-family wire format but remains a separate
agent identity throughout search, analytics, resume, TUI, and HTML export:
- Default and profiles:
~/.omp/agent/sessions/and~/.omp/profiles//agent/sessions/;OMP_PROFILEselects a profile and takes precedence over legacyPI_PROFILE - XDG:
$XDG_DATA_HOME/omp/sessions/and$XDG_DATA_HOME/omp/profiles//sessions/when the OMP XDG root exists - Overrides and ownership:
PI_CODING_AGENT_SESSION_DIRnames the exact OMP sessions directory.CASS_OMP_DATA_ROOTdeclares an OMP-only archive/store root and is the right choice for copied, mounted, or custom OMP data.PI_CODING_AGENT_DIRis shared by both pi-family programs, so CASS conservatively keeps otherwise-ambiguous paths under that root owned by Pi-Agent; use one of the OMP-specific variables when OMP identity matters.PI_CONFIG_DIRchanges the home-relative.ompconfig directory name. - Resume: results in the current live home/config store use
omp [--profile ] --resume; copied profiles, XDG archives, remote mirrors, and explicit roots also carry--session-dirso a canonical-looking archive cannot reopen a different live store - Upgrade behavior: archives created by older cass versions are reclassified from
pi_agenttoompusing the same conservative canonical/XDG/remote-mirror ownership policy as live discovery, then the derived lexical index and analytics are rebuilt so a transcript cannot remain attributed to both agents. The conventional~/.local/share/ompshape is durable path evidence; an arbitrary historical custom$XDG_DATA_HOME/omppath is reclassified only while that root is currently configured and resolvable. Without provider-qualified evidence, ambiguous historical paths fail closed as Pi-Agent rather than letting a generic.../omp/sessionsdirectory steal ownership.
OpenCode reads SQLite databases from workspace directories:
- Location:
.opencode/directories (scans recursively from home) - Format: SQLite database with sessions table
- Detection: Finds directories named
.opencodecontaining database files
🌐 Remote Sources (Multi-Machine Search)
Search across agent sessions from multiple machines—your laptop, desktop, and remote servers—all from a single unified index. cass uses SSH/rsync to efficiently sync session data, tracking provenance so you know where each conversation originated.
Interactive Setup Wizard (Recommended)
The easiest way to configure multi-machine search is the interactive setup wizard:
cass sources setup
What the wizard does:
- Discovers SSH hosts from your
~/.ssh/config - Probes each host to check for:
- Existing cass installation (and version)
- Agent session data (Claude, Codex, Cursor, Gemini, etc.)
- System resources (disk space, memory)
- Lets you select which hosts to configure
- Installs cass on remotes that don't have it (optional)
- Indexes existing sessions on remotes (optional)
- Configures
sources.tomlwith correct paths and mappings - Syncs the configured remotes by running
cass sources syncright after configuration (skipped with--skip-syncor--dry-run;--jsonsetup defers it and reports the command to run)
Wizard options:
| Flag | Purpose |
|---|---|
--hosts |
Configure only specific hosts (comma-separated) |
--dry-run |
Preview changes without applying them |
--non-interactive |
Use auto-detected defaults for scripting |
--skip-install |
Don't install cass on remotes |
--skip-index |
Don't run indexing on remotes |
--skip-sync |
Skip the final cass sources sync. Interactive setup runs that sync after the hosts are configured and records it as complete only once it has actually finished; --json setup always defers it and reports sync.status = "pending" with the command to run |
--resume |
Resume an interrupted setup |
--json |
Output progress as JSON (for automation) |
Examples:
# Full interactive wizard
cass sources setup

# Configure specific hosts only
cass sources setup --hosts laptop,workstation,build-server

# Preview without making changes
cass sources setup --dry-run

# Resume interrupted setup
cass sources setup --resume

# Non-interactive for CI/CD
cass sources setup --non-interactive --hosts myserver --skip-install
Resumable state: If setup is interrupted (Ctrl+C, connection lost), state is saved to the cache directory (~/.cache/cass/setup_state.json on Linux). Resume with --resume.
Testing your real fleet
Tailscale discovery is optional: cass sources discover --tailscale --json adds
online tailnet peers to SSH-config discovery, and cass sources setup --tailscale
offers them in setup. It reads local tailscale status --json with a five-second
deadline; a missing CLI, stopped daemon, or login failure produces a warning and
leaves SSH-config discovery available. Explicit setup --hosts skips discovery.
Connections use ordinary SSH over assigned Tailscale IPv4 addresses, so MagicDNS
is not required. Matching SSH aliases retain their user/key configuration;
otherwise SSH uses its normal defaults. IPv6-only peers are currently omitted.
Tailscale ACLs, SSH authorization and host-key checks still apply; discovery does
not log in, install Tailscale, or change either SSH or tailnet configuration.
The local fixture and Docker tests do not prove that your machines can sync and
search each other's sessions. The opt-in live harness uses actual SSH connections
and cass sources discover, sources add, sources sync, and search. It creates isolated synthetic
Codex sessions on each machine, checks source provenance and filters, repeats a
sync to detect duplicates, and appends messages. It checks both lexical and default
hybrid search, requires one JSON response per sync, holds the real indexing lock to
test busy refusal, and recovers transferred sessions through sources reingest.
A refused SSH connection must leave the other sources searchable.
Keep the inventory and SSH configuration outside this repository. For example, create a mode-0600 JSON file containing:
{
  "ssh_config": "/private/path/to/ssh_config",
  "hosts": [{"ssh": "workstation"}, {"ssh": "laptop"}]
}
Then run with an explicit binary:
python3 scripts/e2e/live_fleet_search.py \
  --inventory /private/path/to/fleet.json \
  --cass-bin /path/to/cass
Python 3 and authenticated SSH access are required on the remote machines.
The Unix runner needs Python 3.9+, rsync, and a CASS binary supporting the tested
commands. Each inventory alias must appear in the supplied SSH configuration;
included configuration files are supported. Host-key verification stays enabled.
To exercise actual tailnet discovery and transport, add --tailscale to the
harness command and use tailnet IPv4 addresses as the private inventory targets.
Keep any required SSH users, keys and trusted host-key aliases in the private SSH
configuration. For a discovery test independent of explicit aliases, use SSH
Match originalhost entries rather than literal Host entries for those addresses.
The harness retains fresh test directories and raw
receipts privately outside git; it never changes existing session archives or
deletes test data. Console results use ordinal labels. An unreachable machine
keeps the overall result failed, even if the other machines pass. Do not attach
raw receipts or inventories to public issues: they contain machine identities.
Remote Installation Methods
When the wizard installs cass on remote machines, it tries every viable method in this priority order, falling through to the next when one fails; setup fails only when all of them do, and the error lists each attempt:
| Priority | Method | Speed | Requirements |
|---|---|---|---|
| 1 | cargo-binstall | ~30s | cargo-binstall pre-installed, compatible release binary |
| 2 | Pre-built binary | ~10s | curl/wget, GitHub access, compatible release binary |
| 3 | cargo install | ~5min | Rust toolchain, 1GB disk, 2GB RAM |
| 4 | Full bootstrap | ~10min | curl, 1GB disk, 2GB RAM (installs rustup) |
crates.io publishing resumed at 0.7.0 (GH#416): the long-stale registry gap (0.6.13, published before the Quill/OMP era) is closed — the entire dependency chain now resolves from crates.io (
frankensearch 0.4.0, thefrankentorch-*family,frankenhnsw), socargo install coding-agent-searchbuilds the current line again. The installer and GitHub Release binaries remain the fastest paths.
Resource Requirements:
- Minimum 1GB disk space for installation
- Recommended 2GB RAM for compilation
- Linux pre-built binaries require glibc 2.38+ on conventional FHS-style distributions; older glibc, musl-only, and NixOS hosts fall back to source installation when possible.
- SSH access with key-based authentication
What Gets Installed:
- The
cassbinary (location depends on method:~/.cargo/bin/cassfor cargo-based,~/.local/bin/cassfor pre-built binary) - No daemon, no background services—just the binary
Installation Progress: The wizard shows real-time progress for each stage:
Installing cass on laptop...
  [1/4] Checking environment...     ✓
  [2/4] Downloading binary...       ████████░░ 80%
  [3/4] Verifying checksum...       ✓
  [4/4] Setting up PATH...          ✓
Use --skip-install if you prefer to install manually on remotes.
Host Discovery & Probing
The setup wizard automatically discovers SSH hosts from your configuration:
Discovery Sources:
~/.ssh/config(parses Host entries)- Hosts with wildcards (
*,?) are automatically excluded
Probe Results (for each discovered host):
| Check | Purpose |
|---|---|
| Connectivity | Can we establish SSH connection? |
| cass Version | Is cass already installed? What version? |
| Agent Data | Which agents have session data? |
| Session Count | How many conversations exist? |
| System Info | OS, architecture, disk space, memory |
Each setup run probes every selected host afresh; probe results are not cached between runs.
Manual Setup
For manual configuration without the wizard:
# Add a remote machine using platform presets
cass sources add [email protected] --preset macos-defaults

# Or specify paths explicitly
cass sources add dev@workstation --path ~/.claude/projects --path ~/.codex/sessions

# Sync sessions from all configured sources
cass sources sync

# Check source health and connectivity
cass sources doctor
Remote Archive Safety
Remote source diagnostics are intentionally local-only. cass triage --json,
cass doctor --json, cass health --json, and cass status --json report the
remote_source_sync summary from cass-owned evidence: sources.toml,
sync_status.json, the local remotes//mirror/ copy, and archive DB
provenance rows. They do not open SSH sessions, mutate remote machines, or
rewrite provider session logs while classifying source gaps.
cass sources doctor is the explicit networked exception: it performs bounded,
read-only probes of configured source hosts. Its per-source human summary keeps
the same native reachability, binary-health, and mirror/sync state codes and
safe command as the JSON report. It intentionally does not claim local search
readiness, because a remote host probe cannot establish the controller's local
SQLite, lexical, or semantic asset state.
This matters because agent harnesses can prune their own logs. If a laptop is
retired, a remote path disappears, or a provider truncates older sessions, the
cass archive DB and cass-owned local mirror may be the only remaining evidence
for those conversations. Treat gap names such as remote_source_unavailable,
remote_source_pruned, local_archive_ahead_of_remote, and
remote_copy_ahead_verified as preservation signals first: keep the archive and
mirror intact, then run the recommended cass sources sync --json (all configured remote sources; --source narrows it) or
source-specific sync command after reviewing the reported evidence.
Raw-mirror retention is explicit and audited. Use cass mirror prune --older-than 90d --json or cass mirror prune --max-size 100GB --json to get a
dry-run plan; add --apply only after reviewing the scope and totals. Preview
entries contain at most 1,000 manifest/blob details; omitted_entry_count
reports additional candidates. Planned counts and bytes cover the entire plan,
including omitted details. Use provider/path selectors to inspect a narrower
scope. Previews do not append audit records. Add
--keep-tag to pin captures linked to tagged conversations. prune
holds down blobs referenced by captures from the last 7 days by default, writes
complete intent/result records to raw-mirror/v1/pruned.jsonl for non-empty
applied plans, and refuses apply mode
while an index/watch job is active.
Applied pruning syncs the audit independently of the optional capture setting
CASS_RAW_MIRROR_FSYNC. Each completed result is recorded before the next
removal; a later failure preserves those earlier results. An abrupt crash
between a removal and its result record can still leave an intent without a
confirmed result.
Use --provider opencode and/or --source-path '*/opencode.db' with an age
or size rule to target one source without retiring unrelated captures.
Repeated providers are alternatives; a source-path glob further narrows them.
A pruned capture of a source that is still on disk is copied again by the next
index run. On a machine whose providers never delete their session files, set
CASS_RAW_MIRROR=0 (or false, no, off) to stop capturing altogether.
Indexing and search are unchanged, and existing captures stay until you prune
them. cass doctor reports raw_mirror_capture_disabled and warns about what is
given up: a session file its provider later deletes survives only in the
archive DB.
With a selector, --max-size measures unique blobs in that selection. Shared
blobs still referenced outside it and orphan blobs without source provenance
remain protected. The JSON plan records the selectors and scope_blob_bytes.
Large mutable sources are stored as 4 MiB content-addressed chunks. Growing
JSONL files reuse every unchanged complete chunk, and SQLite sources reuse
unchanged 4 MiB byte regions, so each historical snapshot remains byte-exact without
writing another full-file blob. Existing whole-blob manifests remain readable;
cass doctor --json reports storage_kind, chunk_count, the full-source
digest, and verifies every referenced chunk before treating a snapshot as
recovery authority.
Configuration File
Sources are configured in the platform config directory (Linux: ~/.config/cass/sources.toml, macOS: ~/Library/Application Support/cass/sources.toml):
[[sources]]
name = "laptop"
type = "ssh"
host = "[email protected]"
paths = ["~/.claude/projects", "~/.codex/sessions"]
sync_schedule = "manual"

[[sources]]
name = "workstation"
type = "ssh"
host = "[email protected]"
paths = ["~/.claude/projects"]
sync_schedule = "daily"

# Path mappings rewrite remote paths to local equivalents
[[sources.path_mappings]]
from = "/home/dev/projects"
to = "/Users/me/projects"

# Agent-specific mappings
[[sources.path_mappings]]
from = "/opt/work"
to = "/Volumes/Work"
agents = ["claude_code"]
Configuration Fields:
| Field | Description |
|---|---|
name |
Friendly identifier (becomes source_id) |
type |
Connection type: ssh or local |
host |
SSH host (user@hostname) |
paths |
Paths to sync (supports ~ expansion) |
sync_schedule |
manual, hourly, or daily. Only the jobs installed by cass schedule install run it; without them it is a label and syncs happen when you run cass sources sync |
path_mappings |
Rewrite remote paths to local equivalents |
CLI Commands
# List configured sources
cass sources list [--verbose] [--json]

# Add a new source
cass sources add  [--name ] [--preset macos-defaults|linux-defaults] [--path ...] [--no-test]

# Remove a source
cass sources remove  [--purge] [-y]

# Check connectivity and config
cass sources doctor [--source ] [--json]

# Sync sessions
cass sources sync [--source ] [--no-index] [--verbose] [--dry-run] [--json]
Excluding Noisy Agent Harnesses
If one harness is generating mostly junk or looped output, you can disable it persistently even if its files remain on disk:
# Inspect current include/exclude state
cass sources agents list --json

# Stop indexing this harness in future runs
cass sources agents exclude openclaw

# Re-enable it later
cass sources agents include openclaw
cass stores this preference in sources.toml (~/.config/cass/sources.toml on Linux, ~/Library/Application Support/cass/sources.toml on macOS), so future scans, syncs, and watch-mode updates remember it automatically.
By default, cass sources agents exclude also removes already archived local data for that agent and rebuilds the lexical index so the exclusion frees space instead of only blocking future imports.
If you want to block future indexing but keep the data already archived:
cass sources agents exclude openclaw --keep-indexed-data
Sync Engine Internals
The sync engine uses rsync over SSH for efficient delta transfers and falls back to other transports when rsync is unavailable:
Transfer Methods (auto-detected):
| Method | When Used | Characteristics |
|---|---|---|
| rsync | rsync available on both ends | Delta transfers, compression, progress stats |
| WSL rsync | Windows without native rsync, WSL with rsync installed | Runs wsl rsync |
| scp | rsync unavailable | Full file copies through the system scp, inheriting the OpenSSH agent, keys and ~/.ssh/config |
| SFTP | the fallbacks above unavailable | Full file transfers via the SSH native protocol |
Safety Guarantees:
- Additive-only syncs: rsync runs WITHOUT
--delete, so remote deletions never propagate locally. - Local copies follow the remote: rsync runs with
-aand without-u, so a local mirror file that differs from the remote is overwritten, even when the local copy is newer. The mirror is a copy of the remote, not a place to edit sessions. - Interrupted transfers resume:
--partialkeeps a partly transferred file under its final name so the next sync continues it. A failed sync can therefore leave a truncated file until the next sync completes.
Transfer Configuration:
| Setting | Default | Purpose |
|---|---|---|
| Connection timeout | 10s | Fail fast on unreachable hosts |
| Transfer timeout | 300 s of I/O inactivity | rsync --timeout aborts a transfer that stalls this long; there is no wall-clock limit on a transfer that keeps moving |
| Compression | Enabled | Reduce bandwidth for text-heavy sessions |
| Partial transfers | Enabled | Resume interrupted syncs |
rsync Flags Used:
-avz --links --safe-links --stats --partial [--protect-args | --secluded-args] --timeout 300 \
  -e "ssh [-F $CASS_SSH_CONFIG] -o BatchMode=yes -o ConnectTimeout=10 -o ServerAliveInterval=15 -o ServerAliveCountMax=3 -o StrictHostKeyChecking=yes"
Where -avz = archive mode + verbose + compression. --protect-args/--secluded-args is auto-detected per remote rsync version (omitted when the remote rejects it), and --timeout carries the transfer timeout in seconds. StrictHostKeyChecking=yes means a host whose key is not already in known_hosts fails with "Host key verification failed". Connect once with plain ssh and accept the key, or add it with ssh-keyscan, before the first sync.
Data Flow:
Remote: ~/.claude/projects/
    ↓ (rsync over SSH)
Local: ~/.local/share/coding-agent-search/remotes//mirror/_/
    ↓ (connector scan)
Index: agent_search.db + index/v9-quill/
Where is a filesystem-safe version of the remote path (e.g. `.claude_projects`), and is an FNV-1a hash of the original path in hex, so foo/bar and foo_bar never collide.
Sessions from remotes are indexed alongside local sessions, with provenance tracking to identify origin.
Path Mappings
When viewing sessions from remote machines, workspace paths may not exist locally. Path mappings rewrite these paths so file links work on your local machine:
# List current mappings
cass sources mappings list laptop

# Add a mapping
cass sources mappings add laptop --from /home/user/projects --to /Users/me/projects

# Test how a path would be rewritten
cass sources mappings test laptop /home/user/projects/myapp/src/main.rs
# Output: /Users/me/projects/myapp/src/main.rs

# Agent-specific mappings (only apply for certain agents)
cass sources mappings add laptop --from /opt/work --to /Volumes/Work --agents claude_code,codex

# Remove a mapping by index
cass sources mappings remove laptop 0
TUI Source Filtering
In the TUI, filter sessions by origin:
- F11: Cycle source filter (all → local → remote → all)
- Shift+F11: Open source filter menu to select specific sources
Remote sessions display with a source indicator (e.g., [laptop]) in the results list.
Provenance Tracking
Each conversation tracks its origin:
source_id: Machine identifier (e.g., "laptop", "workstation")origin_kind:localorremoteorigin_host: the remote host label, absent for local sessionsworkspace_original: Original path on the remote machine (before path mapping)
--fields provenance selects exactly source_id, origin_kind and origin_host.
These fields appear in JSON/robot output and enable filtering:
cass search "auth error" --source laptop --json
cass timeline --since 7d --source remote
cass stats --by-source
🤖 AI / Automation Mode
cass is purpose-built for consumption by AI coding agents—not just as an afterthought, but as a first-class design goal. When you're an AI agent working on a codebase, your own session history and those of other agents become an invaluable knowledge base: solutions to similar problems, context about design decisions, debugging approaches that worked, and institutional memory that would otherwise be lost.
Why Cross-Agent Search Matters
Imagine you're Claude Code working on a React authentication bug. With cass, you can instantly search across:
- Your own previous sessions where you solved similar auth issues
- Codex sessions where someone debugged OAuth flows
- Cursor conversations about token refresh patterns
- Aider chats about security best practices
This cross-pollination of knowledge across different AI agents is transformative. Each agent has different strengths, different context windows, and encounters different problems. cass unifies all this collective intelligence into a single, searchable index.
Self-Documenting API
cass teaches agents how to use it—no external documentation required:
# First-stop capability contract for agents
cass triage --json
cass capabilities --json
# → {"version": "...", "workflows": [...], "mistake_recoveries": [...], "commands": [...], "exit_codes": [...], "env_vars": [...]}

# Full API schema with argument types, defaults, and response shapes
cass introspect --json

# Topic-based help optimized for LLM consumption
cass robot-docs commands # All commands and flags
cass robot-docs schemas # Response JSON schemas
cass robot-docs examples # Copy-paste invocations
cass robot-docs exit-codes # Error handling guide
cass robot-docs guide # Quick-start walkthrough
Forgiving Syntax (Agent-Friendly Parsing)
AI agents sometimes make syntax mistakes. cass aggressively normalizes input to maximize acceptance when intent is clear:
| What you type | What cass understands |
Correction note |
|---|---|---|
cass -robot --limit=5 |
cass --robot --limit=5 |
Single-dash long flags normalized |
cass --Robot --LIMIT 5 |
cass --robot --limit 5 |
Case normalized |
cass search "auth" --max_results 5 |
cass search "auth" --limit 5 |
Snake-case long flag normalized before alias recovery |
cass find "auth" |
cass search "auth" |
find/query/q → search via alias table |
cass --robot-docs |
cass robot-docs |
Flag-as-subcommand detected |
cass commands --json |
cass robot-docs commands |
Robot-docs topic shorthand detected |
cass schemas --json |
cass robot-docs schemas |
Robot-docs topic shorthand detected |
cass ready --json |
cass triage --json |
One-shot triage alias |
cass preflight --json |
cass triage --json |
One-shot triage alias |
cass --json |
cass triage --json |
Top-level robot request defaults to safe preflight |
cass --robot |
cass triage --json |
Top-level robot request defaults to safe preflight |
cass --json search "auth" |
cass search "auth" --json |
Leading structured flag moved to the robot-capable subcommand |
cass --robot status |
cass status --json |
Leading robot flag canonicalized to JSON output |
cass answer "auth" --json |
cass pack "auth" --json |
Cited-handoff aliases normalized to answer pack |
cass why auth failed --json --max-evidence 3 |
cass pack "auth failed" --json --max-evidence 3 |
Question/RC prompt aliases normalized to answer pack |
cass auth failed --json --max-evidence 3 |
cass pack "auth failed" --json --max-evidence 3 |
Bare robot queries with pack-only flags become answer packs |
cass search auth failed --json --max-evidence 3 |
cass pack "auth failed" --json --max-evidence 3 |
Explicit robot search with pack-only flags becomes an answer pack |
cass html-export session.jsonl --json |
cass export-html session.jsonl --json |
Reversed HTML export aliases normalized to the archive exporter |
cass current --json |
cass sessions --current --json |
Current-session shorthand normalized to session discovery |
cass sessions current --json |
cass sessions --current --json |
Positional current accepted as the sessions current flag |
cass search --query "auth" --json |
cass search "auth" --json |
Named query option converted to required positional query |
cass search --q "auth" --json |
cass search "auth" --json |
Short/familiar query aliases converted to required positional query |
cass search auth error --json |
cass search "auth error" --json |
Adjacent unquoted query words folded into one search |
cass auth error --json |
cass search "auth error" --json |
Unquoted robot-mode query words folded into search |
cass search --agent codex --limit 5 auth error --json |
cass search "auth error" --agent codex --limit 5 --json |
Query moved before leading search filters |
cass view --path session.jsonl --line 42 --json |
cass view session.jsonl --line 42 --json |
Named path option converted to required positional path |
cass view session.jsonl --line-number 42 --json |
cass view session.jsonl --line 42 --json |
Legacy alias for --line; still reads raw file line 42 |
cass view session.jsonl line_number=42 --json |
cass view session.jsonl --message-index 42 --json |
A pasted search-hit field selects canonical message 42, not raw line 42 |
cass view source_path=session.jsonl source_id=local line_number=42 --json |
cass view session.jsonl --source local --message-index 42 --json |
Search hit field bundle accepted as a follow-up command (add conversation_id when the file holds several conversations) |
cass search "auth" --format json |
cass search "auth" --robot-format json |
Familiar format spelling converted to robot format |
cass search "auth" --output json |
cass search "auth" --robot-format json |
Familiar output spelling converted to robot format |
cass help search --json |
cass robot-docs commands |
Structured help intent routed to the machine-readable command reference |
cass --format json status |
cass status --robot-format json |
Leading format request moved to the target subcommand |
cass search "auth" --max-results 5 |
cass search "auth" --limit 5 |
Result-count alias converted to canonical limit |
cass search "auth" -n 5 |
cass search "auth" --limit 5 |
Familiar short count flag converted to canonical limit |
cass search "auth" --last 7 --before now |
cass search "auth" --since -7d --until now |
Familiar time-window aliases converted to canonical filters |
cass search "auth" last=7d before=now |
cass search "auth" --since -7d --until now |
Bare time-window assignments converted to canonical filters |
cass search "auth" --provider codex |
cass search "auth" --agent codex |
Provider/tool/connector aliases converted to canonical agent filter |
cass search "auth" provider=codex |
cass search "auth" --agent codex |
Bare provider assignment converted to canonical agent filter |
cass search auth provider codex limit 5 |
cass search auth --agent codex --limit 5 |
Bare filter key/value pairs after a query converted to canonical flags |
cass search --limt 5 |
cass search --limit 5 |
Flag typos within Levenshtein distance ≤2 corrected |
The CLI applies multiple normalization layers:
- Typo correction: when parsing fails, long flag names within Levenshtein distance 2 of a known flag are corrected (e.g.
--limt→--limit), and a first word within distance 2 of a subcommand is corrected to it (e.g.serach→search). A word that already names a subcommand is never changed, socass status --jsnrunsstatus --json.forgetandupgradeare reached only by exact spelling. - Case normalization:
--Robot,--LIMIT→--robot,--limit - Snake-case flag recovery:
--max_results,--data_dir, and other known snake_case long flags become canonical kebab-case before alias recovery runs - Single-dash recovery:
-robot→--robot(common LLM mistake) - Subcommand aliases:
ready/preflight→triage;find/query/q/grep/lookup→search;session→sessions;answer/evidence/bundle/handoff/why/explain/rca/root-cause/rootcause/summarize/summarise→pack;html-export/html_export/exporthtml→export-html;ls/list/info/summary→stats;st/state→status;reindex/idx/rebuild→index;show/get/read→view;diagnose/debug/check→diag;caps/cap→capabilities;inspect/intro→introspect;docs/help-robot/robotdocs→robot-docs - Robot-docs topic shorthands: non-command topics such as
commands,schemas,examples,exit-codes, andquickstartbecomerobot-docsinstead of falling through to search; command topics such asdoctorandsourcesuse structured help (cass help doctor --json,cass sources --help --json). Barecass guideis reserved for the guided-operations planner; usecass robot-docs guidefor the robot-docs walkthrough. - Root robot default:
cass --json,cass --robot, orcass --robot-format jsonwith no subcommand runs read-onlytriage - Leading structured flag recovery:
--json/--robotbefore a robot-capable subcommand is moved onto that subcommand - Named positional recovery:
--query/--q/--text/--patternfor search/pack and--path/--source-path/--file/--sessionfor drill-down/export commands become the required positional argument - Multi-word query recovery: adjacent unquoted query words after
search/packbecome one query positional - Structured format recovery:
--format json|jsonl|compact|sessions|toon,--output json|jsonl|compact|sessions|toon, and--output-format ...are accepted as--robot-format ...on robot-capable commands;export --format ...andexport --outputkeep their export meanings - Structured help recovery:
help --json,help commands --json, andsearch --help --jsonroute torobot-docs guide/robot-docs commands; plain--helpstays native clap help - Result-count aliases:
--max-results,--num-results,--results,--count,--top-k, and-nbecome--limiton commands with result limits - Time-window aliases:
--last 7,--before now,last=7d, andbefore=nowbecome canonical--since/--untilfilters - Provider aliases:
--provider,--tool,--connector, and matching assignments become canonical--agentfilters on search-like commands - Bare option pairs: after at least one search/pack query word,
provider codex,limit 5, andlast 7dbecome canonical filter flags before the remaining words are folded into the query - Pack-intent recovery: a bare robot query or explicit structured-output
searchwith pack-only flags such as--max-evidence,--max-sessions, or--freshness-policybecomespack, not implicit or explicitsearch - Drill-down line aliases:
--line-number,--line_numberandline=42become--line(a raw file line) - Search-hit fields:
line_number=42pasted from a search hit becomes--message-index 42(the canonical message ordinal the hit names), and asource_path=... source_id=... line_number=...bundle becomes the canonical path,--sourceand--message-indexform for follow-upview/expandcommands - Leading-filter query recovery: if a search/pack query comes after leading options, the query is moved back to the required positional slot
- Implicit robot search: unquoted top-level words with an explicit robot/JSON output request become a
searchquery unless they look like a subcommand typo - Current-session shorthand:
current,current-session, andsessions currentbecomesessions --current - Global flag hoisting: Position-independent flag handling
When corrections are applied, cass emits a teaching note to stderr so agents learn the canonical syntax. In robot/JSON mode the same information is emitted as one note: auto-corrected: line per correction on stderr (at most two: the normalization note and the typo-recovery note), so stdout stays data-only. Robot-mode notes are printed only when the command succeeds; a failing command's stderr is its single JSON error envelope. The same notes appear in search output under _meta.effective.auto_corrections with --robot-meta.
Structured Output Formats
Every command supports machine-readable output:
# Pretty-printed JSON (default robot mode)
cass search "error" --robot

# Streaming JSONL: one hit per line. Add --robot-meta to prepend a
# {budget, _meta} header line (elapsed_ms, next_cursor, state, index_freshness).
# The header also appears without --robot-meta when the search timed out
# (budget.timed_out), returned did-you-mean suggestions, --aggregate or --explain.
cass search "error" --robot-format jsonl               # hits only
cass search "error" --robot-format jsonl --robot-meta  # 1 _meta header + hits

# Compact single-line JSON (minimal bytes)
cass search "error" --robot-format compact

# Include performance metadata
cass search "error" --robot --robot-meta
# → { "hits": [...], "_meta": { "elapsed_ms": 12, "cache_hit": true, "wildcard_fallback": false, "lexical_degrade_reason": null, ... } }
#   lexical_degrade_reason is "query_fuel_exhausted" when a hybrid search dropped its
#   lexical leg because Quill's query fuel ran out (see CASS_QUILL_QUERY_FUEL_BUDGET)

# What the search actually ran (--robot-meta): check this instead of trusting the flags
cass search "error" --robot --robot-meta --days 7 | jq '._meta.effective'
# → { "command": "search", "query": "error",
#     "query_structure": "error",           // how the engine groups operands: `a OR b c` -> "a OR (b AND c)"
#     "query_recoveries": [],               // e.g. "1 unclosed '(' closed at the end of the query"
#     "db_path": "/home/you/.local/share/coding-agent-search/agent_search.db",
#     "db_path_source": "default",          // --db | env:CASS_DB_PATH | --data-dir | env:CASS_DATA_DIR | env:XDG_DATA_HOME | default
#     "time_window": { "since_ms": 1758067200000, "since_from": "--days 7", "until_ms": null, "until_from": null },
#     "filters": { "agents": [], "workspaces": [], "source": "all", "sessions_from_paths": null },
#     "auto_corrections": [] }              // each argv correction, worded like its stderr note
#   `cass pack "error" --json` carries the same object for the search it ran in
#   its own `_meta.effective` ("command": "pack", and no search-only "daemon"),
#   with home-directory paths, private hosts and secrets redacted like the rest
#   of the pack (the db_path above reads "[REDACTED_PATH]/agent_search.db").

# Per-hit trust verdict (advisory; --robot-meta only)
cass search "error" --robot --robot-meta
# Each hit then carries a metadata-only `trust` block:
#   "trust": {
#     "schema_version": 1,
#     "trust_tier": "unverified",     // trusted | likely | unverified | stale | failed
#     "confidence": "medium",         // low | medium | high
#     "provenance_refs": [],          // e.g. ["commit:ab0d12ef90ab", "bead:xyz", "release:v0.6.15"]
#     "stale_reason": "aged_out",     // present only when not fully trusted
#     "recommended_followup": "..."   // advisory next step (never a destructive command)
#   }
How agents should branch on trust_tier (relevance is not correctness — a
hit can be a landed fix or a failed attempt):
trust_tier |
Meaning | What to do |
|---|---|---|
trusted |
Landed, proof-backed, release/bead-contained | Safe to reuse |
likely |
Has provenance (commit/closed bead) but not proof-pinned | Confirm via the cited ref first |
unverified |
Relevant but no provenance link, or lexical-only corroboration | Corroborate before reuse |
stale |
Aged out (aged_out) or superseded (superseded_by_newer) |
Prefer a newer result |
failed |
A failed/reverted attempt (failed_attempt) |
Do not reuse |
The verdict is advisory metadata only — it never changes result ordering.
It is derived from metadata-only signals (recency, source health, realized
search mode, cwd-relative workspace match, and — opportunistically — linked
commit/bead/release provenance); it carries no raw session text. The same
trust block is attached to cass pack evidence. Branch on trust_tier and
stale_reason, not on confidence alone.
Provenance correlation is project-scoped and explicit-reference anchored:
for a hit from the project you are running cass in now, cass links it to a
closed bead or commit only when the hit's own indexed text references a known
identifier (bead: or commit:), joined against that project's local
beads and git history. A linked commit's containing release is resolved from
Git. Release containment preserves provenance but does not establish proof of
the excerpt's claim: a landed commit remains proof_debt and cannot become
trusted from this correlation alone. A temporal or
workspace coincidence is never enough, so an unrelated conversation never
inherits another's trust. Off-project hits report workspace_mismatch, and a
hit whose local source file no longer exists on disk reports source_unhealthy
(archive-only) instead of overtrusting a dead path.
# Deterministic answer pack for handoff prompts
cass pack "why did checkout fail" --robot --max-tokens 12000 --limit 40

# Freshness-sensitive pack: fail if selected evidence is outside the window
cass pack "checkout timeout after redirect" --robot \
  --freshness-policy strict --freshness-window-seconds 604800 \
  --max-tokens 12000 --require-evidence

# Token-budgeted pack for pasting into another agent
cass pack "checkout timeout after redirect" --robot \
  --max-tokens 4000 --max-evidence 8 --max-sessions 3 --max-excerpt-chars 600

# Pipeline from broad search to a bounded cited handoff
cass search "checkout timeout" --robot-format sessions \
  | cass pack "checkout timeout root cause" --robot --sessions-from -
Design principle: stdout contains only parseable JSON data; all diagnostics, warnings, and progress go to stderr.
Use search when you are still exploring candidate sessions. Use pack when
you need a compact, cited, extractive artifact to hand to another agent or a
human operator. Use status/health before trusting freshness-sensitive output,
and use doctor only for diagnostics or safe repair workflows. Use
export-html when you need a full browsable session archive; packs are
token-budgeted evidence bundles, not full exports and not external
summarization.
Pack robot output includes health, freshness, privacy, and warnings.
Warnings such as privacy_redactions_applied, semantic_fallback_lexical,
or no_evidence_found are data, not prose; branch on the JSON fields before
copying the pack into another tool. Stale selected evidence is structural:
inspect freshness.stale_evidence_count.
Packs exclude injected skill payloads by default. Add --include-skill-content
to include them explicitly; credential redaction still applies.
privacy.skill_content_included reports whether the selected evidence includes
skill payloads, including after token-budget trimming.
Swarm Operations Workflow
Use the swarm surfaces when multiple agents are sharing one repo and you need a single read-only view before claiming work:
# Current shared-work snapshot; does not claim, reopen, release, or run builds
cass swarm status --json

# Advisory packet for one bead; still create real reservations and Beads updates yourself
cass swarm work-packet --json --bead coding_agent_session_search-example

# Coordination hygiene check before closeout or takeover review
cass swarm lint --json --bead coding_agent_session_search-example

# Read-only sibling dependency drift sentinel
cass swarm dependency-drift --json
swarm status, swarm work-packet, swarm lint, swarm evidence,
swarm proof-debt and swarm failure-patterns collect the same bounded
read-only Git state and Beads exports when run from the repository root
without a fixture. Git uses
porcelain-v2 with optional locks disabled. Beads uses br 0.6.x --no-db, so its
JSONL snapshot is explicitly partial: unexported database changes may exist.
Recheck Beads and reservations before claiming work. Child commands share a
single 15-second request budget and each has an 8 MiB output cap; Beads categories
cap at 512 issues.
Failures report unavailable providers and unknown summary counts, not zero work.
RCH contributes aggregate active/queued job counts, fleet slots and posture from
rch status --json (API 1.0, schema 1.0.0). Responses older than 60 seconds or
more than 5 seconds in the future are unavailable. Worker addresses, commands
and job details are omitted. This provider remains partial: local Cargo/CPU
state and build admission are unknown, even when RCH reports no active jobs.
Agent Mail roster and reservation reads are opt-in: set CASS_SWARM_AGENT_MAIL_URL
to the server's HTTP MCP endpoint and, if required, CASS_SWARM_AGENT_MAIL_TOKEN.
The reader uses only resources/read, never a local database fallback or inbox
read. Mail shares the total request budget with a 3-second cap of its own;
responses are capped at 8 MiB, rosters at 512 agents, and full 250-row reservation
pages are refused. The total reservation count remains unknown; source metadata
reports only the observed active count. Activity and expiry use
the observation time. Task descriptions, reservation reasons and message bodies
are omitted. These observations do not authorize claims or establish proof.
CASS evidence remains unwired. Live lint marks itself partial and adds an
agent-mail-unavailable advisory whenever Agent Mail messages are not
collected. Fixture selection (--fixture or --fixture-dir --fixture-id ) retains deterministic behavior; swarm dependency-drift
also has a live path.
swarm status composes Beads, Agent Mail metadata, git state, rch/build
pressure, cass health/status, and proof references. Stale candidates are
advisory only: coordinate through Beads and Agent Mail before reopening,
force-releasing, or taking over work. Suggested commands are robot-safe
templates, not automatic actions.
The TUI's Swarm tab shows the same live payload for the directory the TUI was
started in. Open it from the command palette (Ctrl+P, "Swarm operations
cockpit") or by clicking its tab; it has no direct key. Entering the tab
starts one background read with this collector;
until it lands, every count shows as ?. Counts of providers that could not
be read stay ?, never zero. r reads again. Rendering never runs a provider
read.
swarm dependency-drift reads Cargo.toml and optional sibling checkouts to
report manifest pins, local HEAD/dirty state, strict validation commands, and
release-risk recommendations. It does not fetch remotes, edit manifests, run
builds, update Beads, send Agent Mail, delete files, or mutate git state.
When status points at prior evidence, use cass pack "query" --robot to create
a bounded cited handoff for another agent. Packs complement the cockpit; they do
not replace Beads for ownership, Agent Mail for coordination, or rch for proof
commands.
Token Budget Management
LLMs have context limits. cass provides multiple levers to control output size:
| Flag | Effect |
|---|---|
--fields minimal |
Only source_path, line_number, agent, source_id, conversation_id |
--fields summary |
minimal plus title, score |
--fields score,title,snippet |
Custom field selection |
--max-content-length 500 |
Truncate long fields (UTF-8 safe, adds "...") |
--max-tokens 2000 |
Soft budget (~4 chars/token); adjusts truncation dynamically |
--limit 5 |
Cap number of results |
cass pack "query" --robot |
Build a cited handoff pack from selected search evidence |
pack --max-tokens N |
Set the pack planner's soft budget |
pack --max-evidence N |
Cap evidence items selected into the pack |
pack --max-sessions N |
Limit how many sessions can contribute evidence |
pack --max-excerpt-chars N |
Shorten each cited excerpt before token estimation |
pack --fields summary |
Return top-level summary fields for a smaller JSON envelope |
pack --field-mask minimal|standard|full |
Select a documented pack projection; --fields accepts the same presets |
pack --freshness-policy strict --freshness-window-seconds N |
Reject stale evidence instead of silently mixing it into a pack |
pack --sessions-from FILE |
Restrict pack evidence to newline-delimited session paths; use - for stdin |
Truncated fields include a *_truncated: true indicator so agents know when they're seeing partial content.
Contributor verification for docs or contract changes should use rch, for example:
rch exec -- env CARGO_TARGET_DIR=${TMPDIR:-/tmp}/rch_target_cass_answer_pack_docs \
  cargo test --test golden_robot_docs
Error Handling for Agents
Errors are structured, actionable, and include recovery hints. A real sample from cass search foo --robot against a fresh data dir:
{
  "error": {
    "code": 3,
    "kind": "missing-index",
    "message": "cass has not been initialized in  yet, so search cannot run until the first index completes.",
    "hint": "Run 'cass index --full' once to discover local sessions and build the initial archive.",
    "retryable": true
  }
}
Kind names are kebab-case (e.g. missing-index, missing-db, semantic-unavailable, embedder-unavailable, ambiguous-source, timeout, config, lock-busy). Agents that branch on err.kind should treat them as stable identifiers. The full set (about 90 kinds) is defined in src/model/cli_error_kind.rs; the canonical way to discover a kind programmatically is to trigger the condition and inspect err.kind from the JSON envelope.
Exit codes follow a semantic convention:
| Code | Meaning | Typical action |
|---|---|---|
| 0 | Success | Parse stdout |
| 1 | Health check failed | Run cass index --full |
| 2 | Usage error | Fix syntax (hint provided) |
| 3 | Index/DB missing | Run cass index --full (retryable: true) |
| 4 | I/O failure or unsafe operation refused (not a network code) | Branch on err.kind: fix path/permissions/space for io/output-not-writable; follow the hint for refused-unsafe |
| 5 | Data corruption, or maintenance required | Inspect cass health --json / cass status --json / cass doctor --json and follow recommended_action: usually rebuild derived assets (maintenance-required, checkpoint_incomplete start that rebuild themselves); only a canonical-archive failure needs repair or restore |
| 6 | Required input missing (password, resume command) | Supply the input (e.g. --password-stdin) and rerun |
| 7 | Lock/busy | Retry later |
| 8 | Partial result (sources sync only: some sources had path failures) |
Inspect per-path errors in the JSON output and retry the failed sources |
| 9 | Unknown error | Check retryable flag |
| 10 | Config / timeout | Depends on err.kind |
| 11 | Config validation | Fix config |
| 12 | Source / SSH | Check remote host |
| 13 | Mapping / not-found | Depends on err.kind |
| 14 | I/O / mapping | Retry or inspect path |
| 15 | Semantic / embedder unavailable | Install model or --mode lexical |
| 20-21 | Model acquisition | Check err.kind, err.hint |
| 22 | I/O during model handling | Retry |
| 23 | Model download | Retry or use --from-file |
| 24 | I/O during model verify/install | Retry |
| 70 | cass index stalled and aborted (kind index-stalled envelope on stderr) |
Inspect cass status --json, then rerun cass index |
| 130 | Interrupted (SIGINT) | Rerun; cass sources setup --resume continues an interrupted setup |
Search/pack timeouts are not exit 8: on expiry search and pack exit 0 with {"hits": [], "budget": {"timed_out": true, "skipped_sections": [...], "recommended_next_probe": "", ...}}, and --robot-format sessions instead fails with exit 10, kind timeout. Explicit --mode semantic is the other exception: when the remaining budget cannot admit semantic setup or dispatch, search fails with exit 10, kind timeout, retryable: true, and a semantic_budget checkpoint=... message, rather than returning an empty or lexical result. Hybrid (explicit or default) instead falls back to lexical and reports semantic_budget_limited.
Codes ≥ 10 are domain-specific and the numeric value alone is ambiguous (e.g. code 10 maps to either config or timeout kinds depending on context). Agents should branch on err.kind from the JSON error envelope — not on the numeric code — when handling codes ≥ 10. See the Error Handling section above for the canonical kind list.
The retryable field tells agents whether a retry might succeed (e.g., transient I/O) vs. guaranteed failure (e.g., invalid path). A lexical query the engine refuses with posting cursor invariant failed (kind search, exit 9) is retryable: false: the same query fails the same way on the same index generation. The hint names the remedy, cass index --full --force-rebuild. Date-filtered searches over an index segment that holds deleted rows triggered it before frankensearch-quill 0.3.2 (GH #499).
Session Analysis Commands
Beyond search, cass provides commands for deep-diving into specific sessions:
# Discover the current session for this workspace
cass sessions --current --json

# List recent sessions for a specific project
cass sessions --workspace /path/to/project --json --limit 5

# Export full conversation to shareable format
cass export /path/to/session.jsonl --format markdown -o conversation.md
cass export /path/to/session.jsonl --format json --include-tools

# Export as self-contained HTML with encryption (recommended for sharing)
cass export-html /path/to/session.jsonl                     # To Downloads folder
printf '%s\n' "pwd" | cass export-html session.jsonl --encrypt --password-stdin
cass export-html session.jsonl --open --json                # Open in browser, JSON output

# Common agent flow: find current session, then export it
cass export-html "$(cass sessions --current --json | jq -r '.sessions[0].path')" --json

# Expand context around a specific line (from search result)
cass expand /path/to/session.jsonl -n 42 -C 5 --json
# → Shows 5 messages before and after line 42

# Activity timeline: when were agents active?
cass timeline --today --json --group-by hour
cass timeline --since 7d --agent claude --json
# → Grouped activity counts, useful for understanding work patterns
Aggregation & Analytics
Aggregate search results server-side to get counts and distributions without transferring full result data:
# Count results by agent
cass search "error" --robot --aggregate agent
# → { "aggregations": { "agent": { "buckets": [{"key": "claude_code", "count": 45}, ...] } } }

# Multi-field aggregation
cass search "bug" --robot --aggregate agent,workspace,date

# Combine with filters
cass search "TODO" --agent claude --robot --aggregate workspace
Aggregation Fields:
| Field | Description |
|---|---|
agent |
Group by agent type (claude_code, codex, cursor, etc.) |
workspace |
Group by workspace/project path |
date |
Group by date (YYYY-MM-DD) |
match_type |
Group by match type (exact, prefix, suffix, substring, wildcard, implicit_wildcard); one search has one type, so this shows a single bucket unless the wildcard fallback replaced the hits |
Response Format:
{
  "aggregations": {
    "agent": {
      "buckets": [
        {"key": "claude_code", "count": 120},
        {"key": "codex", "count": 85}
      ],
      "other_count": 15
    }
  }
}
Top 10 buckets are returned per field, with other_count for remaining items.
Bounded incident mining
Mine recurrent CASS operational incidents from the canonical archive without dumping raw session text:
cass analytics incidents --limit 10 --json

# Tighten the bounded scan for automation or a very large archive
cass analytics incidents --max-sessions 500 --max-messages 50000 \
  --max-bytes 67108864 --budget-ms 5000 --json
The response ranks top_sessions[] by hit count and category breadth and keeps
the exact conversation_id, agent, host, source_id, source_path,
live/archive state, dominant categories, and a structured cass view argv.
That argv carries the effective --db path plus --conversation-id, so it
opens the exact ranked archive row even when multiple sessions share a source
path or the report used a non-default database.
total_sessions, total_hits, and top_sessions_truncated distinguish the
bounded ranked result from the totals observed inside the scan scope.
discovery.partial and stop_reason explicitly distinguish a bounded partial
scan from a complete scan. Counts are scoped to scanned candidates whenever the
scan is partial. --budget-ms is a hard wall-clock result guard around the
independently row-bounded read-only worker. If it expires before a verified
result arrives, count_scope="no_verified_results_hard_timeout" returns an
empty partial report instead of overstating in-flight observations. Candidate
discovery is descending archive-row keyset paging;
--max-sessions bounds that newest-row window before dimensional filters, so a
selective filter can truthfully return a partial empty result instead of scanning
an unbounded archive. Individual messages are inspected through a bounded 4,096-char
fragment; an oversized message returns message-fragment-capped rather than
claiming a complete corpus scan. Raw prompt/tool content is always suppressed; evidence carries
only BLAKE3 fingerprints and basename-redacted paths. The actionable
source_path remains visible solely so the returned view command works.
Chained Search (Pipeline Mode)
Chain multiple searches together by piping session paths from one search to another:
# Find sessions mentioning "auth", then search within those for "token"
cass search "authentication" --robot-format sessions | \
  cass search "refresh token" --sessions-from - --robot

# Build a filtered corpus from today's work
cass search --today --robot-format sessions > today_sessions.txt
cass search "bug fix" --sessions-from today_sessions.txt --robot
How It Works:
- First search with
--robot-format sessionsoutputs one session path per line - Second search with
--sessions-fromrestricts search to those sessions - Use
-to read from stdin for true piping
Use Cases:
- Drill-down: Broad search → narrow within results
- Cross-reference: Find sessions with term A, then find term B within them
- Corpus building: Save session lists for repeated searches
Match Highlighting
Snippets always mark the terms the search engine matched with **bold**, in human-readable output and in robot/JSON output alike. The --highlight flag also marks the query terms' remaining literal occurrences and leaves already-marked text alone, so no term gets two pairs of marks. Only the snippet field is marked; content stays verbatim:
cass search "authentication error" --robot --highlight
# "snippet": "... **authentication** failed with **error** ..."
Highlighting is query-aware: quoted phrases like "auth error" highlight as a unit; individual terms highlight separately.
Pagination & Cursors
For large result sets, use cursor-based pagination:
# First page
cass search "TODO" --robot --robot-meta --limit 20
# → { "hits": [...], "_meta": { "next_cursor": "eyJ..." } }

# Next page
cass search "TODO" --robot --robot-meta --limit 20 --cursor "eyJ..."
A cursor is base64 JSON {"offset": N, "limit": M}: a plain page position, not a snapshot. Any index change between pages (a new session indexed, a rebuild, a forget) shifts the ranking, so the next page can skip or repeat hits. Page quickly, or fix the window with --until when you need stable pages.
Match Counts: Exact or Lower Bound
total_matches answers "how many messages match?", but it is exact only when
cass can afford to count. Every search fetches one hit beyond --limit to learn
whether another page exists. When the page is full and the index is larger than
CASS_SEARCH_EXACT_TOTAL_COUNT_MAX_DOCS documents, cass skips the full count
and reports that limit + 1 as a lower bound. Below the threshold it counts
every match.
| Build | Threshold | stale lock with --limit 10 on a 1,034,219-document index |
|---|---|---|
| v0.9.0 and earlier | 50,000 documents | total_matches: 11 |
| Current (unreleased) | 5,000,000 documents | total_matches: 11915 |
--robot-meta says which kind of number you got:
cass search "stale lock" --robot --robot-meta --limit 10 \
  | jq '{total_matches, precision: ._meta.cursor_manifest.count_precision, why: ._meta.cursor_manifest.count_reason}'
# → {"total_matches": 11915, "precision": "exact", "why": "total_matches is exact; no extra recount was needed"}
# A lower bound reads "precision": "lower_bound".
Why the threshold moved. The 50,000 cap dates from the Tantivy engine,
where counting a common term over millions of documents could dominate the
query. The Quill engine counts cheaply. Paired runs on that 1,034,219-document
archive, capped against exact (--limit 10, read-only, CPU time):
| Query | Exact total | Extra CPU for the exact count |
|---|---|---|
stale lock |
11,915 | ~0.00-0.04 s |
cargo build |
24,944 | ~0.01-0.03 s |
the |
439,461 | ~0.03-0.05 s |
AGENTS.md |
867,087 | ~0.06-0.11 s |
Each search cost about 0.8 s of CPU either way. The capped answer, meanwhile,
was wrong by up to five orders of magnitude, and agents read total_matches as
a count. The default now covers five times that archive; set
CASS_SEARCH_EXACT_TOTAL_COUNT_MAX_DOCS=0 to never count exactly, or raise it
for a larger archive.
Aggregations have their own window. --aggregate buckets are computed over
the top max(1000, limit + offset) hits, so bucket counts on a large archive
describe the best-ranked thousand matches, not the whole corpus. Use an exact
total_matches for "how many", and aggregations for "how are the top hits
distributed".
Request Correlation
For debugging and logging, attach a request ID:
cass search "bug" --robot --request-id "req-12345"
# → { "request_id": "req-12345", "hits": [...], ... }
#   (top level always; also under _meta.request_id with --robot-meta)
Idempotent Operations
For safe retries (e.g., in CI pipelines or flaky networks):
cass index --full --idempotency-key "build-$(date +%Y%m%d)"
# If same key + params were used in last 24h, returns cached result
Query Analysis
Debug why a search returned unexpected results:
cass search "auth*" --robot --explain
# → Adds "explanation": the sanitized query, flat lists of its terms, phrases and
#   operators (not a tree), the query type and index strategy, a low/medium/high cost
#   class, a filter summary and warnings. Wildcards are reported, not expanded.

cass search "auth error" --robot --dry-run
# → Validates query syntax without executing
Traceability
For debugging agent pipelines:
cass search "error" --robot --trace-file /tmp/cass-trace.json
# Appends execution span with timing, exit code, and command details

cass index --full --json --robot-trace-ingest 2>/tmp/cass-ingest-trace.jsonl
# Streams one NDJSON record per ingest batch with wall_ms, batch_msgs,
# inserted_messages, and duplicate-lookup counters for perf bisects
Search Flags Reference
| Flag | Purpose |
|---|---|
--robot / --json |
JSON output (pretty-printed) |
--robot-format jsonl|compact |
Streaming or single-line JSON |
--robot-meta |
Include _meta block (elapsed_ms, cache stats, index freshness, lexical_degrade_reason: "query_fuel_exhausted" or null, wildcard_fallback_skipped: why a sparse result got no automatic wildcard retry, and effective: the database, time window, filters, auto-corrections and query grouping the search actually used) |
--fields minimal|summary| |
Reduce payload size |
--max-content-length N |
Truncate content fields to N chars |
--max-tokens N |
Apply an approximate token budget to robot output |
--timeout N |
Timeout in milliseconds. On expiry search/pack still exit 0 and emit {"hits": [], "budget": {"timed_out": true, "skipped_sections": [...], "recommended_next_probe": "", ...}}; --robot-format sessions fails with exit 10, kind timeout |
--cursor |
Cursor-based pagination (from _meta.next_cursor) |
--request-id ID |
Echoed in response for correlation |
--aggregate agent,workspace,date |
Server-side aggregations |
--explain |
Include query analysis (parsed query, cost estimate) |
--dry-run |
Validate query without executing |
--no-maintenance |
Strict read-only search: never refresh, join, or spawn lexical maintenance, never auto-repair the archive while opening it, and never auto-spawn the daemon (conflicts with --refresh and --daemon) |
--source |
Filter by source: local, remote, all, or specific source ID |
--highlight |
Also mark query-term occurrences the engine left unmarked (snippets always mark matched terms with **) |
Index Flags Reference
| Flag | Purpose |
|---|---|
--idempotency-key KEY |
Safe retries: same key + params returns cached result (24h TTL) |
--json |
JSON output with stats |
--gc |
Reclaim merge-retired lexical segment files and exit: runs the engine's grace-period garbage sweep (a folded segment file is unlinked only once no published MANIFEST generation has referenced it for 300 s) and reports files/bytes reclaimed. Every incremental cass index performs the same sweep at open; doctor --json reports the reclaimable bytes under storage_pressure.full_rebuild_readiness (GH #453) |
When health --json or status --json reports index.status: "hollow", the
live Quill generation serves fewer than half the documents certified by its
completed rebuild checkpoint. index.live_documents reports the served count.
Run cass index to let its pre-scan repair rebuild from the canonical archive;
cass index --full also rescans the session sources. A missing count provides
no hollow-generation verdict.
Robot Documentation System
For machine-readable documentation, use cass robot-docs :
| Topic | Content |
|---|---|
commands |
Full command reference with all flags |
env |
Environment variables and defaults |
paths |
Data directory locations per platform |
guide |
Quick start guide for automation |
schemas |
JSON response schemas |
exit-codes |
Exit code meanings and retry guidance |
examples |
Copy-paste usage examples |
contracts |
API contract version and stability |
sources |
Remote sources configuration guide |
# Get documentation programmatically
cass robot-docs guide
cass robot-docs schemas
cass robot-docs exit-codes

# Machine-first help (wide output, no TUI assumptions)
cass --robot-help
API Contract & Versioning
cass maintains a stable API contract for automation:
cass api-version --json
# → { "crate_version": "", "build_commit": "", "api_version": 1, "contract_version": "1" }

cass introspect --json
# → Full schema: all commands, arguments, response types
Contract Version: Currently 1. Increments only on breaking changes.
Guaranteed Stable:
- Exit codes and their meanings
- JSON response structure for
--robotoutput - Flag names and behaviors
_metablock format
Ready-to-paste blurb for AGENTS.md / CLAUDE.md
🔎 cass — Search All Your Agent History

 What: cass indexes conversations from Claude Code, Codex, Cursor, Gemini, Aider, ChatGPT, and more into a unified, searchable index. Before solving a problem from scratch, check if any agent already solved something similar.

 ⚠️ NEVER run bare cass — it launches an interactive TUI. Always use --robot or --json.

 Quick Start

 # One-shot agent triage (read next_command when present)
 cass triage --json

 # Search across all agent histories
 cass search "authentication error" --robot --limit 5

 # Build a cited handoff pack from search evidence
 cass pack "authentication error root cause" --robot --max-tokens 12000 --limit 40

 # Tight handoff budget with freshness and privacy metadata
 cass pack "authentication error root cause" --robot --max-tokens 4000 --max-evidence 8 --fields summary

 # View a specific result (from search output)
 cass view /path/to/session.jsonl -n 42 --json

 # Expand context around a line
 cass expand /path/to/session.jsonl -n 42 -C 3 --json

 # Learn the full API
 cass capabilities --json # Static agent self-description
 cass robot-docs guide # LLM-optimized docs

 Why Use It

 - Cross-agent knowledge: Find solutions from Codex when using Claude, or vice versa
 - Forgiving syntax: Typos and wrong flags are auto-corrected with teaching notes
 - Token-efficient: --fields minimal returns only essential data; pack budgets cite only selected evidence
 - Copy-safe handoffs: pack warnings include freshness and privacy/redaction status

 Key Flags

 | Flag | Purpose |
 |------------------|--------------------------------------------------------|
 | --robot / --json | Machine-readable JSON output (required!) |
 | --fields minimal | Reduce payload: source_path, line_number, agent, source_id, conversation_id |
 | pack --max-tokens N | Budget a cited handoff pack |
 | --limit N | Cap result count |
 | --agent NAME | Filter to specific agent (claude, codex, cursor, etc.) |
 | --days N | Limit to recent N days |

 stdout = data only, stderr = diagnostics. Exit 0 = success.
🔤 Query Language Reference
cass supports a rich query syntax designed for both humans and machines.
Basic Queries
| Query | Matches |
|---|---|
error |
Messages containing "error" (case-insensitive) |
python error |
Messages containing both "python" AND "error" |
"authentication failed" |
Exact phrase match |
auth fail |
Both terms, in any order |
Boolean Operators
Combine terms with explicit operators for complex queries:
| Operator | Example | Meaning |
|---|---|---|
AND |
python AND error |
Both terms required (default) |
OR |
error OR warning |
Either term matches |
NOT |
error NOT test |
First term, excluding second |
- |
error -test |
Shorthand for NOT |
Operator Precedence: NOT binds tightest, then AND (explicit, &&, or implied between words), then OR (OR, ||). Parentheses group, in the TUI and robot mode alike: a OR b c means a OR (b AND c), while (a OR b) c needs the parentheses. A ( groups only at the start of a word, so code such as foo(bar) stays one term. NOT NOT x is x. Unbalanced parentheses are recovered rather than rejected. The SQLite fallback lanes, used while no lexical index is available, apply the same grammar.
# Complex boolean query
cass search "authentication AND (error OR failure) NOT test" --robot

# Exclude test files
cass search "bug fix -test -spec" --robot

# Either error type
cass search "TypeError OR ValueError" --robot
Phrase Queries
Wrap terms in double quotes for exact phrase matching:
| Query | Matches |
|---|---|
"file not found" |
Exact sequence "file not found" |
"cannot read property" |
Exact JavaScript error message |
"def test_" |
Function definitions starting with test_ |
Phrases match their words adjacent and in order (no slop). Useful for error messages, code patterns, and specific terminology.
Wildcard Patterns
| Pattern | Type | Matches | Performance |
|---|---|---|---|
auth* |
Prefix | "auth", "authentication", "authorize" | Fast (uses edge n-grams) |
*tion |
Suffix | "authentication", "function", "exception" | Slower (term-dictionary expansion) |
*config* |
Substring | "reconfigure", "config.json", "misconfigured" | Slowest (term-dictionary expansion) |
test_* |
Prefix on test |
anything whose token starts with "test" | Fast |
Tip: Prefix wildcards (foo*) use edge n-grams computed at index time: prefixes of 2–20 characters of every alphanumeric word, taken from titles and from the first 4 KiB of each message. Suffix and substring wildcards expand over the index's term dictionary, at most 16,384 terms per pattern; a pattern matching more terms fails rather than scanning. The tokenizer splits on anything that is not a letter or digit: test_* is a prefix match on test, c++ searches for c, and foo.bar means foo AND bar anywhere in the message, not the literal string. Phrases ("...") match adjacent words in order (slop 0).
Query Modifiers
# Field-specific search (in robot mode)
cass search "error" --agent claude --workspace /path/to/project

# Time-bounded search
cass search "bug" --since 2024-01-01 --until 2024-01-31
cass search "bug" --today
cass search "bug" --days 7

# Combined filters
cass search "authentication" --agent codex --workspace myproject --week
Flexible Time Input
cass accepts a wide variety of time/date formats for filtering:
| Format | Examples | Description |
|---|---|---|
| Relative | -7d, -24h, -30m, -1w |
Days, hours, minutes, weeks ago |
| Keywords | now, today, yesterday |
Named reference points |
| ISO 8601 | 2024-11-25, 2024-11-25T14:30:00Z |
Standard datetime |
| US Dates | 11/25/2024, 11-25-2024 |
Month/Day/Year |
| Unix Timestamp | 1732579200 |
Seconds since epoch |
| Unix Millis | 1732579200000 |
Milliseconds (auto-detected) |
Intelligent Heuristics:
- Numbers of 100,000,000,000 (10^11) or more are milliseconds; smaller numbers are seconds
- Years are written in full (
2024, not24) - A value that names a whole day (a date without a time,
today,yesterday) starts at local midnight as--sinceand runs through the day's last millisecond as--until, so--until 2024-01-31includes January 31 - For
searchandpack, a--since/--untilvalue that cannot be parsed, or a--sincelater than--until, is a usage error (exit 2, kindusage); it is never silently ignored
# All equivalent for "last week"
cass search "bug" --since -7d
cass search "bug" --since "-1w"
cass search "bug" --days 7

# Date range
cass search "feature" --since 2024-01-01 --until 2024-01-31

# Mix formats
cass search "error" --since yesterday --until now
Match Types
Search results include a match_type indicator. It describes the query, not each hit: every hit of a search carries the type of the least precise pattern in the query (e.g. auth* *tion stamps suffix on all hits).
| Type | Meaning | Match Quality order |
|---|---|---|
exact |
No wildcards: exact terms (and edge n-gram prefixes) | 1 |
prefix |
Trailing wildcard (auth*) |
2 |
suffix |
Leading wildcard (*tion) |
3 |
substring |
Both sides (*config*) |
4 |
wildcard |
Inner wildcard (f*o) |
5 |
implicit_wildcard |
Automatic wildcard fallback on a sparse exact search | 6 |
Relevance scores carry no boost for the match type; only the TUI's Match Quality ranking mode (F12) orders by it.
Auto-Fuzzy Fallback
When an exact query's first page returns fewer than 3 results (or fewer than a smaller --limit), cass retries with wildcard expansion:
auth→*auth*- It runs only on indexes with at most 10,000 documents (
CASS_AUTOMATIC_WILDCARD_FALLBACK_MAX_DOCS;0disables it), so on a typical real archive it does not run. - It skips queries that already use wildcards, boolean operators or phrases, and zero-hit queries containing a token longer than 16 characters.
- The wildcard results replace the exact ones only when they find more hits; robot mode then reports
_meta.wildcard_fallback: true. When a sparse result did not get the retry,_meta.wildcard_fallback_skippedsays why:index_over_automatic_limit(the index is over the document cap),automatic_retry_disabled(the cap is0) orlong_query_term; add explicit wildcards to run it anyway - TUI shows a "fuzzy" indicator in the status bar
⌨️ Complete Keyboard Reference
Global Keys
| Key | Action |
|---|---|
Ctrl+C |
Force quit |
Esc / F10 |
Unwind: close the open modal or surface, otherwise quit |
F1 / Alt+? |
Toggle help screen |
F2 / Alt+T |
Next theme (cycles all 19 presets) |
Shift+F2 / Alt+Shift+T |
Previous theme |
Ctrl+B |
Toggle border style (rounded/square) |
Ctrl+P / Alt+P |
Open the command palette |
Ctrl+S |
Toggle the stats bar |
Ctrl+Shift+S |
Open the sources management surface |
Alt+A |
Open the analytics dashboard |
Alt+M |
Toggle macro recording (replay with cass tui --play-macro FILE) |
Ctrl+Shift+I |
Toggle the inspector overlay |
Ctrl+Shift+R |
Force re-index |
Ctrl+Shift+Del |
Reset all TUI state |
Ctrl+Z / Ctrl+Shift+Z |
Undo / redo |
Launch-time flags: cass tui --refresh (alias --catch-up) runs an incremental index pass before opening; --record-macro FILE / --play-macro FILE record and replay input events.
Search Bar (Query Input)
| Key | Action |
|---|---|
| Type | Live search as you type; plain characters (including ?, y, o, c, 1-9, -, =) go into the query |
Enter |
Open the selected hit; with no selected hit, submit the query (if the query is empty, edit the last filter chip) |
Backspace |
Delete character; if the query is empty, remove the last filter chip |
Left/Right, Ctrl+Left/Ctrl+Right |
Move the cursor by character / by word |
Home/End |
Jump the cursor to the start / end of the query |
Ctrl+L |
Clear the query |
Ctrl+U / Ctrl+K / Ctrl+W |
Kill to line start / to line end / previous word |
Ctrl+R |
Cycle through query history |
Ctrl+N / Ctrl+Shift+N |
Next / previous query-history entry |
Ctrl+F |
Toggle wildcard fallback |
Ctrl+Shift+Y |
Copy the query |
Navigation
| Key | Action |
|---|---|
Up/Down |
Move selection in results list |
PageUp/PageDown |
Scroll by page |
Tab / Shift+Tab |
Toggle focus between results and detail pane / move focus left |
Alt+h/j/k/l |
Vim-style directional focus (left/down/up/right) |
Alt+1..Alt+9 |
Switch to pane N |
Alt+- / Alt+= |
Shrink / grow the results pane |
Alt+D |
Hide / show the detail pane |
Alt+[ / Alt+] |
Timeline jump backward / forward |
Filtering
| Key | Action |
|---|---|
F3 / Alt+G |
Open agent filter palette |
Shift+F3 / Alt+Shift+G |
Clear the agent filter |
F4 / Alt+W |
Open workspace filter palette |
Shift+F4 / Alt+Shift+W / Ctrl+Del |
Clear all active filters |
F5 |
Set "from" time filter |
F6 |
Set "to" time filter |
Shift+F5 |
Cycle time presets: 24h → 7d → 30d → all |
F11 / Shift+F11 |
Cycle the source filter / open the source filter menu |
Alt+/ |
Open the pane filter |
Modes & Display
| Key | Action |
|---|---|
F7 / Alt+C |
Cycle context window size: S → M → L → XL |
Ctrl+Space |
Momentary "peek" to XL context |
F9 |
Toggle match mode: standard (default) ↔ prefix, where every bare word of 2+ characters also matches as a prefix (auth → auth*; phrases, operators and wildcards are left as typed) |
F12 / Alt+R |
Cycle ranking: recent → balanced → relevance → quality → newest → oldest |
Alt+F |
Cycle result grouping: agent → conversation → workspace → flat |
Alt+S |
Cycle search mode (lexical / semantic / hybrid). Without an installed model (or vector index) the status line says results stay lexical and names the command: cass models install (offline --from-file ) or cass index --semantic; nothing downloads on its own |
Ctrl+D |
Cycle density: Compact → Cozy → Spacious |
Ctrl+1..Ctrl+9 |
Save the current view to slot N |
Shift+1..Shift+9 |
Load the view from slot N |
For one chronological list across agents, select flat grouping with Alt+F
and newest ranking with F12. Grouping is also available in the command
palette and is preserved with ranking and filters in saved views.
Selection & Actions
| Key | Action |
|---|---|
Enter / Ctrl+M |
Open selected result in the detail modal (Messages tab by default) |
Ctrl+X |
Toggle selection on current result |
Ctrl+A |
Select/deselect all visible results |
Alt+B |
Open bulk actions menu (when items selected) |
Ctrl+Enter |
Add to multi-open queue |
Ctrl+O |
Open all queued items in editor |
F8 / Alt+O |
Open selected hit in $EDITOR |
Alt+V |
View raw |
Alt+Shift+J |
Toggle JSON view |
Ctrl+Y |
Copy path |
Alt+Y |
Copy snippet |
Ctrl+Shift+C |
Copy content |
Alt+E |
Bookmark the selected hit (cass bookmarks list shows bookmarks) |
Ctrl+E |
Open the export modal |
Ctrl+Shift+E |
Export Markdown immediately |
Alt+U / Alt+N / Alt+I |
Update banner: upgrade now / show release notes / skip this version |
Detail Pane
These apply while the detail modal is open:
| Key | Action |
|---|---|
Esc |
Close the detail modal |
Tab |
Cycle detail tabs |
/ (or Ctrl+F, Alt+/) |
Start find-in-detail; type to search, Enter advances to the next match |
n / N |
Next / previous contextual search hit within this session |
Enter (Messages tab) |
Next contextual search hit |
j / k, Up/Down |
Scroll |
g / G, Home/End |
Scroll to top / bottom |
{ / } |
Jump to previous / next message |
[ / ] |
Jump to previous / next user message |
w |
Toggle line wrap |
e / c |
Expand / collapse all tool and system messages |
e, h (Export tab) |
Open the HTML export modal; m exports Markdown |
F7 |
Cycle context window size |
Ctrl+Space |
Momentary "peek" to XL context |
Detail Tabs
The detail pane has six tabs, cycled with Tab:
| Tab | Content | Best For |
|---|---|---|
| Messages | Full conversation with markdown rendering | Reading full context |
| Snippets | Keyword-extracted summaries | Quick scanning |
| Raw | Unformatted JSON/text | Debugging, copying exact content |
| Json | Syntax-highlighted, pretty-printed JSON (static; no collapsible tree) | Inspecting structured payloads |
| Analytics | Per-session token timeline, tool calls, message stats | Understanding one session |
| Export | Export actions and filename previews (HTML/Markdown) | Sharing a session |
Context Window Sizing
Control how much content shows in the detail preview. Cycle with F7:
| Size | Characters | Use Case |
|---|---|---|
| Small | ~200 | Quick scanning, narrow terminals |
| Medium | ~400 | Default balanced view |
| Large | ~800 | Reading longer passages |
| XLarge | ~1600 | Full context, code review |
Peek Mode (Ctrl+Space): Temporarily expand to XL context. Press again to restore previous size. Useful for quick deep-dives without changing your preferred default.
Mouse Support
- Click on result to select
- Click on filter chip to edit/remove
- Scroll in any pane
- Double-click to open result
Bulk Operations
Efficiently work with multiple search results at once:
Multi-Select Mode:
- Press
Ctrl+Xto toggle selection on current result (checkbox appears) - Navigate to other results and press
Ctrl+Xagain - Press
Ctrl+Ato select/deselect all visible results - Selected count shown in footer: "3 selected"
Bulk Actions Menu (Alt+B when items selected):
| Action | Description |
|---|---|
| Open All | Open all selected files in editor |
| Copy Paths | Copy all file paths to clipboard |
| Export | Export selected results to file |
| Clear Selection | Deselect all items |
Multi-Open Queue: For opening many files without navigating away:
- Press
Ctrl+Enterto add current result to queue - Continue searching and adding more results
- Press
Ctrl+Oto open all queued items - Confirmation prompt appears for 12+ items
Clipboard Operations:
Ctrl+Y- Copy the current item's pathAlt+Y- Copy the current item's snippetCtrl+Shift+C- Copy the current item's content- Bulk actions menu → Copy Paths for every selected item
📊 Ranking & Scoring Explained
The Six Ranking Modes
Cycle through modes with F12 (or Alt+R) in the TUI. The search engine returns hits in its own relevance order; the mode then re-orders the results the TUI has loaded (the first page of up to 250 hits, plus every further page you load), so the whole loaded list always follows one order. Ranking modes are TUI-only; robot search returns engine order.
-
Recent Heavy: Score =
relevance × 0.3 + recency × 0.7. Best for: "What was I working on?" -
Balanced (default): Score =
relevance × 0.5 + recency × 0.5. Best for general-purpose search. -
Relevance: Score =
relevance × 0.8 + recency × 0.2. Best for "find the best explanation of X". -
Match Quality: exact matches first, then prefix, suffix, subs