DAIL-SQL
DAIL-SQL is a highly effective and efficient approach for optimizing the utilization of LLM on Text-to-SQL. It has proven its superiority by achieving a remarkable score of 86.2% on the Spider leaderboard using GPT-4 during testing. Notably, it only requires approximately 1600 tokens per question in Spider-dev. In addition to this, we have achieved an even higher score of 86.6% on Spider-test through self-consistency voting of GPT-4.
Dawei Gao, Haibin Wang, Yaliang Li, Xiuyu Sun, Yichen Qian, Bolin Ding and Jingren Zhou. Text-to-SQL Empowered by Large Language Models: A Benchmark Evaluation. CoRR abs/2308.15363 (2023).
Paper link: arXiv
Overview
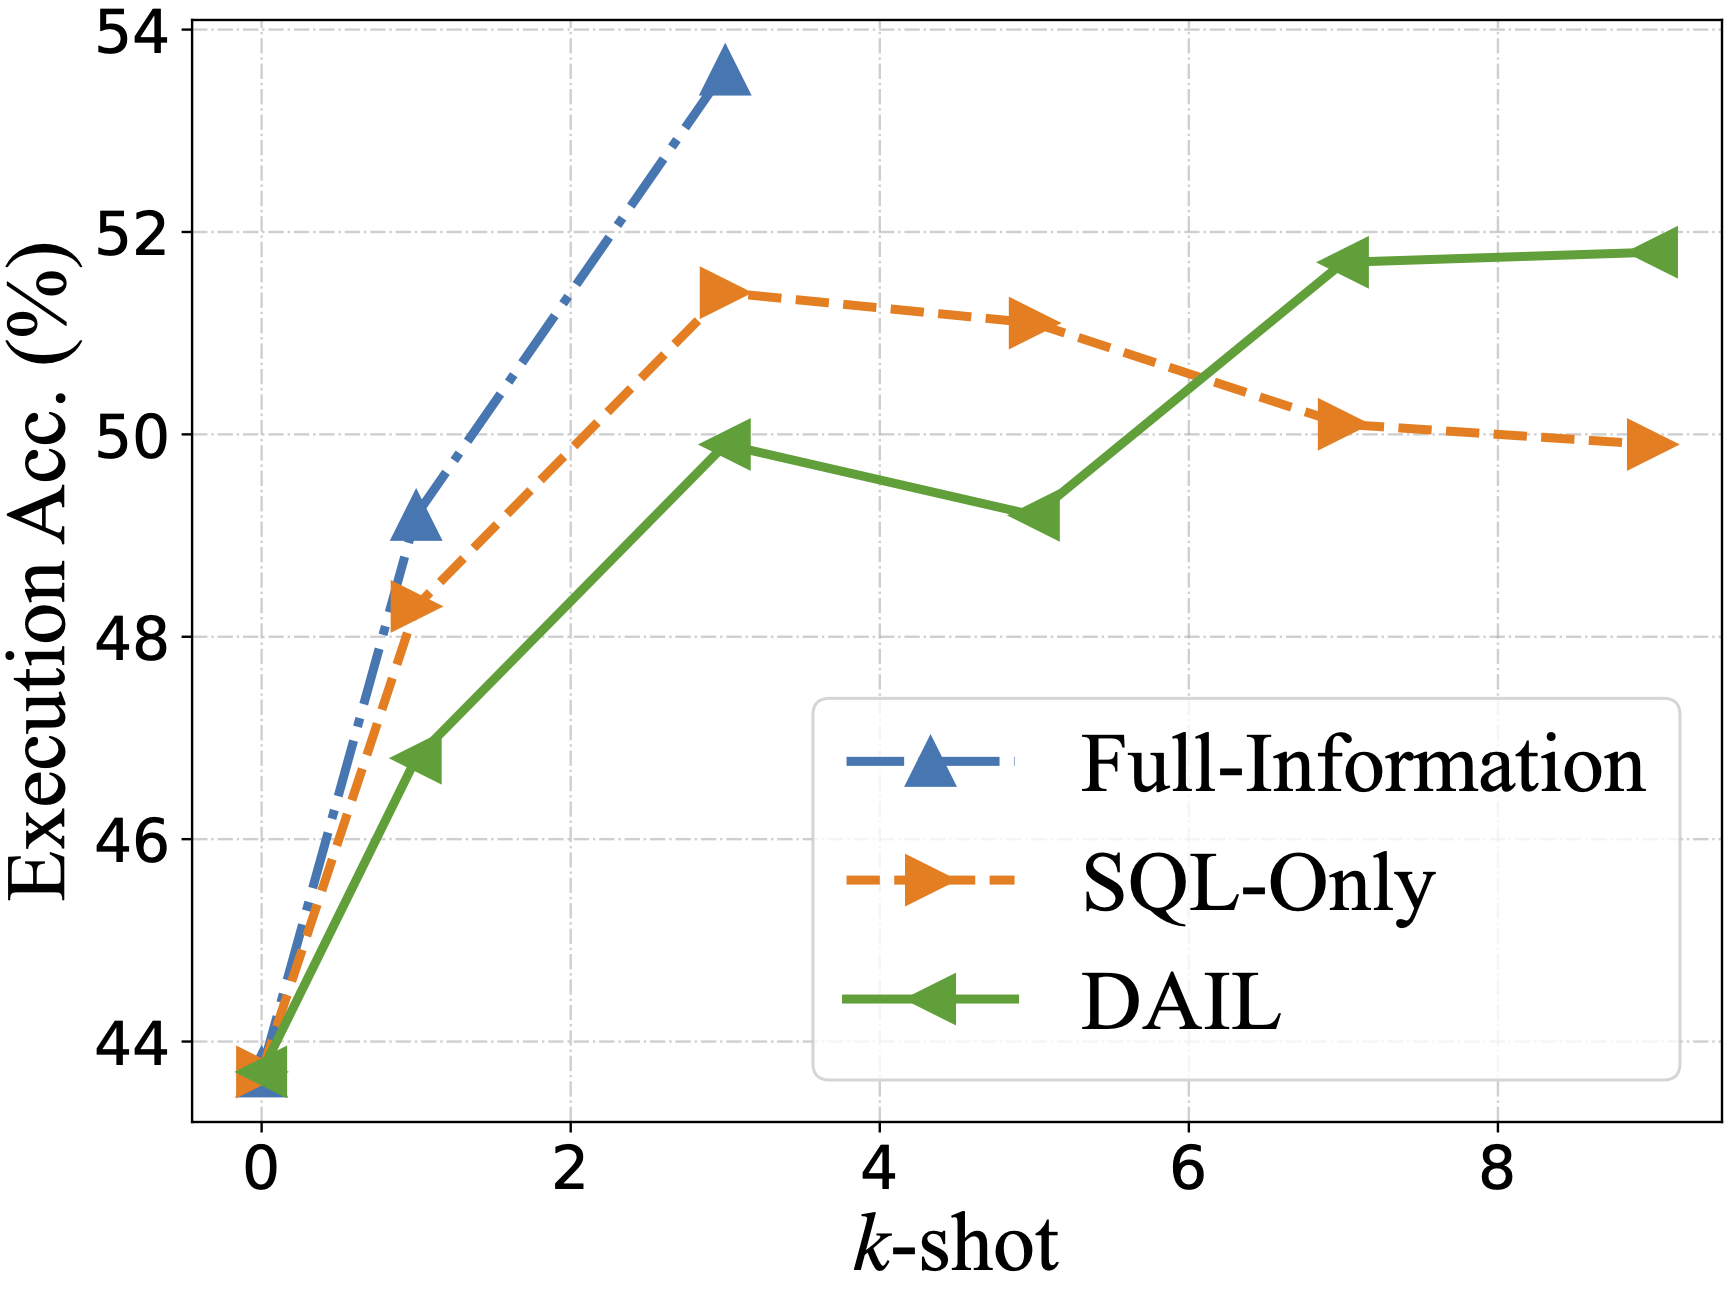
To provide a systematical and in-depth understanding of Text-to-SQL prompt engineering, we empirically evaluate several strategies from prior studies. First, we compare several typical question representations in zero-shot scenario with different LLMs, and identify their pros and cons. After that, we investigate example selection and organization strategies in few-shot scenario. For example selection, we compare different selection strategies and further verify the hypothesis that LLMs learn from the mappings between question and SQL skeleton. Regarding example organization, we explore the option of displaying full information, solely SQL queries or question-SQL pair.
Last but not least, our integrated solution, named DAIL-SQL, refreshes the Spider leaderboard with 86.6% execution accuracy, and wins the first place. Compared with previous solutions, DAIL-SQL encodes structure knowledge as SQL statements, selects examples based on their skeleton similarities and removes cross-domain knowledge from examples for token efficiency.
Environment Setup
To set up the environment, you should download the stanford-cornlp and unzip it to the folder ./third_party.
Next, you need to launch the coreNLP server:
apt install default-jre
apt install default-jdk
cd third_party/stanford-corenlp-full-2018-10-05
nohup java -mx4g -cp "*" edu.stanford.nlp.pipeline.StanfordCoreNLPServer &
cd ../../
In addition, set up the Python environment:
conda create -n DAIL-SQL python=3.8
conda activate DAIL-SQL
python -m pip install --upgrade pip
pip install -r requirements.txt
python nltk_downloader.py
Data Preparation
You need to download the Spider to the folder ./dataset/spider.
Run
Data Preprocess
python data_preprocess.py
Prompt Generation
Select examples with masked question similarity:
python generate_question.py \
--data_type spider \
--split test \
--tokenizer gpt-3.5-turbo \
--max_seq_len 4096 \
--prompt_repr SQL \
--k_shot 9 \
--example_type QA \
--selector_type  EUCDISQUESTIONMASK
Select examples considering both question similarity and query similarity:
python generate_question.py \
--data_type spider \
--split test \
--tokenizer gpt-3.5-turbo \
--max_seq_len 4096 \
--selector_type EUCDISMASKPRESKLSIMTHR \
--pre_test_result [your_pre_generated_queries_file] \
--prompt_repr SQL \
--k_shot 9 \
--example_type QA
Calling the LLM
Without voting:
python ask_llm.py \
--openai_api_key [your_openai_api_key]  \
--model gpt-4 \
--question [prompt_dir]
With self-consistency voting:
python ask_llm.py \
--openai_api_key [your_openai_api_key]  \
--model gpt-4 \
--question [prompt_dir] \
--n 5 \
--db_dir ./dataset/spider/database \
--temperature 1.0
Running Example
bash run_dail_sql_mini.sh [your_openai_api_key]
Experiments
In our works, we systematically study prompt engineering for LLM-based Text-to-SQL methods, including five question representations, two prompt components, four example selections, and three example organizations on four LLMs. The study sheds light on identifying suitable question representations and key points to leverage the in-context learning capacity of LLMs for Text-to-SQL task. We present our experimental results in the Spider train split. Here, we take Graphix as our preliminary model to pre-generate the SQL query for acquiring query similarity. Please refer to the Test Suites for evaluation metrics.
Question Representations
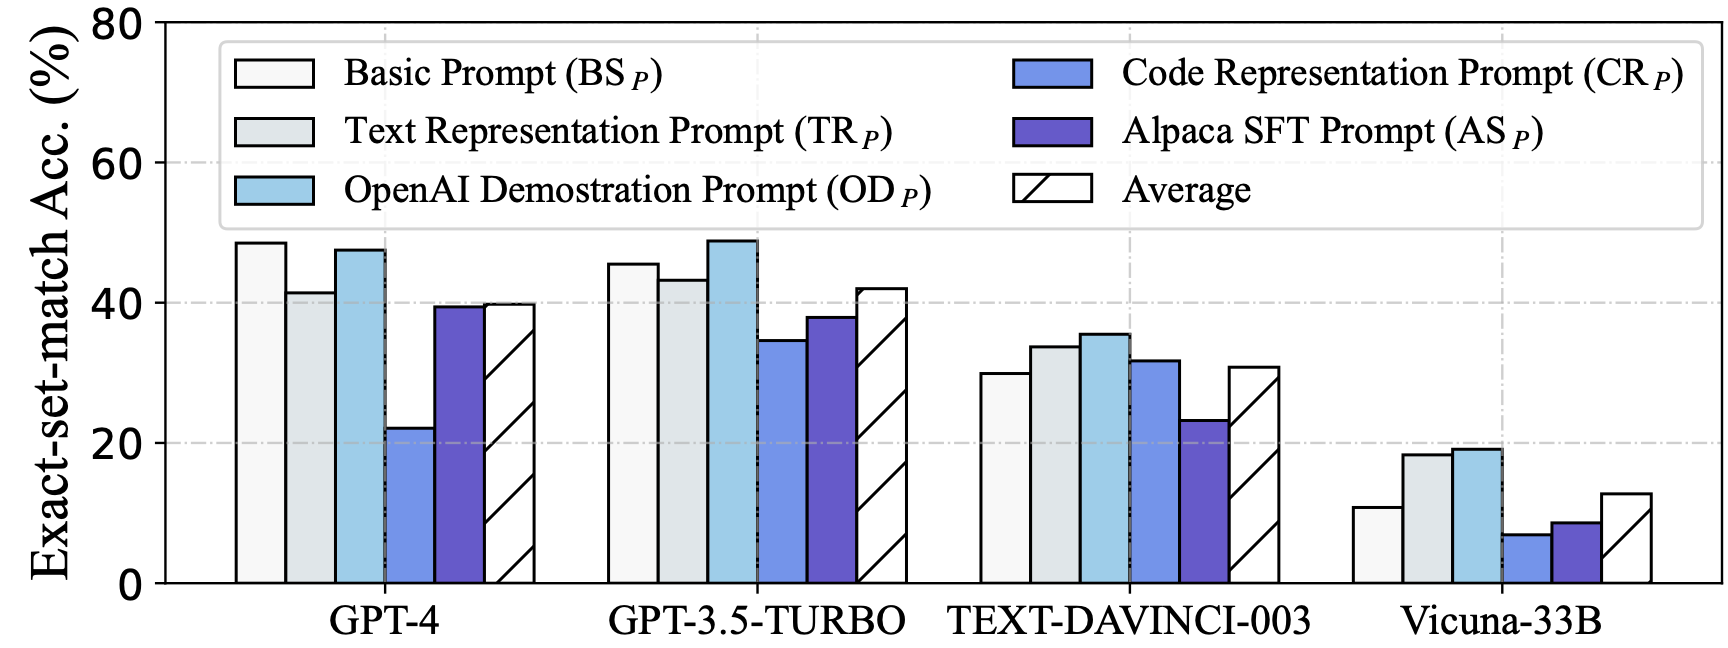
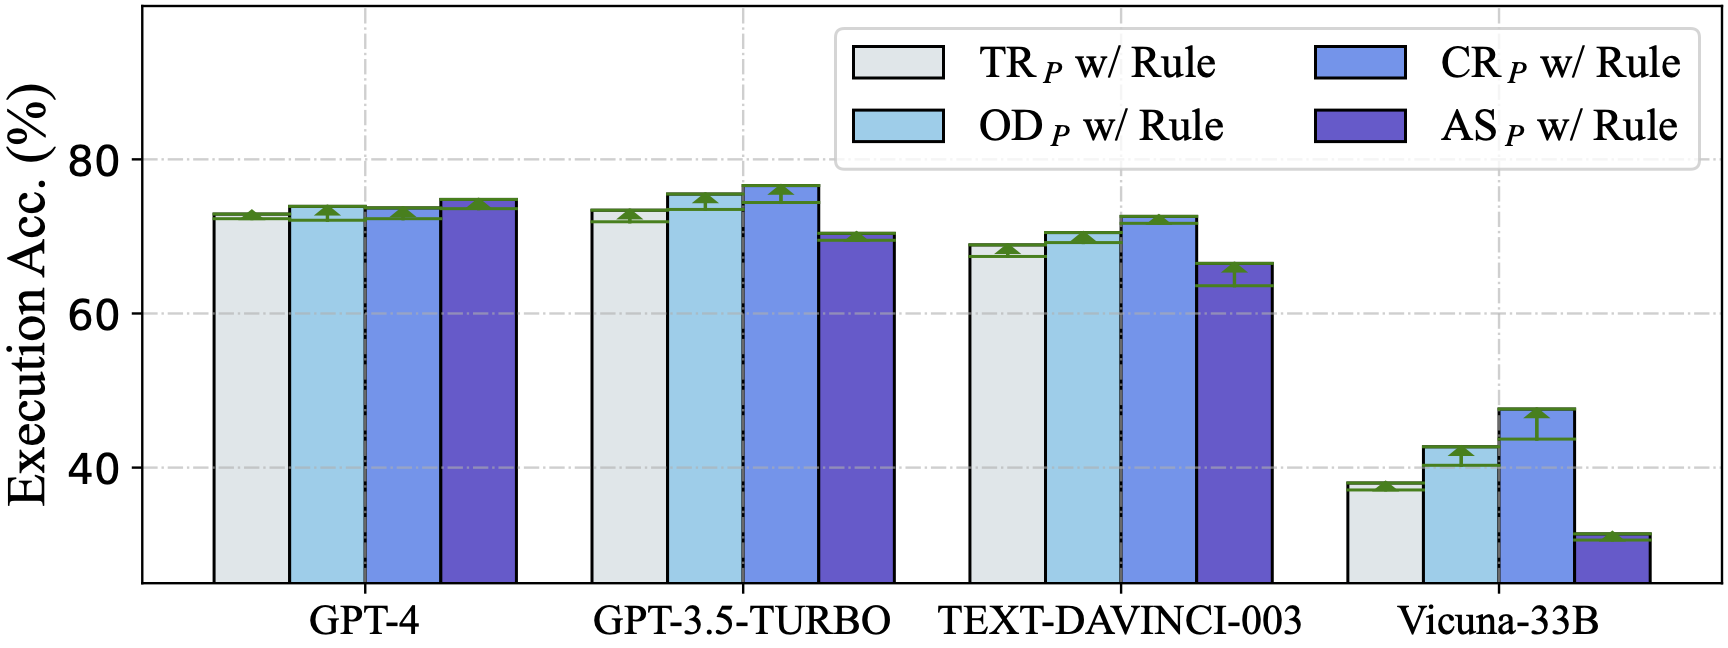
We evaluate five question representations summarized from other works under zero-shot scenario, employing four LLMs: GPT-4, GPT-3.5-TURBO, TEXT-DAVINCI-003, and Vicuna-33B. We find Code Representation Prompt and OpenAI Demostration Prompt are preferred.
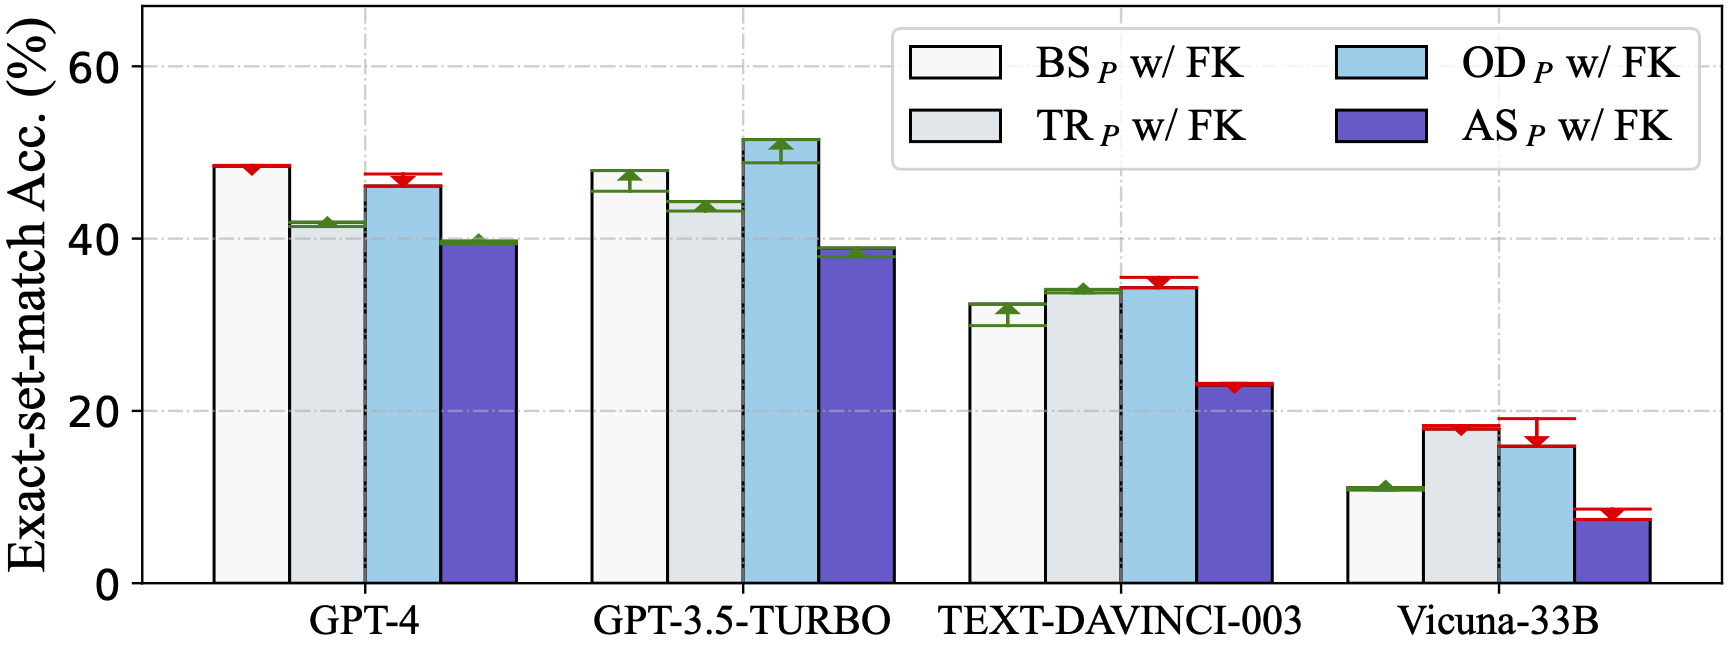
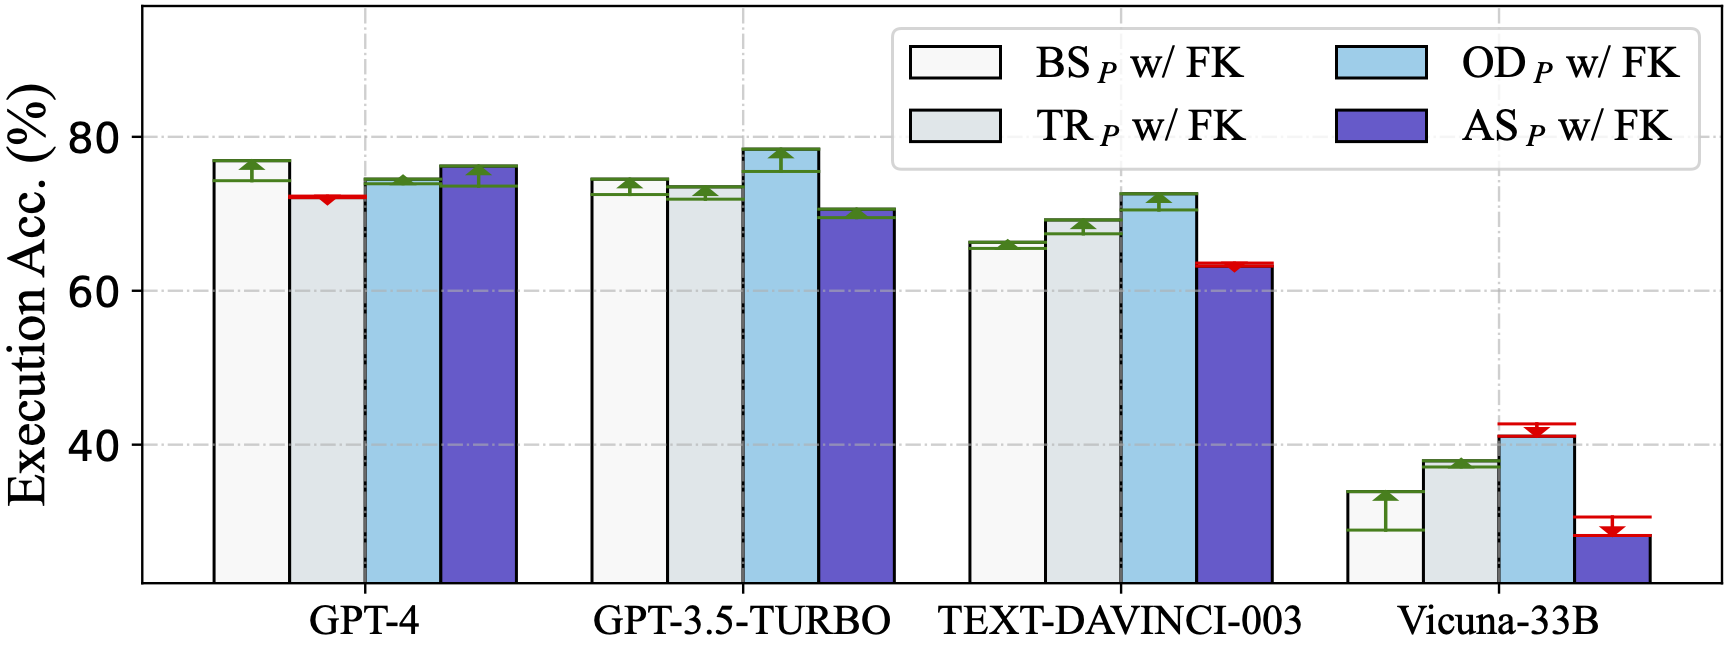
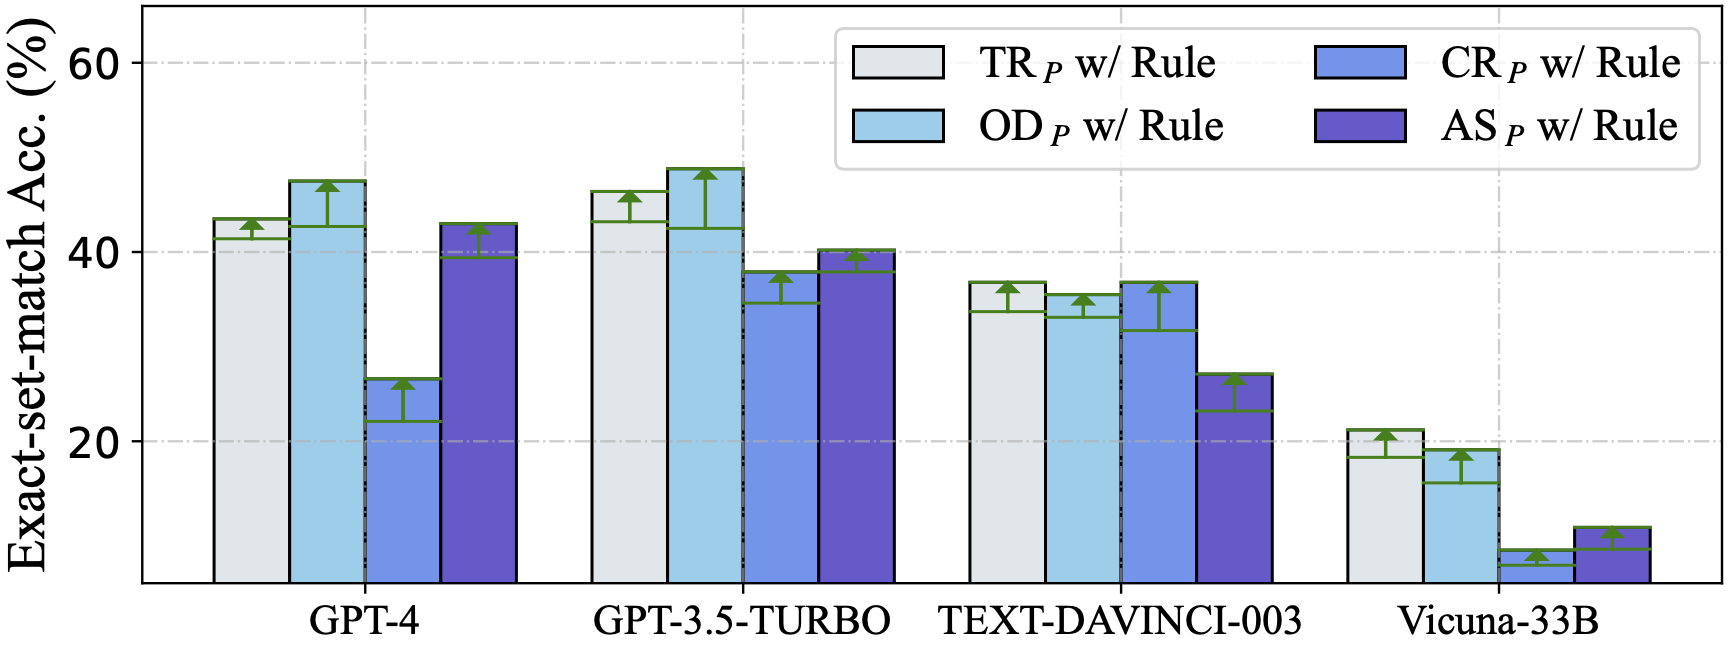
We also investigate the impact of foreign key and "with no explanation" rule implication. Both the foreign key and the "with no explanation" rule implication are beneficial for Text-to-SQL task.
Example Selections
We then study the effects of different example selections under few-shot scenario. We emphasize the importance to consider both question similarity and query similarity as DAIL-SQL does in example selection.
Few-shot
Selection
Question
Similarity
Query
Similarity
GPT-4
GPT-3.5-TURBO
TEXT-DAVINCI-003
Vicuna-33B
EM
EX
EM
EX
EM
EX
EM
EX
0-shot
22.1
72.3
34.6
74.4
31.7
71.7
6.9
43.7
1-shot
Random
0.23
0.47
41.7
77.4
45.9
73.9
38.2
70.6
14.4
47.9
Question Similarity Selection
0.39
0.65
53.3
78.8
51.9
74.3
44.1
72.3
16.5
48.5
Masked Question Similarity Selection
0.57
0.80
58.2
79.1
57.4
76.0
47.9
75.0
21.4
48.7
DAIL Selection
0.56
0.95
62.1
80.2
59.5
75.5
51.9
76.9
22.8
49.2
3-shot
Random
0.23
0.48
48.9
79.4
49.0
73.6
41.7
71.6
16.8
46.9
Question Similarity Selection
0.37
0.63
56.3
79.2
53.8
74.7
52.2
74.1
21.1
47.1
Masked Question Similarity Selection
0.54
0.78
66.1
81.5
61.1
77.3
59.7
77.0
27.7
52.3
DAIL Selection
0.53
0.94
69.1
81.7
63.9
77.8
64.4
79.5
30.7
53.6
5-shot
Random
0.23
0.48
51.6
79.5
52.9
75.7
49.0
72.1
Question Similarity Selection
0.36
0.61
58.2
79.9
55.9
75.1
54.8
73.2
Masked Question Similarity Selection
0.52
0.77
66.8
82.0
62.3
77.9
64.7
78.6
DAIL Selection
0.52
0.94
71.9
82.4
66.7
78.1
67.7
80.5
Example Organizations
Finally, we examine example organizations in DAIL-SQL, excluding the token-cost database schema in the examples and only presenting question and query pairs to LLMs. In our analysis, we contrast the DAIL-SQL organization with both Full-Information and SQL-Only organizations, finding that the DAIL organization is a highly effective and efficient approach for potent LLMs.
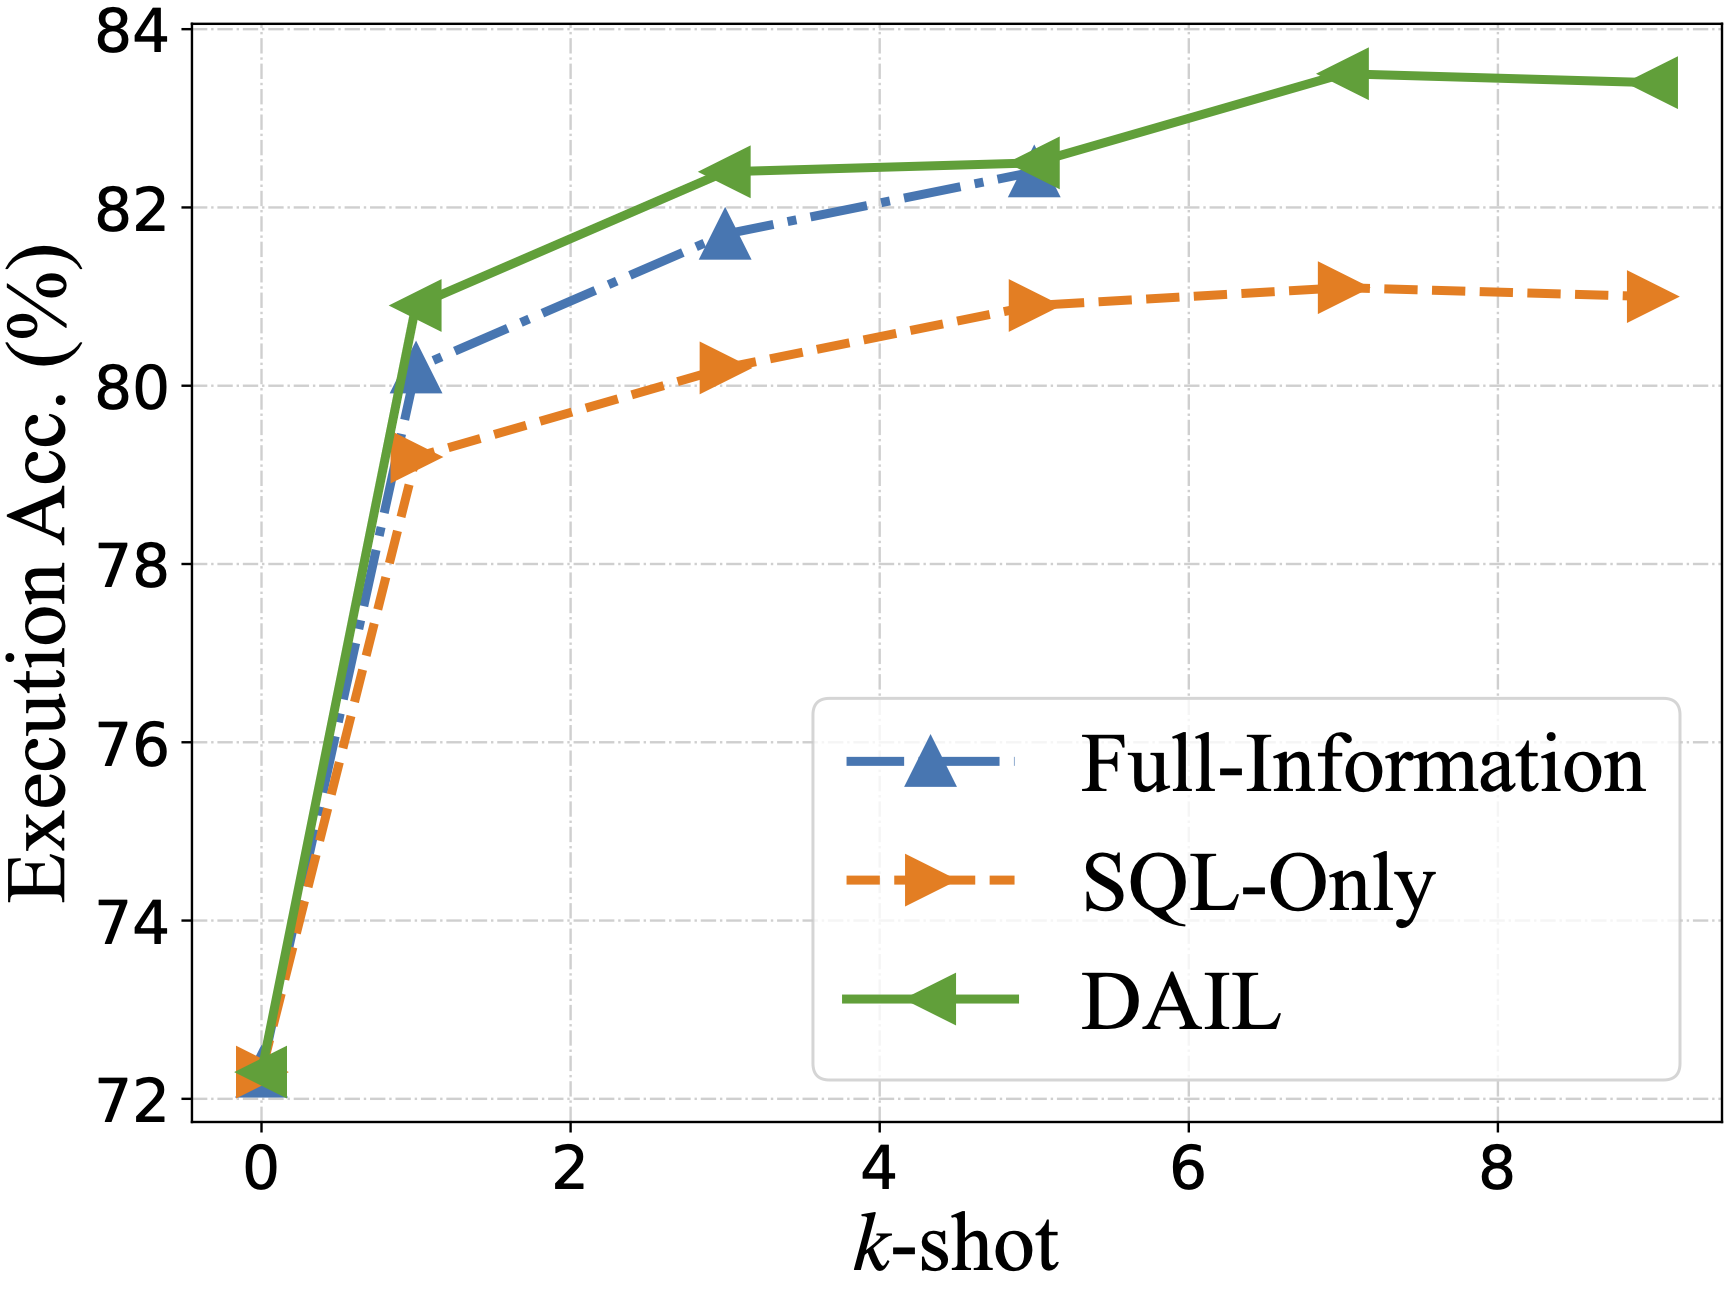
GPT-4
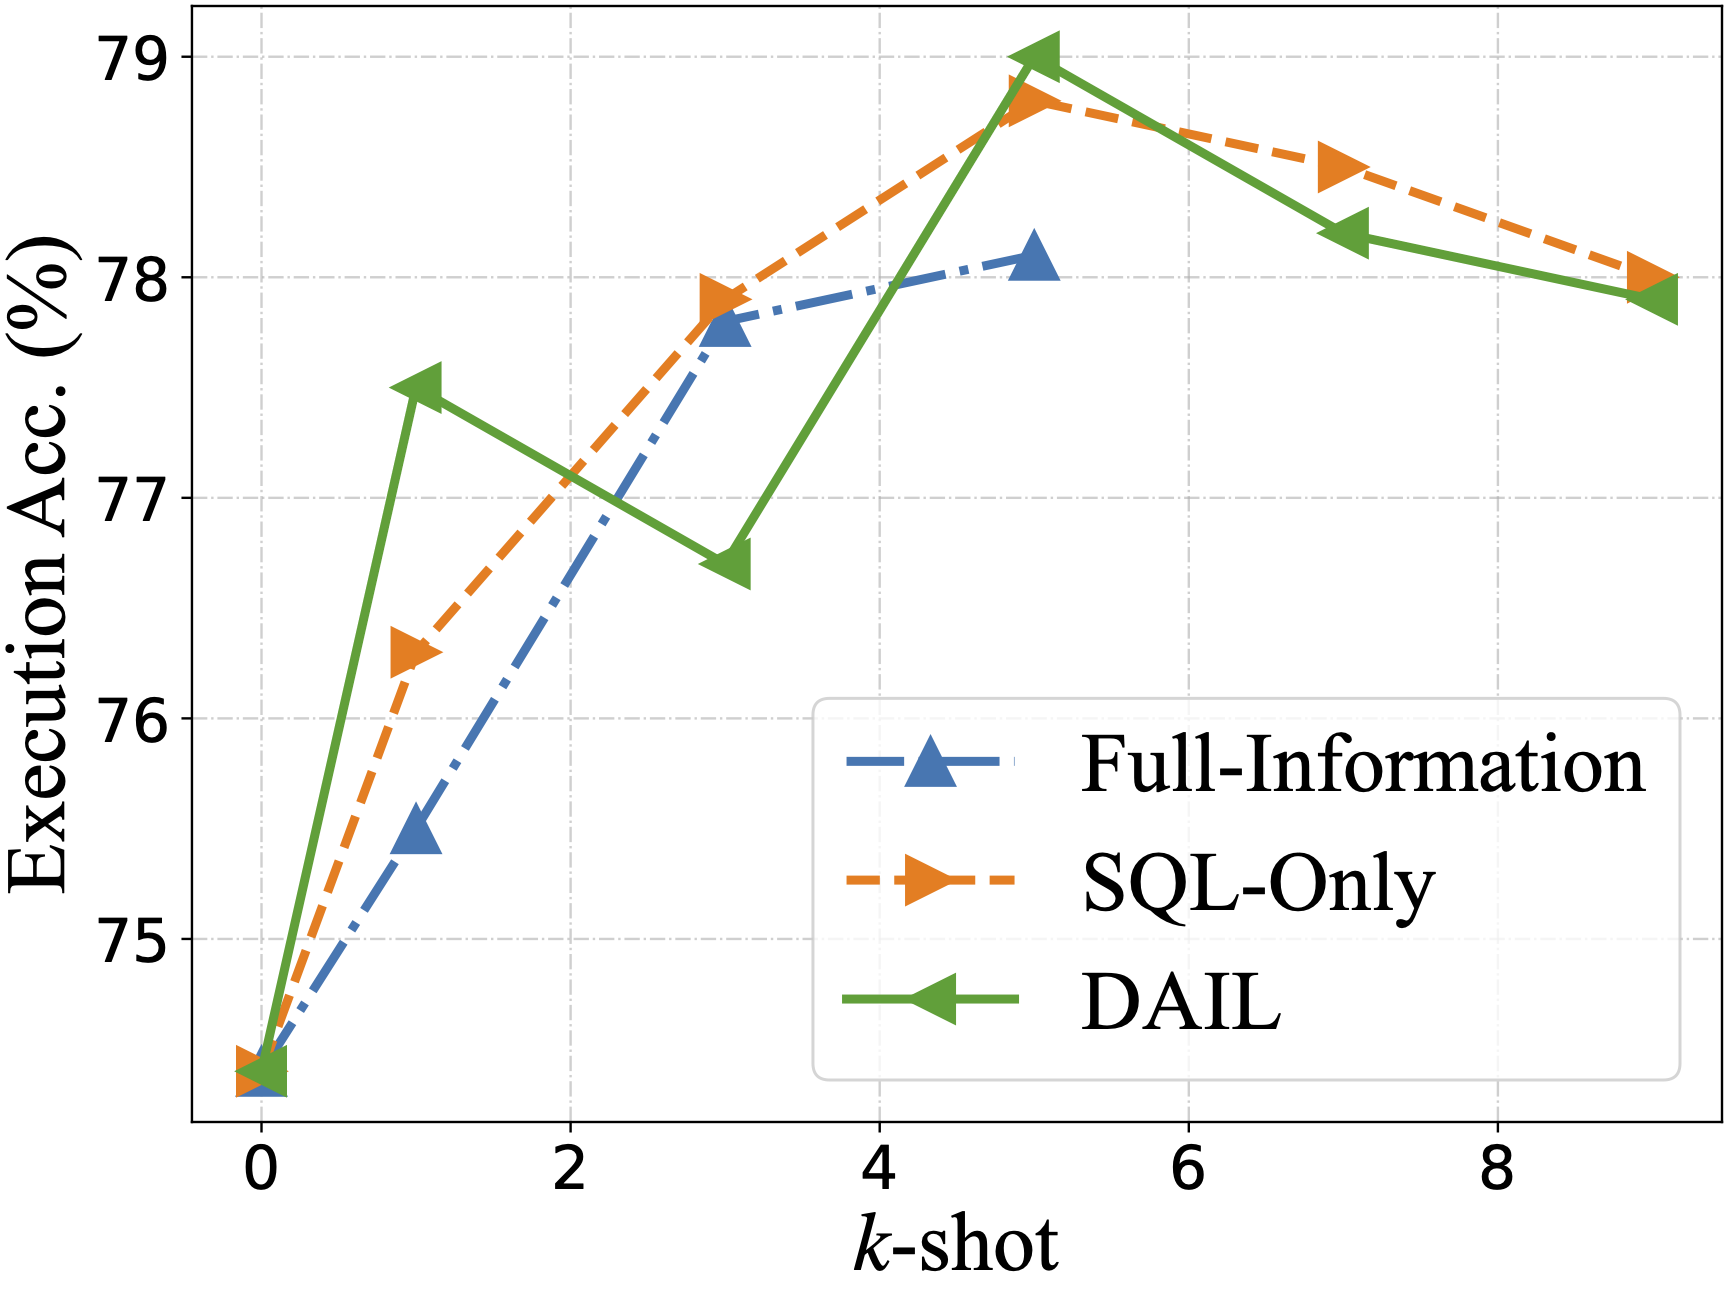
GPT-3.5-TURBO
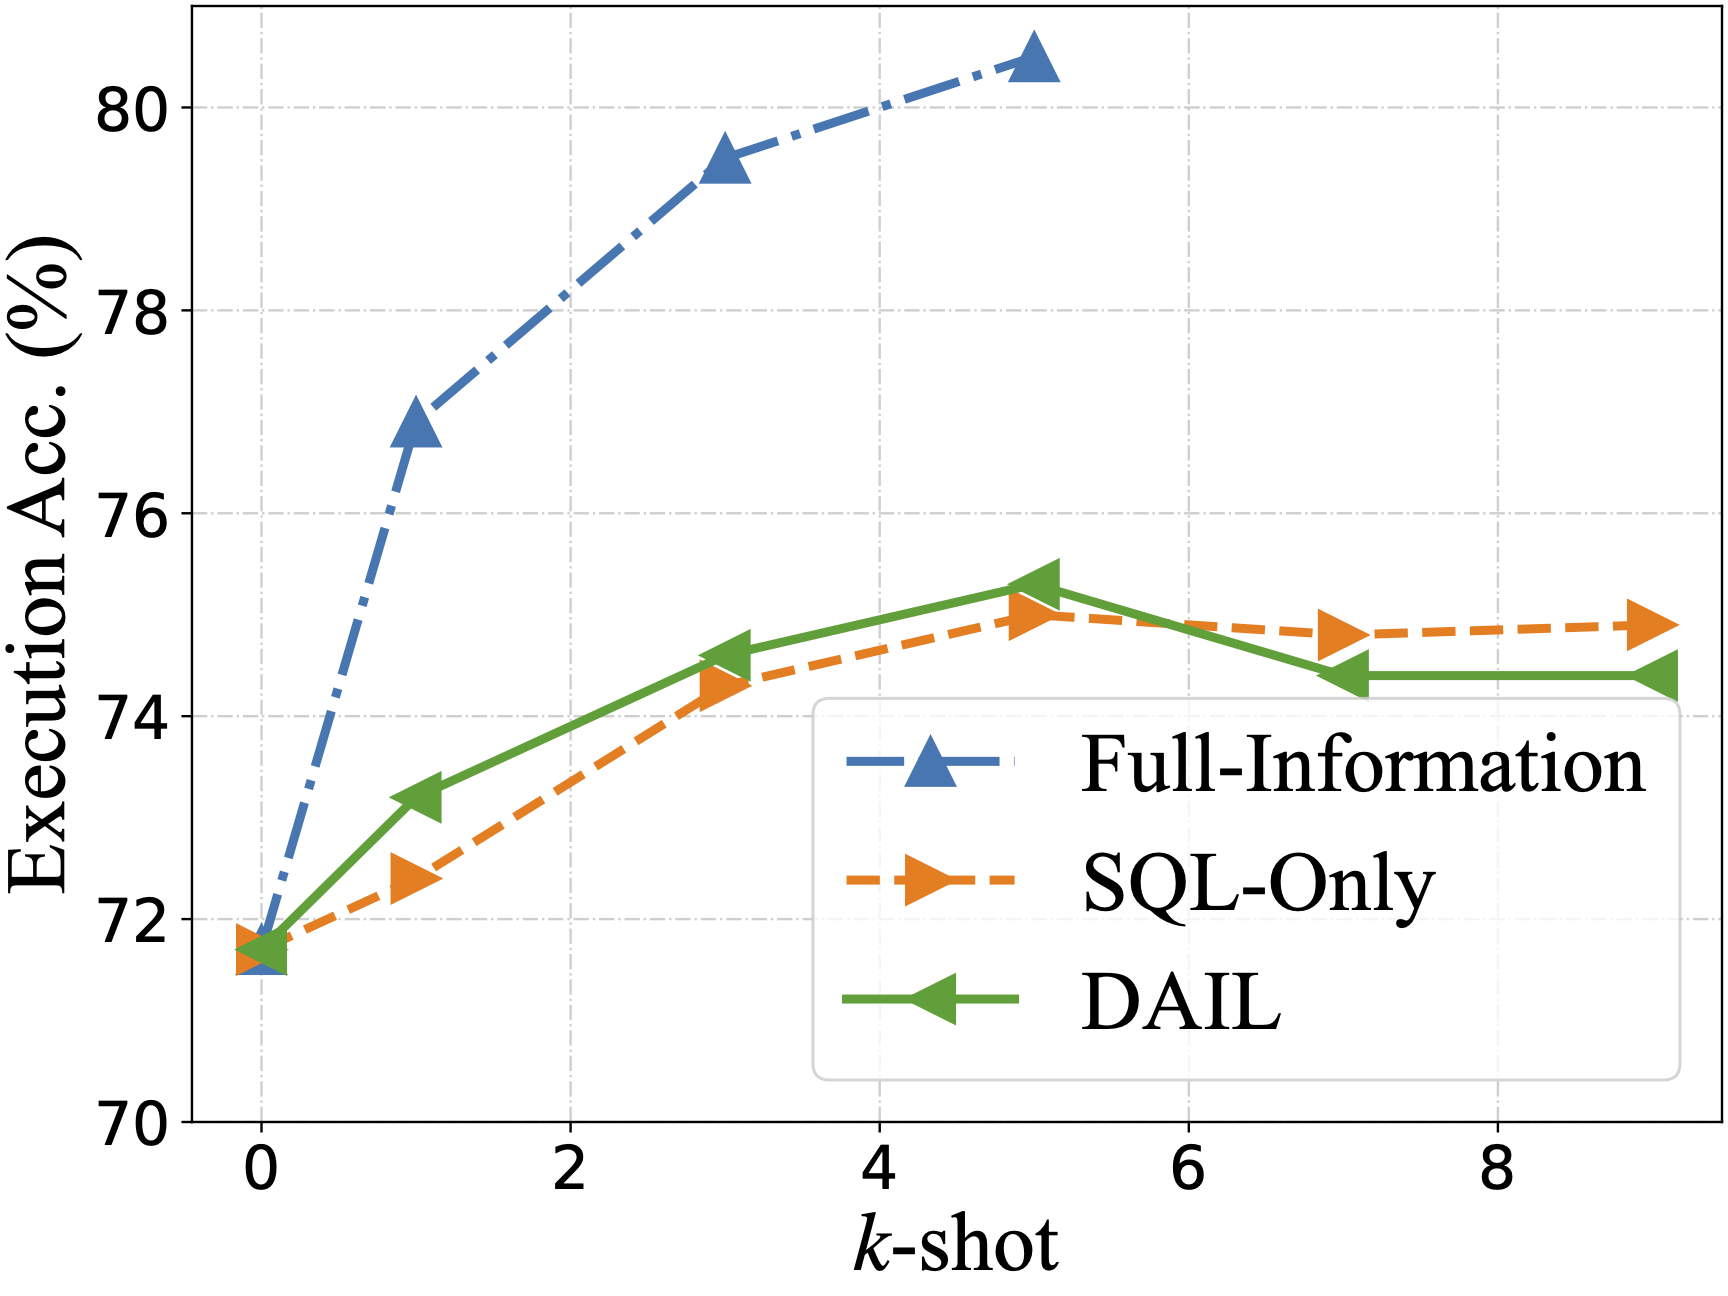
TEXT-DAVINCI-003
Vicuna-33B
Evaluation of DAIL-SQL
In evaluation, we take GPT-4 itself as the preliminary model for acquiring query similarity.
The commands are shown in run_dail_sql.sh and run_dail_sql_with_sc.sh.
| Method | Dev EM | Dev EX | Test EM | Test EX |
|---|---|---|---|---|
| DAIL-SQL+GPT-4 | 70.0 | 83.1 | 66.5 | 86.2 |
| DAIL-SQL+GPT-4+Self-consistency | 68.7 | 83.6 | 66.0 | 86.6 |
Bibtex
If DAIL-SQL is useful for you, please consider to cite it. Thank you! :)
@article{dail_sql,
    author  =   {Dawei Gao and
    Haibin Wang and
    Yaliang Li and
    Xiuyu Sun and
    Yichen Qian and
    Bolin Ding and
    Jingren Zhou},
    title   =   {Text-to-SQL Empowered by Large Language Models: A Benchmark Evaluation},
    journal =   {CoRR},
    volume  =   {abs/2308.15363},
    year    =   {2023}
}
Acknowledgements
The codes of schema-linking are inspired by RAT-SQL.
The codes of self-consistency voting are inspired by C3SQL.